-f https://developer.int
查看更多 [安装IPEX](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html) 的方法。
-
-### 在 Trainer 中使用 IPEX
-在 Trainer 中使用 IPEX 时,您应在训练命令参数中添加 `use_ipex`、`bf16` 或 `fp16` 以及 `no_cuda` 来启用自动混合精度。
-
-以 [Transformers 问答任务](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)为例:
-
-- 在 CPU 上使用 BF16 自动混合精度训练 IPEX 的示例如下:
- python examples/pytorch/question-answering/run_qa.py \
---model_name_or_path google-bert/bert-base-uncased \
---dataset_name squad \
---do_train \
---do_eval \
---per_device_train_batch_size 12 \
---learning_rate 3e-5 \
---num_train_epochs 2 \
---max_seq_length 384 \
---doc_stride 128 \
---output_dir /tmp/debug_squad/ \
---use_ipex \
---bf16 \
---use_cpu
-
-如果您想在脚本中启用 `use_ipex` 和 `bf16`,请像下面这样将这些参数添加到 `TrainingArguments` 中:
-```diff
-training_args = TrainingArguments(
- output_dir=args.output_path,
-+ bf16=True,
-+ use_ipex=True,
-+ use_cpu=True,
- **kwargs
-)
-```
-
### 实践示例
博客: [使用 Intel Sapphire Rapids 加速 PyTorch Transformers](https://huggingface.co/blog/intel-sapphire-rapids)
diff --git a/docs/source/zh/perf_train_special.md b/docs/source/zh/perf_train_special.md
index 8e7929ecb1cd..cb0b83805441 100644
--- a/docs/source/zh/perf_train_special.md
+++ b/docs/source/zh/perf_train_special.md
@@ -34,23 +34,7 @@ rendered properly in your Markdown viewer.
pip install torch torchvision torchaudio
```
-[`TrainingArguments`]类默认使用`mps`设备(如果可用)因此无需显式设置设备。例如,您可以直接运行[run_glue.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py)脚本,在无需进行任何修改的情况下自动启用 MPS 后端。
-
-```diff
-export TASK_NAME=mrpc
-
-python examples/pytorch/text-classification/run_glue.py \
- --model_name_or_path google-bert/bert-base-cased \
- --task_name $TASK_NAME \
-- --use_mps_device \
- --do_train \
- --do_eval \
- --max_seq_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/ \
-```
+[`TrainingArguments`]类默认使用`mps`设备(如果可用)因此无需显式设置设备。
用于[分布式设置](https://pytorch.org/docs/stable/distributed.html#backends)的后端(如`gloo`和`nccl`)不支持`mps`设备,这也意味着使用 MPS 后端时只能在单个 GPU 上进行训练。
diff --git a/docs/source/zh/run_scripts.md b/docs/source/zh/run_scripts.md
deleted file mode 100644
index 60e78fcb9e9b..000000000000
--- a/docs/source/zh/run_scripts.md
+++ /dev/null
@@ -1,287 +0,0 @@
-
-
-# 使用脚本进行训练
-
-除了 🤗 Transformers [notebooks](./notebooks),还有示例脚本演示了如何使用[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch)训练模型以解决特定任务。
-
-您还可以在这些示例中找到我们在[研究项目](https://github.com/huggingface/transformers-research-projects/)和[遗留示例](https://github.com/huggingface/transformers/tree/main/examples/legacy)中使用过的脚本,这些脚本主要是由社区贡献的。这些脚本已不再被积极维护,需要使用特定版本的🤗 Transformers, 可能与库的最新版本不兼容。
-
-示例脚本可能无法在初始配置下直接解决每个问题,您可能需要根据要解决的问题调整脚本。为了帮助您,大多数脚本都完全暴露了数据预处理的方式,允许您根据需要对其进行编辑。
-
-如果您想在示例脚本中实现任何功能,请在[论坛](https://discuss.huggingface.co/)或[issue](https://github.com/huggingface/transformers/issues)上讨论,然后再提交Pull Request。虽然我们欢迎修复错误,但不太可能合并添加更多功能的Pull Request,因为这会降低可读性。
-
-本指南将向您展示如何在[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization)中运行示例摘要训练脚本。
-
-## 设置
-
-要成功运行示例脚本的最新版本,您必须在新虚拟环境中**从源代码安装 🤗 Transformers**:
-
-```bash
-git clone https://github.com/huggingface/transformers
-cd transformers
-pip install .
-```
-
-对于旧版本的示例脚本,请点击下面的切换按钮:
-
-
- 老版本🤗 Transformers示例
-
-
-
-然后切换您clone的 🤗 Transformers 仓到特定的版本,例如v3.5.1:
-
-```bash
-git checkout tags/v3.5.1
-```
-
-在安装了正确的库版本后,进入您选择的版本的`example`文件夹并安装例子要求的环境:
-
-```bash
-pip install -r requirements.txt
-```
-
-## 运行脚本
-
-
-示例脚本从🤗 [Datasets](https://huggingface.co/docs/datasets/)库下载并预处理数据集。然后,脚本通过[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)使用支持摘要任务的架构对数据集进行微调。以下示例展示了如何在[CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail)数据集上微调[T5-small](https://huggingface.co/google-t5/t5-small)。由于T5模型的训练方式,它需要一个额外的`source_prefix`参数。这个提示让T5知道这是一个摘要任务。
-
-```bash
-python examples/pytorch/summarization/run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-## 分布式训练和混合精度
-
-[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) 支持分布式训练和混合精度,这意味着你也可以在脚本中使用它。要启用这两个功能,可以做如下设置:
-
-- 添加 `fp16` 参数以启用混合精度。
-- 使用 `nproc_per_node` 参数设置使用的GPU数量。
-
-
-```bash
-torchrun \
- --nproc_per_node 8 pytorch/summarization/run_summarization.py \
- --fp16 \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-## 在TPU上运行脚本
-
-
-张量处理单元(TPUs)是专门设计用于加速性能的。PyTorch使用 [PyTorch/XLA](https://github.com/pytorch/xla/blob/master/README.md) 支持TPU。要使用TPU,请启动`xla_spawn.py`脚本并使用`num_cores`参数设置要使用的TPU核心数量。
-
-```bash
-python xla_spawn.py --num_cores 8 \
- summarization/run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-## 基于🤗 Accelerate运行脚本
-
-🤗 [Accelerate](https://huggingface.co/docs/accelerate) 是一个仅支持 PyTorch 的库,它提供了一种统一的方法来在不同类型的设置(仅 CPU、多个 GPU、多个TPU)上训练模型,同时保持对 PyTorch 训练循环的完全可见性。如果你还没有安装 🤗 Accelerate,请确保你已经安装了它:
-
-> 注意:由于 Accelerate 正在快速发展,因此必须安装 git 版本的 accelerate 来运行脚本。
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-你需要使用`run_summarization_no_trainer.py`脚本,而不是`run_summarization.py`脚本。🤗 Accelerate支持的脚本需要在文件夹中有一个`task_no_trainer.py`文件。首先运行以下命令以创建并保存配置文件:
-
-```bash
-accelerate config
-```
-检测您的设置以确保配置正确:
-
-```bash
-accelerate test
-```
-
-现在您可以开始训练模型了:
-
-```bash
-accelerate launch run_summarization_no_trainer.py \
- --model_name_or_path google-t5/t5-small \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir ~/tmp/tst-summarization
-```
-
-## 使用自定义数据集
-
-摘要脚本支持自定义数据集,只要它们是CSV或JSON Line文件。当你使用自己的数据集时,需要指定一些额外的参数:
-- `train_file` 和 `validation_file` 分别指定您的训练和验证文件的路径。
-- `text_column` 是输入要进行摘要的文本。
-- `summary_column` 是目标输出的文本。
-
-使用自定义数据集的摘要脚本看起来是这样的:
-
-
-```bash
-python examples/pytorch/summarization/run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --train_file path_to_csv_or_jsonlines_file \
- --validation_file path_to_csv_or_jsonlines_file \
- --text_column text_column_name \
- --summary_column summary_column_name \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-## 测试脚本
-
-通常,在提交整个数据集之前,最好先在较少的数据集示例上运行脚本,以确保一切按预期工作,因为完整数据集的处理可能需要花费几个小时的时间。使用以下参数将数据集截断为最大样本数:
-
-- `max_train_samples`
-- `max_eval_samples`
-- `max_predict_samples`
-
-
-```bash
-python examples/pytorch/summarization/run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --max_train_samples 50 \
- --max_eval_samples 50 \
- --max_predict_samples 50 \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-并非所有示例脚本都支持`max_predict_samples`参数。如果您不确定您的脚本是否支持此参数,请添加`-h`参数进行检查:
-
-```bash
-examples/pytorch/summarization/run_summarization.py -h
-```
-
-## 从checkpoint恢复训练
-
-另一个有用的选项是从之前的checkpoint恢复训练。这将确保在训练中断时,您可以从之前停止的地方继续进行,而无需重新开始。有两种方法可以从checkpoint恢复训练。
-
-```bash
-python examples/pytorch/summarization/run_summarization.py
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --resume_from_checkpoint path_to_specific_checkpoint \
- --predict_with_generate
-```
-
-## 分享模型
-
-所有脚本都可以将您的最终模型上传到[Model Hub](https://huggingface.co/models)。在开始之前,请确保您已登录Hugging Face:
-
-```bash
-hf auth login
-```
-
-然后,在脚本中添加`push_to_hub`参数。这个参数会创建一个带有您Hugging Face用户名和`output_dir`中指定的文件夹名称的仓库。
-
-为了给您的仓库指定一个特定的名称,使用`push_to_hub_model_id`参数来添加它。该仓库将自动列出在您的命名空间下。
-
-以下示例展示了如何上传具有特定仓库名称的模型:
-
-
-```bash
-python examples/pytorch/summarization/run_summarization.py
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --push_to_hub \
- --push_to_hub_model_id finetuned-t5-cnn_dailymail \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
diff --git a/docs/source/zh/training.md b/docs/source/zh/training.md
index fb96590ae351..b346e9934f73 100644
--- a/docs/source/zh/training.md
+++ b/docs/source/zh/training.md
@@ -304,6 +304,4 @@ torch.cuda.empty_cache()
更多微调例子可参考如下链接:
-- [🤗 Transformers 示例](https://github.com/huggingface/transformers/tree/main/examples) 包含用于在 PyTorch 和 TensorFlow 中训练常见自然语言处理任务的脚本。
-
- [🤗 Transformers 笔记](notebooks) 包含针对特定任务在 PyTorch 和 TensorFlow 中微调模型的各种`notebook`。
diff --git a/examples/3D_parallel.py b/examples/3D_parallel.py
deleted file mode 100644
index d500e9aec41c..000000000000
--- a/examples/3D_parallel.py
+++ /dev/null
@@ -1,434 +0,0 @@
-# Copyright 2024 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-""":
-This script is used to test training a model using Tensor Parallelism and Data Parallelism.
-
-Usage:
-export CUDA_VISIBLE_DEVICES=0,1,2,3
-export CUDA_VISIBLE_DEVICES=4,5,6,7
-export CUDA_VISIBLE_DEVICES=5,6,7
-TP_SIZE=2 DP_SIZE=2 torchrun --nproc_per_node=4 --rdzv_endpoint=localhost:29503 examples/3D_parallel.py
-CP_SIZE=2 DP_SIZE=2 torchrun --nproc_per_node=4 examples/3D_parallel.py
-CP_SIZE=2 TP_SIZE=2 torchrun --nproc_per_node=4 examples/3D_parallel.py
-DP_SIZE=2 CP_SIZE=2 TP_SIZE=2 torchrun --nproc_per_node=8 examples/3D_parallel.py
-
-TP_SIZE=1 CP_SIZE=4 torchrun --nproc_per_node=4 examples/3D_parallel.py
-TP_SIZE=1 DP_SIZE=4 torchrun --nproc_per_node=4 examples/3D_parallel.py
-TP_SIZE=4 DP_SIZE=1 torchrun --nproc_per_node=4 --rdzv_endpoint=localhost:29503 examples/3D_parallel.py
-IGNORE_SANITY=1 CP_SIZE=1 TP_SIZE=1 DP_SIZE=1 torchrun --nproc_per_node=1 --rdzv_endpoint=localhost:29504 examples/3D_parallel.py
-ocalhost:29504 test_train.py
-"""
-
-import logging
-import os
-from collections.abc import Iterable
-from contextlib import nullcontext
-
-import torch
-import torch.distributed as dist
-import torch.distributed.checkpoint as dcp
-import torch.optim as optim
-import wandb
-from datasets import load_dataset
-from torch.distributed.checkpoint.state_dict import get_state_dict, set_state_dict
-from torch.distributed.checkpoint.stateful import Stateful
-from torch.distributed.device_mesh import DeviceMesh
-from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
-from torch.distributed.fsdp import ShardingStrategy
-from torch.distributed.tensor import DTensor
-from torch.distributed.tensor.experimental import context_parallel
-from torch.nn.attention import SDPBackend, sdpa_kernel
-from torch.utils.data import DataLoader
-from torch.utils.data.distributed import DistributedSampler
-
-from transformers import AutoModelForCausalLM, AutoTokenizer
-
-
-# torch.use_deterministic_algorithms(True)
-torch.backends.cudnn.deterministic = True
-
-# Set up logging
-logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
-)
-logger = logging.getLogger(__name__)
-
-# from torch.distributed.tensor.experimental._attention import set_rotate_method
-
-# set_rotate_method("alltoall") # CP rotate shards using all-to-all
-
-
-def main():
- tp_size = int(os.environ.get("TP_SIZE", "1"))
- dp_size = int(os.environ.get("DP_SIZE", "1"))
- cp_size = int(os.environ.get("CP_SIZE", "1")) # Add CP size configuration
- sdpa_backend = SDPBackend.FLASH_ATTENTION # For CP
- # sdpa_backend = SDPBackend.MATH # For CP
- global_batch_size = 8 # Desired global batch size
- seq_len = 1024 # Sequence length
- num_train_steps = 10000 # Number of training steps
- LR = 1e-5
- model_name = "HuggingFaceTB/SmolLM2-1.7B"
- # model_name = "unsloth/Llama-3.2-1B"
-
- CHECKPOINT_DIR = f"checkpoint_tp{tp_size}_dp{dp_size}_cp{cp_size}"
-
- # Initialize distributed environment
- if "RANK" in os.environ and "WORLD_SIZE" in os.environ:
- dist.init_process_group("nccl")
- rank = dist.get_rank()
- world_size = dist.get_world_size()
- local_rank = int(os.environ["LOCAL_RANK"])
- torch.cuda.set_device(local_rank)
-
- assert world_size == tp_size * dp_size * cp_size, (
- f"World size ({world_size}) must equal TP size ({tp_size}) * DP size ({dp_size}) * CP size ({cp_size})"
- )
-
- mesh = torch.arange(world_size).reshape(dp_size, tp_size, cp_size)
- world_mesh = DeviceMesh(device_type="cuda", mesh=mesh, mesh_dim_names=("dp", "tp", "cp"))
- tp_mesh = world_mesh["tp"]
- dp_mesh = world_mesh["dp"]
- cp_mesh = world_mesh["cp"]
- world_mesh["dp", "cp"]._flatten(mesh_dim_name="dp_cp")
- logger.info(f"Created DeviceMesh: {world_mesh}")
- logger.info(
- f"Distributed setup - Rank: {rank}, World size: {world_size}, Local rank: {local_rank}, DP: {dp_mesh.get_local_rank()}, TP: {tp_mesh.get_local_rank()}, CP: {cp_mesh.get_local_rank()}"
- )
-
- if dist.get_rank() == 0:
- wandb.init(
- project="tp_dp_test",
- config={
- "tp_size": tp_size,
- "dp_size": dp_size,
- "cp_size": cp_size,
- "global_batch_size": global_batch_size,
- "model_name": model_name,
- "dataset": "roneneldan/TinyStories-1M",
- "seq_len": seq_len,
- "lr": LR,
- "weight_decay": 0.1,
- },
- name=f"llama_tp{tp_size}_dp{dp_size}_cp{cp_size}"
- if model_name == "unsloth/Llama-3.2-1B"
- else f"tp{tp_size}_dp{dp_size}_cp{cp_size}",
- )
- logger.info("Wandb initialized.")
- # Log the current file to wandb
- wandb.save("test_train.py")
-
- # Load model and tokenizer
- logger.info(f"Loading model and tokenizer from {model_name}")
- tokenizer = AutoTokenizer.from_pretrained(model_name)
- if tokenizer.pad_token is None:
- tokenizer.pad_token = tokenizer.eos_token
- logger.info(f"Set pad_token to eos_token: {tokenizer.pad_token}")
-
- model = AutoModelForCausalLM.from_pretrained(
- model_name,
- device_mesh=tp_mesh if dist.is_initialized() else None,
- tp_plan="auto",
- dtype=torch.bfloat16,
- )
- logger.info(f"Model loaded onto device mesh: {tp_mesh}")
- device = torch.device(f"cuda:{local_rank}")
- logger.info(f"Using device: {device} for non-model tensors")
- use_ddp = False
- if dist.is_initialized() and dp_mesh.size() > 1:
- model = FSDP(model, device_mesh=dp_mesh, sharding_strategy=ShardingStrategy.NO_SHARD)
- use_ddp = True
-
- model.train()
-
- logger.info("Loading TinyStories dataset...")
- raw_dataset = load_dataset("roneneldan/TinyStories", split="train[:1%]") # Use 1% for faster testing
-
- def tokenize_function(examples):
- # Tokenize the text without padding
- tokenized_batch = tokenizer(
- examples["text"], padding=False, truncation=True, max_length=seq_len, return_tensors=None
- )
- # Set labels to be the same as input_ids for Causal LM
- tokenized_batch["labels"] = tokenized_batch["input_ids"].copy()
- return tokenized_batch
-
- tokenized_dataset = raw_dataset.map(tokenize_function, batched=True, remove_columns=["text"])
- logger.info(f"Dataset loaded and tokenized. Size: {len(tokenized_dataset)}")
-
- # Create packed sequences
- def create_packed_sequences(examples):
- # Flatten all sequences
- all_tokens = []
- for input_ids in examples["input_ids"]:
- all_tokens.extend(input_ids)
-
- # Split into sequences of seq_len + 1 (for input + label)
- num_sequences = len(all_tokens) // (seq_len + 1)
- packed_input_ids = []
- packed_labels = []
-
- for i in range(num_sequences):
- start_idx = i * (seq_len + 1)
- end_idx = start_idx + (seq_len + 1)
- # Get the full sequence
- full_sequence = all_tokens[start_idx:end_idx]
- # For input_ids, remove the last token
- packed_input_ids.append(full_sequence[:-1])
- # For labels, remove the first token
- packed_labels.append(full_sequence[1:])
-
- return {"input_ids": packed_input_ids, "labels": packed_labels}
-
- # Apply packing to the dataset
- packed_dataset = tokenized_dataset.map(
- create_packed_sequences,
- batched=True,
- remove_columns=tokenized_dataset.column_names,
- batch_size=1000, # Process in batches for efficiency
- num_proc=60,
- )
- logger.info(f"Dataset packed. New size: {len(packed_dataset)}")
-
- # Shuffle the packed dataset
- packed_dataset = packed_dataset.shuffle(seed=42)
- logger.info("Packed dataset shuffled")
-
- # Calculate local batch size
- if dist.is_initialized():
- assert global_batch_size % dp_mesh.size() == 0, (
- f"Global batch size ({global_batch_size}) must be divisible by DP size ({dp_mesh.size()})"
- )
- local_batch_size = global_batch_size // dp_mesh.size()
- else:
- local_batch_size = global_batch_size
-
- logger.info(
- f"Global batch size: {global_batch_size}, DP size: {dp_size if dist.is_initialized() else 1}, Local batch size: {local_batch_size}"
- )
-
- # Simple collate function since sequences are already packed
- def collate_fn(batch):
- input_ids = torch.tensor([item["input_ids"] for item in batch], dtype=torch.long)
- labels = torch.tensor([item["labels"] for item in batch], dtype=torch.long)
- return {"input_ids": input_ids, "labels": labels}
-
- if dist.is_initialized():
- sampler = DistributedSampler(
- packed_dataset, num_replicas=dp_mesh.size(), rank=dp_mesh.get_local_rank(), shuffle=False
- )
- else:
- sampler = None
-
- dataloader = DataLoader(
- packed_dataset,
- batch_size=local_batch_size,
- sampler=sampler,
- shuffle=False,
- collate_fn=collate_fn,
- pin_memory=True,
- )
- logger.info(f"DataLoader created. Distributed: {dist.is_initialized()}")
-
- optimizer = optim.AdamW(model.parameters(), lr=LR, weight_decay=0.1)
-
- # Training loop
- logger.info(f"Starting training for {num_train_steps} steps...")
- model.train()
- step = 0
- while step < num_train_steps:
- for batch in dataloader:
- if step >= num_train_steps:
- break # Exit loop if max steps reached
-
- # Move batch to appropriate device
- batch = {k: v.to(device) for k, v in batch.items()}
- optimizer.zero_grad()
-
- # Add position_ids to batch before CP sharding
- batch_size = batch["input_ids"].shape[0]
- position_ids = torch.arange(0, seq_len, dtype=torch.long, device=device)
- position_ids = position_ids.unsqueeze(0).expand(batch_size, -1)
- batch["position_ids"] = position_ids
- from torch.distributed.tensor.experimental._attention import _cp_options
-
- _cp_options.enable_load_balance = False
-
- with sdpa_kernel(sdpa_backend): # TODO: ideally move this to attention implementation
- cp_context = (
- nullcontext()
- if cp_mesh.size() == 1
- else context_parallel(
- cp_mesh,
- buffers=[
- batch["input_ids"],
- batch["labels"],
- batch["position_ids"],
- ],
- buffer_seq_dims=[1, 1, 1],
- )
- )
- with cp_context:
- # Pop labels from batch before model forward pass
- labels = batch.pop("labels")
- outputs = model(**batch) # [mbs, seq_len/cp]
- loss = outputs.loss
- logits = outputs.logits
-
- # Compute loss with shifted labels
- loss = model.loss_function(
- logits=logits, labels=None, shift_labels=labels, vocab_size=model.config.vocab_size
- )
- loss.backward()
-
- # all reduce grads across dp_cp if applicable
- all_reduce_grads(model, world_mesh, use_ddp=use_ddp)
-
- if hasattr(model, "clip_grad_norm_"):
- gradnorm = model.clip_grad_norm_(max_norm=1.0, norm_type=2.0) # TODO: fix reported gradnorm
- else:
- # only works with FSDP's NO_SHARD otherwise we should use FSDP's clip_grad_norm_
- assert len(list(model.parameters())) > 5, "No parameters found in model. Probably DDP bug.."
- gradnorm = clip_grad_norm_(model.parameters(), max_norm=1.0, norm_type=2.0, foreach=True)
-
- optimizer.step()
- # allreduce loss across cp_dp before logging
- if dist.is_initialized() and (cp_mesh.size() > 1 or dp_mesh.size() > 1):
- dist.all_reduce(loss, group=world_mesh["dp_cp"].get_group(), op=dist.ReduceOp.AVG)
- current_loss = loss.item()
-
- # Log loss and gradnorm to wandb (only on rank 0 of dp group)
- if not dist.is_initialized() or dist.get_rank() == 0:
- logger.info(
- f"Step: {step} | GBS: {global_batch_size} | DP: {dp_mesh.size()} | TP: {tp_mesh.size()} | CP: {cp_mesh.size()} | Loss: {current_loss} | Gradnorm: {gradnorm} | lr: {LR}"
- )
- wandb.log(
- {
- "train/loss": current_loss,
- "train/gradnorm": gradnorm,
- "step": step,
- "lr": LR,
- "GBS": global_batch_size,
- }
- )
-
- step += 1 # Increment step count
-
- logger.info("Training loop finished.")
-
- # Save model using DCP (only if distributed)
- if dist.is_initialized():
- state_dict = {"app": AppState(model, optimizer)}
- dcp.save(
- state_dict=state_dict,
- checkpoint_id=CHECKPOINT_DIR,
- )
- logger.info(f"Saved checkpoint to {CHECKPOINT_DIR}")
- else:
- # Fallback to regular save for non-distributed case
- save_dir = "test_model_nondist"
- model.save_pretrained(save_dir)
- tokenizer.save_pretrained(save_dir) # Save tokenizer too
- logger.info(f"Saved model to {save_dir}")
-
- dist.destroy_process_group()
- logger.info("Cleaned up distributed process group")
- # Finish wandb run on rank 0
- if dist.get_rank() == 0:
- wandb.finish()
- logger.info("Wandb run finished.")
-
-
-def all_reduce_grads(model, world_mesh, use_ddp):
- """All reduce gradients across dp_cp if applicable."""
- cp_mesh = world_mesh["cp"]
- if use_ddp:
- # DDP/FSDP takes care of syncing grads
- mesh = cp_mesh
- else:
- mesh = world_mesh["dp", "cp"]._flatten(mesh_dim_name="dp_cp")
- if dist.is_initialized() and mesh.size() > 1:
- for name, param in model.named_parameters():
- if param.grad is not None:
- # Workaround for cross-mesh communication limitation with DTensor gradients
- if isinstance(param.grad, DTensor):
- local_grad = param.grad.to_local()
- # Ensure grad requires grad for inplace modification checks (might not be needed)
- # local_grad = local_grad.detach().requires_grad_(True)
- torch.distributed.all_reduce(local_grad, op=torch.distributed.ReduceOp.SUM, group=mesh.get_group())
- local_grad = local_grad / mesh.size()
- # Assign averaged grad back - need careful handling if DTensor structure is complex
- # This simple assignment might work if the grad structure matches param structure
- param.grad = DTensor.from_local(
- local_grad, device_mesh=param.grad.device_mesh, placements=param.grad.placements
- )
- else:
- # Handle regular tensors if any exist (e.g. buffers not converted to DTensor)
- torch.distributed.all_reduce(param.grad, op=torch.distributed.ReduceOp.AVG, group=mesh.get_group())
-
-
-class AppState(Stateful):
- """Wrapper for checkpointing the Application State including model and optimizer."""
-
- def __init__(self, model, optimizer=None):
- self.model = model
- self.optimizer = optimizer
-
- def state_dict(self):
- model_state_dict, optimizer_state_dict = get_state_dict(self.model, self.optimizer)
- return {"model": model_state_dict, "optim": optimizer_state_dict}
-
- def load_state_dict(self, state_dict):
- set_state_dict(
- self.model, self.optimizer, model_state_dict=state_dict["model"], optim_state_dict=state_dict["optim"]
- )
-
-
-def clip_grad_norm_(
- parameters: Iterable[torch.Tensor],
- max_norm: float,
- norm_type: float = 2.0,
- error_if_nonfinite: bool = False,
- foreach: bool | None = None,
-) -> torch.Tensor:
- """
- Clip the gradient norm of an iterable of parameters.
- """
- # Filter out parameters with no gradients
- parameters = [p for p in parameters if p.grad is not None]
- assert len(parameters) > 0, "No parameters with gradients found"
-
- # Calculate total norm
- if norm_type == float("inf"):
- total_norm = max(p.grad.detach().abs().max() for p in parameters)
- else:
- total_norm = torch.norm(torch.stack([torch.norm(p.grad.detach(), norm_type) for p in parameters]), norm_type)
-
- # Convert DTensor to local tensor if needed
- if isinstance(total_norm, DTensor):
- total_norm = total_norm.full_tensor()
-
- # Clip gradients
- clip_coef = max_norm / (total_norm + 1e-6)
- if clip_coef < 1:
- for p in parameters:
- p.grad.detach().mul_(clip_coef)
-
- return total_norm
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/README.md b/examples/README.md
deleted file mode 100644
index ba2a9abd6e37..000000000000
--- a/examples/README.md
+++ /dev/null
@@ -1,150 +0,0 @@
-
-
-# Examples
-
-We host a wide range of example scripts, in addition to [research projects](https://github.com/huggingface/transformers-research-projects/), as well as some [legacy examples](https://github.com/huggingface/transformers/tree/main/examples/legacy). Note that unlike the main examples these are not actively maintained, and may require specific older versions of dependencies in order to run.
-
-While we strive to present as many use cases as possible, the example scripts are just that - examples. It is expected that they won't work out-of-the-box on your specific problem and that you will be required to change a few lines of code to adapt them to your needs. To help you with that, most of the examples fully expose the preprocessing of the data, allowing you to tweak and edit them as required.
-
-Please discuss on the [forum](https://discuss.huggingface.co/) or in an [issue](https://github.com/huggingface/transformers/issues) a feature you would like to implement in an example before submitting a PR; we welcome bug fixes, but since we want to keep the examples as simple as possible it's unlikely that we will merge a pull request adding more functionality at the cost of readability.
-
-## Important note
-
-**Important**
-
-To make sure you can successfully run the latest versions of the example scripts, you have to **install the library from source** and install some example-specific requirements. To do this, execute the following steps in a new virtual environment:
-```bash
-git clone https://github.com/huggingface/transformers
-cd transformers
-pip install .
-```
-Then cd in the example folder of your choice and run
-```bash
-pip install -r requirements.txt
-```
-
-To browse the examples corresponding to released versions of 🤗 Transformers, click on the line below and then on your desired version of the library:
-
-
- Examples for older versions of 🤗 Transformers
-
-
-
-Alternatively, you can switch your cloned 🤗 Transformers to a specific version (for instance with v3.5.1) with
-```bash
-git checkout tags/v3.5.1
-```
-and run the example command as usual afterward.
-
-## Running the Examples on Hugging Face Jobs
-
-Each example script declares its dependencies in a [PEP 723](https://peps.python.org/pep-0723/) `# /// script` header, so it runs on [Hugging Face Jobs](https://huggingface.co/docs/hub/jobs) straight from its GitHub URL, with no environment to set up. Pass the URL to `hf jobs uv run` and the script's arguments after it:
-
-```bash
-hf jobs uv run --flavor a10g-small --timeout 30m -s HF_TOKEN -- \
- https://raw.githubusercontent.com/huggingface/transformers/main/examples/pytorch/image-classification/run_image_classification.py \
- --model_name_or_path google/vit-base-patch16-224-in21k \
- --dataset_name ethz/food101 \
- --do_train --do_eval \
- --remove_unused_columns False \
- --max_train_samples 2000 --max_eval_samples 500 --num_train_epochs 1 \
- --output_dir vit-food101 \
- --push_to_hub
-```
-
-`--flavor` picks the hardware, `--timeout` sets the time limit (30 minutes by default), and `-s HF_TOKEN` forwards your token so the script can push the model. The `--` before the URL keeps the two apart, so a script argument that shares a name with an `hf` flag, such as `--token`, goes to the script. This trains on 2,000 images and finishes in about three minutes. For the full run, drop the `--max_*` and `--num_train_epochs` flags and raise `--timeout` to `2h`: three epochs over Food-101 take about an hour on `a10g-small`. See [Train Models on Jobs](https://huggingface.co/docs/hub/jobs-training) for the details.
-
-## Running the Examples on Remote Hardware with Auto-Setup
-
-[run_on_remote.py](./run_on_remote.py) is a script that launches any example on remote self-hosted hardware,
-with automatic hardware and environment setup. It uses [Runhouse](https://github.com/run-house/runhouse) to launch
-on self-hosted hardware (e.g. in your own cloud account or on-premise cluster) but there are other options
-for running remotely as well. You can easily customize the example used, command line arguments, dependencies,
-and type of compute hardware, and then run the script to automatically launch the example.
-
-You can refer to
-[hardware setup](https://www.run.house/docs/tutorials/quick-start-cloud)
-for more information about hardware and dependency setup with Runhouse, or this
-[Colab tutorial](https://colab.research.google.com/drive/1sh_aNQzJX5BKAdNeXthTNGxKz7sM9VPc) for a more in-depth
-walkthrough.
-
-You can run the script with the following commands:
-
-```bash
-# First install runhouse:
-pip install runhouse
-
-# For an on-demand V100 with whichever cloud provider you have configured:
-python run_on_remote.py \
- --example pytorch/text-generation/run_generation.py \
- --model_type=gpt2 \
- --model_name_or_path=openai-community/gpt2 \
- --prompt "I am a language model and"
-
-# For byo (bring your own) cluster:
-python run_on_remote.py --host --user --key_path \
- --example
-
-# For on-demand instances
-python run_on_remote.py --instance --provider \
- --example
-```
-
-You can also adapt the script to your own needs.
diff --git a/examples/pytorch/continuous_batching.py b/examples/generate/continuous_batching.py
similarity index 97%
rename from examples/pytorch/continuous_batching.py
rename to examples/generate/continuous_batching.py
index bd0b2c3b16c9..c84a361bb2f4 100644
--- a/examples/pytorch/continuous_batching.py
+++ b/examples/generate/continuous_batching.py
@@ -315,6 +315,6 @@ def batch_generate(
prof.export_chrome_trace(filename)
# Example usage:
-# python examples/pytorch/continuous_batching.py --attn sdpa --add-prefix --samples 10 --compare
-# python examples/pytorch/continuous_batching.py --attn flash_attention_2 -mp none --add-prefix --samples 500
-# python examples/pytorch/continuous_batching.py -mp none -cg yes --samples 10 --max-new-tokens 32 --profile profile_wip.json
+# python examples/generate/continuous_batching.py --attn sdpa --add-prefix --samples 10 --compare
+# python examples/generate/continuous_batching.py --attn flash_attention_2 -mp none --add-prefix --samples 500
+# python examples/generate/continuous_batching.py -mp none -cg yes --samples 10 --max-new-tokens 32 --profile profile_wip.json
diff --git a/examples/pytorch/continuous_batching_simple.py b/examples/generate/continuous_batching_simple.py
similarity index 100%
rename from examples/pytorch/continuous_batching_simple.py
rename to examples/generate/continuous_batching_simple.py
diff --git a/examples/pytorch/transformers_serve_cb_eval_job.py b/examples/generate/transformers_serve_cb_eval_job.py
similarity index 100%
rename from examples/pytorch/transformers_serve_cb_eval_job.py
rename to examples/generate/transformers_serve_cb_eval_job.py
diff --git a/examples/pytorch/3d_parallel_checks.py b/examples/pytorch/3d_parallel_checks.py
deleted file mode 100644
index a99988d98247..000000000000
--- a/examples/pytorch/3d_parallel_checks.py
+++ /dev/null
@@ -1,792 +0,0 @@
-# Copyright 2024 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-""":
-This script is used to test training a model using Tensor Parallelism and Data Parallelism.
-
-Usage:
-export CUDA_VISIBLE_DEVICES=0,1,2,3
-export CUDA_VISIBLE_DEVICES=4,5,6,7
-export CUDA_VISIBLE_DEVICES=5,6,7
-TP_SIZE=2 DP_SIZE=2 torchrun --nproc_per_node=4 --rdzv_endpoint=localhost:29503 test_train.py
-CP_SIZE=2 DP_SIZE=2 torchrun --nproc_per_node=4 test_train.py
-CP_SIZE=2 TP_SIZE=2 torchrun --nproc_per_node=4 test_train.py
-
-TP_SIZE=1 CP_SIZE=4 torchrun --nproc_per_node=4 test_train.py
-TP_SIZE=1 DP_SIZE=4 torchrun --nproc_per_node=4 test_train.py
-TP_SIZE=4 DP_SIZE=1 torchrun --nproc_per_node=4 --rdzv_endpoint=localhost:29503 test_train.py
-IGNORE_SANITY=1 CP_SIZE=1 TP_SIZE=1 DP_SIZE=1 torchrun --nproc_per_node=1 --rdzv_endpoint=l
-ocalhost:29504 test_train.py
-"""
-
-import logging
-import os
-from collections.abc import Iterable
-from contextlib import nullcontext
-
-import torch
-import torch.distributed as dist
-import torch.distributed.checkpoint as dcp
-import torch.nn as nn
-import torch.optim as optim
-import wandb
-from datasets import load_dataset
-from torch.distributed.checkpoint.state_dict import get_state_dict, set_state_dict
-from torch.distributed.checkpoint.stateful import Stateful
-from torch.distributed.device_mesh import DeviceMesh
-from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
-from torch.distributed.fsdp import ShardingStrategy
-from torch.distributed.tensor import DTensor
-from torch.distributed.tensor.experimental import context_parallel
-from torch.nn.attention import SDPBackend, sdpa_kernel
-from torch.utils.data import DataLoader, default_collate
-from torch.utils.data.distributed import DistributedSampler
-
-from transformers import AutoModelForCausalLM, AutoTokenizer
-
-
-ignore_sanity_checks = int(os.environ.get("IGNORE_SANITY", "0")) == 1
-# torch.use_deterministic_algorithms(True)
-torch.backends.cudnn.deterministic = True
-
-# Set up logging
-logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
-)
-logger = logging.getLogger(__name__)
-
-# from torch.distributed.tensor.experimental._attention import set_rotate_method
-
-# set_rotate_method("alltoall") # rotate shards using all-to-all
-
-
-def main():
- tp_size = int(os.environ.get("TP_SIZE", "1"))
- dp_size = int(os.environ.get("DP_SIZE", "4"))
- cp_size = int(os.environ.get("CP_SIZE", "1")) # Add CP size configuration
- sdpa_backend = SDPBackend.FLASH_ATTENTION # For CP
- # sdpa_backend = SDPBackend.MATH # For CP
- global_batch_size = 8 # Desired global batch size
- seq_len = 1024 # Sequence length
- num_train_steps = 10000 # Number of training steps
- LR = 1e-5
- model_name = "HuggingFaceTB/SmolLM2-1.7B"
- # model_name = "unsloth/Llama-3.2-1B"
-
- CHECKPOINT_DIR = f"checkpoint_tp{tp_size}_dp{dp_size}_cp{cp_size}"
-
- # Initialize distributed environment
- if "RANK" in os.environ and "WORLD_SIZE" in os.environ:
- dist.init_process_group("nccl")
- rank = dist.get_rank()
- world_size = dist.get_world_size()
- local_rank = int(os.environ["LOCAL_RANK"])
- torch.cuda.set_device(local_rank)
-
- assert world_size == tp_size * dp_size * cp_size, (
- f"World size ({world_size}) must equal TP size ({tp_size}) * DP size ({dp_size}) * CP size ({cp_size})"
- )
-
- mesh = torch.arange(world_size).reshape(dp_size, tp_size, cp_size)
- world_mesh = DeviceMesh(device_type="cuda", mesh=mesh, mesh_dim_names=("dp", "tp", "cp"))
- tp_mesh = world_mesh["tp"]
- dp_mesh = world_mesh["dp"]
- cp_mesh = world_mesh["cp"]
- world_mesh["dp", "cp"]._flatten(mesh_dim_name="dp_cp")
- logger.info(f"Created DeviceMesh: {world_mesh}")
- logger.info(
- f"Distributed setup - Rank: {rank}, World size: {world_size}, Local rank: {local_rank}, DP: {dp_mesh.get_local_rank()}, TP: {tp_mesh.get_local_rank()}, CP: {cp_mesh.get_local_rank()}"
- )
-
- if dist.get_rank() == 0:
- wandb.init(
- project="tp_dp_test",
- config={
- "tp_size": tp_size,
- "dp_size": dp_size,
- "cp_size": cp_size,
- "global_batch_size": global_batch_size,
- "model_name": model_name,
- "dataset": "roneneldan/TinyStories-1M",
- "seq_len": seq_len,
- "lr": LR,
- "weight_decay": 0.1,
- },
- name=f"llama_tp{tp_size}_dp{dp_size}_cp{cp_size}"
- if model_name == "unsloth/Llama-3.2-1B"
- else f"tp{tp_size}_dp{dp_size}_cp{cp_size}",
- )
- logger.info(f"ignore_sanity_checks is set to: {ignore_sanity_checks}")
- logger.info("Wandb initialized.")
- # Log the current file to wandb
- wandb.save("test_train.py")
-
- else:
- logger.info("Running in non-distributed mode. DeviceMesh not applicable.")
- rank = 0
- world_size = 1
- local_rank = 0
- device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
- wandb.init(
- project="tp_dp_test",
- config={
- "tp_size": 1,
- "dp_size": 1,
- "global_batch_size": global_batch_size,
- "model_name": model_name,
- "dataset": "roneneldan/TinyStories-1M",
- "seq_len": seq_len,
- },
- name="llama_tp1_dp1_nondist" if model_name == "unsloth/Llama-3.2-1B" else "tp1_dp1_nondist",
- )
- logger.info("Wandb initialized for non-distributed run.")
-
- # Load model and tokenizer
- logger.info(f"Loading model and tokenizer from {model_name}")
- tokenizer = AutoTokenizer.from_pretrained(model_name)
- if tokenizer.pad_token is None:
- tokenizer.pad_token = tokenizer.eos_token
- logger.info(f"Set pad_token to eos_token: {tokenizer.pad_token}")
-
- model = AutoModelForCausalLM.from_pretrained(
- model_name,
- device_mesh=tp_mesh if dist.is_initialized() else None,
- tp_plan="auto",
- dtype=torch.bfloat16,
- )
- logger.info(f"Model loaded onto device mesh: {tp_mesh}")
-
- if dist.is_initialized():
- assert model.config.num_key_value_heads % tp_mesh.size() == 0, (
- f"num_key_value_heads={model.config.num_key_value_heads} must be divisible by tp_size={tp_mesh.size()}"
- )
- device = torch.device(f"cuda:{local_rank}")
- else:
- model = model.to(device)
-
- logger.info(f"Using device: {device} for non-model tensors")
- use_ddp = False
- if dist.is_initialized() and dp_mesh.size() > 1:
- # FSDP1
- model = FSDP(model, device_mesh=dp_mesh, sharding_strategy=ShardingStrategy.NO_SHARD)
- # FSDP2
- # for transformer_block in model.model.layers:
- # fully_shard(transformer_block, mesh=dp_mesh, reshard_after_forward=False)
- # fully_shard(model.model, mesh=dp_mesh, reshard_after_forward=False)
- # DDP
- # replicate(model, device_mesh=dp_mesh, bucket_cap_mb=100)
- # assert len(list(model.parameters()))>5, "No parameters found in model. Probably DDP/FSDP bug.." # TODO: we should be cautious abt using model.parameters()
- use_ddp = True
-
- model.train()
- assert len(list(model.parameters())) > 0, "No parameters found in model. Probably DDP bug.."
- assert len([p for p in model.parameters() if p.requires_grad]) > 0, (
- "No gradients found in model. Probably DDP bug.."
- )
-
- if dist.is_initialized() and not ignore_sanity_checks:
- # assert model is replicated across all dp
- for name, param in model.named_parameters():
- sanity_check_tensor_sync(param, dp_mesh)
-
- # assert model is different across tp (only for sharded params)
- for name, param in model.named_parameters():
- if isinstance(param, DTensor) and param.placements[0].is_shard():
- # Only check sharded parameters for non-sync across TP
- sanity_check_tensor_sync(param, tp_mesh, not_sync=True)
- elif isinstance(param, DTensor) and param.placements[0].is_replicate():
- # Replicated parameters should be the same across TP
- sanity_check_tensor_sync(param, tp_mesh)
-
- # assert model is replicated across cp
- for name, param in model.named_parameters():
- sanity_check_tensor_sync(param, cp_mesh)
-
- # Load and preprocess TinyStories dataset
- logger.info("Loading TinyStories dataset...")
- raw_dataset = load_dataset("roneneldan/TinyStories", split="train[:1%]") # Use 1% for faster testing
-
- def tokenize_function(examples):
- # Tokenize the text without padding
- tokenized_batch = tokenizer(
- examples["text"], padding=False, truncation=True, max_length=seq_len, return_tensors=None
- )
- # Set labels to be the same as input_ids for Causal LM
- tokenized_batch["labels"] = tokenized_batch["input_ids"].copy()
- return tokenized_batch
-
- tokenized_dataset = raw_dataset.map(tokenize_function, batched=True, remove_columns=["text"])
- logger.info(f"Dataset loaded and tokenized. Size: {len(tokenized_dataset)}")
-
- # Create packed sequences
- def create_packed_sequences(examples):
- # Flatten all sequences
- all_tokens = []
- for input_ids in examples["input_ids"]:
- all_tokens.extend(input_ids)
-
- # Split into sequences of seq_len + 1 (for input + label)
- num_sequences = len(all_tokens) // (seq_len + 1)
- packed_input_ids = []
- packed_labels = []
-
- for i in range(num_sequences):
- start_idx = i * (seq_len + 1)
- end_idx = start_idx + (seq_len + 1)
- # Get the full sequence
- full_sequence = all_tokens[start_idx:end_idx]
- # For input_ids, remove the last token
- packed_input_ids.append(full_sequence[:-1])
- # For labels, remove the first token
- packed_labels.append(full_sequence[1:])
-
- return {"input_ids": packed_input_ids, "labels": packed_labels}
-
- # Apply packing to the dataset
- packed_dataset = tokenized_dataset.map(
- create_packed_sequences,
- batched=True,
- remove_columns=tokenized_dataset.column_names,
- batch_size=1000, # Process in batches for efficiency
- num_proc=60,
- )
- logger.info(f"Dataset packed. New size: {len(packed_dataset)}")
-
- # Shuffle the packed dataset
- packed_dataset = packed_dataset.shuffle(seed=42)
- logger.info("Packed dataset shuffled")
-
- # Calculate local batch size
- if dist.is_initialized():
- assert global_batch_size % dp_mesh.size() == 0, (
- f"Global batch size ({global_batch_size}) must be divisible by DP size ({dp_mesh.size()})"
- )
- local_batch_size = global_batch_size // dp_mesh.size()
- else:
- local_batch_size = global_batch_size
-
- logger.info(
- f"Global batch size: {global_batch_size}, DP size: {dp_size if dist.is_initialized() else 1}, Local batch size: {local_batch_size}"
- )
-
- # Simple collate function since sequences are already packed
- def collate_fn(batch):
- input_ids = torch.tensor([item["input_ids"] for item in batch], dtype=torch.long)
- labels = torch.tensor([item["labels"] for item in batch], dtype=torch.long)
- return {"input_ids": input_ids, "labels": labels}
-
- if dist.is_initialized():
- sampler = DistributedSampler(
- packed_dataset, num_replicas=dp_mesh.size(), rank=dp_mesh.get_local_rank(), shuffle=False
- )
- else:
- sampler = None
-
- dataloader = DataLoader(
- packed_dataset,
- batch_size=local_batch_size,
- sampler=sampler,
- shuffle=False,
- collate_fn=collate_fn,
- )
- logger.info(f"DataLoader created. Distributed: {dist.is_initialized()}")
-
- optimizer = optim.AdamW(model.parameters(), lr=LR, weight_decay=0.1)
-
- # Training loop
- logger.info(f"Starting training for {num_train_steps} steps...")
- model.train()
- step = 0
- while step < num_train_steps:
- for batch in dataloader:
- if step >= num_train_steps:
- break # Exit loop if max steps reached
-
- # Move batch to appropriate device
- batch = {k: v.to(device) for k, v in batch.items()}
-
- # Sanity checks for batch distribution (only if distributed)
- if dist.is_initialized() and not ignore_sanity_checks:
- # check batch is same across all tp
- sanity_check_tensor_sync(batch["input_ids"], tp_mesh)
- # check batch is different across dp
- sanity_check_tensor_sync(batch["input_ids"], dp_mesh, not_sync=True)
-
- optimizer.zero_grad()
-
- # Add position_ids to batch before CP sharding
- batch_size = batch["input_ids"].shape[0]
- position_ids = torch.arange(0, seq_len, dtype=torch.long, device=device)
- position_ids = position_ids.unsqueeze(0).expand(batch_size, -1)
- batch["position_ids"] = position_ids
- from torch.distributed.tensor.experimental._attention import _cp_options
-
- _cp_options.enable_load_balance = False
-
- with sdpa_kernel(sdpa_backend): # TODO: ideally move this to attention implementation
- cp_context = (
- nullcontext()
- if cp_mesh.size() == 1
- else context_parallel(
- cp_mesh,
- buffers=[
- batch["input_ids"],
- batch["labels"],
- batch["position_ids"],
- ], # TODO: need to add attention mask
- buffer_seq_dims=[1, 1, 1],
- )
- )
- with cp_context:
- # Pop labels from batch before model forward pass
- labels = batch.pop("labels")
- outputs = model(**batch) # [mbs, seq_len/cp]
- loss = outputs.loss
- logits = outputs.logits
-
- # Compute loss with shifted labels
- loss = model.loss_function(
- logits=logits, labels=None, shift_labels=labels, vocab_size=model.config.vocab_size
- )
-
- # Sanity checks for logits
- if dist.is_initialized() and not ignore_sanity_checks:
- # sanity_check_tensor_sync(logits, tp_mesh) # TODO: only true without sequence parallel
- sanity_check_tensor_sync(logits, dp_mesh, not_sync=True)
- sanity_check_tensor_sync(logits, cp_mesh, not_sync=True)
-
- loss.backward()
-
- # all reduce grads across dp_cp if applicable
- all_reduce_grads(model, world_mesh, use_ddp=use_ddp)
-
- # Sanity checks for gradients (only if distributed)
- if dist.is_initialized() and not ignore_sanity_checks:
- # check grads are not same across all tp (for sharded grads)
- for name, param in model.named_parameters():
- if param.grad is not None and isinstance(param.grad, DTensor):
- if param.grad.placements[0].is_shard():
- sanity_check_tensor_sync(param.grad, tp_mesh, not_sync=True)
- elif param.grad.placements[0].is_replicate():
- sanity_check_tensor_sync(param.grad, tp_mesh)
- # check grads are same across dp
- for name, param in model.named_parameters():
- if param.grad is not None and dp_mesh.size() > 1:
- sanity_check_tensor_sync(param.grad, dp_mesh)
- # check grads are same across cp
- for name, param in model.named_parameters():
- if param.grad is not None and cp_mesh.size() > 1:
- sanity_check_tensor_sync(param.grad, cp_mesh)
-
- # Calculate gradient norm and clip gradients
- if hasattr(model, "clip_grad_norm_"):
- # when using FSDP or DDP, model.parameters() doesn't work
- gradnorm = model.clip_grad_norm_(max_norm=1.0, norm_type=2.0)
- else:
- assert len(list(model.parameters())) > 2, "No parameters found in model. Probably DDP bug.."
- assert len([p for p in model.parameters() if p.requires_grad]) > 2, (
- "No gradients found in model. Probably DDP bug.."
- )
- assert len([p for p in model.parameters() if p.grad is not None]) > 2, (
- "No gradients found in model. Probably DDP bug.."
- )
- # only works with FSDP's NO_SHARD otherwise we should use FSDP's clip_grad_norm_
- gradnorm = clip_grad_norm_(model.parameters(), max_norm=1.0, norm_type=2.0, foreach=True)
-
- optimizer.step()
- # Sanity checks for updated model parameters (only if distributed)
- if dist.is_initialized() and not ignore_sanity_checks:
- # check updated model is different across all tp (for sharded params)
- for name, param in model.named_parameters():
- if isinstance(param, DTensor):
- if param.placements[0].is_shard():
- sanity_check_tensor_sync(param, tp_mesh, not_sync=True)
- elif param.placements[0].is_replicate():
- sanity_check_tensor_sync(param, tp_mesh)
- # check updated model is same across dp
- for name, param in model.named_parameters():
- sanity_check_tensor_sync(param, dp_mesh)
- # check updated model is same across cp
- for name, param in model.named_parameters():
- sanity_check_tensor_sync(param, cp_mesh)
-
- # allreduce loss across cp_dp before logging
- if dist.is_initialized() and (cp_mesh.size() > 1 or dp_mesh.size() > 1):
- dist.all_reduce(loss, group=world_mesh["dp_cp"].get_group(), op=dist.ReduceOp.AVG)
- current_loss = loss.item()
-
- # Log loss and gradnorm to wandb (only on rank 0 of dp group)
- if not dist.is_initialized() or dist.get_rank() == 0:
- logger.info(
- f"Step: {step} | GBS: {global_batch_size} | DP: {dp_mesh.size()} | TP: {tp_mesh.size()} | CP: {cp_mesh.size()} | Loss: {current_loss} | Gradnorm: {gradnorm} | lr: {LR}"
- )
- wandb.log(
- {
- "train/loss": current_loss,
- "train/gradnorm": gradnorm,
- "step": step,
- "lr": LR,
- "GBS": global_batch_size,
- }
- )
-
- step += 1 # Increment step count
-
- logger.info("Training loop finished.")
-
- # Save model using DCP (only if distributed)
- if dist.is_initialized():
- state_dict = {"app": AppState(model, optimizer)}
- dcp.save(
- state_dict=state_dict,
- checkpoint_id=CHECKPOINT_DIR,
- )
- logger.info(f"Saved checkpoint to {CHECKPOINT_DIR}")
- else:
- # Fallback to regular save for non-distributed case
- save_dir = "test_model_nondist"
- model.save_pretrained(save_dir)
- tokenizer.save_pretrained(save_dir) # Save tokenizer too
- logger.info(f"Saved model to {save_dir}")
-
- # Example of loading the checkpoint (only if distributed)
- if dist.is_initialized():
- # Create a new model instance
- logger.info("Creating new model instance for verification")
- new_model = AutoModelForCausalLM.from_pretrained(
- model_name,
- device_mesh=tp_mesh,
- dtype=torch.bfloat16, # Use same dtype
- )
- new_optimizer = optim.AdamW(new_model.parameters(), lr=LR)
-
- # Load checkpoint into new model
- state_dict = {"app": AppState(new_model, new_optimizer)}
- dcp.load(
- state_dict=state_dict,
- checkpoint_id=CHECKPOINT_DIR,
- )
- logger.info("Loaded checkpoint into new model")
-
- # Verify model weights match
- logger.info("Verifying model weights match...")
- for (name1, param1), (name2, param2) in zip(model.named_parameters(), new_model.named_parameters()):
- torch.testing.assert_close(
- param1.to_local(),
- param2.to_local(),
- rtol=1e-3,
- atol=1e-3,
- msg=f"Weights mismatch in {name1} vs {name2}",
- )
-
- # Verify optimizer states match
- logger.info("Verifying optimizer states match...")
- for name1, state1 in optimizer.state_dict().items():
- state2 = new_optimizer.state_dict()[name1]
- if name1 == "state":
- # Compare state dictionaries for each parameter
- for param_id, param_state1 in state1.items():
- param_state2 = state2[param_id]
- # Compare each state component (step, exp_avg, exp_avg_sq)
- for key, value1 in param_state1.items():
- value2 = param_state2[key]
- if isinstance(value1, DTensor):
- # Convert DTensors to local tensors for comparison
- torch.testing.assert_close(
- value1.to_local(),
- value2.to_local(),
- rtol=1e-5,
- atol=1e-5,
- msg=f"Optimizer state mismatch in state[{param_id}][{key}]",
- )
- else:
- torch.testing.assert_close(
- value1,
- value2,
- rtol=1e-5,
- atol=1e-5,
- msg=f"Optimizer state mismatch in state[{param_id}][{key}]",
- )
- elif name1 == "param_groups":
- # Compare param_groups (excluding the actual params list)
- for i, (group1, group2) in enumerate(zip(state1, state2)):
- for key in group1:
- if key != "params": # Skip comparing the params list
- assert group1[key] == group2[key], f"Param group mismatch in param_groups[{i}][{key}]"
-
- # Run a forward pass with both models to verify outputs match
- logger.info("Running forward pass verification...")
- with torch.no_grad():
- # Use the last batch for verification
- batch = {k: v.to(device) for k, v in batch.items()} # Ensure batch is on correct device
- original_outputs = model(**batch)
- new_outputs = new_model(**batch)
- torch.testing.assert_close(
- original_outputs.logits.to_local(),
- new_outputs.logits.to_local(),
- rtol=1e-3,
- atol=1e-3,
- msg="Model outputs do not match!",
- ) # Increased tolerance slightly for bf16
-
- # Clean up distributed environment and finish wandb run
- if dist.is_initialized():
- dist.destroy_process_group()
- logger.info("Cleaned up distributed process group")
- # Finish wandb run on rank 0
- if dist.get_rank() == 0:
- wandb.finish()
- logger.info("Wandb run finished.")
- else:
- wandb.finish()
- logger.info("Wandb run finished.")
-
-
-def all_reduce_grads(model, world_mesh, use_ddp):
- """All reduce gradients across dp_cp if applicable."""
- cp_mesh = world_mesh["cp"]
- if use_ddp:
- # DDP takes care of syncing grads
- mesh = cp_mesh
- else:
- mesh = world_mesh["dp", "cp"]._flatten(mesh_dim_name="dp_cp")
- if dist.is_initialized() and mesh.size() > 1:
- for name, param in model.named_parameters():
- if param.grad is not None:
- # Workaround for cross-mesh communication limitation with DTensor gradients
- if isinstance(param.grad, DTensor):
- local_grad = param.grad.to_local()
- # Ensure grad requires grad for inplace modification checks (might not be needed)
- # local_grad = local_grad.detach().requires_grad_(True)
- torch.distributed.all_reduce(local_grad, op=torch.distributed.ReduceOp.SUM, group=mesh.get_group())
- local_grad = local_grad / mesh.size()
- # Assign averaged grad back - need careful handling if DTensor structure is complex
- # This simple assignment might work if the grad structure matches param structure
- param.grad = DTensor.from_local(
- local_grad, device_mesh=param.grad.device_mesh, placements=param.grad.placements
- )
- else:
- # Handle regular tensors if any exist (e.g. buffers not converted to DTensor)
- torch.distributed.all_reduce(param.grad, op=torch.distributed.ReduceOp.AVG, group=mesh.get_group())
-
-
-class ContextParallelCollator:
- """Collator for context parallel training that splits sequences into chunks."""
-
- def __init__(self, cp_mesh: DeviceMesh | None = None):
- self.cp_mesh = cp_mesh
-
- def __call__(self, batch: dict[str, torch.Tensor]) -> dict[str, torch.Tensor]:
- batch = default_collate(batch)
- if self.cp_mesh is not None and self.cp_mesh.size() > 1:
- # Get sequence length from the input batch
- seq_len = batch["input_ids"].shape[1]
- assert seq_len % self.cp_mesh.size() == 0, (
- f"Sequence length {seq_len} must be divisible by CP size {self.cp_mesh.size()}"
- )
- chunk_size = seq_len // self.cp_mesh.size()
- cp_rank = self.cp_mesh.get_local_rank()
- start_idx = cp_rank * chunk_size
- end_idx = start_idx + chunk_size
-
- # Keep only the local chunk of the sequence
- batch["input_ids"] = batch["input_ids"][:, start_idx:end_idx]
- batch["attention_mask"] = batch["attention_mask"][:, start_idx:end_idx]
- batch["labels"] = batch["labels"][:, start_idx:end_idx]
-
- return batch
-
-
-class AppState(Stateful):
- """Wrapper for checkpointing the Application State including model and optimizer."""
-
- def __init__(self, model, optimizer=None):
- self.model = model
- self.optimizer = optimizer
-
- def state_dict(self):
- model_state_dict, optimizer_state_dict = get_state_dict(self.model, self.optimizer)
- return {"model": model_state_dict, "optim": optimizer_state_dict}
-
- def load_state_dict(self, state_dict):
- set_state_dict(
- self.model, self.optimizer, model_state_dict=state_dict["model"], optim_state_dict=state_dict["optim"]
- )
-
-
-def sanity_check_tensor_sync(
- tensor: torch.Tensor, mesh: DeviceMesh, rtol: float = 1e-4, atol: float = 1e-4, not_sync: bool = False
-) -> None:
- """
- Verify that a tensor is synchronized (or not synchronized) across all processes in the mesh's process group.
- Handles both regular tensors and DTensors.
-
- Args:
- tensor (torch.Tensor): The tensor to check for synchronization (can be DTensor)
- mesh (DeviceMesh): The device mesh containing the process group
- rtol (float): Relative tolerance for comparison
- atol (float): Absolute tolerance for comparison
- not_sync (bool): If True, asserts that tensors are NOT synchronized. If False, asserts they are synchronized.
- """
- if not dist.is_initialized() or mesh.size() == 1:
- return # No need to check in non-distributed mode
-
- # Get the process group from the mesh
- pg = mesh.get_group()
-
- # Convert DTensor to local tensor if needed
- if hasattr(tensor, "to_local"):
- local_tensor = tensor.to_local()
- else:
- local_tensor = tensor
-
- # Gather tensors from all processes
- world_size = dist.get_world_size(pg)
- gathered_tensors = [torch.empty_like(local_tensor) for _ in range(world_size)]
- dist.all_gather(gathered_tensors, local_tensor, group=pg)
-
- # Compare each tensor with the first one
- for i in range(1, world_size):
- try:
- torch.testing.assert_close(gathered_tensors[0], gathered_tensors[i], rtol=rtol, atol=atol)
- except AssertionError as e:
- if not_sync:
- continue
- # # Add detailed debugging for logit synchronization issues
- # print(f"\nLogit synchronization error between rank 0 and rank {i}:")
- # print(f"Tensor shape: {gathered_tensors[0].shape}")
- # print(f"Number of mismatched elements: {(gathered_tensors[0] != gathered_tensors[i]).sum()}")
- # print(f"Percentage of mismatched elements: {((gathered_tensors[0] != gathered_tensors[i]).sum() / gathered_tensors[0].numel() * 100):.2f}%")
-
- # # Find the first few mismatches
- # mismatches = torch.nonzero(gathered_tensors[0] != gathered_tensors[i])
- # print("\nFirst few mismatches:")
- # for idx in mismatches[:5]:
- # idx = tuple(idx.tolist())
- # print(f"Index {idx}:")
- # print(f"Rank 0 value: {gathered_tensors[0][idx]}")
- # print(f"Rank {i} value: {gathered_tensors[i][idx]}")
- # print(f"Absolute difference: {abs(gathered_tensors[0][idx] - gathered_tensors[i][idx])}")
- # print(f"Relative difference: {abs(gathered_tensors[0][idx] - gathered_tensors[i][idx]) / max(abs(gathered_tensors[0][idx]), abs(gathered_tensors[i][idx]))}")
-
- # # Check if differences are systematic (e.g., all positive or negative)
- # diff = gathered_tensors[0] - gathered_tensors[i]
- # print(f"\nDifference statistics:")
- # print(f"Mean difference: {diff.mean()}")
- # print(f"Std difference: {diff.std()}")
- # print(f"Max positive difference: {diff.max()}")
- # print(f"Max negative difference: {diff.min()}")
- raise e
-
-
-def clip_grad_norm_(
- parameters: Iterable[torch.Tensor],
- max_norm: float,
- norm_type: float = 2.0,
- error_if_nonfinite: bool = False,
- foreach: bool | None = None,
-) -> torch.Tensor:
- """
- Clip the gradient norm of an iterable of parameters.
- """
- # Filter out parameters with no gradients
- parameters = [p for p in parameters if p.grad is not None]
- assert len(parameters) > 0, "No parameters with gradients found"
-
- # Calculate total norm
- if norm_type == float("inf"):
- total_norm = max(p.grad.detach().abs().max() for p in parameters)
- else:
- total_norm = torch.norm(torch.stack([torch.norm(p.grad.detach(), norm_type) for p in parameters]), norm_type)
-
- # Convert DTensor to local tensor if needed
- if isinstance(total_norm, DTensor):
- total_norm = total_norm.full_tensor()
-
- # Clip gradients
- clip_coef = max_norm / (total_norm + 1e-6)
- if clip_coef < 1:
- for p in parameters:
- p.grad.detach().mul_(clip_coef)
-
- return total_norm
-
-
-def check_params_sync(model_params, original_params):
- """
- Check if original_params are being updated in sync with model parameters.
-
- Args:
- model_params: Iterator of model parameters after update
- original_params: List of original parameters before DDP wrapping
- """
- for mp, op in zip(model_params, original_params):
- if isinstance(mp, DTensor):
- mp = mp.to_local()
- if isinstance(op, DTensor):
- op = op.to_local()
- if not torch.allclose(mp.data, op.data, rtol=0, atol=0):
- raise RuntimeError(f"Parameters out of sync: model param {mp.data} != original param {op.data}")
- return True
-
-
-def get_parameters(model: nn.Module) -> Iterable[torch.Tensor]:
- """
- Get all parameters from a model by iterating over its modules.
- This is an alternative to model.parameters() that works with DTensor models.
-
- Args:
- model (nn.Module): The model to get parameters from
-
- Returns:
- Iterable[torch.Tensor]: An iterator over all parameters in the model
- """
- for module in model._modules.values():
- # Look for parameters in module attributes
- for attr in module.__dict__.values():
- if isinstance(attr, torch.Tensor) and attr.requires_grad:
- yield attr
- # Recursively get parameters from submodules
- yield from get_parameters(module)
-
-
-def update_model_parameters(model: nn.Module) -> None:
- """
- Update model._parameters using named_modules() to ensure all parameters are properly tracked.
-
- Args:
- model (nn.Module): The model to update parameters for
- """
- # Clear existing parameters
- model._parameters = {}
-
- # Add parameters from named_modules
- for name, module in model.named_modules():
- # Skip the root module itself
- if name == "":
- continue
-
- # Get the parameter name by removing 'module.' prefix if it exists
- param_name = name.replace("module.", "")
-
- # Add weight and bias parameters if they exist
- if hasattr(module, "weight") and module.weight is not None:
- model._parameters[f"{param_name}.weight"] = module.weight
- if hasattr(module, "bias") and module.bias is not None:
- model._parameters[f"{param_name}.bias"] = module.bias
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/README.md b/examples/pytorch/README.md
deleted file mode 100644
index 2712ee047d50..000000000000
--- a/examples/pytorch/README.md
+++ /dev/null
@@ -1,293 +0,0 @@
-
-
-# Examples
-
-This folder contains actively maintained examples of use of 🤗 Transformers using the PyTorch backend, organized by ML task.
-
-## The Big Table of Tasks
-
-Here is the list of all our examples:
-- with information on whether they are **built on top of `Trainer`** (if not, they still work, they might
- just lack some features),
-- whether or not they have a version using the [🤗 Accelerate](https://github.com/huggingface/accelerate) library.
-- whether or not they leverage the [🤗 Datasets](https://github.com/huggingface/datasets) library.
-- links to **Colab notebooks** to walk through the scripts and run them easily,
-
-
-| Task | Example datasets | Trainer support | 🤗 Accelerate | 🤗 Datasets | Colab
-|---|---|:---:|:---:|:---:|:---:|
-| [**`language-modeling`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling) | [WikiText-2](https://huggingface.co/datasets/Salesforce/wikitext) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
-| [**`multiple-choice`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/multiple-choice) | [SWAG](https://huggingface.co/datasets/allenai/swag) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
-| [**`question-answering`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering) | [SQuAD](https://huggingface.co/datasets/rajpurkar/squad) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
-| [**`summarization`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) | [XSum](https://huggingface.co/datasets/EdinburghNLP/xsum) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
-| [**`text-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification) | [GLUE](https://huggingface.co/datasets/nyu-mll/glue) | ✅ | ✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)
-| [**`text-generation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation) | - | n/a | - | - | [](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/02_how_to_generate.ipynb)
-| [**`token-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/token-classification) | [CoNLL NER](https://huggingface.co/datasets/tomaarsen/conll2003) | ✅ |✅ | ✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
-| [**`translation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/translation) | [WMT](https://huggingface.co/datasets/wmt/wmt17) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)
-| [**`speech-recognition`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/speech-recognition) | [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/speech_recognition.ipynb)
-| [**`multi-lingual speech-recognition`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/speech-recognition) | [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multi_lingual_speech_recognition.ipynb)
-| [**`audio-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/audio-classification) | [SUPERB KS](https://huggingface.co/datasets/s3prl/superb) | ✅ | - |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb)
-| [**`image-pretraining`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining) | [ImageNet-1k](https://huggingface.co/datasets/ILSVRC/imagenet-1k) | ✅ | - |✅ | /
-| [**`image-classification`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) | [CIFAR-10](https://huggingface.co/datasets/uoft-cs/cifar10) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)
-| [**`semantic-segmentation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) | [SCENE_PARSE_150](https://huggingface.co/datasets/merve/scene_parse_150) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb)
-| [**`object-detection`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection) | [CPPE-5](https://huggingface.co/datasets/rishitdagli/cppe-5) | ✅ | ✅ |✅ | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/pytorch/object_detection.ipynb)
-| [**`instance-segmentation`**](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation) | [ADE20K sample](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) | ✅ | ✅ |✅ |
-
-
-## Running quick tests
-
-Most examples are equipped with a mechanism to truncate the number of dataset samples to the desired length. This is useful for debugging purposes, for example to quickly check that all stages of the programs can complete, before running the same setup on the full dataset which may take hours to complete.
-
-For example here is how to truncate all three splits to just 50 samples each:
-```bash
-examples/pytorch/token-classification/run_ner.py \
---max_train_samples 50 \
---max_eval_samples 50 \
---max_predict_samples 50 \
-[...]
-```
-
-Most example scripts should have the first two command line arguments and some have the third one. You can quickly check if a given example supports any of these by passing a `-h` option, e.g.:
-```bash
-token-classification/run_ner.py -h
-```
-
-## Resuming training
-
-You can resume training from a previous checkpoint like this:
-
-1. Pass `--resume_from_checkpoint path_to_a_specific_checkpoint` to resume training from that checkpoint folder.
-
-Should you want to turn an example into a notebook where you'd no longer have access to the command
-line, 🤗 Trainer supports resuming from a checkpoint via `trainer.train(resume_from_checkpoint)`.
-
-1. If `resume_from_checkpoint` is `True` it will look for the last checkpoint in the value of `output_dir` passed via `TrainingArguments`.
-2. If `resume_from_checkpoint` is a path to a specific checkpoint it will use that saved checkpoint folder to resume the training from.
-
-
-### Upload the trained/fine-tuned model to the Hub
-
-All the example scripts support automatic upload of your final model to the [Model Hub](https://huggingface.co/models) by adding a `--push_to_hub` argument. It will then create a repository with your username slash the name of the folder you are using as `output_dir`. For instance, `"sgugger/test-mrpc"` if your username is `sgugger` and you are working in the folder `~/tmp/test-mrpc`.
-
-To specify a given repository name, use the `--hub_model_id` argument. You will need to specify the whole repository name (including your username), for instance `--hub_model_id sgugger/finetuned-bert-mrpc`. To upload to an organization you are a member of, just use the name of that organization instead of your username: `--hub_model_id huggingface/finetuned-bert-mrpc`.
-
-A few notes on this integration:
-
-- you will need to be logged in to the Hugging Face website locally for it to work, the easiest way to achieve this is to run `hf auth login` and then type your username and password when prompted. You can also pass along your authentication token with the `--hub_token` argument.
-- the `output_dir` you pick will either need to be a new folder or a local clone of the distant repository you are using.
-
-## Distributed training and mixed precision
-
-All the PyTorch scripts mentioned above work out of the box with distributed training and mixed precision, thanks to
-the [Trainer API](https://huggingface.co/transformers/main_classes/trainer.html). To launch one of them on _n_ GPUs,
-use the following command:
-
-```bash
-torchrun \
- --nproc_per_node number_of_gpu_you_have path_to_script.py \
- --all_arguments_of_the_script
-```
-
-As an example, here is how you would fine-tune the BERT large model (with whole word masking) on the text
-classification MNLI task using the `run_glue` script, with 8 GPUs:
-
-```bash
-torchrun \
- --nproc_per_node 8 text-classification/run_glue.py \
- --model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
- --task_name mnli \
- --do_train \
- --do_eval \
- --max_seq_length 128 \
- --per_device_train_batch_size 8 \
- --learning_rate 2e-5 \
- --num_train_epochs 3.0 \
- --output_dir /tmp/mnli_output/
-```
-
-If you have a GPU with mixed precision capabilities (architecture Pascal or more recent), you can use mixed precision
-training with PyTorch 1.6.0 or latest. Just add the flag `--fp16` to your command launching one of the scripts mentioned above!
-
-Using mixed precision training usually results in 2x-speedup for training with the same final results (as shown in
-[this table](https://github.com/huggingface/transformers/tree/main/examples/text-classification#mixed-precision-training)
-for text classification).
-
-## Running on TPUs
-
-When using Tensorflow, TPUs are supported out of the box as a `tf.distribute.Strategy`.
-
-When using PyTorch, we support TPUs thanks to `pytorch/xla`. For more context and information on how to setup your TPU environment refer to Google's documentation and to the
-very detailed [pytorch/xla README](https://github.com/pytorch/xla/blob/master/README.md).
-
-In this repo, we provide a very simple launcher script named
-[xla_spawn.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/xla_spawn.py) that lets you run our
-example scripts on multiple TPU cores without any boilerplate. Just pass a `--num_cores` flag to this script, then your
-regular training script with its arguments (this is similar to the `torch.distributed.launch` helper for
-`torch.distributed`):
-
-```bash
-python xla_spawn.py --num_cores num_tpu_you_have \
- path_to_script.py \
- --all_arguments_of_the_script
-```
-
-As an example, here is how you would fine-tune the BERT large model (with whole word masking) on the text
-classification MNLI task using the `run_glue` script, with 8 TPUs (from this folder):
-
-```bash
-python xla_spawn.py --num_cores 8 \
- text-classification/run_glue.py \
- --model_name_or_path google-bert/bert-large-uncased-whole-word-masking \
- --task_name mnli \
- --do_train \
- --do_eval \
- --max_seq_length 128 \
- --per_device_train_batch_size 8 \
- --learning_rate 2e-5 \
- --num_train_epochs 3.0 \
- --output_dir /tmp/mnli_output/
-```
-
-## Using Accelerate
-
-Most PyTorch example scripts have a version using the [🤗 Accelerate](https://github.com/huggingface/accelerate) library
-that exposes the training loop so it's easy for you to customize or tweak them to your needs. They all require you to
-install `accelerate` with the latest development version
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-Then you can easily launch any of the scripts by running
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch path_to_script.py --args_to_script
-```
-
-## Logging & Experiment tracking
-
-You can easily log and monitor your runs code. The following are currently supported:
-
-* [TensorBoard](https://www.tensorflow.org/tensorboard)
-* [Weights & Biases](https://docs.wandb.ai/integrations/huggingface)
-* [Comet ML](https://www.comet.com/docs/v2/integrations/ml-frameworks/transformers/)
-* [ClearML](https://clear.ml/docs/latest/docs/getting_started/ds/ds_first_steps)
-* [DVCLive](https://dvc.org/doc/dvclive/ml-frameworks/huggingface)
-
-### Weights & Biases
-
-To use Weights & Biases, install the wandb package with:
-
-```bash
-pip install wandb
-```
-
-Then log in the command line:
-
-```bash
-wandb login
-```
-
-If you are in Jupyter or Colab, you should login with:
-
-```python
-import wandb
-wandb.login()
-```
-
-To enable logging to W&B, include `"wandb"` in the `report_to` of your `TrainingArguments` or script. Or just pass along `--report_to_all` if you have `wandb` installed.
-
-Whenever you use the `Trainer` class, your losses, evaluation metrics, model topology and gradients will automatically be logged.
-
-Advanced configuration is possible by setting environment variables:
-
-| Environment Variable | Value |
-|---|---|
-| WANDB_LOG_MODEL | Log the model as artifact (log the model as artifact at the end of training) (`false` by default) |
-| WANDB_WATCH | one of `gradients` (default) to log histograms of gradients, `all` to log histograms of both gradients and parameters, or `false` for no histogram logging |
-| WANDB_PROJECT | Organize runs by project |
-
-Set run names with `run_name` argument present in scripts or as part of `TrainingArguments`.
-
-Additional configuration options are available through generic [wandb environment variables](https://docs.wandb.com/library/environment-variables).
-
-Refer to related [documentation & examples](https://docs.wandb.ai/integrations/huggingface).
-
-### Comet
-
-To use `comet_ml`, install the Python package with:
-
-```bash
-pip install comet_ml
-```
-
-or if in a Conda environment:
-
-```bash
-conda install -c comet_ml -c anaconda -c conda-forge comet_ml
-```
-
-### ClearML
-
-To use ClearML, install the clearml package with:
-
-```bash
-pip install clearml
-```
-
-Then [create new credentials]() from the ClearML Server. You can get a free hosted server [here]() or [self-host your own]()!
-After creating your new credentials, you can either copy the local snippet which you can paste after running:
-
-```bash
-clearml-init
-```
-
-Or you can copy the jupyter snippet if you are in Jupyter or Colab:
-
-```python
-%env CLEARML_WEB_HOST=https://app.clear.ml
-%env CLEARML_API_HOST=https://api.clear.ml
-%env CLEARML_FILES_HOST=https://files.clear.ml
-%env CLEARML_API_ACCESS_KEY=***
-%env CLEARML_API_SECRET_KEY=***
-```
-
-
-To enable logging to ClearML, include `"clearml"` in the `report_to` of your `TrainingArguments` or script. Or just pass along `--report_to all` if you have `clearml` already installed.
-
-Advanced configuration is possible by setting environment variables:
-
-| Environment Variable | Value |
-|---|---|
-| CLEARML_PROJECT | Name of the project in ClearML. (default: `"HuggingFace Transformers"`) |
-| CLEARML_TASK | Name of the task in ClearML. (default: `"Trainer"`) |
-
-Additional configuration options are available through generic [clearml environment variables](https://clear.ml/docs/latest/docs/configs/env_vars).
diff --git a/examples/pytorch/_tests_requirements.txt b/examples/pytorch/_tests_requirements.txt
deleted file mode 100644
index 210f560740b3..000000000000
--- a/examples/pytorch/_tests_requirements.txt
+++ /dev/null
@@ -1,33 +0,0 @@
-tensorboard
-scikit-learn
-seqeval
-psutil
-sacrebleu >= 1.4.12
-git+https://github.com/huggingface/accelerate@main#egg=accelerate
-rouge-score
-tensorflow_datasets
-matplotlib
-git-python==1.0.3
-faiss-cpu
-streamlit
-elasticsearch
-nltk
-pandas
-datasets >= 1.13.3
-fire
-pytest
-conllu
-sentencepiece != 0.1.92
-protobuf
-torch
-torchvision
-torchaudio
-torchcodec
-jiwer
-librosa
-evaluate >= 0.2.0
-timm
-albumentations >= 1.4.16
-torchmetrics
-pycocotools
-Pillow>=10.0.1,<=15.0
diff --git a/examples/pytorch/audio-classification/README.md b/examples/pytorch/audio-classification/README.md
deleted file mode 100644
index 6802e9263715..000000000000
--- a/examples/pytorch/audio-classification/README.md
+++ /dev/null
@@ -1,146 +0,0 @@
-
-
-# Audio classification examples
-
-The following examples showcase how to fine-tune `Wav2Vec2` for audio classification using PyTorch.
-
-Speech recognition models that have been pretrained in unsupervised fashion on audio data alone,
-*e.g.* [Wav2Vec2](https://huggingface.co/transformers/main/model_doc/wav2vec2.html),
-[HuBERT](https://huggingface.co/transformers/main/model_doc/hubert.html),
-[XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html), have shown to require only
-very little annotated data to yield good performance on speech classification datasets.
-
-## Single-GPU
-
-The following command shows how to fine-tune [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) on the 🗣️ [Keyword Spotting subset](https://huggingface.co/datasets/s3prl/superb#ks) of the SUPERB dataset.
-
-```bash
-python run_audio_classification.py \
- --model_name_or_path facebook/wav2vec2-base \
- --dataset_name s3prl/superb \
- --dataset_config_name ks \
- --output_dir wav2vec2-base-ft-keyword-spotting \
- --remove_unused_columns False \
- --do_train \
- --do_eval \
- --fp16 \
- --learning_rate 3e-5 \
- --max_length_seconds 1 \
- --attention_mask False \
- --warmup_steps 0.1 \
- --num_train_epochs 5 \
- --per_device_train_batch_size 32 \
- --gradient_accumulation_steps 4 \
- --per_device_eval_batch_size 32 \
- --dataloader_num_workers 4 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --metric_for_best_model accuracy \
- --save_total_limit 3 \
- --seed 0 \
- --push_to_hub
-```
-
-On a single V100 GPU (16GB), this script should run in ~14 minutes and yield accuracy of **98.26%**.
-
-👀 See the results here: [anton-l/wav2vec2-base-ft-keyword-spotting](https://huggingface.co/anton-l/wav2vec2-base-ft-keyword-spotting)
-
-> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
-
-## Multi-GPU
-
-The following command shows how to fine-tune [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) for 🌎 **Language Identification** on the [CommonLanguage dataset](https://huggingface.co/datasets/regisss/common_language).
-
-```bash
-python run_audio_classification.py \
- --model_name_or_path facebook/wav2vec2-base \
- --dataset_name regisss/common_language \
- --audio_column_name audio \
- --label_column_name language \
- --output_dir wav2vec2-base-lang-id \
- --remove_unused_columns False \
- --do_train \
- --do_eval \
- --fp16 \
- --learning_rate 3e-4 \
- --max_length_seconds 16 \
- --attention_mask False \
- --warmup_steps 0.1 \
- --num_train_epochs 10 \
- --per_device_train_batch_size 8 \
- --gradient_accumulation_steps 4 \
- --per_device_eval_batch_size 1 \
- --dataloader_num_workers 8 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --metric_for_best_model accuracy \
- --save_total_limit 3 \
- --seed 0 \
- --push_to_hub
-```
-
-On 4 V100 GPUs (16GB), this script should run in ~1 hour and yield accuracy of **79.45%**.
-
-👀 See the results here: [anton-l/wav2vec2-base-lang-id](https://huggingface.co/anton-l/wav2vec2-base-lang-id)
-
-## Sharing your model on 🤗 Hub
-
-0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
-
-1. Make sure you have `git-lfs` installed and git set up.
-
-```bash
-$ apt install git-lfs
-```
-
-2. Log in with your HuggingFace account credentials using `hf`
-
-```bash
-$ hf auth login
-# ...follow the prompts
-```
-
-3. When running the script, pass the following arguments:
-
-```bash
-python run_audio_classification.py \
- --push_to_hub \
- --hub_model_id \
- ...
-```
-
-### Examples
-
-The following table shows a couple of demonstration fine-tuning runs.
-It has been verified that the script works for the following datasets:
-
-- [SUPERB Keyword Spotting](https://huggingface.co/datasets/s3prl/superb#ks)
-- [Common Language](https://huggingface.co/datasets/regisss/common_language)
-
-| Dataset | Pretrained Model | # transformer layers | Accuracy on eval | GPU setup | Training time | Fine-tuned Model & Logs |
-|---------|------------------|----------------------|------------------|-----------|---------------|--------------------------|
-| Keyword Spotting | [ntu-spml/distilhubert](https://huggingface.co/ntu-spml/distilhubert) | 2 | 0.9706 | 1 V100 GPU | 11min | [here](https://huggingface.co/anton-l/distilhubert-ft-keyword-spotting) |
-| Keyword Spotting | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 12 | 0.9826 | 1 V100 GPU | 14min | [here](https://huggingface.co/anton-l/wav2vec2-base-ft-keyword-spotting) |
-| Keyword Spotting | [facebook/hubert-base-ls960](https://huggingface.co/facebook/hubert-base-ls960) | 12 | 0.9819 | 1 V100 GPU | 14min | [here](https://huggingface.co/anton-l/hubert-base-ft-keyword-spotting) |
-| Keyword Spotting | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 24 | 0.9757 | 1 V100 GPU | 15min | [here](https://huggingface.co/anton-l/sew-mid-100k-ft-keyword-spotting) |
-| Common Language | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 12 | 0.7945 | 4 V100 GPUs | 1h10m | [here](https://huggingface.co/anton-l/wav2vec2-base-lang-id) |
diff --git a/examples/pytorch/audio-classification/requirements.txt b/examples/pytorch/audio-classification/requirements.txt
deleted file mode 100644
index d23b9b86f190..000000000000
--- a/examples/pytorch/audio-classification/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-datasets[audio]>=1.14.0
-evaluate
-librosa
-torchaudio
-torch>=1.6
diff --git a/examples/pytorch/audio-classification/run_audio_classification.py b/examples/pytorch/audio-classification/run_audio_classification.py
deleted file mode 100644
index 844cbe7fb795..000000000000
--- a/examples/pytorch/audio-classification/run_audio_classification.py
+++ /dev/null
@@ -1,401 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets[audio]>=1.14.0",
-# "evaluate",
-# "librosa",
-# "torchaudio",
-# "torch>=1.6",
-# ]
-# ///
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-from random import randint
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import DatasetDict, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoFeatureExtractor,
- AutoModelForAudioClassification,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.14.0", "To fix: pip install -r examples/pytorch/audio-classification/requirements.txt")
-
-
-def random_subsample(wav: np.ndarray, max_length: float, sample_rate: int = 16000):
- """Randomly sample chunks of `max_length` seconds from the input audio"""
- sample_length = int(round(sample_rate * max_length))
- if len(wav) <= sample_length:
- return wav
- random_offset = randint(0, len(wav) - sample_length - 1)
- return wav[random_offset : random_offset + sample_length]
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- dataset_name: str | None = field(default=None, metadata={"help": "Name of a dataset from the datasets package"})
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(
- default=None, metadata={"help": "A file containing the training audio paths and labels."}
- )
- eval_file: str | None = field(
- default=None, metadata={"help": "A file containing the validation audio paths and labels."}
- )
- train_split_name: str = field(
- default="train",
- metadata={
- "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
- },
- )
- eval_split_name: str = field(
- default="validation",
- metadata={
- "help": (
- "The name of the training data set split to use (via the datasets library). Defaults to 'validation'"
- )
- },
- )
- audio_column_name: str = field(
- default="audio",
- metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
- )
- label_column_name: str = field(
- default="label", metadata={"help": "The name of the dataset column containing the labels. Defaults to 'label'"}
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_length_seconds: float = field(
- default=20,
- metadata={"help": "Audio clips will be randomly cut to this length during training if the value is set."},
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- default="facebook/wav2vec2-base",
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from the Hub"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- feature_extractor_name: str | None = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- freeze_feature_encoder: bool = field(
- default=True, metadata={"help": "Whether to freeze the feature encoder layers of the model."}
- )
- attention_mask: bool = field(
- default=True, metadata={"help": "Whether to generate an attention mask in the feature extractor."}
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Initialize our dataset and prepare it for the audio classification task.
- raw_datasets = DatasetDict()
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.train_split_name,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- raw_datasets["eval"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.eval_split_name,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- if data_args.audio_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--audio_column_name {data_args.audio_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--audio_column_name` to the correct audio column - one of "
- f"{', '.join(raw_datasets['train'].column_names)}."
- )
-
- if data_args.label_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--label_column_name {data_args.label_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--label_column_name` to the correct text column - one of "
- f"{', '.join(raw_datasets['train'].column_names)}."
- )
-
- # Setting `return_attention_mask=True` is the way to get a correctly masked mean-pooling over
- # transformer outputs in the classifier, but it doesn't always lead to better accuracy
- feature_extractor = AutoFeatureExtractor.from_pretrained(
- model_args.feature_extractor_name or model_args.model_name_or_path,
- return_attention_mask=model_args.attention_mask,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # `datasets` takes care of automatically loading and resampling the audio,
- # so we just need to set the correct target sampling rate.
- raw_datasets = raw_datasets.cast_column(
- data_args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
- )
-
- model_input_name = feature_extractor.model_input_names[0]
-
- def train_transforms(batch):
- """Apply train_transforms across a batch."""
- subsampled_wavs = []
- for audio in batch[data_args.audio_column_name]:
- wav = random_subsample(
- audio["array"], max_length=data_args.max_length_seconds, sample_rate=feature_extractor.sampling_rate
- )
- subsampled_wavs.append(wav)
- inputs = feature_extractor(subsampled_wavs, sampling_rate=feature_extractor.sampling_rate)
- output_batch = {model_input_name: inputs.get(model_input_name)}
- output_batch["labels"] = list(batch[data_args.label_column_name])
-
- return output_batch
-
- def val_transforms(batch):
- """Apply val_transforms across a batch."""
- wavs = [audio["array"] for audio in batch[data_args.audio_column_name]]
- inputs = feature_extractor(wavs, sampling_rate=feature_extractor.sampling_rate)
- output_batch = {model_input_name: inputs.get(model_input_name)}
- output_batch["labels"] = list(batch[data_args.label_column_name])
-
- return output_batch
-
- # Prepare label mappings.
- # We'll include these in the model's config to get human readable labels in the Inference API.
- labels = raw_datasets["train"].features[data_args.label_column_name].names
- label2id, id2label = {}, {}
- for i, label in enumerate(labels):
- label2id[label] = str(i)
- id2label[str(i)] = label
-
- # Load the accuracy metric from the datasets package
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
-
- # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with
- # `predictions` and `label_ids` fields) and has to return a dictionary string to float.
- def compute_metrics(eval_pred):
- """Computes accuracy on a batch of predictions"""
- predictions = np.argmax(eval_pred.predictions, axis=1)
- return metric.compute(predictions=predictions, references=eval_pred.label_ids)
-
- config = AutoConfig.from_pretrained(
- model_args.config_name or model_args.model_name_or_path,
- num_labels=len(labels),
- label2id=label2id,
- id2label=id2label,
- finetuning_task="audio-classification",
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForAudioClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
-
- # freeze the convolutional waveform encoder
- if model_args.freeze_feature_encoder:
- model.freeze_feature_encoder()
-
- if training_args.do_train:
- if data_args.max_train_samples is not None:
- raw_datasets["train"] = (
- raw_datasets["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
- )
- # Set the training transforms
- raw_datasets["train"].set_transform(train_transforms, output_all_columns=False)
-
- if training_args.do_eval:
- if data_args.max_eval_samples is not None:
- raw_datasets["eval"] = (
- raw_datasets["eval"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
- )
- # Set the validation transforms
- raw_datasets["eval"].set_transform(val_transforms, output_all_columns=False)
-
- # Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=raw_datasets["train"] if training_args.do_train else None,
- eval_dataset=raw_datasets["eval"] if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=feature_extractor,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "audio-classification",
- "dataset": data_args.dataset_name,
- "tags": ["audio-classification"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/conftest.py b/examples/pytorch/conftest.py
deleted file mode 100644
index 7d7a38084f9b..000000000000
--- a/examples/pytorch/conftest.py
+++ /dev/null
@@ -1,47 +0,0 @@
-# Copyright 2020 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# tests directory-specific settings - this file is run automatically
-# by pytest before any tests are run
-
-import sys
-import warnings
-from os.path import abspath, dirname, join
-
-
-# allow having multiple repository checkouts and not needing to remember to rerun
-# `pip install -e '.[dev]'` when switching between checkouts and running tests.
-git_repo_path = abspath(join(dirname(dirname(dirname(__file__))), "src"))
-sys.path.insert(1, git_repo_path)
-tests_path = abspath(join(dirname(dirname(dirname(__file__))), "tests"))
-sys.path.insert(1, tests_path)
-
-
-# silence FutureWarning warnings in tests since often we can't act on them until
-# they become normal warnings - i.e. the tests still need to test the current functionality
-warnings.simplefilter(action="ignore", category=FutureWarning)
-
-
-def pytest_addoption(parser):
- from transformers.testing_utils import pytest_addoption_shared
-
- pytest_addoption_shared(parser)
-
-
-def pytest_terminal_summary(terminalreporter):
- from transformers.testing_utils import pytest_terminal_summary_main
-
- make_reports = terminalreporter.config.getoption("--make-reports")
- if make_reports:
- pytest_terminal_summary_main(terminalreporter, id=make_reports)
diff --git a/examples/pytorch/context_parallel.py b/examples/pytorch/context_parallel.py
deleted file mode 100644
index d24ff45873db..000000000000
--- a/examples/pytorch/context_parallel.py
+++ /dev/null
@@ -1,94 +0,0 @@
-# Copyright 2024 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-import os
-
-import torch
-import torch.distributed as dist
-from torch.distributed.device_mesh import init_device_mesh
-from torch.distributed.tensor.experimental import context_parallel
-from torch.nn.attention import SDPBackend, sdpa_kernel
-from torch.nn.parallel import DistributedDataParallel as DDP
-
-from transformers import AutoModelForCausalLM
-from transformers.loss.loss_utils import ForCausalLMLoss
-
-
-world_size = int(os.environ.get("WORLD_SIZE", "1"))
-cp_mesh = init_device_mesh("cuda", (world_size,))
-rank = torch.distributed.get_node_local_rank()
-
-device = "cuda"
-dtype = torch.bfloat16
-sdpa_backend = SDPBackend.FLASH_ATTENTION
-
-# prepare inputs
-batch_size = 1
-seq_len = 128
-
-input_ids = torch.randint(low=8, high=64, size=(batch_size, seq_len), device=device)
-
-ignore_index = -100
-# When using CP, we need to use `shift_labels`
-shift_labels = torch.nn.functional.pad(input_ids, (0, 1), value=ignore_index)
-shift_labels = shift_labels[..., 1:].contiguous()
-
-position_ids = (
- torch.cumsum(torch.ones(size=input_ids.size(), dtype=input_ids.dtype, device=input_ids.device), dim=1) - 1
-)
-
-# sync input as they are created randomly
-dist.broadcast(input_ids, src=0)
-dist.broadcast(shift_labels, src=0)
-dist.broadcast(position_ids, src=0)
-
-# model and optimizer
-repo_id = "Qwen/Qwen2.5-Coder-0.5B-Instruct"
-model = AutoModelForCausalLM.from_pretrained(repo_id, dtype=dtype, device_map=device)
-optimizer = torch.optim.Adam(model.parameters(), lr=1e-5)
-
-model.train()
-model.zero_grad()
-optimizer.zero_grad()
-
-# For loss
-vocab_size = model.config.vocab_size
-
-# so training could be synced
-model = DDP(model, device_ids=[rank])
-
-# prepare for CP
-buffers = (input_ids, shift_labels, position_ids)
-buffer_seq_dims = (1, 1, 1)
-# `no_restore_buffers=set(buffers)` is required if `loss.backward` is outside `context_parallel`.
-# no_restore_buffers = set(buffers)
-no_restore_buffers = None
-
-# run with CP
-with sdpa_kernel(sdpa_backend):
- with context_parallel(
- cp_mesh,
- buffers=buffers,
- buffer_seq_dims=buffer_seq_dims,
- no_restore_buffers=no_restore_buffers,
- ):
- outputs = model(input_ids, shift_labels=shift_labels, position_ids=position_ids)
- print(outputs.logits.shape)
-
- # So far we need to compute `loss` outside `model.forward` when using `shift_labels`
- # loss = outputs.loss
- loss = ForCausalLMLoss(logits=outputs.logits, labels=None, shift_labels=shift_labels, vocab_size=vocab_size)
-
- # This could be outside `context_parallel` context if `no_restore_buffers` is specified
- loss.backward()
- optimizer.step()
diff --git a/examples/pytorch/contrastive-image-text/README.md b/examples/pytorch/contrastive-image-text/README.md
deleted file mode 100644
index 9211c0cc59f9..000000000000
--- a/examples/pytorch/contrastive-image-text/README.md
+++ /dev/null
@@ -1,101 +0,0 @@
-
-
-# VisionTextDualEncoder and CLIP model training examples
-
-The following example showcases how to train a CLIP-like vision-text dual encoder model
-using a pre-trained vision and text encoder.
-
-Such a model can be used for natural language image search and potentially zero-shot image classification.
-The model is inspired by [CLIP](https://openai.com/blog/clip/), introduced by Alec Radford et al.
-The idea is to train a vision encoder and a text encoder jointly to project the representation of images and their
-captions into the same embedding space, such that the caption embeddings are located near the embeddings
-of the images they describe.
-
-### Download COCO dataset (2017)
-This example uses COCO dataset (2017) through a custom dataset script, which requires users to manually download the
-COCO dataset before training.
-
-```bash
-mkdir data
-cd data
-wget http://images.cocodataset.org/zips/train2017.zip
-wget http://images.cocodataset.org/zips/val2017.zip
-wget http://images.cocodataset.org/zips/test2017.zip
-wget http://images.cocodataset.org/annotations/annotations_trainval2017.zip
-wget http://images.cocodataset.org/annotations/image_info_test2017.zip
-cd ..
-```
-
-Having downloaded COCO dataset manually you should be able to load with the `ydshieh/coc_dataset_script` dataset loading script:
-
-```py
-import os
-import datasets
-
-COCO_DIR = os.path.join(os.getcwd(), "data")
-ds = datasets.load_dataset("ydshieh/coco_dataset_script", "2017", data_dir=COCO_DIR)
-```
-
-### Create a model from a vision encoder model and a text encoder model
-Next, we create a [VisionTextDualEncoderModel](https://huggingface.co/docs/transformers/model_doc/vision-text-dual-encoder#visiontextdualencoder).
-The `VisionTextDualEncoderModel` class lets you load any vision and text encoder model to create a dual encoder.
-Here is an example of how to load the model using pre-trained vision and text models.
-
-```python3
-from transformers import (
- VisionTextDualEncoderModel,
- VisionTextDualEncoderProcessor,
- AutoTokenizer,
- AutoImageProcessor
-)
-
-model = VisionTextDualEncoderModel.from_vision_text_pretrained(
- "openai/clip-vit-base-patch32", "FacebookAI/roberta-base"
-)
-
-tokenizer = AutoTokenizer.from_pretrained("FacebookAI/roberta-base")
-image_processor = AutoImageProcessor.from_pretrained("openai/clip-vit-base-patch32")
-processor = VisionTextDualEncoderProcessor(image_processor, tokenizer)
-
-# save the model and processor
-model.save_pretrained("clip-roberta")
-processor.save_pretrained("clip-roberta")
-```
-
-This loads both the text and vision encoders using pre-trained weights, the projection layers are randomly
-initialized except for CLIP's vision model. If you use CLIP to initialize the vision model then the vision projection weights are also
-loaded using the pre-trained weights.
-
-### Train the model
-Finally, we can run the example script to train the model:
-
-```bash
-python run_clip.py \
- --output_dir ./clip-roberta-finetuned \
- --model_name_or_path ./clip-roberta \
- --data_dir $PWD/data \
- --dataset_name ydshieh/coco_dataset_script \
- --dataset_config_name=2017 \
- --image_column image_path \
- --caption_column caption \
- --remove_unused_columns=False \
- --do_train --do_eval \
- --per_device_train_batch_size="64" \
- --per_device_eval_batch_size="64" \
- --learning_rate="5e-5" --warmup_steps="0" --weight_decay 0.1 \
- --push_to_hub
-```
diff --git a/examples/pytorch/contrastive-image-text/requirements.txt b/examples/pytorch/contrastive-image-text/requirements.txt
deleted file mode 100644
index a789fee85eef..000000000000
--- a/examples/pytorch/contrastive-image-text/requirements.txt
+++ /dev/null
@@ -1,3 +0,0 @@
-torch>=1.5.0
-torchvision>=0.6.0
-datasets>=1.8.0
\ No newline at end of file
diff --git a/examples/pytorch/contrastive-image-text/run_clip.py b/examples/pytorch/contrastive-image-text/run_clip.py
deleted file mode 100644
index a28723c1d424..000000000000
--- a/examples/pytorch/contrastive-image-text/run_clip.py
+++ /dev/null
@@ -1,518 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2022 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=1.8.0",
-# ]
-# ///
-
-"""
-Training a CLIP like dual encoder models using text and vision encoders in the library.
-
-The script can be used to train CLIP like models for languages other than English by using
-a text encoder pre-trained in the desired language. Currently this script supports the following vision
-and text models:
-Vision models: ViT(https://huggingface.co/models?filter=vit), CLIP (https://huggingface.co/models?filter=clip)
-Text models: BERT, ROBERTa (https://huggingface.co/models?filter=fill-mask)
-"""
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import torch
-from datasets import load_dataset
-from PIL import Image
-from torchvision.io import ImageReadMode, read_image
-from torchvision.transforms import CenterCrop, ConvertImageDtype, Normalize, Resize
-from torchvision.transforms.functional import InterpolationMode
-
-import transformers
-from transformers import (
- AutoImageProcessor,
- AutoModel,
- AutoTokenizer,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/contrastive-image-text/requirements.txt")
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- freeze_vision_model: bool = field(
- default=False, metadata={"help": "Whether to freeze the vision model parameters or not."}
- )
- freeze_text_model: bool = field(
- default=False, metadata={"help": "Whether to freeze the text model parameters or not."}
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- data_dir: str | None = field(default=None, metadata={"help": "The data directory containing input files."})
- image_column: str | None = field(
- default="image_path",
- metadata={"help": "The name of the column in the datasets containing the full image file paths."},
- )
- caption_column: str | None = field(
- default="caption",
- metadata={"help": "The name of the column in the datasets containing the image captions."},
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a jsonlines file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file (a jsonlines file)."},
- )
- max_seq_length: int | None = field(
- default=128,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
-
- def __post_init__(self):
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
-
-dataset_name_mapping = {
- "image_caption_dataset.py": ("image_path", "caption"),
-}
-
-
-# We use torchvision for faster image pre-processing. The transforms are implemented as nn.Module,
-# so we jit it to be faster.
-class Transform(torch.nn.Module):
- def __init__(self, image_size, mean, std):
- super().__init__()
- self.transforms = torch.nn.Sequential(
- Resize([image_size], interpolation=InterpolationMode.BICUBIC),
- CenterCrop(image_size),
- ConvertImageDtype(torch.float),
- Normalize(mean, std),
- )
-
- def forward(self, x) -> torch.Tensor:
- """`x` should be an instance of `PIL.Image.Image`"""
- with torch.no_grad():
- x = self.transforms(x)
- return x
-
-
-def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- input_ids = torch.tensor([example["input_ids"] for example in examples], dtype=torch.long)
- attention_mask = torch.tensor([example["attention_mask"] for example in examples], dtype=torch.long)
- return {
- "pixel_values": pixel_values,
- "input_ids": input_ids,
- "attention_mask": attention_mask,
- "return_loss": True,
- }
-
-
-def main():
- # 1. Parse input arguments
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # 2. Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # 4. Load dataset
- # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files this script will use the first column for the full image path and the second column for the
- # captions (unless you specify column names for this with the `image_column` and `caption_column` arguments).
- #
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- dataset = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- keep_in_memory=False,
- data_dir=data_args.data_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- dataset = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # 5. Load pretrained model, tokenizer, and image processor
- if model_args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- elif model_args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- # Load image_processor, in this script we only use this to get the mean and std for normalization.
- image_processor = AutoImageProcessor.from_pretrained(
- model_args.image_processor_name or model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- model = AutoModel.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- config = model.config
-
- def _freeze_params(module):
- for param in module.parameters():
- param.requires_grad = False
-
- if model_args.freeze_vision_model:
- _freeze_params(model.vision_model)
-
- if model_args.freeze_text_model:
- _freeze_params(model.text_model)
-
- # set seed for torch dataloaders
- set_seed(training_args.seed)
-
- # Preprocessing the datasets.
- # We need to tokenize inputs and targets.
- if training_args.do_train:
- column_names = dataset["train"].column_names
- elif training_args.do_eval:
- column_names = dataset["validation"].column_names
- else:
- logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
- return
-
- # 6. Get the column names for input/target.
- dataset_columns = dataset_name_mapping.get(data_args.dataset_name)
- if data_args.image_column is None:
- image_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
- else:
- image_column = data_args.image_column
- if image_column not in column_names:
- raise ValueError(
- f"--image_column' value '{data_args.image_column}' needs to be one of: {', '.join(column_names)}"
- )
- if data_args.caption_column is None:
- caption_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
- else:
- caption_column = data_args.caption_column
- if caption_column not in column_names:
- raise ValueError(
- f"--caption_column' value '{data_args.caption_column}' needs to be one of: {', '.join(column_names)}"
- )
-
- # 7. Preprocessing the datasets.
- # Initialize torchvision transforms and jit it for faster processing.
- image_transformations = Transform(
- config.vision_config.image_size, image_processor.image_mean, image_processor.image_std
- )
- image_transformations = torch.jit.script(image_transformations)
-
- # Preprocessing the datasets.
- # We need to tokenize input captions and transform the images.
- def tokenize_captions(examples):
- captions = list(examples[caption_column])
- text_inputs = tokenizer(captions, max_length=data_args.max_seq_length, padding="max_length", truncation=True)
- examples["input_ids"] = text_inputs.input_ids
- examples["attention_mask"] = text_inputs.attention_mask
- return examples
-
- def transform_images(examples):
- images = [read_image(image_file, mode=ImageReadMode.RGB) for image_file in examples[image_column]]
- examples["pixel_values"] = [image_transformations(image) for image in images]
- return examples
-
- def filter_corrupt_images(examples):
- """remove problematic images"""
- valid_images = []
- for image_file in examples[image_column]:
- try:
- Image.open(image_file)
- valid_images.append(True)
- except Exception:
- valid_images.append(False)
- return valid_images
-
- if training_args.do_train:
- if "train" not in dataset:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = dataset["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- train_dataset = train_dataset.filter(
- filter_corrupt_images, batched=True, num_proc=data_args.preprocessing_num_workers
- )
- train_dataset = train_dataset.map(
- function=tokenize_captions,
- batched=True,
- remove_columns=[col for col in column_names if col != image_column],
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
-
- # Transform images on the fly as doing it on the whole dataset takes too much time.
- train_dataset.set_transform(transform_images)
-
- if training_args.do_eval:
- if "validation" not in dataset:
- raise ValueError("--do_eval requires a train validation")
- eval_dataset = dataset["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- eval_dataset = eval_dataset.filter(
- filter_corrupt_images, batched=True, num_proc=data_args.preprocessing_num_workers
- )
- eval_dataset = eval_dataset.map(
- function=tokenize_captions,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=[col for col in column_names if col != image_column],
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- # Transform images on the fly as doing it on the whole dataset takes too much time.
- eval_dataset.set_transform(transform_images)
-
- # 8. Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- data_collator=collate_fn,
- )
-
- # 9. Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- tokenizer.save_pretrained(training_args.output_dir)
- image_processor.save_pretrained(training_args.output_dir)
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # 10. Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # 11. Write Training Stats and push to hub.
- finetuned_from = model_args.model_name_or_path
- # If from a local directory, don't set `finetuned_from` as this is required to be a valid repo. id on the Hub.
- if os.path.isdir(finetuned_from):
- finetuned_from = None
- kwargs = {"finetuned_from": finetuned_from, "tasks": "contrastive-image-text-modeling"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/image-classification/README.md b/examples/pytorch/image-classification/README.md
deleted file mode 100644
index ac68bd7c51e4..000000000000
--- a/examples/pytorch/image-classification/README.md
+++ /dev/null
@@ -1,212 +0,0 @@
-
-
-# Image classification examples
-
-This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForImageClassification` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForImageClassification) (such as [ViT](https://huggingface.co/docs/transformers/main/en/model_doc/vit), [ConvNeXT](https://huggingface.co/docs/transformers/main/en/model_doc/convnext), [ResNet](https://huggingface.co/docs/transformers/main/en/model_doc/resnet), [Swin Transformer](https://huggingface.co/docs/transformers/main/en/model_doc/swin)...) using PyTorch. They can be used to fine-tune models on both [datasets from the hub](#using-datasets-from-hub) as well as on [your own custom data](#using-your-own-data).
-
- -
-Try out the inference widget here: https://huggingface.co/google/vit-base-patch16-224
-
-Content:
-- [PyTorch version, Trainer](#pytorch-version-trainer)
-- [PyTorch version, no Trainer](#pytorch-version-no-trainer)
-
-## PyTorch version, Trainer
-
-Based on the script [`run_image_classification.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/image-classification/run_image_classification.py).
-
-The script leverages the 🤗 [Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to automatically take care of the training for you, running on distributed environments right away.
-
-### Using datasets from Hub
-
-Here we show how to fine-tune a Vision Transformer (`ViT`) on the [beans](https://huggingface.co/datasets/AI-Lab-Makerere/beans) dataset, to classify the disease type of bean leaves.
-
-```bash
-python run_image_classification.py \
- --dataset_name AI-Lab-Makerere/beans \
- --output_dir ./beans_outputs/ \
- --remove_unused_columns False \
- --label_column_name labels \
- --do_train \
- --do_eval \
- --push_to_hub \
- --push_to_hub_model_id vit-base-beans \
- --learning_rate 2e-5 \
- --num_train_epochs 5 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --save_total_limit 3 \
- --seed 1337
-```
-
-👀 See the results here: [nateraw/vit-base-beans](https://huggingface.co/nateraw/vit-base-beans).
-
-Note that you can replace the model and dataset by simply setting the `model_name_or_path` and `dataset_name` arguments respectively, with any model or dataset from the [hub](https://huggingface.co/). For an overview of all possible arguments, we refer to the [docs](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) of the `TrainingArguments`, which can be passed as flags.
-
-> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
-
-### Using your own data
-
-To use your own dataset, there are 2 ways:
-- you can either provide your own folders as `--train_dir` and/or `--validation_dir` arguments
-- you can upload your dataset to the hub (possibly as a private repo, if you prefer so), and simply pass the `--dataset_name` argument.
-
-Below, we explain both in more detail.
-
-#### Provide them as folders
-
-If you provide your own folders with images, the script expects the following directory structure:
-
-```bash
-root/dog/xxx.png
-root/dog/xxy.png
-root/dog/[...]/xxz.png
-
-root/cat/123.png
-root/cat/nsdf3.png
-root/cat/[...]/asd932_.png
-```
-
-In other words, you need to organize your images in subfolders, based on their class. You can then run the script like this:
-
-```bash
-python run_image_classification.py \
- --train_dir \
- --output_dir ./outputs/ \
- --remove_unused_columns False \
- --do_train \
- --do_eval
-```
-
-Internally, the script will use the [`ImageFolder`](https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder) feature which will automatically turn the folders into 🤗 Dataset objects.
-
-##### 💡 The above will split the train dir into training and evaluation sets
- - To control the split amount, use the `--train_val_split` flag.
- - To provide your own validation split in its own directory, you can pass the `--validation_dir ` flag.
-
-#### Upload your data to the hub, as a (possibly private) repo
-
-It's very easy (and convenient) to upload your image dataset to the hub using the [`ImageFolder`](https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder) feature available in 🤗 Datasets. Simply do the following:
-
-```python
-from datasets import load_dataset
-
-# example 1: local folder
-dataset = load_dataset("imagefolder", data_dir="path_to_your_folder")
-
-# example 2: local files (supported formats are tar, gzip, zip, xz, rar, zstd)
-dataset = load_dataset("imagefolder", data_files="path_to_zip_file")
-
-# example 3: remote files (supported formats are tar, gzip, zip, xz, rar, zstd)
-dataset = load_dataset("imagefolder", data_files="https://download.microsoft.com/download/3/E/1/3E1C3F21-ECDB-4869-8368-6DEBA77B919F/kagglecatsanddogs_3367a.zip")
-
-# example 4: providing several splits
-dataset = load_dataset("imagefolder", data_files={"train": ["path/to/file1", "path/to/file2"], "test": ["path/to/file3", "path/to/file4"]})
-```
-
-`ImageFolder` will create a `label` column, and the label name is based on the directory name.
-
-Next, push it to the hub!
-
-```python
-# assuming you have ran the hf auth login command in a terminal
-dataset.push_to_hub("name_of_your_dataset")
-
-# if you want to push to a private repo, simply pass private=True:
-dataset.push_to_hub("name_of_your_dataset", private=True)
-```
-
-and that's it! You can now train your model by simply setting the `--dataset_name` argument to the name of your dataset on the hub (as explained in [Using datasets from the 🤗 hub](#using-datasets-from-hub)).
-
-More on this can also be found in [this blog post](https://huggingface.co/blog/image-search-datasets).
-
-### Sharing your model on 🤗 Hub
-
-0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
-
-1. Make sure you have `git-lfs` installed and git set up.
-
-```bash
-$ apt install git-lfs
-$ git config --global user.email "you@example.com"
-$ git config --global user.name "Your Name"
-```
-
-2. Log in with your HuggingFace account credentials using `hf`:
-
-```bash
-$ hf auth login
-# ...follow the prompts
-```
-
-3. When running the script, pass the following arguments:
-
-```bash
-python run_image_classification.py \
- --push_to_hub \
- --push_to_hub_model_id \
- ...
-```
-
-## PyTorch version, no Trainer
-
-Based on the script [`run_image_classification_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/image-classification/run_image_classification_no_trainer.py).
-
-Like `run_image_classification.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on an image classification task. The main difference is that this script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, and supports mixed precision by
-the means of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_image_classification_no_trainer.py --image_column_name img
-```
-
-This command is the same and will work for:
-
-- single/multiple CPUs
-- single/multiple GPUs
-- TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
-
-Regarding using custom data with this script, we refer to [using your own data](#using-your-own-data).
diff --git a/examples/pytorch/image-classification/requirements.txt b/examples/pytorch/image-classification/requirements.txt
deleted file mode 100644
index 2779c1c6a870..000000000000
--- a/examples/pytorch/image-classification/requirements.txt
+++ /dev/null
@@ -1,6 +0,0 @@
-accelerate>=0.12.0
-torch>=1.5.0
-torchvision>=0.6.0
-datasets>=2.14.0
-evaluate
-scikit-learn
\ No newline at end of file
diff --git a/examples/pytorch/image-classification/run_image_classification.py b/examples/pytorch/image-classification/run_image_classification.py
deleted file mode 100755
index 5b13753175a6..000000000000
--- a/examples/pytorch/image-classification/run_image_classification.py
+++ /dev/null
@@ -1,432 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate>=0.12.0",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=2.14.0",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import evaluate
-import numpy as np
-import torch
-from datasets import load_dataset
-from PIL import Image
-from torchvision.transforms import (
- CenterCrop,
- Compose,
- Lambda,
- Normalize,
- RandomHorizontalFlip,
- RandomResizedCrop,
- Resize,
- ToTensor,
-)
-
-import transformers
-from transformers import (
- MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING,
- AutoConfig,
- AutoImageProcessor,
- AutoModelForImageClassification,
- HfArgumentParser,
- TimmWrapperImageProcessor,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-""" Fine-tuning a 🤗 Transformers model for image classification"""
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/image-classification/requirements.txt")
-
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_IMAGE_CLASSIFICATION_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def pil_loader(path: str):
- with open(path, "rb") as f:
- im = Image.open(f)
- return im.convert("RGB")
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
- them on the command line.
- """
-
- dataset_name: str | None = field(
- default=None,
- metadata={
- "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
- },
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_dir: str | None = field(default=None, metadata={"help": "A folder containing the training data."})
- validation_dir: str | None = field(default=None, metadata={"help": "A folder containing the validation data."})
- train_val_split: float | None = field(
- default=0.15, metadata={"help": "Percent to split off of train for validation."}
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- image_column_name: str = field(
- default="image",
- metadata={"help": "The name of the dataset column containing the image data. Defaults to 'image'."},
- )
- label_column_name: str = field(
- default="label",
- metadata={"help": "The name of the dataset column containing the labels. Defaults to 'label'."},
- )
-
- def __post_init__(self):
- if self.dataset_name is None and (self.train_dir is None and self.validation_dir is None):
- raise ValueError(
- "You must specify either a dataset name from the hub or a train and/or validation directory."
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- default="google/vit-base-patch16-224-in21k",
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- model_type: str | None = field(
- default=None,
- metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Initialize our dataset and prepare it for the 'image-classification' task.
- if data_args.dataset_name is not None:
- dataset = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_dir is not None:
- data_files["train"] = os.path.join(data_args.train_dir, "**")
- if data_args.validation_dir is not None:
- data_files["validation"] = os.path.join(data_args.validation_dir, "**")
- dataset = load_dataset(
- "imagefolder",
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- )
-
- dataset_column_names = dataset["train"].column_names if "train" in dataset else dataset["validation"].column_names
- if data_args.image_column_name not in dataset_column_names:
- raise ValueError(
- f"--image_column_name {data_args.image_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--image_column_name` to the correct audio column - one of "
- f"{', '.join(dataset_column_names)}."
- )
- if data_args.label_column_name not in dataset_column_names:
- raise ValueError(
- f"--label_column_name {data_args.label_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--label_column_name` to the correct text column - one of "
- f"{', '.join(dataset_column_names)}."
- )
-
- def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- labels = torch.tensor([example[data_args.label_column_name] for example in examples])
- return {"pixel_values": pixel_values, "labels": labels}
-
- # If we don't have a validation split, split off a percentage of train as validation.
- data_args.train_val_split = None if "validation" in dataset else data_args.train_val_split
- if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(data_args.train_val_split)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Prepare label mappings.
- # We'll include these in the model's config to get human readable labels in the Inference API.
- labels = dataset["train"].features[data_args.label_column_name].names
- label2id, id2label = {}, {}
- for i, label in enumerate(labels):
- label2id[label] = str(i)
- id2label[str(i)] = label
-
- # Load the accuracy metric from the datasets package
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
-
- # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
- # predictions and label_ids field) and has to return a dictionary string to float.
- def compute_metrics(p):
- """Computes accuracy on a batch of predictions"""
- return metric.compute(predictions=np.argmax(p.predictions, axis=1), references=p.label_ids)
-
- config = AutoConfig.from_pretrained(
- model_args.config_name or model_args.model_name_or_path,
- num_labels=len(labels),
- label2id=label2id,
- id2label=id2label,
- finetuning_task="image-classification",
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForImageClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
- image_processor = AutoImageProcessor.from_pretrained(
- model_args.image_processor_name or model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # Define torchvision transforms to be applied to each image.
- if isinstance(image_processor, TimmWrapperImageProcessor):
- _train_transforms = image_processor.train_transforms
- _val_transforms = image_processor.val_transforms
- else:
- if "shortest_edge" in image_processor.size:
- size = image_processor.size["shortest_edge"]
- else:
- size = (image_processor.size["height"], image_processor.size["width"])
-
- # Create normalization transform
- if hasattr(image_processor, "image_mean") and hasattr(image_processor, "image_std"):
- normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
- else:
- normalize = Lambda(lambda x: x)
- _train_transforms = Compose(
- [
- RandomResizedCrop(size),
- RandomHorizontalFlip(),
- ToTensor(),
- normalize,
- ]
- )
- _val_transforms = Compose(
- [
- Resize(size),
- CenterCrop(size),
- ToTensor(),
- normalize,
- ]
- )
-
- def train_transforms(example_batch):
- """Apply _train_transforms across a batch."""
- example_batch["pixel_values"] = [
- _train_transforms(pil_img.convert("RGB")) for pil_img in example_batch[data_args.image_column_name]
- ]
- return example_batch
-
- def val_transforms(example_batch):
- """Apply _val_transforms across a batch."""
- example_batch["pixel_values"] = [
- _val_transforms(pil_img.convert("RGB")) for pil_img in example_batch[data_args.image_column_name]
- ]
- return example_batch
-
- if training_args.do_train:
- if "train" not in dataset:
- raise ValueError("--do_train requires a train dataset")
- if data_args.max_train_samples is not None:
- dataset["train"] = (
- dataset["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
- )
- # Set the training transforms
- dataset["train"].set_transform(train_transforms)
-
- if training_args.do_eval:
- if "validation" not in dataset:
- raise ValueError("--do_eval requires a validation dataset")
- if data_args.max_eval_samples is not None:
- dataset["validation"] = (
- dataset["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
- )
- # Set the validation transforms
- dataset["validation"].set_transform(val_transforms)
-
- # Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=dataset["train"] if training_args.do_train else None,
- eval_dataset=dataset["validation"] if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=image_processor,
- data_collator=collate_fn,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "image-classification",
- "dataset": data_args.dataset_name,
- "tags": ["image-classification", "vision"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/image-classification/run_image_classification_no_trainer.py b/examples/pytorch/image-classification/run_image_classification_no_trainer.py
deleted file mode 100644
index 33b9e42e3b01..000000000000
--- a/examples/pytorch/image-classification/run_image_classification_no_trainer.py
+++ /dev/null
@@ -1,658 +0,0 @@
-# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate>=0.12.0",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=2.14.0",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""Finetuning any 🤗 Transformers model for image classification leveraging 🤗 Accelerate."""
-
-import argparse
-import json
-import logging
-import math
-import os
-from pathlib import Path
-
-import datasets
-import evaluate
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from torchvision.transforms import (
- CenterCrop,
- Compose,
- Lambda,
- Normalize,
- RandomHorizontalFlip,
- RandomResizedCrop,
- Resize,
- ToTensor,
-)
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import AutoConfig, AutoImageProcessor, AutoModelForImageClassification, SchedulerType, get_scheduler
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/image-classification/requirements.txt")
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Fine-tune a Transformers model on an image classification dataset")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default="uoft-cs/cifar10",
- help=(
- "The name of the Dataset (from the HuggingFace hub) to train on (could be your own, possibly private,"
- " dataset)."
- ),
- )
- parser.add_argument("--train_dir", type=str, default=None, help="A folder containing the training data.")
- parser.add_argument("--validation_dir", type=str, default=None, help="A folder containing the validation data.")
- parser.add_argument(
- "--max_train_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--max_eval_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--train_val_split",
- type=float,
- default=0.15,
- help="Percent to split off of train for validation",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- default="google/vit-base-patch16-224-in21k",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- parser.add_argument(
- "--ignore_mismatched_sizes",
- action="store_true",
- help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
- )
- parser.add_argument(
- "--image_column_name",
- type=str,
- default="image",
- help="The name of the dataset column containing the image data. Defaults to 'image'.",
- )
- parser.add_argument(
- "--label_column_name",
- type=str,
- default="label",
- help="The name of the dataset column containing the labels. Defaults to 'label'.",
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.dataset_name is None and args.train_dir is None and args.validation_dir is None:
- raise ValueError("Need either a dataset name or a training/validation folder.")
-
- if args.push_to_hub or args.with_tracking:
- if args.output_dir is None:
- raise ValueError(
- "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
- )
-
- if args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- logger.info(accelerator.state)
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own training and evaluation files (see below)
- # or specify a Dataset from the hub (the dataset will be downloaded automatically from the datasets Hub).
-
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- if (
- args.dataset_name is not None and args.train_dir is None and args.validation_dir is None
- ): # Downloading and loading a dataset from the hub.
- dataset = load_dataset(args.dataset_name, trust_remote_code=args.trust_remote_code)
- else:
- data_files = {}
- if args.train_dir is not None:
- data_files["train"] = os.path.join(args.train_dir, "**")
- if args.validation_dir is not None:
- data_files["validation"] = os.path.join(args.validation_dir, "**")
- dataset = load_dataset(
- "imagefolder",
- data_files=data_files,
- )
- # See more about loading custom images at
- # https://huggingface.co/docs/datasets/v2.0.0/en/image_process#imagefolder.
-
- dataset_column_names = dataset["train"].column_names if "train" in dataset else dataset["validation"].column_names
- if args.image_column_name not in dataset_column_names:
- raise ValueError(
- f"--image_column_name {args.image_column_name} not found in dataset '{args.dataset_name}'. "
- "Make sure to set `--image_column_name` to the correct audio column - one of "
- f"{', '.join(dataset_column_names)}."
- )
- if args.label_column_name not in dataset_column_names:
- raise ValueError(
- f"--label_column_name {args.label_column_name} not found in dataset '{args.dataset_name}'. "
- "Make sure to set `--label_column_name` to the correct text column - one of "
- f"{', '.join(dataset_column_names)}."
- )
-
- # If we don't have a validation split, split off a percentage of train as validation.
- args.train_val_split = None if "validation" in dataset else args.train_val_split
- if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(args.train_val_split)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Prepare label mappings.
- # We'll include these in the model's config to get human readable labels in the Inference API.
- labels = dataset["train"].features[args.label_column_name].names
- label2id = {label: str(i) for i, label in enumerate(labels)}
- id2label = {str(i): label for i, label in enumerate(labels)}
-
- # Load pretrained model and image processor
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- args.model_name_or_path,
- num_labels=len(labels),
- id2label=id2label,
- label2id=label2id,
- finetuning_task="image-classification",
- trust_remote_code=args.trust_remote_code,
- )
- image_processor = AutoImageProcessor.from_pretrained(
- args.model_name_or_path,
- trust_remote_code=args.trust_remote_code,
- )
- model = AutoModelForImageClassification.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- ignore_mismatched_sizes=args.ignore_mismatched_sizes,
- trust_remote_code=args.trust_remote_code,
- )
-
- # Preprocessing the datasets
-
- # Define torchvision transforms to be applied to each image.
- if "shortest_edge" in image_processor.size:
- size = image_processor.size["shortest_edge"]
- else:
- size = (image_processor.size["height"], image_processor.size["width"])
- normalize = (
- Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
- if hasattr(image_processor, "image_mean") and hasattr(image_processor, "image_std")
- else Lambda(lambda x: x)
- )
- train_transforms = Compose(
- [
- RandomResizedCrop(size),
- RandomHorizontalFlip(),
- ToTensor(),
- normalize,
- ]
- )
- val_transforms = Compose(
- [
- Resize(size),
- CenterCrop(size),
- ToTensor(),
- normalize,
- ]
- )
-
- def preprocess_train(example_batch):
- """Apply _train_transforms across a batch."""
- example_batch["pixel_values"] = [
- train_transforms(image.convert("RGB")) for image in example_batch[args.image_column_name]
- ]
- return example_batch
-
- def preprocess_val(example_batch):
- """Apply _val_transforms across a batch."""
- example_batch["pixel_values"] = [
- val_transforms(image.convert("RGB")) for image in example_batch[args.image_column_name]
- ]
- return example_batch
-
- with accelerator.main_process_first():
- if args.max_train_samples is not None:
- dataset["train"] = dataset["train"].shuffle(seed=args.seed).select(range(args.max_train_samples))
- # Set the training transforms
- train_dataset = dataset["train"].with_transform(preprocess_train)
- if args.max_eval_samples is not None:
- dataset["validation"] = dataset["validation"].shuffle(seed=args.seed).select(range(args.max_eval_samples))
- # Set the validation transforms
- eval_dataset = dataset["validation"].with_transform(preprocess_val)
-
- # DataLoaders creation:
- def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- labels = torch.tensor([example[args.label_column_name] for example in examples])
- return {"pixel_values": pixel_values, "labels": labels}
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=collate_fn, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=collate_fn, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("image_classification_no_trainer", experiment_config)
-
- # Get the metric function
- metric = evaluate.load("accuracy")
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir,
- is_main_process=accelerator.is_main_process,
- save_function=accelerator.save,
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- predictions = outputs.logits.argmax(dim=-1)
- predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
- metric.add_batch(
- predictions=predictions,
- references=references,
- )
-
- eval_metric = metric.compute()
- logger.info(f"epoch {epoch}: {eval_metric}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "accuracy": eval_metric,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(all_results, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/image-pretraining/README.md b/examples/pytorch/image-pretraining/README.md
deleted file mode 100644
index 767f857e8dd0..000000000000
--- a/examples/pytorch/image-pretraining/README.md
+++ /dev/null
@@ -1,254 +0,0 @@
-
-
-# Image pretraining examples
-
-This directory contains Python scripts that allow you to pre-train Transformer-based vision models (like [ViT](https://huggingface.co/docs/transformers/model_doc/vit), [Swin Transformer](https://huggingface.co/docs/transformers/model_doc/swin)) on your own data, after which you can easily load the weights into a [`AutoModelForImageClassification`](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModelForImageClassification). It currently includes scripts for:
-- [SimMIM](#simmim) (by Microsoft Research)
-- [MAE](#mae) (by Facebook AI).
-
-NOTE: If you encounter problems/have suggestions for improvement, open an issue on Github and tag @NielsRogge.
-
-
-## SimMIM
-
-The `run_mim.py` script can be used to pre-train any Transformer-based vision model in the library (concretely, any model supported by the `AutoModelForMaskedImageModeling` API) for masked image modeling as proposed in [SimMIM: A Simple Framework for Masked Image Modeling](https://huggingface.co/papers/2111.09886) using PyTorch.
-
-
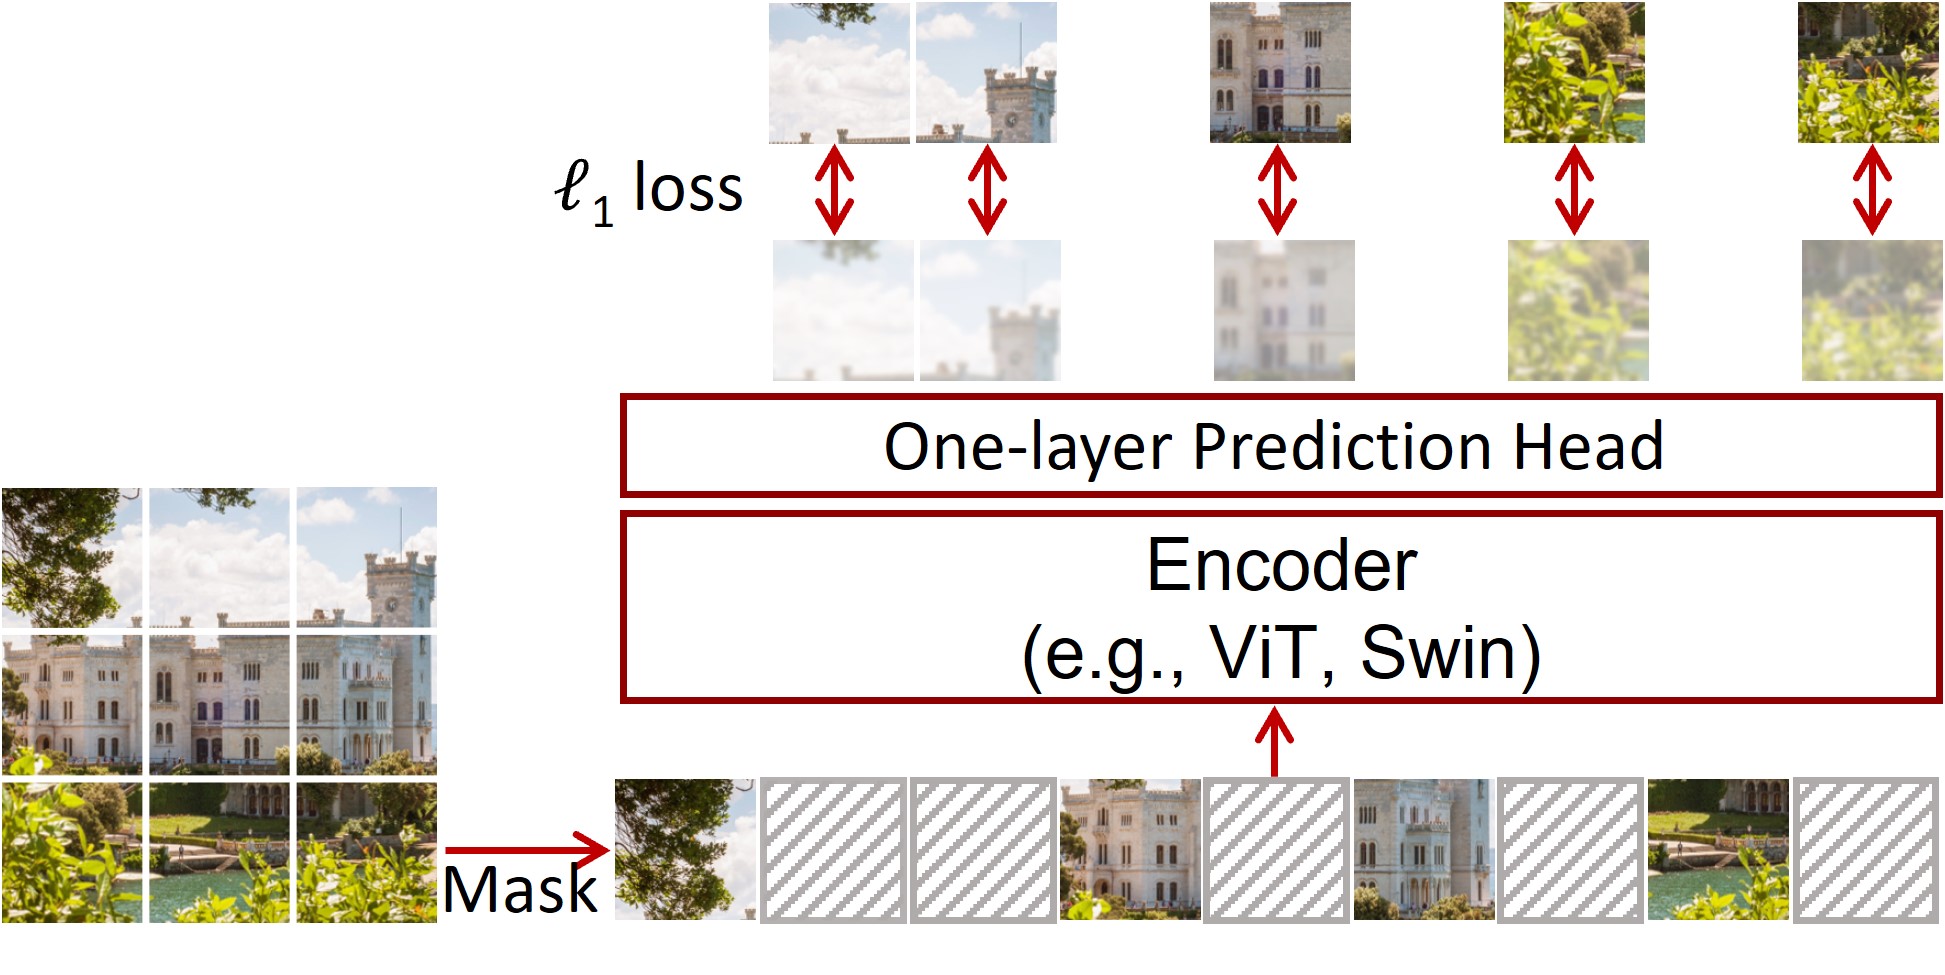 -
- SimMIM framework. Taken from the original paper.
-
-The goal for the model is to predict raw pixel values for the masked patches, using just a linear layer as prediction head. The model is trained using a simple L1 loss.
-
-### Using datasets from 🤗 datasets
-
-Here we show how to pre-train a `ViT` from scratch for masked image modeling on the [cifar10](https://huggingface.co/datasets/uoft-cs/cifar10) dataset.
-
-Alternatively, one can decide to further pre-train an already pre-trained (or fine-tuned) checkpoint from the [hub](https://huggingface.co/). This can be done by setting the `model_name_or_path` argument to "google/vit-base-patch16-224-in21k" for example (and not specifying the `model_type` argument).
-
-```bash
-!python run_mim.py \
- --model_type vit \
- --output_dir ./outputs/ \
- --remove_unused_columns False \
- --label_names bool_masked_pos \
- --do_train \
- --do_eval \
- --learning_rate 2e-5 \
- --weight_decay 0.05 \
- --num_train_epochs 100 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --save_total_limit 3 \
- --seed 1337
-```
-
-Here, we train for 100 epochs with a learning rate of 2e-5. Note that the SimMIM authors used a more sophisticated learning rate schedule, see the [config files](https://github.com/microsoft/SimMIM/blob/main/configs/vit_base__800ep/simmim_pretrain__vit_base__img224__800ep.yaml) for more info. One can easily tweak the script to include this learning rate schedule (several learning rate schedulers are supported via the [training arguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)).
-
-We can also for instance replicate the pre-training of a Swin Transformer using the same architecture as used by the SimMIM authors. For this, we first create a custom configuration and save it locally:
-
-```python
-from transformers import SwinConfig
-
-IMAGE_SIZE = 192
-PATCH_SIZE = 4
-EMBED_DIM = 128
-DEPTHS = [2, 2, 18, 2]
-NUM_HEADS = [4, 8, 16, 32]
-WINDOW_SIZE = 6
-
-config = SwinConfig(
- image_size=IMAGE_SIZE,
- patch_size=PATCH_SIZE,
- embed_dim=EMBED_DIM,
- depths=DEPTHS,
- num_heads=NUM_HEADS,
- window_size=WINDOW_SIZE,
-)
-config.save_pretrained("path_to_config")
-```
-
-Next, we can run the script by providing the path to this custom configuration (replace `path_to_config` below with your path):
-
-```bash
-!python run_mim.py \
- --config_name_or_path path_to_config \
- --model_type swin \
- --output_dir ./outputs/ \
- --remove_unused_columns False \
- --label_names bool_masked_pos \
- --do_train \
- --do_eval \
- --learning_rate 2e-5 \
- --num_train_epochs 5 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --save_total_limit 3 \
- --seed 1337
-```
-
-This will train a Swin Transformer from scratch.
-
-### Using your own data
-
-To use your own dataset, the training script expects the following directory structure:
-
-```bash
-root/dog/xxx.png
-root/dog/xxy.png
-root/dog/[...]/xxz.png
-
-root/cat/123.png
-root/cat/nsdf3.png
-root/cat/[...]/asd932_.png
-```
-
-Note that you can put images in dummy subfolders, whose names will be ignored by default (as labels aren't required). You can also just place all images into a single dummy subfolder. Once you've prepared your dataset, you can run the script like this:
-
-```bash
-python run_mim.py \
- --model_type vit \
- --dataset_name nateraw/image-folder \
- --train_dir \
- --output_dir ./outputs/ \
- --remove_unused_columns False \
- --label_names bool_masked_pos \
- --do_train \
- --do_eval
-```
-
-## MAE
-
-The `run_mae.py` script can be used to pre-train a Vision Transformer as a masked autoencoder (MAE), as proposed in [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377). The script can be used to train a `ViTMAEForPreTraining` model in the Transformers library, using PyTorch. After self-supervised pre-training, one can load the weights of the encoder directly into a `ViTForImageClassification`. The MAE method allows for learning high-capacity models that generalize well: e.g., a vanilla ViT-Huge model achieves the best accuracy (87.8%) among methods that use only ImageNet-1K data.
-
-The goal for the model is to predict raw pixel values for the masked patches. As the model internally masks patches and learns to reconstruct them, there's no need for any labels. The model uses the mean squared error (MSE) between the reconstructed and original images in the pixel space.
-
-### Using datasets from 🤗 `datasets`
-
-One can use the following command to pre-train a `ViTMAEForPreTraining` model from scratch on the [cifar10](https://huggingface.co/datasets/uoft-cs/cifar10) dataset:
-
-```bash
-python run_mae.py \
- --dataset_name uoft-cs/cifar10 \
- --output_dir ./vit-mae-demo \
- --remove_unused_columns False \
- --label_names pixel_values \
- --mask_ratio 0.75 \
- --norm_pix_loss \
- --do_train \
- --do_eval \
- --base_learning_rate 1.5e-4 \
- --lr_scheduler_type cosine \
- --weight_decay 0.05 \
- --num_train_epochs 800 \
- --warmup_steps 0.05 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --logging_strategy steps \
- --logging_steps 10 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --load_best_model_at_end True \
- --save_total_limit 3 \
- --seed 1337
-```
-
-Here we set:
-- `mask_ratio` to 0.75 (to mask 75% of the patches for each image)
-- `norm_pix_loss` to use normalized pixel values as target (the authors reported better representations with this enabled)
-- `base_learning_rate` to 1.5e-4. Note that the effective learning rate is computed by the [linear schedule](https://huggingface.co/papers/1706.02677): `lr` = `blr` * total training batch size / 256. The total training batch size is computed as `training_args.train_batch_size` * `training_args.gradient_accumulation_steps` * `training_args.world_size`.
-
-This replicates the same hyperparameters as used in the original implementation, as shown in the table below.
-
-
 -
- Original hyperparameters. Taken from the original paper.
-
-Alternatively, one can decide to further pre-train an already pre-trained (or fine-tuned) checkpoint from the [hub](https://huggingface.co/). This can be done by setting the `model_name_or_path` argument to "facebook/vit-mae-base" for example.
-
-
-### Using your own data
-
-To use your own dataset, the training script expects the following directory structure:
-
-```bash
-root/dog/xxx.png
-root/dog/xxy.png
-root/dog/[...]/xxz.png
-
-root/cat/123.png
-root/cat/nsdf3.png
-root/cat/[...]/asd932_.png
-```
-
-Note that you can put images in dummy subfolders, whose names will be ignored by default (as labels aren't required). You can also just place all images into a single dummy subfolder. Once you've prepared your dataset, you can run the script like this:
-
-```bash
-python run_mae.py \
- --model_type vit_mae \
- --dataset_name nateraw/image-folder \
- --train_dir \
- --output_dir ./outputs/ \
- --remove_unused_columns False \
- --label_names pixel_values \
- --do_train \
- --do_eval
-```
-
-#### 💡 The above will split the train dir into training and evaluation sets
- - To control the split amount, use the `--train_val_split` flag.
- - To provide your own validation split in its own directory, you can pass the `--validation_dir ` flag.
-
-
-## Sharing your model on 🤗 Hub
-
-0. If you haven't already, [sign up](https://huggingface.co/join) for a 🤗 account
-
-1. Make sure you have `git-lfs` installed and git set up.
-
-```bash
-$ apt install git-lfs
-$ git config --global user.email "you@example.com"
-$ git config --global user.name "Your Name"
-```
-
-2. Log in with your HuggingFace account credentials using `hf`
-
-```bash
-$ hf auth login
-# ...follow the prompts
-```
-
-3. When running the script, pass the following arguments:
-
-```bash
-python run_xxx.py \
- --push_to_hub \
- --push_to_hub_model_id \
- ...
-```
\ No newline at end of file
diff --git a/examples/pytorch/image-pretraining/requirements.txt b/examples/pytorch/image-pretraining/requirements.txt
deleted file mode 100644
index a789fee85eef..000000000000
--- a/examples/pytorch/image-pretraining/requirements.txt
+++ /dev/null
@@ -1,3 +0,0 @@
-torch>=1.5.0
-torchvision>=0.6.0
-datasets>=1.8.0
\ No newline at end of file
diff --git a/examples/pytorch/image-pretraining/run_mae.py b/examples/pytorch/image-pretraining/run_mae.py
deleted file mode 100644
index 272f74e94fef..000000000000
--- a/examples/pytorch/image-pretraining/run_mae.py
+++ /dev/null
@@ -1,395 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=1.8.0",
-# ]
-# ///
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import torch
-from datasets import load_dataset
-from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
-from torchvision.transforms.functional import InterpolationMode
-
-import transformers
-from transformers import (
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- ViTImageProcessor,
- ViTMAEConfig,
- ViTMAEForPreTraining,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-""" Pre-training a 🤗 ViT model as an MAE (masked autoencoder), as proposed in https://huggingface.co/papers/2111.06377."""
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- dataset_name: str | None = field(
- default="uoft-cs/cifar10", metadata={"help": "Name of a dataset from the datasets package"}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- image_column_name: str | None = field(
- default=None, metadata={"help": "The column name of the images in the files."}
- )
- train_dir: str | None = field(default=None, metadata={"help": "A folder containing the training data."})
- validation_dir: str | None = field(default=None, metadata={"help": "A folder containing the validation data."})
- train_val_split: float | None = field(
- default=0.15, metadata={"help": "Percent to split off of train for validation."}
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
-
- def __post_init__(self):
- data_files = {}
- if self.train_dir is not None:
- data_files["train"] = self.train_dir
- if self.validation_dir is not None:
- data_files["val"] = self.validation_dir
- self.data_files = data_files if data_files else None
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/image processor we are going to pre-train.
- """
-
- model_name_or_path: str = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
- )
- },
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name_or_path"}
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- mask_ratio: float = field(
- default=0.75, metadata={"help": "The ratio of the number of masked tokens in the input sequence."}
- )
- norm_pix_loss: bool = field(
- default=True, metadata={"help": "Whether or not to train with normalized pixel values as target."}
- )
-
-
-@dataclass
-class CustomTrainingArguments(TrainingArguments):
- base_learning_rate: float = field(
- default=1e-3, metadata={"help": "Base learning rate: absolute_lr = base_lr * total_batch_size / 256."}
- )
-
-
-def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- return {"pixel_values": pixel_values}
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, CustomTrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Initialize our dataset.
- ds = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- data_files=data_args.data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # If we don't have a validation split, split off a percentage of train as validation.
- data_args.train_val_split = None if "validation" in ds else data_args.train_val_split
- if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
- split = ds["train"].train_test_split(data_args.train_val_split)
- ds["train"] = split["train"]
- ds["validation"] = split["test"]
-
- # Load pretrained model and image processor
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- }
- if model_args.config_name:
- config = ViTMAEConfig.from_pretrained(model_args.config_name, **config_kwargs)
- elif model_args.model_name_or_path:
- config = ViTMAEConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = ViTMAEConfig()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- # adapt config
- config.update(
- {
- "mask_ratio": model_args.mask_ratio,
- "norm_pix_loss": model_args.norm_pix_loss,
- }
- )
-
- # create image processor
- if model_args.image_processor_name:
- image_processor = ViTImageProcessor.from_pretrained(model_args.image_processor_name, **config_kwargs)
- elif model_args.model_name_or_path:
- image_processor = ViTImageProcessor.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- image_processor = ViTImageProcessor()
-
- # create model
- if model_args.model_name_or_path:
- model = ViTMAEForPreTraining.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- )
- else:
- logger.info("Training new model from scratch")
- model = ViTMAEForPreTraining(config)
-
- if training_args.do_train:
- column_names = ds["train"].column_names
- else:
- column_names = ds["validation"].column_names
-
- if data_args.image_column_name is not None:
- image_column_name = data_args.image_column_name
- elif "image" in column_names:
- image_column_name = "image"
- elif "img" in column_names:
- image_column_name = "img"
- else:
- image_column_name = column_names[0]
-
- # transformations as done in original MAE paper
- # source: https://github.com/facebookresearch/mae/blob/main/main_pretrain.py
- if "shortest_edge" in image_processor.size:
- size = image_processor.size["shortest_edge"]
- else:
- size = (image_processor.size["height"], image_processor.size["width"])
- transforms = Compose(
- [
- Lambda(lambda img: img.convert("RGB") if img.mode != "RGB" else img),
- RandomResizedCrop(size, scale=(0.2, 1.0), interpolation=InterpolationMode.BICUBIC),
- RandomHorizontalFlip(),
- ToTensor(),
- Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
- ]
- )
-
- def preprocess_images(examples):
- """Preprocess a batch of images by applying transforms."""
-
- examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
- return examples
-
- if training_args.do_train:
- if "train" not in ds:
- raise ValueError("--do_train requires a train dataset")
- if data_args.max_train_samples is not None:
- ds["train"] = ds["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
- # Set the training transforms
- ds["train"].set_transform(preprocess_images)
-
- if training_args.do_eval:
- if "validation" not in ds:
- raise ValueError("--do_eval requires a validation dataset")
- if data_args.max_eval_samples is not None:
- ds["validation"] = (
- ds["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
- )
- # Set the validation transforms
- ds["validation"].set_transform(preprocess_images)
-
- # Compute absolute learning rate
- total_train_batch_size = (
- training_args.train_batch_size * training_args.gradient_accumulation_steps * training_args.world_size
- )
- if training_args.base_learning_rate is not None:
- training_args.learning_rate = training_args.base_learning_rate * total_train_batch_size / 256
-
- # Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=ds["train"] if training_args.do_train else None,
- eval_dataset=ds["validation"] if training_args.do_eval else None,
- processing_class=image_processor,
- data_collator=collate_fn,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "tasks": "masked-auto-encoding",
- "dataset": data_args.dataset_name,
- "tags": ["masked-auto-encoding"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/image-pretraining/run_mim.py b/examples/pytorch/image-pretraining/run_mim.py
deleted file mode 100644
index be9f4af71c2a..000000000000
--- a/examples/pytorch/image-pretraining/run_mim.py
+++ /dev/null
@@ -1,470 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=1.8.0",
-# ]
-# ///
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import numpy as np
-import torch
-from datasets import load_dataset
-from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- IMAGE_PROCESSOR_MAPPING,
- MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING,
- AutoConfig,
- AutoImageProcessor,
- AutoModelForMaskedImageModeling,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-""" Pre-training a 🤗 Transformers model for simple masked image modeling (SimMIM).
-Any model supported by the AutoModelForMaskedImageModeling API can be used.
-"""
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
-
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class into argparse arguments to be able to
- specify them on the command line.
- """
-
- dataset_name: str | None = field(
- default="uoft-cs/cifar10", metadata={"help": "Name of a dataset from the datasets package"}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- image_column_name: str | None = field(
- default=None,
- metadata={"help": "The column name of the images in the files. If not set, will try to use 'image' or 'img'."},
- )
- train_dir: str | None = field(default=None, metadata={"help": "A folder containing the training data."})
- validation_dir: str | None = field(default=None, metadata={"help": "A folder containing the validation data."})
- train_val_split: float | None = field(
- default=0.15, metadata={"help": "Percent to split off of train for validation."}
- )
- mask_patch_size: int = field(default=32, metadata={"help": "The size of the square patches to use for masking."})
- mask_ratio: float = field(
- default=0.6,
- metadata={"help": "Percentage of patches to mask."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
-
- def __post_init__(self):
- data_files = {}
- if self.train_dir is not None:
- data_files["train"] = self.train_dir
- if self.validation_dir is not None:
- data_files["val"] = self.validation_dir
- self.data_files = data_files if data_files else None
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/image processor we are going to pre-train.
- """
-
- model_name_or_path: str = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Can be a local path to a pytorch_model.bin or a "
- "checkpoint identifier on the hub. "
- "Don't set if you want to train a model from scratch."
- )
- },
- )
- model_type: str | None = field(
- default=None,
- metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
- )
- config_name_or_path: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store (cache) the pretrained models/datasets downloaded from the hub"},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- image_size: int | None = field(
- default=None,
- metadata={
- "help": (
- "The size (resolution) of each image. If not specified, will use `image_size` of the configuration."
- )
- },
- )
- patch_size: int | None = field(
- default=None,
- metadata={
- "help": (
- "The size (resolution) of each patch. If not specified, will use `patch_size` of the configuration."
- )
- },
- )
- encoder_stride: int | None = field(
- default=None,
- metadata={"help": "Stride to use for the encoder."},
- )
-
-
-class MaskGenerator:
- """
- A class to generate boolean masks for the pretraining task.
-
- A mask is a 1D tensor of shape (model_patch_size**2,) where the value is either 0 or 1,
- where 1 indicates "masked".
- """
-
- def __init__(self, input_size=192, mask_patch_size=32, model_patch_size=4, mask_ratio=0.6):
- self.input_size = input_size
- self.mask_patch_size = mask_patch_size
- self.model_patch_size = model_patch_size
- self.mask_ratio = mask_ratio
-
- if self.input_size % self.mask_patch_size != 0:
- raise ValueError("Input size must be divisible by mask patch size")
- if self.mask_patch_size % self.model_patch_size != 0:
- raise ValueError("Mask patch size must be divisible by model patch size")
-
- self.rand_size = self.input_size // self.mask_patch_size
- self.scale = self.mask_patch_size // self.model_patch_size
-
- self.token_count = self.rand_size**2
- self.mask_count = int(np.ceil(self.token_count * self.mask_ratio))
-
- def __call__(self):
- mask_idx = np.random.permutation(self.token_count)[: self.mask_count]
- mask = np.zeros(self.token_count, dtype=int)
- mask[mask_idx] = 1
-
- mask = mask.reshape((self.rand_size, self.rand_size))
- mask = mask.repeat(self.scale, axis=0).repeat(self.scale, axis=1)
-
- return torch.tensor(mask.flatten())
-
-
-def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- mask = torch.stack([example["mask"] for example in examples])
- return {"pixel_values": pixel_values, "bool_masked_pos": mask}
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Initialize our dataset.
- ds = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- data_files=data_args.data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # If we don't have a validation split, split off a percentage of train as validation.
- data_args.train_val_split = None if "validation" in ds else data_args.train_val_split
- if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
- split = ds["train"].train_test_split(data_args.train_val_split)
- ds["train"] = split["train"]
- ds["validation"] = split["test"]
-
- # Create config
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.config_name_or_path:
- config = AutoConfig.from_pretrained(model_args.config_name_or_path, **config_kwargs)
- elif model_args.model_name_or_path:
- config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = CONFIG_MAPPING[model_args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- # make sure the decoder_type is "simmim" (only relevant for BEiT)
- if hasattr(config, "decoder_type"):
- config.decoder_type = "simmim"
-
- # adapt config
- model_args.image_size = model_args.image_size if model_args.image_size is not None else config.image_size
- model_args.patch_size = model_args.patch_size if model_args.patch_size is not None else config.patch_size
- model_args.encoder_stride = (
- model_args.encoder_stride if model_args.encoder_stride is not None else config.encoder_stride
- )
-
- config.update(
- {
- "image_size": model_args.image_size,
- "patch_size": model_args.patch_size,
- "encoder_stride": model_args.encoder_stride,
- }
- )
-
- # create image processor
- if model_args.image_processor_name:
- image_processor = AutoImageProcessor.from_pretrained(model_args.image_processor_name, **config_kwargs)
- elif model_args.model_name_or_path:
- image_processor = AutoImageProcessor.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- IMAGE_PROCESSOR_TYPES = {
- conf.model_type: image_processor_class for conf, image_processor_class in IMAGE_PROCESSOR_MAPPING.items()
- }
- image_processor = IMAGE_PROCESSOR_TYPES[model_args.model_type][-1]()
-
- # create model
- if model_args.model_name_or_path:
- model = AutoModelForMaskedImageModeling.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForMaskedImageModeling.from_config(config, trust_remote_code=model_args.trust_remote_code)
-
- if training_args.do_train:
- column_names = ds["train"].column_names
- else:
- column_names = ds["validation"].column_names
-
- if data_args.image_column_name is not None:
- image_column_name = data_args.image_column_name
- elif "image" in column_names:
- image_column_name = "image"
- elif "img" in column_names:
- image_column_name = "img"
- else:
- image_column_name = column_names[0]
-
- # transformations as done in original SimMIM paper
- # source: https://github.com/microsoft/SimMIM/blob/main/data/data_simmim.py
- transforms = Compose(
- [
- Lambda(lambda img: img.convert("RGB") if img.mode != "RGB" else img),
- RandomResizedCrop(model_args.image_size, scale=(0.67, 1.0), ratio=(3.0 / 4.0, 4.0 / 3.0)),
- RandomHorizontalFlip(),
- ToTensor(),
- Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
- ]
- )
-
- # create mask generator
- mask_generator = MaskGenerator(
- input_size=model_args.image_size,
- mask_patch_size=data_args.mask_patch_size,
- model_patch_size=model_args.patch_size,
- mask_ratio=data_args.mask_ratio,
- )
-
- def preprocess_images(examples):
- """Preprocess a batch of images by applying transforms + creating a corresponding mask, indicating
- which patches to mask."""
-
- examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
- examples["mask"] = [mask_generator() for i in range(len(examples[image_column_name]))]
-
- return examples
-
- if training_args.do_train:
- if "train" not in ds:
- raise ValueError("--do_train requires a train dataset")
- if data_args.max_train_samples is not None:
- ds["train"] = ds["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
- # Set the training transforms
- ds["train"].set_transform(preprocess_images)
-
- if training_args.do_eval:
- if "validation" not in ds:
- raise ValueError("--do_eval requires a validation dataset")
- if data_args.max_eval_samples is not None:
- ds["validation"] = (
- ds["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
- )
- # Set the validation transforms
- ds["validation"].set_transform(preprocess_images)
-
- # Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=ds["train"] if training_args.do_train else None,
- eval_dataset=ds["validation"] if training_args.do_eval else None,
- processing_class=image_processor,
- data_collator=collate_fn,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "masked-image-modeling",
- "dataset": data_args.dataset_name,
- "tags": ["masked-image-modeling"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/image-pretraining/run_mim_no_trainer.py b/examples/pytorch/image-pretraining/run_mim_no_trainer.py
deleted file mode 100644
index 7c99231aedb6..000000000000
--- a/examples/pytorch/image-pretraining/run_mim_no_trainer.py
+++ /dev/null
@@ -1,811 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "torch>=1.5.0",
-# "torchvision>=0.6.0",
-# "datasets>=1.8.0",
-# ]
-# ///
-
-import argparse
-import logging
-import math
-import os
-from pathlib import Path
-
-import datasets
-import numpy as np
-import torch
-from accelerate import Accelerator, DistributedType
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from torchvision.transforms import Compose, Lambda, Normalize, RandomHorizontalFlip, RandomResizedCrop, ToTensor
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- IMAGE_PROCESSOR_MAPPING,
- MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING,
- AutoConfig,
- AutoImageProcessor,
- AutoModelForMaskedImageModeling,
- SchedulerType,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-""" Pre-training a 🤗 Transformers model for simple masked image modeling (SimMIM)
-without using HuggingFace Trainer.
-Any model supported by the AutoModelForMaskedImageModeling API can be used.
-"""
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/image-pretraining/requirements.txt")
-
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_IMAGE_MODELING_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(
- description="Finetune a transformers model on a simple Masked Image Modeling task"
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- default="uoft-cs/cifar10",
- help="Name of a dataset from the datasets package",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--image_column_name",
- type=str,
- default=None,
- help="The column name of the images in the files. If not set, will try to use 'image' or 'img'.",
- )
- parser.add_argument(
- "--train_dir",
- type=str,
- default=None,
- help="A folder containing the training data.",
- )
- parser.add_argument(
- "--validation_dir",
- type=None,
- default=None,
- help="A folder containing the validation data.",
- )
- parser.add_argument(
- "--train_val_split",
- type=float,
- default=0.15,
- help="Percent to split off of train for validation.",
- )
- parser.add_argument(
- "--mask_patch_size",
- type=int,
- default=32,
- help="The size of the square patches to use for masking.",
- )
- parser.add_argument(
- "--mask_ratio",
- type=float,
- default=0.6,
- help="Percentage of patches to mask.",
- )
- parser.add_argument(
- "--max_train_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--max_eval_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- default=None,
- help=(
- "The model checkpoint for weights initialization. Can be a local path to a pytorch_model.bin or a "
- "checkpoint identifier on the hub. "
- "Don't set if you want to train a model from scratch."
- ),
- )
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES),
- )
- parser.add_argument(
- "--config_name_or_path",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--config_overrides",
- type=str,
- default=None,
- help=(
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- ),
- )
- parser.add_argument(
- "--cache_dir",
- type=str,
- default=None,
- help="Where do you want to store (cache) the pretrained models/datasets downloaded from the hub",
- )
- parser.add_argument(
- "--model_revision",
- type=str,
- default="main",
- help="The specific model version to use (can be a branch name, tag name or commit id).",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--image_processor_name",
- type=str,
- default=None,
- help="Name or path of preprocessor config.",
- )
- parser.add_argument(
- "--token",
- type=str,
- default=None,
- help=(
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- ),
- )
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--image_size",
- type=int,
- default=None,
- help="The size (resolution) of each image. If not specified, will use `image_size` of the configuration.",
- )
- parser.add_argument(
- "--patch_size",
- type=int,
- default=None,
- help="The size (resolution) of each patch. If not specified, will use `patch_size` of the configuration.",
- )
- parser.add_argument(
- "--encoder_stride",
- type=int,
- default=None,
- help={"help": "Stride to use for the encoder."},
- )
- parser.add_argument(
- "--push_to_hub",
- action="store_true",
- help="Whether or not to push the model to the Hub.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- parser.add_argument(
- "--seed",
- type=int,
- default=None,
- help="A seed for reproducible training.",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="The initial learning rate for [`AdamW`] optimizer.",
- )
- parser.add_argument(
- "--weight_decay",
- type=float,
- default=0.0,
- help="Weight decay to use.",
- )
- parser.add_argument(
- "--num_train_epochs",
- type=float,
- default=3.0,
- help="Total number of training epochs to perform (if not an integer, will perform the decimal part percents of the last epoch before stopping training).",
- )
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps",
- type=int,
- default=0,
- help="Number of steps for the warmup in the lr scheduler.",
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--output_dir",
- type=str,
- default=None,
- help="Where to store the final model.",
- )
- args = parser.parse_args()
-
- # Sanity checks
- data_files = {}
- if args.train_dir is not None:
- data_files["train"] = args.train_dir
- if args.validation_dir is not None:
- data_files["val"] = args.validation_dir
- args.data_files = data_files if data_files else None
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-class MaskGenerator:
- """
- A class to generate boolean masks for the pretraining task.
-
- A mask is a 1D tensor of shape (model_patch_size**2,) where the value is either 0 or 1,
- where 1 indicates "masked".
- """
-
- def __init__(self, input_size=192, mask_patch_size=32, model_patch_size=4, mask_ratio=0.6):
- self.input_size = input_size
- self.mask_patch_size = mask_patch_size
- self.model_patch_size = model_patch_size
- self.mask_ratio = mask_ratio
-
- if self.input_size % self.mask_patch_size != 0:
- raise ValueError("Input size must be divisible by mask patch size")
- if self.mask_patch_size % self.model_patch_size != 0:
- raise ValueError("Mask patch size must be divisible by model patch size")
-
- self.rand_size = self.input_size // self.mask_patch_size
- self.scale = self.mask_patch_size // self.model_patch_size
-
- self.token_count = self.rand_size**2
- self.mask_count = int(np.ceil(self.token_count * self.mask_ratio))
-
- def __call__(self):
- mask_idx = np.random.permutation(self.token_count)[: self.mask_count]
- mask = np.zeros(self.token_count, dtype=int)
- mask[mask_idx] = 1
-
- mask = mask.reshape((self.rand_size, self.rand_size))
- mask = mask.repeat(self.scale, axis=0).repeat(self.scale, axis=1)
-
- return torch.tensor(mask.flatten())
-
-
-def collate_fn(examples):
- pixel_values = torch.stack([example["pixel_values"] for example in examples])
- mask = torch.stack([example["mask"] for example in examples])
- return {"pixel_values": pixel_values, "bool_masked_pos": mask}
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(
- gradient_accumulation_steps=args.gradient_accumulation_steps,
- **accelerator_log_kwargs,
- )
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
-
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Initialize our dataset.
- ds = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- data_files=args.data_files,
- cache_dir=args.cache_dir,
- token=args.token,
- trust_remote_code=args.trust_remote_code,
- )
-
- # If we don't have a validation split, split off a percentage of train as validation.
- args.train_val_split = None if "validation" in ds else args.train_val_split
- if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
- split = ds["train"].train_test_split(args.train_val_split)
- ds["train"] = split["train"]
- ds["validation"] = split["test"]
-
- # Create config
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config_kwargs = {
- "cache_dir": args.cache_dir,
- "revision": args.model_revision,
- "token": args.token,
- "trust_remote_code": args.trust_remote_code,
- }
- if args.config_name_or_path:
- config = AutoConfig.from_pretrained(args.config_name_or_path, **config_kwargs)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, **config_kwargs)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
- if args.config_overrides is not None:
- logger.info(f"Overriding config: {args.config_overrides}")
- config.update_from_string(args.config_overrides)
- logger.info(f"New config: {config}")
-
- # make sure the decoder_type is "simmim" (only relevant for BEiT)
- if hasattr(config, "decoder_type"):
- config.decoder_type = "simmim"
-
- # adapt config
- args.image_size = args.image_size if args.image_size is not None else config.image_size
- args.patch_size = args.patch_size if args.patch_size is not None else config.patch_size
- args.encoder_stride = args.encoder_stride if args.encoder_stride is not None else config.encoder_stride
-
- config.update(
- {
- "image_size": args.image_size,
- "patch_size": args.patch_size,
- "encoder_stride": args.encoder_stride,
- }
- )
-
- # create image processor
- if args.image_processor_name:
- image_processor = AutoImageProcessor.from_pretrained(args.image_processor_name, **config_kwargs)
- elif args.model_name_or_path:
- image_processor = AutoImageProcessor.from_pretrained(args.model_name_or_path, **config_kwargs)
- else:
- IMAGE_PROCESSOR_TYPES = {
- conf.model_type: image_processor_class for conf, image_processor_class in IMAGE_PROCESSOR_MAPPING.items()
- }
- image_processor = IMAGE_PROCESSOR_TYPES[args.model_type]()
-
- # create model
- if args.model_name_or_path:
- model = AutoModelForMaskedImageModeling.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- cache_dir=args.cache_dir,
- revision=args.model_revision,
- token=args.token,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForMaskedImageModeling.from_config(
- config,
- token=args.token,
- trust_remote_code=args.trust_remote_code,
- )
-
- column_names = ds["train"].column_names
-
- if args.image_column_name is not None:
- image_column_name = args.image_column_name
- elif "image" in column_names:
- image_column_name = "image"
- elif "img" in column_names:
- image_column_name = "img"
- else:
- image_column_name = column_names[0]
-
- # transformations as done in original SimMIM paper
- # source: https://github.com/microsoft/SimMIM/blob/main/data/data_simmim.py
- transforms = Compose(
- [
- Lambda(lambda img: img.convert("RGB")),
- RandomResizedCrop(args.image_size, scale=(0.67, 1.0), ratio=(3.0 / 4.0, 4.0 / 3.0)),
- RandomHorizontalFlip(),
- ToTensor(),
- Normalize(mean=image_processor.image_mean, std=image_processor.image_std),
- ]
- )
-
- # create mask generator
- mask_generator = MaskGenerator(
- input_size=args.image_size,
- mask_patch_size=args.mask_patch_size,
- model_patch_size=args.patch_size,
- mask_ratio=args.mask_ratio,
- )
-
- def preprocess_images(examples):
- """Preprocess a batch of images by applying transforms + creating a corresponding mask, indicating
- which patches to mask."""
-
- examples["pixel_values"] = [transforms(image) for image in examples[image_column_name]]
- examples["mask"] = [mask_generator() for i in range(len(examples[image_column_name]))]
-
- return examples
-
- if args.max_train_samples is not None:
- ds["train"] = ds["train"].shuffle(seed=args.seed).select(range(args.max_train_samples))
- # Set the training transforms
- ds["train"].set_transform(preprocess_images)
-
- if args.max_eval_samples is not None:
- ds["validation"] = ds["validation"].shuffle(seed=args.seed).select(range(args.max_eval_samples))
- # Set the validation transforms
- ds["validation"].set_transform(preprocess_images)
-
- # DataLoaders creation:
- train_dataloader = DataLoader(
- ds["train"],
- shuffle=True,
- collate_fn=collate_fn,
- batch_size=args.per_device_train_batch_size,
- )
- eval_dataloader = DataLoader(
- ds["validation"],
- collate_fn=collate_fn,
- batch_size=args.per_device_eval_batch_size,
- )
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Note -> the training dataloader needs to be prepared before we grab his length below (cause its length will be
- # shorter in multiprocess)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model,
- optimizer,
- train_dataloader,
- eval_dataloader,
- lr_scheduler,
- )
-
- # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
- if accelerator.distributed_type == DistributedType.TPU:
- model.tie_weights()
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("mim_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(ds['train'])}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(int(args.max_train_steps)), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- losses = []
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
-
- loss = outputs.loss
- losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
-
- losses = torch.cat(losses)
- eval_loss = torch.mean(losses)
-
- logger.info(f"epoch {epoch}: eval_loss: {eval_loss}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "eval_loss": eval_loss,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/instance-segmentation/README.md b/examples/pytorch/instance-segmentation/README.md
deleted file mode 100644
index 7385a077e620..000000000000
--- a/examples/pytorch/instance-segmentation/README.md
+++ /dev/null
@@ -1,235 +0,0 @@
-
-
-# Instance Segmentation Examples
-
-This directory contains two scripts that demonstrate how to fine-tune [MaskFormer](https://huggingface.co/docs/transformers/model_doc/maskformer) and [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) for instance segmentation using PyTorch.
-For other instance segmentation models, such as [DETR](https://huggingface.co/docs/transformers/model_doc/detr) and [Conditional DETR](https://huggingface.co/docs/transformers/model_doc/conditional_detr), the scripts need to be adjusted to properly handle input and output data.
-
-Content:
-- [PyTorch Version with Trainer](#pytorch-version-with-trainer)
-- [PyTorch Version with Accelerate](#pytorch-version-with-accelerate)
-- [Reload and Perform Inference](#reload-and-perform-inference)
-- [Note on Custom Data](#note-on-custom-data)
-
-## PyTorch Version with Trainer
-
-This example is based on the script [`run_instance_segmentation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/instance-segmentation/run_instance_segmentation.py).
-
-The script uses the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to manage training automatically, including distributed environments.
-
-Here, we show how to fine-tune a [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) model on a subsample of the [ADE20K](https://huggingface.co/datasets/merve/scene_parse_150) dataset. We created a [small dataset](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) with approximately 2,000 images containing only "person" and "car" annotations; all other pixels are marked as "background."
-
-Here is the `label2id` mapping for this dataset:
-
-```python
-label2id = {
- "background": 0,
- "person": 1,
- "car": 2,
-}
-```
-
-Since the `background` label is not an instance and we don't want to predict it, we will use `do_reduce_labels` to remove it from the data.
-
-Run the training with the following command:
-
-```bash
-python run_instance_segmentation.py \
- --model_name_or_path facebook/mask2former-swin-tiny-coco-instance \
- --output_dir finetune-instance-segmentation-ade20k-mini-mask2former \
- --dataset_name qubvel-hf/ade20k-mini \
- --do_reduce_labels \
- --image_height 256 \
- --image_width 256 \
- --do_train \
- --fp16 \
- --num_train_epochs 40 \
- --learning_rate 1e-5 \
- --lr_scheduler_type constant \
- --per_device_train_batch_size 8 \
- --gradient_accumulation_steps 2 \
- --dataloader_num_workers 8 \
- --dataloader_persistent_workers \
- --dataloader_prefetch_factor 4 \
- --do_eval \
- --eval_strategy epoch \
- --logging_strategy epoch \
- --save_strategy epoch \
- --save_total_limit 2 \
- --push_to_hub
-```
-
-The resulting model can be viewed [here](https://huggingface.co/qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former). Always refer to the original paper for details on training hyperparameters. To improve model quality, consider:
-- Changing image size parameters (`--image_height`/`--image_width`)
-- Adjusting training parameters such as learning rate, batch size, warmup, optimizer, and more (see [TrainingArguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments))
-- Adding more image augmentations (we created a helpful [HF Space](https://huggingface.co/spaces/qubvel-hf/albumentations-demo) to choose some)
-
-You can also replace the model [checkpoint](https://huggingface.co/models?search=maskformer).
-
-## PyTorch Version with Accelerate
-
-This example is based on the script [`run_instance_segmentation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py).
-
-The script uses [🤗 Accelerate](https://github.com/huggingface/accelerate) to write your own training loop in PyTorch and run it on various environments, including CPU, multi-CPU, GPU, multi-GPU, and TPU, with support for mixed precision.
-
-First, configure the environment:
-
-```bash
-accelerate config
-```
-
-Answer the questions regarding your training environment. Then, run:
-
-```bash
-accelerate test
-```
-
-This command ensures everything is ready for training. Finally, launch training with:
-
-```bash
-accelerate launch run_instance_segmentation_no_trainer.py \
- --model_name_or_path facebook/mask2former-swin-tiny-coco-instance \
- --output_dir finetune-instance-segmentation-ade20k-mini-mask2former-no-trainer \
- --dataset_name qubvel-hf/ade20k-mini \
- --do_reduce_labels \
- --image_height 256 \
- --image_width 256 \
- --num_train_epochs 40 \
- --learning_rate 1e-5 \
- --lr_scheduler_type constant \
- --per_device_train_batch_size 8 \
- --gradient_accumulation_steps 2 \
- --dataloader_num_workers 8 \
- --push_to_hub
-```
-
-With this setup, you can train on multiple GPUs, log everything to trackers (like Weights and Biases, Tensorboard), and regularly push your model to the hub (with the repo name set to `args.output_dir` under your HF username).
-With the default settings, the script fine-tunes a [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) model on the sample of [ADE20K](https://huggingface.co/datasets/qubvel-hf/ade20k-mini) dataset. The resulting model can be viewed [here](https://huggingface.co/qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former-no-trainer).
-
-## Reload and Perform Inference
-
-After training, you can easily load your trained model and perform inference as follows:
-
-```python
-import torch
-import requests
-import matplotlib.pyplot as plt
-
-from PIL import Image
-from transformers import Mask2FormerForUniversalSegmentation, Mask2FormerImageProcessor
-
-# Load image
-image = Image.open(requests.get("http://farm4.staticflickr.com/3017/3071497290_31f0393363_z.jpg", stream=True).raw)
-
-# Load model and image processor
-device = "cuda"
-checkpoint = "qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former"
-
-model = Mask2FormerForUniversalSegmentation.from_pretrained(checkpoint, device_map=device)
-image_processor = Mask2FormerImageProcessor.from_pretrained(checkpoint)
-
-# Run inference on image
-inputs = image_processor(images=[image], return_tensors="pt").to(device)
-with torch.no_grad():
- outputs = model(**inputs)
-
-# Post-process outputs
-outputs = image_processor.post_process_instance_segmentation(outputs, target_sizes=[(image.height, image.width)])
-
-print("Mask shape: ", outputs[0]["segmentation"].shape)
-print("Mask values: ", outputs[0]["segmentation"].unique())
-for segment in outputs[0]["segments_info"]:
- print("Segment: ", segment)
-```
-
-```
-Mask shape: torch.Size([427, 640])
-Mask values: tensor([-1., 0., 1., 2., 3., 4., 5., 6.])
-Segment: {'id': 0, 'label_id': 0, 'was_fused': False, 'score': 0.946127}
-Segment: {'id': 1, 'label_id': 1, 'was_fused': False, 'score': 0.961582}
-Segment: {'id': 2, 'label_id': 1, 'was_fused': False, 'score': 0.968367}
-Segment: {'id': 3, 'label_id': 1, 'was_fused': False, 'score': 0.819527}
-Segment: {'id': 4, 'label_id': 1, 'was_fused': False, 'score': 0.655761}
-Segment: {'id': 5, 'label_id': 1, 'was_fused': False, 'score': 0.531299}
-Segment: {'id': 6, 'label_id': 1, 'was_fused': False, 'score': 0.929477}
-```
-
-Use the following code to visualize the results:
-
-```python
-import numpy as np
-import matplotlib.pyplot as plt
-
-segmentation = outputs[0]["segmentation"].numpy()
-
-plt.figure(figsize=(10, 10))
-plt.subplot(1, 2, 1)
-plt.imshow(np.array(image))
-plt.axis("off")
-plt.subplot(1, 2, 2)
-plt.imshow(segmentation)
-plt.axis("off")
-plt.show()
-```
-
-
-
-## Note on Custom Data
-
-Here is a short script demonstrating how to create your own dataset for instance segmentation and push it to the hub:
-
-> Note: Annotations should be represented as 3-channel images (similar to the [scene_parsing_150](https://huggingface.co/datasets/zhoubolei/scene_parse_150#instance_segmentation-1) dataset). The first channel is a semantic-segmentation map with values corresponding to `label2id`, the second is an instance-segmentation map where each instance has a unique value, and the third channel should be empty (filled with zeros).
-
-```python
-from datasets import Dataset, DatasetDict
-from datasets import Image as DatasetImage
-
-label2id = {
- "background": 0,
- "person": 1,
- "car": 2,
-}
-
-train_split = {
- "image": [, , , ...],
- "annotation": [, , , ...],
-}
-
-validation_split = {
- "image": [, , , ...],
- "annotation": [, , , ...],
-}
-
-def create_instance_segmentation_dataset(label2id, **splits):
- dataset_dict = {}
- for split_name, split in splits.items():
- split["semantic_class_to_id"] = [label2id] * len(split["image"])
- dataset_split = (
- Dataset.from_dict(split)
- .cast_column("image", DatasetImage())
- .cast_column("annotation", DatasetImage())
- )
- dataset_dict[split_name] = dataset_split
- return DatasetDict(dataset_dict)
-
-dataset = create_instance_segmentation_dataset(label2id, train=train_split, validation=validation_split)
-dataset.push_to_hub("qubvel-hf/ade20k-nano")
-```
-
-Use this dataset for fine-tuning by specifying its name with `--dataset_name `.
-
-See also: [Dataset Creation Guide](https://huggingface.co/docs/datasets/image_dataset#create-an-image-dataset)
\ No newline at end of file
diff --git a/examples/pytorch/instance-segmentation/requirements.txt b/examples/pytorch/instance-segmentation/requirements.txt
deleted file mode 100644
index 7772958dee7a..000000000000
--- a/examples/pytorch/instance-segmentation/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-albumentations >= 1.4.16
-timm
-datasets
-torchmetrics
-pycocotools
diff --git a/examples/pytorch/instance-segmentation/run_instance_segmentation.py b/examples/pytorch/instance-segmentation/run_instance_segmentation.py
deleted file mode 100644
index be0a1a2c115e..000000000000
--- a/examples/pytorch/instance-segmentation/run_instance_segmentation.py
+++ /dev/null
@@ -1,476 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "timm",
-# "datasets",
-# "torchmetrics",
-# "pycocotools",
-# ]
-# ///
-
-"""Finetuning 🤗 Transformers model for instance segmentation leveraging the Trainer API."""
-
-import logging
-import os
-import sys
-from collections.abc import Mapping
-from dataclasses import dataclass, field
-from functools import partial
-from typing import Any
-
-import albumentations as A
-import numpy as np
-import torch
-from datasets import load_dataset
-from torchmetrics.detection.mean_ap import MeanAveragePrecision
-
-import transformers
-from transformers import (
- AutoImageProcessor,
- AutoModelForUniversalSegmentation,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
-)
-from transformers.image_processing_utils import BatchFeature
-from transformers.trainer import EvalPrediction
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/instance-segmentation/requirements.txt")
-
-
-@dataclass
-class Arguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
- them on the command line.
- """
-
- model_name_or_path: str = field(
- default="facebook/mask2former-swin-tiny-coco-instance",
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- dataset_name: str = field(
- default="qubvel-hf/ade20k-mini",
- metadata={
- "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- image_height: int | None = field(default=512, metadata={"help": "Image height after resizing."})
- image_width: int | None = field(default=512, metadata={"help": "Image width after resizing."})
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- do_reduce_labels: bool = field(
- default=False,
- metadata={
- "help": (
- "If background class is labeled as 0 and you want to remove it from the labels, set this flag to True."
- )
- },
- )
-
-
-def augment_and_transform_batch(
- examples: Mapping[str, Any], transform: A.Compose, image_processor: AutoImageProcessor
-) -> BatchFeature:
- batch = {
- "pixel_values": [],
- "mask_labels": [],
- "class_labels": [],
- }
-
- for pil_image, pil_annotation in zip(examples["image"], examples["annotation"]):
- image = np.array(pil_image)
- semantic_and_instance_masks = np.array(pil_annotation)[..., :2]
-
- # Apply augmentations
- output = transform(image=image, mask=semantic_and_instance_masks)
-
- aug_image = output["image"]
- aug_semantic_and_instance_masks = output["mask"]
- aug_instance_mask = aug_semantic_and_instance_masks[..., 1]
-
- # Create mapping from instance id to semantic id
- unique_semantic_id_instance_id_pairs = np.unique(aug_semantic_and_instance_masks.reshape(-1, 2), axis=0)
- instance_id_to_semantic_id = {
- instance_id: semantic_id for semantic_id, instance_id in unique_semantic_id_instance_id_pairs
- }
-
- # Apply the image processor transformations: resizing, rescaling, normalization
- model_inputs = image_processor(
- images=[aug_image],
- segmentation_maps=[aug_instance_mask],
- instance_id_to_semantic_id=instance_id_to_semantic_id,
- return_tensors="pt",
- )
-
- batch["pixel_values"].append(model_inputs.pixel_values[0])
- batch["mask_labels"].append(model_inputs.mask_labels[0])
- batch["class_labels"].append(model_inputs.class_labels[0])
-
- return batch
-
-
-def collate_fn(examples):
- batch = {}
- batch["pixel_values"] = torch.stack([example["pixel_values"] for example in examples])
- batch["class_labels"] = [example["class_labels"] for example in examples]
- batch["mask_labels"] = [example["mask_labels"] for example in examples]
- if "pixel_mask" in examples[0]:
- batch["pixel_mask"] = torch.stack([example["pixel_mask"] for example in examples])
- return batch
-
-
-@dataclass
-class ModelOutput:
- class_queries_logits: torch.Tensor
- masks_queries_logits: torch.Tensor
-
-
-def nested_cpu(tensors):
- if isinstance(tensors, (list, tuple)):
- return type(tensors)(nested_cpu(t) for t in tensors)
- elif isinstance(tensors, Mapping):
- return type(tensors)({k: nested_cpu(t) for k, t in tensors.items()})
- elif isinstance(tensors, torch.Tensor):
- return tensors.cpu().detach()
- else:
- return tensors
-
-
-class Evaluator:
- """
- Compute metrics for the instance segmentation task.
- """
-
- def __init__(
- self,
- image_processor: AutoImageProcessor,
- id2label: Mapping[int, str],
- threshold: float = 0.0,
- ):
- """
- Initialize evaluator with image processor, id2label mapping and threshold for filtering predictions.
-
- Args:
- image_processor (AutoImageProcessor): Image processor for
- `post_process_instance_segmentation` method.
- id2label (Mapping[int, str]): Mapping from class id to class name.
- threshold (float): Threshold to filter predicted boxes by confidence. Defaults to 0.0.
- """
- self.image_processor = image_processor
- self.id2label = id2label
- self.threshold = threshold
- self.metric = self.get_metric()
-
- def get_metric(self):
- metric = MeanAveragePrecision(iou_type="segm", class_metrics=True)
- return metric
-
- def reset_metric(self):
- self.metric.reset()
-
- def postprocess_target_batch(self, target_batch) -> list[dict[str, torch.Tensor]]:
- """Collect targets in a form of list of dictionaries with keys "masks", "labels"."""
- batch_masks = target_batch[0]
- batch_labels = target_batch[1]
- post_processed_targets = []
- for masks, labels in zip(batch_masks, batch_labels):
- post_processed_targets.append(
- {
- "masks": masks.to(dtype=torch.bool),
- "labels": labels,
- }
- )
- return post_processed_targets
-
- def get_target_sizes(self, post_processed_targets) -> list[list[int]]:
- target_sizes = []
- for target in post_processed_targets:
- target_sizes.append(target["masks"].shape[-2:])
- return target_sizes
-
- def postprocess_prediction_batch(self, prediction_batch, target_sizes) -> list[dict[str, torch.Tensor]]:
- """Collect predictions in a form of list of dictionaries with keys "masks", "labels", "scores"."""
-
- model_output = ModelOutput(class_queries_logits=prediction_batch[0], masks_queries_logits=prediction_batch[1])
- post_processed_output = self.image_processor.post_process_instance_segmentation(
- model_output,
- threshold=self.threshold,
- target_sizes=target_sizes,
- return_binary_maps=True,
- )
-
- post_processed_predictions = []
- for image_predictions, target_size in zip(post_processed_output, target_sizes):
- if image_predictions["segments_info"]:
- post_processed_image_prediction = {
- "masks": image_predictions["segmentation"].to(dtype=torch.bool),
- "labels": torch.tensor([x["label_id"] for x in image_predictions["segments_info"]]),
- "scores": torch.tensor([x["score"] for x in image_predictions["segments_info"]]),
- }
- else:
- # for void predictions, we need to provide empty tensors
- post_processed_image_prediction = {
- "masks": torch.zeros([0, *target_size], dtype=torch.bool),
- "labels": torch.tensor([]),
- "scores": torch.tensor([]),
- }
- post_processed_predictions.append(post_processed_image_prediction)
-
- return post_processed_predictions
-
- @torch.no_grad()
- def __call__(self, evaluation_results: EvalPrediction, compute_result: bool = False) -> Mapping[str, float]:
- """
- Update metrics with current evaluation results and return metrics if `compute_result` is True.
-
- Args:
- evaluation_results (EvalPrediction): Predictions and targets from evaluation.
- compute_result (bool): Whether to compute and return metrics.
-
- Returns:
- Mapping[str, float]: Metrics in a form of dictionary {: }
- """
- prediction_batch = nested_cpu(evaluation_results.predictions)
- target_batch = nested_cpu(evaluation_results.label_ids)
-
- # For metric computation we need to provide:
- # - targets in a form of list of dictionaries with keys "masks", "labels"
- # - predictions in a form of list of dictionaries with keys "masks", "labels", "scores"
- post_processed_targets = self.postprocess_target_batch(target_batch)
- target_sizes = self.get_target_sizes(post_processed_targets)
- post_processed_predictions = self.postprocess_prediction_batch(prediction_batch, target_sizes)
-
- # Compute metrics
- self.metric.update(post_processed_predictions, post_processed_targets)
-
- if not compute_result:
- return
-
- metrics = self.metric.compute()
-
- # Replace list of per class metrics with separate metric for each class
- classes = metrics.pop("classes")
- map_per_class = metrics.pop("map_per_class")
- mar_100_per_class = metrics.pop("mar_100_per_class")
- for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
- class_name = self.id2label[class_id.item()] if self.id2label is not None else class_id.item()
- metrics[f"map_{class_name}"] = class_map
- metrics[f"mar_100_{class_name}"] = class_mar
-
- metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
-
- # Reset metric for next evaluation
- self.reset_metric()
-
- return metrics
-
-
-def setup_logging(training_args: TrainingArguments) -> None:
- """Setup logging according to `training_args`."""
-
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
-
-def find_last_checkpoint(training_args: TrainingArguments) -> str | None:
- """Find the last checkpoint in the output directory according to parameters specified in `training_args`."""
-
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
-
- return checkpoint
-
-
-def main():
- # See all possible arguments in https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments
- # or by passing the --help flag to this script.
-
- parser = HfArgumentParser([Arguments, TrainingArguments])
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- args, training_args = parser.parse_args_into_dataclasses()
-
- # Set default training arguments for instance segmentation
- training_args.eval_do_concat_batches = False
- training_args.batch_eval_metrics = True
- training_args.remove_unused_columns = False
-
- # Setup logging and log on each process the small summary:
- setup_logging(training_args)
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Load last checkpoint from output_dir if it exists (and we are not overwriting it)
- checkpoint = find_last_checkpoint(training_args)
-
- # ------------------------------------------------------------------------------------------------
- # Load dataset, prepare splits
- # ------------------------------------------------------------------------------------------------
-
- dataset = load_dataset(args.dataset_name, trust_remote_code=args.trust_remote_code)
-
- # We need to specify the label2id mapping for the model
- # it is a mapping from semantic class name to class index.
- # In case your dataset does not provide it, you can create it manually:
- # label2id = {"background": 0, "cat": 1, "dog": 2}
- label2id = dataset["train"][0]["semantic_class_to_id"]
-
- if args.do_reduce_labels:
- label2id = {name: idx for name, idx in label2id.items() if idx != 0} # remove background class
- label2id = {name: idx - 1 for name, idx in label2id.items()} # shift class indices by -1
-
- id2label = {v: k for k, v in label2id.items()}
-
- # ------------------------------------------------------------------------------------------------
- # Load pretrained config, model and image processor
- # ------------------------------------------------------------------------------------------------
- model = AutoModelForUniversalSegmentation.from_pretrained(
- args.model_name_or_path,
- label2id=label2id,
- id2label=id2label,
- ignore_mismatched_sizes=True,
- token=args.token,
- )
-
- image_processor = AutoImageProcessor.from_pretrained(
- args.model_name_or_path,
- do_resize=True,
- size={"height": args.image_height, "width": args.image_width},
- do_reduce_labels=args.do_reduce_labels,
- reduce_labels=args.do_reduce_labels, # TODO: remove when mask2former support `do_reduce_labels`
- token=args.token,
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define image augmentations and dataset transforms
- # ------------------------------------------------------------------------------------------------
- train_augment_and_transform = A.Compose(
- [
- A.HorizontalFlip(p=0.5),
- A.RandomBrightnessContrast(p=0.5),
- A.HueSaturationValue(p=0.1),
- ],
- )
- validation_transform = A.Compose(
- [A.NoOp()],
- )
-
- # Make transform functions for batch and apply for dataset splits
- train_transform_batch = partial(
- augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
- )
- validation_transform_batch = partial(
- augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
- )
-
- dataset["train"] = dataset["train"].with_transform(train_transform_batch)
- dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
-
- # ------------------------------------------------------------------------------------------------
- # Model training and evaluation with Trainer API
- # ------------------------------------------------------------------------------------------------
-
- compute_metrics = Evaluator(image_processor=image_processor, id2label=id2label, threshold=0.0)
-
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=dataset["train"] if training_args.do_train else None,
- eval_dataset=dataset["validation"] if training_args.do_eval else None,
- processing_class=image_processor,
- data_collator=collate_fn,
- compute_metrics=compute_metrics,
- )
-
- # Training
- if training_args.do_train:
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Final evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate(eval_dataset=dataset["validation"], metric_key_prefix="test")
- trainer.log_metrics("test", metrics)
- trainer.save_metrics("test", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": args.model_name_or_path,
- "dataset": args.dataset_name,
- "tags": ["image-segmentation", "instance-segmentation", "vision"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py b/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
deleted file mode 100644
index 2559498ec85b..000000000000
--- a/examples/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
+++ /dev/null
@@ -1,751 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "timm",
-# "datasets",
-# "torchmetrics",
-# "pycocotools",
-# ]
-# ///
-
-"""Finetuning 🤗 Transformers model for instance segmentation with Accelerate 🚀."""
-
-import argparse
-import json
-import logging
-import math
-import os
-import sys
-from collections.abc import Mapping
-from functools import partial
-from pathlib import Path
-from typing import Any
-
-import albumentations as A
-import datasets
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch.utils.data import DataLoader
-from torchmetrics.detection.mean_ap import MeanAveragePrecision
-from tqdm import tqdm
-
-import transformers
-from transformers import (
- AutoImageProcessor,
- AutoModelForUniversalSegmentation,
- SchedulerType,
- get_scheduler,
-)
-from transformers.image_processing_utils import BatchFeature
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/instance-segmentation/requirements.txt")
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model for instance segmentation task")
-
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to a pretrained model or model identifier from huggingface.co/models.",
- default="facebook/mask2former-swin-tiny-coco-instance",
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- help="Name of the dataset on the hub.",
- default="qubvel-hf/ade20k-mini",
- )
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--image_height",
- type=int,
- default=384,
- help="The height of the images to feed the model.",
- )
- parser.add_argument(
- "--image_width",
- type=int,
- default=384,
- help="The width of the images to feed the model.",
- )
- parser.add_argument(
- "--do_reduce_labels",
- action="store_true",
- help="Whether to reduce the number of labels by removing the background class.",
- )
- parser.add_argument(
- "--cache_dir",
- type=str,
- help="Path to a folder in which the model and dataset will be cached.",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--dataloader_num_workers",
- type=int,
- default=4,
- help="Number of workers to use for the dataloaders.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument(
- "--adam_beta1",
- type=float,
- default=0.9,
- help="Beta1 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_beta2",
- type=float,
- default=0.999,
- help="Beta2 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_epsilon",
- type=float,
- default=1e-8,
- help="Epsilon for AdamW optimizer",
- )
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- required=False,
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.push_to_hub or args.with_tracking:
- if args.output_dir is None:
- raise ValueError(
- "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
- )
-
- if args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
-
- return args
-
-
-def augment_and_transform_batch(
- examples: Mapping[str, Any], transform: A.Compose, image_processor: AutoImageProcessor
-) -> BatchFeature:
- batch = {
- "pixel_values": [],
- "mask_labels": [],
- "class_labels": [],
- }
-
- for pil_image, pil_annotation in zip(examples["image"], examples["annotation"]):
- image = np.array(pil_image)
- semantic_and_instance_masks = np.array(pil_annotation)[..., :2]
-
- # Apply augmentations
- output = transform(image=image, mask=semantic_and_instance_masks)
-
- aug_image = output["image"]
- aug_semantic_and_instance_masks = output["mask"]
- aug_instance_mask = aug_semantic_and_instance_masks[..., 1]
-
- # Create mapping from instance id to semantic id
- unique_semantic_id_instance_id_pairs = np.unique(aug_semantic_and_instance_masks.reshape(-1, 2), axis=0)
- instance_id_to_semantic_id = {
- instance_id: semantic_id for semantic_id, instance_id in unique_semantic_id_instance_id_pairs
- }
-
- # Apply the image processor transformations: resizing, rescaling, normalization
- model_inputs = image_processor(
- images=[aug_image],
- segmentation_maps=[aug_instance_mask],
- instance_id_to_semantic_id=instance_id_to_semantic_id,
- return_tensors="pt",
- )
-
- batch["pixel_values"].append(model_inputs.pixel_values[0])
- batch["mask_labels"].append(model_inputs.mask_labels[0])
- batch["class_labels"].append(model_inputs.class_labels[0])
-
- return batch
-
-
-def collate_fn(examples):
- batch = {}
- batch["pixel_values"] = torch.stack([example["pixel_values"] for example in examples])
- batch["class_labels"] = [example["class_labels"] for example in examples]
- batch["mask_labels"] = [example["mask_labels"] for example in examples]
- if "pixel_mask" in examples[0]:
- batch["pixel_mask"] = torch.stack([example["pixel_mask"] for example in examples])
- return batch
-
-
-def nested_cpu(tensors):
- if isinstance(tensors, (list, tuple)):
- return type(tensors)(nested_cpu(t) for t in tensors)
- elif isinstance(tensors, Mapping):
- return type(tensors)({k: nested_cpu(t) for k, t in tensors.items()})
- elif isinstance(tensors, torch.Tensor):
- return tensors.cpu().detach()
- else:
- return tensors
-
-
-def evaluation_loop(model, image_processor, accelerator: Accelerator, dataloader, id2label):
- metric = MeanAveragePrecision(iou_type="segm", class_metrics=True)
-
- for inputs in tqdm(dataloader, total=len(dataloader), disable=not accelerator.is_local_main_process):
- with torch.no_grad():
- outputs = model(**inputs)
-
- inputs = accelerator.gather_for_metrics(inputs)
- inputs = nested_cpu(inputs)
-
- outputs = accelerator.gather_for_metrics(outputs)
- outputs = nested_cpu(outputs)
-
- # For metric computation we need to provide:
- # - targets in a form of list of dictionaries with keys "masks", "labels"
- # - predictions in a form of list of dictionaries with keys "masks", "labels", "scores"
-
- post_processed_targets = []
- post_processed_predictions = []
- target_sizes = []
-
- # Collect targets
- for masks, labels in zip(inputs["mask_labels"], inputs["class_labels"]):
- post_processed_targets.append(
- {
- "masks": masks.to(dtype=torch.bool),
- "labels": labels,
- }
- )
- target_sizes.append(masks.shape[-2:])
-
- # Collect predictions
- post_processed_output = image_processor.post_process_instance_segmentation(
- outputs,
- threshold=0.0,
- target_sizes=target_sizes,
- return_binary_maps=True,
- )
-
- for image_predictions, target_size in zip(post_processed_output, target_sizes):
- if image_predictions["segments_info"]:
- post_processed_image_prediction = {
- "masks": image_predictions["segmentation"].to(dtype=torch.bool),
- "labels": torch.tensor([x["label_id"] for x in image_predictions["segments_info"]]),
- "scores": torch.tensor([x["score"] for x in image_predictions["segments_info"]]),
- }
- else:
- # for void predictions, we need to provide empty tensors
- post_processed_image_prediction = {
- "masks": torch.zeros([0, *target_size], dtype=torch.bool),
- "labels": torch.tensor([]),
- "scores": torch.tensor([]),
- }
- post_processed_predictions.append(post_processed_image_prediction)
-
- # Update metric for batch targets and predictions
- metric.update(post_processed_predictions, post_processed_targets)
-
- # Compute metrics
- metrics = metric.compute()
-
- # Replace list of per class metrics with separate metric for each class
- classes = metrics.pop("classes")
- map_per_class = metrics.pop("map_per_class")
- mar_100_per_class = metrics.pop("mar_100_per_class")
- for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
- class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
- metrics[f"map_{class_name}"] = class_map
- metrics[f"mar_100_{class_name}"] = class_mar
-
- metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
-
- return metrics
-
-
-def setup_logging(accelerator: Accelerator) -> None:
- """Setup logging according to `training_args`."""
-
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- logger.setLevel(logging.INFO)
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
-
-def handle_repository_creation(accelerator: Accelerator, args: argparse.Namespace):
- """Create a repository for the model and dataset if `args.push_to_hub` is set."""
-
- repo_id = None
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- return repo_id
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
- setup_logging(accelerator)
-
- # If passed along, set the training seed now.
- # We set device_specific to True as we want different data augmentation per device.
- if args.seed is not None:
- set_seed(args.seed, device_specific=True)
-
- # Create repository if push ot hub is specified
- repo_id = handle_repository_creation(accelerator, args)
-
- if args.push_to_hub:
- api = HfApi()
-
- # ------------------------------------------------------------------------------------------------
- # Load dataset, prepare splits
- # ------------------------------------------------------------------------------------------------
-
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
-
- # We need to specify the label2id mapping for the model
- # it is a mapping from semantic class name to class index.
- # In case your dataset does not provide it, you can create it manually:
- # label2id = {"background": 0, "cat": 1, "dog": 2}
- label2id = dataset["train"][0]["semantic_class_to_id"]
-
- if args.do_reduce_labels:
- label2id = {name: idx for name, idx in label2id.items() if idx != 0} # remove background class
- label2id = {name: idx - 1 for name, idx in label2id.items()} # shift class indices by -1
-
- id2label = {v: k for k, v in label2id.items()}
-
- # ------------------------------------------------------------------------------------------------
- # Load pretrained model and image processor
- # ------------------------------------------------------------------------------------------------
- model = AutoModelForUniversalSegmentation.from_pretrained(
- args.model_name_or_path,
- label2id=label2id,
- id2label=id2label,
- ignore_mismatched_sizes=True,
- token=args.hub_token,
- )
-
- image_processor = AutoImageProcessor.from_pretrained(
- args.model_name_or_path,
- do_resize=True,
- size={"height": args.image_height, "width": args.image_width},
- do_reduce_labels=args.do_reduce_labels,
- reduce_labels=args.do_reduce_labels, # TODO: remove when mask2former support `do_reduce_labels`
- token=args.hub_token,
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define image augmentations and dataset transforms
- # ------------------------------------------------------------------------------------------------
- train_augment_and_transform = A.Compose(
- [
- A.HorizontalFlip(p=0.5),
- A.RandomBrightnessContrast(p=0.5),
- A.HueSaturationValue(p=0.1),
- ],
- )
- validation_transform = A.Compose(
- [A.NoOp()],
- )
-
- # Make transform functions for batch and apply for dataset splits
- train_transform_batch = partial(
- augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
- )
- validation_transform_batch = partial(
- augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
- )
-
- with accelerator.main_process_first():
- dataset["train"] = dataset["train"].with_transform(train_transform_batch)
- dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
-
- dataloader_common_args = {
- "num_workers": args.dataloader_num_workers,
- "persistent_workers": True,
- "collate_fn": collate_fn,
- }
- train_dataloader = DataLoader(
- dataset["train"], shuffle=True, batch_size=args.per_device_train_batch_size, **dataloader_common_args
- )
- valid_dataloader = DataLoader(
- dataset["validation"], shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define optimizer, scheduler and prepare everything with the accelerator
- # ------------------------------------------------------------------------------------------------
-
- # Optimizer
- optimizer = torch.optim.AdamW(
- list(model.parameters()),
- lr=args.learning_rate,
- betas=[args.adam_beta1, args.adam_beta2],
- eps=args.adam_epsilon,
- )
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, valid_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, valid_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("instance_segmentation_no_trainer", experiment_config)
-
- # ------------------------------------------------------------------------------------------------
- # Run training with evaluation on each epoch
- # ------------------------------------------------------------------------------------------------
-
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(dataset['train'])}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
-
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
-
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir,
- is_main_process=accelerator.is_main_process,
- save_function=accelerator.save,
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- repo_id=repo_id,
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_type="model",
- token=args.hub_token,
- )
-
- if completed_steps >= args.max_train_steps:
- break
-
- logger.info("***** Running evaluation *****")
- metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
-
- logger.info(f"epoch {epoch}: {metrics}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "train_loss": total_loss.item() / len(train_dataloader),
- **metrics,
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- # ------------------------------------------------------------------------------------------------
- # Run evaluation on test dataset and save the model
- # ------------------------------------------------------------------------------------------------
-
- logger.info("***** Running evaluation on test dataset *****")
- metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
- metrics = {f"test_{k}": v for k, v in metrics.items()}
-
- logger.info(f"Test metrics: {metrics}")
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(metrics, f, indent=2)
-
- image_processor.save_pretrained(args.output_dir)
-
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- ignore_patterns=["epoch_*"],
- )
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/README.md b/examples/pytorch/language-modeling/README.md
deleted file mode 100644
index df268387269e..000000000000
--- a/examples/pytorch/language-modeling/README.md
+++ /dev/null
@@ -1,240 +0,0 @@
-
-
-## Language model training
-
-Fine-tuning (or training from scratch) the library models for language modeling on a text dataset for GPT, GPT-2,
-ALBERT, BERT, DistilBERT, RoBERTa, XLNet... GPT and GPT-2 are trained or fine-tuned using a causal language modeling
-(CLM) loss while ALBERT, BERT, DistilBERT and RoBERTa are trained or fine-tuned using a masked language modeling (MLM)
-loss. XLNet uses permutation language modeling (PLM), you can find more information about the differences between those
-objectives in our [model summary](https://huggingface.co/transformers/model_summary.html).
-
-There are two sets of scripts provided. The first set leverages the Trainer API. The second set with `no_trainer` in the suffix uses a custom training loop and leverages the 🤗 Accelerate library . Both sets use the 🤗 Datasets library. You can easily customize them to your needs if you need extra processing on your datasets.
-
-The following examples, will run on datasets hosted on our [hub](https://huggingface.co/datasets) or with your own
-text files for training and validation. We give examples of both below.
-
-### GPT-2/GPT and causal language modeling
-
-The following example fine-tunes GPT-2 on WikiText-2. We're using the raw WikiText-2 (no tokens were replaced before
-the tokenization). The loss here is that of causal language modeling.
-
-```bash
-python run_clm.py \
- --model_name_or_path openai-community/gpt2 \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-clm
-```
-
-This takes about half an hour to train on a single K80 GPU and about one minute for the evaluation to run. It reaches
-a score of ~20 perplexity once fine-tuned on the dataset.
-
-To run on your own training and validation files, use the following command:
-
-```bash
-python run_clm.py \
- --model_name_or_path openai-community/gpt2 \
- --train_file path_to_train_file \
- --validation_file path_to_validation_file \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-clm
-```
-
-This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_clm_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
-
-```bash
-python run_clm_no_trainer.py \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --model_name_or_path openai-community/gpt2 \
- --output_dir /tmp/test-clm
-```
-
-### GPT-2/GPT and causal language modeling with fill-in-the middle objective
-
-The following example fine-tunes GPT-2 on WikiText-2 but using the Fill-in-middle training objective. FIM objective was proposed in [Efficient Training of Language Models to Fill in the Middle](https://huggingface.co/papers/2207.14255). They showed that autoregressive language models can learn to infill text after applying a straightforward transformation to the dataset, which simply moves a span of text from the middle of a document to its end.
-
-We're using the raw WikiText-2 (no tokens were replaced before the tokenization). The loss here is that of causal language modeling.
-
-```bash
-python run_fim.py \
- --model_name_or_path gpt2 \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --fim_rate 0.5 \
- --fim_spm_rate 0.2 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-clm
-```
-
-To run on your own training and validation files, use the following command:
-
-```bash
-python run_fim.py \
- --model_name_or_path gpt2 \
- --train_file path_to_train_file \
- --validation_file path_to_validation_file \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --fim_rate 0.5 \
- --fim_spm_rate 0.2 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-clm
-```
-
-This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_fim_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
-
-```bash
-python run_fim_no_trainer.py \
- --model_name_or_path gpt2 \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --model_name_or_path gpt2 \
- --fim_rate 0.5 \
- --fim_spm_rate 0.2 \
- --output_dir /tmp/test-clm
-```
-
-**Note**: Passing in FIM rate as `0.5` means that FIM transformations will be applied to the dataset with a probability of 50%. Whereas passing in FIM SPM rate as `0.2` means that 20% of FIM transformations will use SPM (or Suffix-Prefix-Middle) and the remaining 80% will use PSM (or Prefix-Suffix-Middle) mode of transformation.
-
-### RoBERTa/BERT/DistilBERT and masked language modeling
-
-The following example fine-tunes RoBERTa on WikiText-2. Here too, we're using the raw WikiText-2. The loss is different
-as BERT/RoBERTa have a bidirectional mechanism; we're therefore using the same loss that was used during their
-pre-training: masked language modeling.
-
-In accordance to the RoBERTa paper, we use dynamic masking rather than static masking. The model may, therefore,
-converge slightly slower (over-fitting takes more epochs).
-
-```bash
-python run_mlm.py \
- --model_name_or_path FacebookAI/roberta-base \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-mlm
-```
-
-To run on your own training and validation files, use the following command:
-
-```bash
-python run_mlm.py \
- --model_name_or_path FacebookAI/roberta-base \
- --train_file path_to_train_file \
- --validation_file path_to_validation_file \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-mlm
-```
-
-If your dataset is organized with one sample per line, you can use the `--line_by_line` flag (otherwise the script
-concatenates all texts and then splits them in blocks of the same length).
-
-This uses the built in HuggingFace `Trainer` for training. If you want to use a custom training loop, you can utilize or adapt the `run_mlm_no_trainer.py` script. Take a look at the script for a list of supported arguments. An example is shown below:
-
-```bash
-python run_mlm_no_trainer.py \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --model_name_or_path FacebookAI/roberta-base \
- --output_dir /tmp/test-mlm
-```
-
-**Note:** On TPU, you should use the flag `--pad_to_max_length` in conjunction with the `--line_by_line` flag to make
-sure all your batches have the same length.
-
-### Whole word masking
-
-This part was moved to https://github.com/huggingface/transformers-research-projects/tree/main/mlm_wwm.
-
-### XLNet and permutation language modeling
-
-XLNet uses a different training objective, which is permutation language modeling. It is an autoregressive method
-to learn bidirectional contexts by maximizing the expected likelihood over all permutations of the input
-sequence factorization order.
-
-We use the `--plm_probability` flag to define the ratio of length of a span of masked tokens to surrounding
-context length for permutation language modeling.
-
-The `--max_span_length` flag may also be used to limit the length of a span of masked tokens used
-for permutation language modeling.
-
-Here is how to fine-tune XLNet on wikitext-2:
-
-```bash
-python run_plm.py \
- --model_name_or_path=xlnet/xlnet-base-cased \
- --dataset_name Salesforce/wikitext \
- --dataset_config_name wikitext-2-raw-v1 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-plm
-```
-
-To fine-tune it on your own training and validation file, run:
-
-```bash
-python run_plm.py \
- --model_name_or_path=xlnet/xlnet-base-cased \
- --train_file path_to_train_file \
- --validation_file path_to_validation_file \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --do_train \
- --do_eval \
- --output_dir /tmp/test-plm
-```
-
-If your dataset is organized with one sample per line, you can use the `--line_by_line` flag (otherwise the script
-concatenates all texts and then splits them in blocks of the same length).
-
-**Note:** On TPU, you should use the flag `--pad_to_max_length` in conjunction with the `--line_by_line` flag to make
-sure all your batches have the same length.
-
-## Streaming
-
-To use the streaming dataset mode which can be very useful for large datasets, add `--streaming` to the command line. This is supported by `run_mlm.py`, `run_clm.py` and `run_fim.py`. Make sure to adapt the other scripts to your use case by taking inspiration from them.
-
-## Creating a model on the fly
-
-When training a model from scratch, configuration values may be overridden with the help of `--config_overrides`:
-
-
-```bash
-python run_clm.py --model_type gpt2 --tokenizer_name openai-community/gpt2 \ --config_overrides="n_embd=1024,n_head=16,n_layer=48,n_positions=102" \
-[...]
-```
-
-This feature is only available in `run_clm.py`, `run_plm.py`, `run_mlm.py` and `run_fim.py`.
diff --git a/examples/pytorch/language-modeling/requirements.txt b/examples/pytorch/language-modeling/requirements.txt
deleted file mode 100644
index 851e8de09ccd..000000000000
--- a/examples/pytorch/language-modeling/requirements.txt
+++ /dev/null
@@ -1,7 +0,0 @@
-accelerate >= 0.12.0
-torch >= 1.3
-datasets >= 2.14.0
-sentencepiece != 0.1.92
-protobuf
-evaluate
-scikit-learn
diff --git a/examples/pytorch/language-modeling/run_clm.py b/examples/pytorch/language-modeling/run_clm.py
deleted file mode 100755
index a2d0034fb62a..000000000000
--- a/examples/pytorch/language-modeling/run_clm.py
+++ /dev/null
@@ -1,712 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...) on a text file or a dataset.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=text-generation
-"""
-# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
-
-import logging
-import math
-import os
-import sys
-from dataclasses import dataclass, field
-from itertools import chain
-
-import datasets
-import evaluate
-import torch
-from datasets import IterableDataset, IterableDatasetDict, load_dataset
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_FOR_CAUSAL_LM_MAPPING,
- AutoConfig,
- AutoModelForCausalLM,
- AutoTokenizer,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
- is_torch_xla_available,
- set_seed,
-)
-from transformers.testing_utils import CaptureLogger
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_CAUSAL_LM_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
- """
-
- model_name_or_path: str | None = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
- )
- },
- )
- model_type: str | None = field(
- default=None,
- metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- dtype: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
- "dtype will be automatically derived from the model's weights."
- ),
- "choices": ["auto", "bfloat16", "float16", "float32"],
- },
- )
-
- def __post_init__(self):
- if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
- raise ValueError(
- "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
- block_size: int | None = field(
- default=None,
- metadata={
- "help": (
- "Optional input sequence length after tokenization. "
- "The training dataset will be truncated in block of this size for training. "
- "Default to the model max input length for single sentence inputs (take into account special tokens)."
- )
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- validation_split_percentage: int | None = field(
- default=5,
- metadata={
- "help": "The percentage of the train set used as validation set in case there's no validation split"
- },
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- keep_linebreaks: bool = field(
- default=True, metadata={"help": "Whether to keep line breaks when using TXT files or not."}
- )
-
- def __post_init__(self):
- if self.streaming:
- require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
-
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
-
-
-def split_streaming_dataset(
- full_streaming_dataset,
- validation_percentage: int = 5,
-) -> IterableDatasetDict:
- """
- Splits a streaming dataset into
- training and validation IterableDatasets, and supports methods like .map(), .filter(),
- .take() and properties like .features on the resulting streams.
-
- Args:
- full_streaming_dataset (Dataset): The name of the dataset to load (e.g., "HuggingFaceFW/fineweb").
- validation_percentage (int): The proportion of the dataset to be used for validation split.
-
- Returns:
- IterableDatasetDict: An IterableDatasetDict containing two IterableDataset objects: (train_stream, validation_stream).
- """
- if not (0 < validation_percentage < 100):
- raise ValueError(
- f"validation_percentage must be between 0 and 100 (exclusive). Passed: {validation_percentage}"
- )
-
- def split_generator(is_train: bool):
- for i, example in enumerate(full_streaming_dataset):
- if is_train:
- if i % 100 > validation_percentage:
- yield example
- else:
- if i % 100 < validation_percentage:
- yield example
-
- features = full_streaming_dataset.features
- train_stream = IterableDataset.from_generator(split_generator, gen_kwargs={"is_train": True}, features=features)
- validation_stream = IterableDataset.from_generator(
- split_generator, gen_kwargs={"is_train": False}, features=features
- )
-
- return IterableDatasetDict({"train": train_stream, "validation": validation_stream})
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- if "validation" not in raw_datasets:
- if data_args.streaming:
- dataset_stream = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split="train",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- raw_datasets = split_streaming_dataset(dataset_stream, data_args.validation_split_percentage)
- else:
- raw_datasets["validation"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- dataset_args = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = (
- data_args.train_file.split(".")[-1]
- if data_args.train_file is not None
- else data_args.validation_file.split(".")[-1]
- )
- if extension == "txt":
- extension = "text"
- dataset_args["keep_linebreaks"] = data_args.keep_linebreaks
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- if data_args.streaming:
- dataset_stream = load_dataset(
- extension,
- data_files=data_files,
- split="train",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
- raw_datasets = split_streaming_dataset(dataset_stream, data_args.validation_split_percentage)
- else:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
-
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
-
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.config_name:
- config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
- elif model_args.model_name_or_path:
- config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = CONFIG_MAPPING[model_args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- tokenizer_kwargs = {
- "cache_dir": model_args.cache_dir,
- "use_fast": model_args.use_fast_tokenizer,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
- elif model_args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if model_args.model_name_or_path:
- dtype = model_args.dtype if model_args.dtype in ["auto", None] else getattr(torch, model_args.dtype)
- model = AutoModelForCausalLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- dtype=dtype,
- )
- else:
- model = AutoModelForCausalLM.from_config(config, trust_remote_code=model_args.trust_remote_code)
- n_params = sum({p.data_ptr(): p.numel() for p in model.parameters()}.values())
- logger.info(f"Training new model from scratch - Total size={n_params / 2**20:.2f}M params")
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- if training_args.do_train:
- column_names = list(raw_datasets["train"].features)
- else:
- column_names = list(raw_datasets["validation"].features)
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- # since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
- tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
-
- def tokenize_function(examples):
- with CaptureLogger(tok_logger) as cl:
- output = tokenizer(examples[text_column_name])
- # clm input could be much much longer than block_size
- if "Token indices sequence length is longer than the" in cl.out:
- tok_logger.warning(
- "^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits"
- " before being passed to the model."
- )
- return output
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- if not data_args.streaming:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
- else:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- remove_columns=column_names,
- )
- if hasattr(config, "max_position_embeddings"):
- max_pos_embeddings = config.max_position_embeddings
- else:
- # Define a default value if the attribute is missing in the config.
- max_pos_embeddings = 1024
-
- if data_args.block_size is None:
- block_size = tokenizer.model_max_length
- if block_size > max_pos_embeddings:
- logger.warning(
- f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
- f"Using block_size={min(1024, max_pos_embeddings)} instead. You can change that default value by passing --block_size xxx."
- )
- if max_pos_embeddings > 0:
- block_size = min(1024, max_pos_embeddings)
- else:
- block_size = 1024
- else:
- if data_args.block_size > tokenizer.model_max_length:
- logger.warning(
- f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model "
- f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
- )
- block_size = min(data_args.block_size, tokenizer.model_max_length)
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // block_size) * block_size
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
- for k, t in concatenated_examples.items()
- }
- result["labels"] = result["input_ids"].copy()
- return result
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
- # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
- # to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- with training_args.main_process_first(desc="grouping texts together"):
- if not data_args.streaming:
- lm_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc=f"Grouping texts in chunks of {block_size}",
- )
- else:
- lm_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- )
-
- if training_args.do_train:
- if "train" not in tokenized_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = lm_datasets["train"]
- if data_args.max_train_samples is not None:
- if data_args.streaming:
- train_dataset = train_dataset.take(data_args.max_train_samples)
- else:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in tokenized_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = lm_datasets["validation"]
- if data_args.max_eval_samples is not None:
- if data_args.streaming:
- eval_dataset = eval_dataset.take(data_args.max_eval_samples)
- else:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- def preprocess_logits_for_metrics(logits, labels):
- if isinstance(logits, tuple):
- # Depending on the model and config, logits may contain extra tensors,
- # like past_key_values, but logits always come first
- logits = logits[0]
- return logits.argmax(dim=-1)
-
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
-
- def compute_metrics(eval_preds):
- preds, labels = eval_preds
- # preds have the same shape as the labels, after the argmax(-1) has been calculated
- # by preprocess_logits_for_metrics but we need to shift the labels
- labels = labels[:, 1:].reshape(-1)
- preds = preds[:, :-1].reshape(-1)
- return metric.compute(predictions=preds, references=labels)
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- # Data collator will default to DataCollatorWithPadding, so we change it.
- data_collator=default_data_collator,
- compute_metrics=compute_metrics if training_args.do_eval and not is_torch_xla_available() else None,
- preprocess_logits_for_metrics=preprocess_logits_for_metrics
- if training_args.do_eval and not is_torch_xla_available()
- else None,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- if data_args.streaming:
- metrics["train_samples"] = max_train_samples
- else:
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- if data_args.streaming:
- metrics["eval_samples"] = max_eval_samples
- else:
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- try:
- perplexity = math.exp(metrics["eval_loss"])
- except OverflowError:
- perplexity = float("inf")
- metrics["perplexity"] = perplexity
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-generation"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_clm_no_trainer.py b/examples/pytorch/language-modeling/run_clm_no_trainer.py
deleted file mode 100755
index 659c2866330c..000000000000
--- a/examples/pytorch/language-modeling/run_clm_no_trainer.py
+++ /dev/null
@@ -1,737 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for causal language modeling (GPT, GPT-2, CTRL, ...)
-on a text file or a dataset without using HuggingFace Trainer.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=text-generation
-"""
-# You can also adapt this script on your own causal language modeling task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from itertools import chain
-from pathlib import Path
-
-import datasets
-import torch
-from accelerate import Accelerator, DistributedType
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForCausalLM,
- AutoTokenizer,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a causal language modeling task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv, txt or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv, txt or a json file containing the validation data."
- )
- parser.add_argument(
- "--validation_split_percentage",
- default=5,
- help="The percentage of the train set used as validation set in case there's no validation split",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument(
- "--block_size",
- type=int,
- default=None,
- help=(
- "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
- " this size for training. Default to the model max input length for single sentence inputs (take into"
- " account special tokens)."
- ),
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.dataset_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`train_file` should be a csv, json or txt file.")
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`validation_file` should be a csv, json or txt file.")
-
- if args.push_to_hub:
- if args.output_dir is None:
- raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- os.makedirs(args.output_dir, exist_ok=True)
- gitignore_path = os.path.join(args.output_dir, ".gitignore")
- content = ""
- if os.path.exists(gitignore_path):
- with open(gitignore_path, "r", encoding="utf-8") as f:
- content = f.read()
- with open(gitignore_path, "a", encoding="utf-8") as f:
- if content and not content.endswith("\n"):
- f.write("\n")
- if "step_*" not in content:
- f.write("step_*\n")
- if "epoch_*" not in content:
- f.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[:{args.validation_split_percentage}%]",
- trust_remote_code=args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[{args.validation_split_percentage}%:]",
- trust_remote_code=args.trust_remote_code,
- )
- else:
- data_files = {}
- dataset_args = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- if extension == "txt":
- extension = "text"
- dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
- raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{args.validation_split_percentage}%]",
- **dataset_args,
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{args.validation_split_percentage}%:]",
- **dataset_args,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(
- args.config_name,
- trust_remote_code=args.trust_remote_code,
- )
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(
- args.model_name_or_path,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForCausalLM.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForCausalLM.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- column_names = raw_datasets["train"].column_names
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- def tokenize_function(examples):
- return tokenizer(examples[text_column_name])
-
- with accelerator.main_process_first():
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- if args.block_size is None:
- block_size = tokenizer.model_max_length
- if block_size > config.max_position_embeddings:
- logger.warning(
- f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
- f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
- )
- block_size = min(1024, config.max_position_embeddings)
- else:
- if args.block_size > tokenizer.model_max_length:
- logger.warning(
- f"The block_size passed ({args.block_size}) is larger than the maximum length for the model "
- f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
- )
- block_size = min(args.block_size, tokenizer.model_max_length)
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // block_size) * block_size
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
- for k, t in concatenated_examples.items()
- }
- result["labels"] = result["input_ids"].copy()
- return result
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
- # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
- # to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- with accelerator.main_process_first():
- lm_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- load_from_cache_file=not args.overwrite_cache,
- desc=f"Grouping texts in chunks of {block_size}",
- )
-
- train_dataset = lm_datasets["train"]
- eval_dataset = lm_datasets["validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(
- eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
- if accelerator.distributed_type == DistributedType.TPU:
- model.tie_weights()
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("clm_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- losses = []
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
-
- loss = outputs.loss
- losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
-
- losses = torch.cat(losses)
- try:
- eval_loss = torch.mean(losses)
- perplexity = math.exp(eval_loss)
- except OverflowError:
- perplexity = float("inf")
-
- logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "perplexity": perplexity,
- "eval_loss": eval_loss,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump({"perplexity": perplexity}, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_fim.py b/examples/pytorch/language-modeling/run_fim.py
deleted file mode 100644
index 4df34b2a0779..000000000000
--- a/examples/pytorch/language-modeling/run_fim.py
+++ /dev/null
@@ -1,846 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for causal language modeling using
-Fill-in-the middle (FIM) objective on a text file or a dataset.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=text-generation
-"""
-# You should adapt this script on your own causal language modeling task. Pointers for this are left as comments.
-
-import logging
-import math
-import os
-import sys
-from dataclasses import dataclass, field
-from itertools import chain
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_FOR_CAUSAL_LM_MAPPING,
- AutoConfig,
- AutoModelForCausalLM,
- AutoTokenizer,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
- is_torch_xla_available,
- set_seed,
-)
-from transformers.integrations import is_deepspeed_zero3_enabled
-from transformers.testing_utils import CaptureLogger
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_CAUSAL_LM_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
- """
-
- model_name_or_path: str | None = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
- )
- },
- )
- model_type: str | None = field(
- default=None,
- metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- dtype: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
- "dtype will be automatically derived from the model's weights."
- ),
- "choices": ["auto", "bfloat16", "float16", "float32"],
- },
- )
- pad_to_multiple_of: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad the embedding layer to a multiple depending on the device. ",
- "For NVIDIA GPUs, this will be a multiple of 8, for TPUs a multiple of 128.",
- )
- },
- )
- attn_implementation: str | None = field(
- default="sdpa", metadata={"help": ("The attention implementation to use. ")}
- )
-
- def __post_init__(self):
- if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
- raise ValueError(
- "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
- block_size: int | None = field(
- default=None,
- metadata={
- "help": (
- "Optional input sequence length after tokenization. "
- "The training dataset will be truncated in block of this size for training. "
- "Default to the model max input length for single sentence inputs (take into account special tokens)."
- )
- },
- )
- fim_rate: float | None = field(
- default=0.5,
- metadata={
- "help": (
- "Optional probability with which the FIM transformation is applied to the example. "
- "Default is 0.5. A rate of 1.0 means every example will undergo FIM transformation, "
- "while a rate of 0.0 means no example will."
- )
- },
- )
- fim_spm_rate: float | None = field(
- default=0.5,
- metadata={
- "help": (
- "Within the examples undergoing FIM transformation, this rate determines the probability "
- "of applying the Sentence Permutation Mode (SPM). "
- "Default is 0.5. A rate of 1.0 means all FIM transformations will use SPM, "
- "while a rate of 0.0 means none will."
- )
- },
- )
- truncate_or_pad: bool | None = field(
- default=True,
- metadata={
- "help": (
- "Indicates whether the transformed example should be truncated or padded to maintain "
- "the same length as the original example. "
- "Default is True. If False, the function will not truncate or pad the examples."
- )
- },
- )
- fim_prefix_token: str | None = field(
- default="",
- metadata={"help": ("Fill-in-Middle Prefix token. Defaults to ''.")},
- )
- fim_middle_token: str | None = field(
- default="",
- metadata={"help": ("Fill-in-Middle Middle token. Defaults to ''.")},
- )
- fim_suffix_token: str | None = field(
- default="",
- metadata={"help": ("Fill-in-Middle Suffix token. Defaults to ''.")},
- )
- pad_token: str | None = field(
- default="",
- metadata={
- "help": (
- "Fill-in-Middle Pad token. Used only when 'truncate_or_pad' is set to True. Defaults to ''."
- )
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- validation_split_percentage: int | None = field(
- default=5,
- metadata={
- "help": "The percentage of the train set used as validation set in case there's no validation split"
- },
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- keep_linebreaks: bool = field(
- default=True, metadata={"help": "Whether to keep line breaks when using TXT files or not."}
- )
-
- def __post_init__(self):
- if self.streaming:
- require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
-
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Set a numpy random state for FIM transformations
- np_rng = np.random.RandomState(seed=training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- dataset_args = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = (
- data_args.train_file.split(".")[-1]
- if data_args.train_file is not None
- else data_args.validation_file.split(".")[-1]
- )
- if extension == "txt":
- extension = "text"
- dataset_args["keep_linebreaks"] = data_args.keep_linebreaks
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- **dataset_args,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.html.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
-
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.config_name:
- config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
- elif model_args.model_name_or_path:
- config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = CONFIG_MAPPING[model_args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- tokenizer_kwargs = {
- "cache_dir": model_args.cache_dir,
- "use_fast": model_args.use_fast_tokenizer,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
- elif model_args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if model_args.model_name_or_path:
- dtype = model_args.dtype if model_args.dtype in ["auto", None] else getattr(torch, model_args.dtype)
- model = AutoModelForCausalLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- dtype=dtype,
- attn_implementation=model_args.attn_implementation,
- )
-
- else:
- model = AutoModelForCausalLM.from_config(
- config,
- trust_remote_code=model_args.trust_remote_code,
- attn_implementation=model_args.attn_implementation,
- )
- n_params = sum({p.data_ptr(): p.numel() for p in model.parameters()}.values())
- logger.info(f"Training new model from scratch - Total size={n_params / 2**20:.2f}M params")
-
- # Add the new FIM tokens to the tokenizer and resize model's vocab embeddings
- special_tokens = [data_args.fim_prefix_token, data_args.fim_middle_token, data_args.fim_suffix_token]
- if data_args.truncate_or_pad:
- special_tokens.append(data_args.pad_token)
-
- # Get the factor by which the embedding layer should be padded based on the device
- pad_factor = 1
- if torch.cuda.is_available():
- pad_factor = 8
-
- elif is_torch_xla_available(check_is_tpu=True):
- pad_factor = 128
-
- # Add the new tokens to the tokenizer
- tokenizer.add_tokens(special_tokens)
- original_embeddings = model.get_input_embeddings()
-
- if is_deepspeed_zero3_enabled():
- import deepspeed
-
- with deepspeed.zero.GatheredParameters(original_embeddings.weight, modifier_rank=0):
- # Get the pre-expansion embeddings of the model and resize the embedding layer
- model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
- embeddings = model.get_input_embeddings()
-
- # Sample the embeddings for the new tokens from a multivariate normal distribution
- # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
- # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
- mean = original_embeddings.mean(dim=0)
- n = original_embeddings.size()[0]
- sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
- dist = torch.distributions.multivariate_normal.MultivariateNormal(
- mean,
- covariance_matrix=1e-5 * sigma,
- )
- new_token_embeddings = torch.stack(
- tuple(dist.sample() for _ in range(len(special_tokens))),
- dim=0,
- )
- else:
- original_embeddings = model.get_input_embeddings()
- # Get the pre-expansion embeddings of the model and resize the embedding layer
- model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
- embeddings = model.get_input_embeddings()
-
- # Sample the embeddings for the new tokens from a multivariate normal distribution
- # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
- # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
- mean = original_embeddings.mean(dim=0)
- n = original_embeddings.size()[0]
- sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
- dist = torch.distributions.multivariate_normal.MultivariateNormal(
- mean,
- covariance_matrix=1e-5 * sigma,
- )
- new_token_embeddings = torch.stack(
- tuple(dist.sample() for _ in range(len(special_tokens))),
- dim=0,
- )
-
- if is_deepspeed_zero3_enabled():
- import deepspeed
-
- with deepspeed.zero.GatheredParameters(embeddings.weight, modifier_rank=0):
- # Set the new tokens' embeddings to the newly sampled embeddings
- embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
- else:
- # Set the new tokens' embeddings to the newly sampled embeddings
- embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
-
- # Update the model's embeddings with the new embeddings
- model.set_input_embeddings(embeddings)
-
- logger.info("Added special tokens to the tokenizer and resized model's embedding layer")
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- if training_args.do_train:
- column_names = list(raw_datasets["train"].features)
- else:
- column_names = list(raw_datasets["validation"].features)
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- # since this will be pickled to avoid _LazyModule error in Hasher force logger loading before tokenize_function
- tok_logger = transformers.utils.logging.get_logger("transformers.tokenization_utils_base")
-
- def tokenize_function(examples):
- with CaptureLogger(tok_logger) as cl:
- output = tokenizer(examples[text_column_name])
- # clm-fim input could be much much longer than block_size
- if "Token indices sequence length is longer than the" in cl.out:
- tok_logger.warning(
- "^^^^^^^^^^^^^^^^ Please ignore the warning above - this long input will be chunked into smaller bits"
- " before being passed to the model."
- )
- return output
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- if not data_args.streaming:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
- else:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- remove_columns=column_names,
- )
-
- if data_args.block_size is None:
- block_size = tokenizer.model_max_length
- if block_size > config.max_position_embeddings:
- logger.warning(
- f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
- f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
- )
- block_size = min(1024, config.max_position_embeddings)
- else:
- if data_args.block_size > tokenizer.model_max_length:
- logger.warning(
- f"The block_size passed ({data_args.block_size}) is larger than the maximum length for the model "
- f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
- )
- block_size = min(data_args.block_size, tokenizer.model_max_length)
-
- # Data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // block_size) * block_size
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
- for k, t in concatenated_examples.items()
- }
- result["labels"] = result["input_ids"].copy()
- return result
-
- # Get the FIM-specific token ids
- prefix_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_prefix_token)
- middle_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_middle_token)
- suffix_tok_id = tokenizer.convert_tokens_to_ids(data_args.fim_suffix_token)
- pad_tok_id = None
-
- # If truncate_or_pad is on, also get pad token id
- if data_args.truncate_or_pad:
- pad_tok_id = tokenizer.convert_tokens_to_ids(data_args.pad_token)
-
- # The two functions below perform the FIM transformation on the data (either PSM or SPM or PSM+SPM)
- # Don't call fim_transform directly in .map()
- # Adapted from https://github.com/loubnabnl/santacoder-finetuning/blob/main/fim.py#L22C13-L83
- def fim_transform(example):
- """
- This function performs FIM transformation on a single example (list of tokens)
- """
- if np_rng.binomial(1, data_args.fim_rate):
- boundaries = sorted(np_rng.randint(low=0, high=len(example) + 1, size=2))
-
- prefix = example[: boundaries[0]]
- middle = example[boundaries[0] : boundaries[1]]
- suffix = example[boundaries[1] :]
-
- if data_args.truncate_or_pad:
- total_length = len(prefix) + len(middle) + len(suffix) + 3
- diff = total_length - len(example)
- if diff > 0:
- suffix = suffix[: max(0, len(suffix) - diff)]
- elif diff < 0:
- suffix.extend([pad_tok_id] * (-diff))
-
- if np_rng.binomial(1, data_args.fim_spm_rate):
- # Apply Suffix-Prefix-Middle (SPM) transformation
- transformed_example = [prefix_tok_id, suffix_tok_id] + suffix + [middle_tok_id] + prefix + middle
- else:
- # Apply Prefix-Suffix-Middle (PSM) transformation
- transformed_example = [prefix_tok_id] + prefix + [suffix_tok_id] + suffix + [middle_tok_id] + middle
- else:
- transformed_example = example
-
- return transformed_example
-
- # Below function is the one you are supposed to call in the .map() function
- def apply_fim(examples):
- """
- Apply FIM transformation to a batch of examples
- """
- fim_transform_ids = [fim_transform(ids) for ids in examples["input_ids"]]
- examples["input_ids"] = fim_transform_ids
- examples["labels"] = fim_transform_ids
- # If your application requires custom attention mask, please adjust this function's below line.
- # Since FIM transformation increases the number of tokens in input_ids and labels
- # but leaves the number of tokens unchanged in attention_masks which would cause problems
- examples["attention_mask"] = [[1] * len(mask) for mask in examples["input_ids"]]
- return examples
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
- # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
- # to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- # FIM transformations are only supposed to be applied before group_texts processing otherwise some sentences will
- # have 3-4 more tokens than others due to probabilistic addition of FIM-specific tokens which will raise errors
- with training_args.main_process_first(desc="processing texts together"):
- if not data_args.streaming:
- fim_datasets = tokenized_datasets.map(
- apply_fim,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Performing FIM transformation",
- )
- lm_datasets = fim_datasets.map(
- group_texts,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc=f"Grouping texts in chunks of {block_size}",
- )
- else:
- fim_datasets = tokenized_datasets.map(
- apply_fim,
- batched=True,
- )
- lm_datasets = fim_datasets.map(
- group_texts,
- batched=True,
- )
-
- if training_args.do_train:
- if "train" not in tokenized_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = lm_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in tokenized_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = lm_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- def preprocess_logits_for_metrics(logits, labels):
- if isinstance(logits, tuple):
- # Depending on the model and config, logits may contain extra tensors,
- # like past_key_values, but logits always come first
- logits = logits[0]
- return logits.argmax(dim=-1)
-
- metric = evaluate.load("accuracy")
-
- def compute_metrics(eval_preds):
- preds, labels = eval_preds
- # preds have the same shape as the labels, after the argmax(-1) has been calculated
- # by preprocess_logits_for_metrics but we need to shift the labels
- labels = labels[:, 1:].reshape(-1)
- preds = preds[:, :-1].reshape(-1)
- return metric.compute(predictions=preds, references=labels)
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- # Data collator will default to DataCollatorWithPadding, so we change it.
- data_collator=default_data_collator,
- compute_metrics=compute_metrics
- if training_args.do_eval and not is_torch_xla_available(check_is_tpu=True)
- else None,
- preprocess_logits_for_metrics=(
- preprocess_logits_for_metrics
- if training_args.do_eval and not is_torch_xla_available(check_is_tpu=True)
- else None
- ),
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
- try:
- perplexity = math.exp(metrics["eval_loss"])
- except OverflowError:
- perplexity = float("inf")
- metrics["perplexity"] = perplexity
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-generation"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_fim_no_trainer.py b/examples/pytorch/language-modeling/run_fim_no_trainer.py
deleted file mode 100644
index b6bdc3a552c8..000000000000
--- a/examples/pytorch/language-modeling/run_fim_no_trainer.py
+++ /dev/null
@@ -1,918 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for causal language modeling using
-Fill-in-the middle (FIM) objective on a text file or a dataset without using HuggingFace Trainer.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=text-generation
-"""
-# You can also adapt this script on your own fim causal language modeling task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from itertools import chain
-from pathlib import Path
-
-import datasets
-import numpy as np
-import torch
-from accelerate import Accelerator, DistributedType
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import Repository, create_repo
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForCausalLM,
- AutoTokenizer,
- SchedulerType,
- default_data_collator,
- get_scheduler,
- is_torch_xla_available,
-)
-from transformers.integrations import is_deepspeed_zero3_enabled
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(
- description="Finetune a transformers model on a causal language modeling task using fill-in-the middle objective"
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv, txt or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv, txt or a json file containing the validation data."
- )
- parser.add_argument(
- "--validation_split_percentage",
- default=5,
- help="The percentage of the train set used as validation set in case there's no validation split",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=42, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument(
- "--block_size",
- type=int,
- default=None,
- help=(
- "Optional input sequence length after tokenization. The training dataset will be truncated in block of"
- " this size for training. Default to the model max input length for single sentence inputs (take into"
- " account special tokens)."
- ),
- )
- parser.add_argument(
- "--fim_rate",
- type=float,
- default=0.5,
- help=(
- " Optional probability with which the FIM transformation is applied to the example."
- " Default is 0.5. A rate of 1.0 means every example will undergo FIM transformation,"
- " while a rate of 0.0 means no example will."
- ),
- )
- parser.add_argument(
- "--fim_spm_rate",
- type=float,
- default=0.5,
- help=(
- "Within the examples undergoing FIM transformation, this rate determines the probability"
- " of applying the Sentence Permutation Mode (SPM)."
- " Default is 0.5. A rate of 1.0 means all FIM transformations will use SPM,"
- " while a rate of 0.0 means none will."
- ),
- )
- parser.add_argument(
- "--truncate_or_pad",
- type=bool,
- default=True,
- help=(
- "Indicates whether the transformed example should be truncated or padded to maintain"
- " the same length as the original example."
- " Default is True. If False, the function will not truncate or pad the examples."
- ),
- )
- parser.add_argument(
- "--fim_prefix_token",
- type=str,
- default="",
- help="Fill-in-Middle Prefix token. Defaults to ''.",
- )
- parser.add_argument(
- "--fim_middle_token",
- type=str,
- default="",
- help="Fill-in-Middle Middle token. Defaults to ''.",
- )
- parser.add_argument(
- "--fim_suffix_token",
- type=str,
- default="",
- help="Fill-in-Middle Middle token. Defaults to ''.",
- )
- parser.add_argument(
- "--fim_pad_token",
- type=str,
- default="",
- help=("Fill-in-Middle Pad token. Used only when 'truncate_or_pad' is set to True. Defaults to ''."),
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--no_keep_linebreaks", action="store_true", help="Do not keep line breaks when using TXT files."
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.dataset_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`train_file` should be a csv, json or txt file.")
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`validation_file` should be a csv, json or txt file.")
-
- if args.push_to_hub:
- if args.output_dir is None:
- raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
- # Set a numpy random state for FIM transformations
- np_rng = np.random.RandomState(seed=args.seed)
- else:
- # Still set a random state for FIM transformations
- np_rng = np.random.RandomState(seed=42)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- repo_id = create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
- # Clone repo locally
- repo = Repository(args.output_dir, clone_from=repo_id, token=args.hub_token)
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[:{args.validation_split_percentage}%]",
- trust_remote_code=args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[{args.validation_split_percentage}%:]",
- trust_remote_code=args.trust_remote_code,
- )
- else:
- data_files = {}
- dataset_args = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.train_file.split(".")[-1]
- if extension == "txt":
- extension = "text"
- dataset_args["keep_linebreaks"] = not args.no_keep_linebreaks
- raw_datasets = load_dataset(extension, data_files=data_files, **dataset_args)
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{args.validation_split_percentage}%]",
- **dataset_args,
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{args.validation_split_percentage}%:]",
- **dataset_args,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.html.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(
- args.config_name,
- trust_remote_code=args.trust_remote_code,
- )
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(
- args.model_name_or_path,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForCausalLM.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForCausalLM.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # Add the new FIM tokens to the tokenizer and resize model's vocab embeddings
- special_tokens = [args.fim_prefix_token, args.fim_middle_token, args.fim_suffix_token]
- if args.truncate_or_pad:
- special_tokens.append(args.fim_pad_token)
-
- # Get the factor by which the embedding layer should be padded based on the device
- pad_factor = 1
- if torch.cuda.is_available():
- pad_factor = 8
-
- elif is_torch_xla_available(check_is_tpu=True):
- pad_factor = 128
-
- # Add the new tokens to the tokenizer
- tokenizer.add_tokens(special_tokens)
- original_embeddings = model.get_input_embeddings()
-
- if is_deepspeed_zero3_enabled():
- import deepspeed
-
- with deepspeed.zero.GatheredParameters(original_embeddings.weight, modifier_rank=0):
- # Get the pre-expansion embeddings of the model and resize the embedding layer
- model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
- embeddings = model.get_input_embeddings()
-
- # Sample the embeddings for the new tokens from a multivariate normal distribution
- # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
- # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
- mean = original_embeddings.mean(dim=0)
- n = original_embeddings.size()[0]
- sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
- dist = torch.distributions.multivariate_normal.MultivariateNormal(
- mean,
- covariance_matrix=1e-5 * sigma,
- )
- new_token_embeddings = torch.stack(
- tuple(dist.sample() for _ in range(len(special_tokens))),
- dim=0,
- )
- else:
- original_embeddings = model.get_input_embeddings()
- # Get the pre-expansion embeddings of the model and resize the embedding layer
- model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=pad_factor)
- embeddings = model.get_input_embeddings()
-
- # Sample the embeddings for the new tokens from a multivariate normal distribution
- # We do this so that the new embeddings are close to the original embeddings and not necessarily zero
- # More on this: https://nlp.stanford.edu/~johnhew/vocab-expansion.html
- mean = original_embeddings.mean(dim=0)
- n = original_embeddings.size()[0]
- sigma = ((original_embeddings - mean).T @ (original_embeddings - mean)) / n
- dist = torch.distributions.multivariate_normal.MultivariateNormal(
- mean,
- covariance_matrix=1e-5 * sigma,
- )
- new_token_embeddings = torch.stack(
- tuple(dist.sample() for _ in range(len(special_tokens))),
- dim=0,
- )
-
- if is_deepspeed_zero3_enabled():
- import deepspeed
-
- with deepspeed.zero.GatheredParameters(embeddings.weight, modifier_rank=0):
- # Set the new tokens' embeddings to the newly sampled embeddings
- embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
- else:
- # Set the new tokens' embeddings to the newly sampled embeddings
- embeddings.weight.data[-len(special_tokens) :] = new_token_embeddings
-
- # Update the model's embeddings with the new embeddings
- model.set_input_embeddings(embeddings)
-
- logger.info("Added special tokens to the tokenizer and resized model's embedding layer")
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- column_names = raw_datasets["train"].column_names
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- def tokenize_function(examples):
- return tokenizer(examples[text_column_name])
-
- with accelerator.main_process_first():
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- if args.block_size is None:
- block_size = tokenizer.model_max_length
- if block_size > config.max_position_embeddings:
- logger.warning(
- f"The tokenizer picked seems to have a very large `model_max_length` ({tokenizer.model_max_length}). "
- f"Using block_size={min(1024, config.max_position_embeddings)} instead. You can change that default value by passing --block_size xxx."
- )
- block_size = min(1024, config.max_position_embeddings)
- else:
- if args.block_size > tokenizer.model_max_length:
- logger.warning(
- f"The block_size passed ({args.block_size}) is larger than the maximum length for the model "
- f"({tokenizer.model_max_length}). Using block_size={tokenizer.model_max_length}."
- )
- block_size = min(args.block_size, tokenizer.model_max_length)
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of block_size.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < block_size we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // block_size) * block_size
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
- for k, t in concatenated_examples.items()
- }
- result["labels"] = result["input_ids"].copy()
- return result
-
- # Get the FIM-specific token ids
- prefix_tok_id = tokenizer.convert_tokens_to_ids(args.fim_prefix_token)
- middle_tok_id = tokenizer.convert_tokens_to_ids(args.fim_middle_token)
- suffix_tok_id = tokenizer.convert_tokens_to_ids(args.fim_suffix_token)
- pad_tok_id = None
-
- # If truncate_or_pad is on, also get pad token id
- if args.truncate_or_pad:
- pad_tok_id = tokenizer.convert_tokens_to_ids(args.fim_pad_token)
-
- # The two functions below perform the FIM transformation on the data (either PSM or SPM or PSM+SPM)
- # Don't call fim_transform directly in .map()
- # Adapted from https://github.com/loubnabnl/santacoder-finetuning/blob/main/fim.py#L22C13-L83
- def fim_transform(example):
- """
- This function performs FIM transformation on a single example (list of tokens)
- """
- if np_rng.binomial(1, args.fim_rate):
- boundaries = sorted(np_rng.randint(low=0, high=len(example) + 1, size=2))
-
- prefix = example[: boundaries[0]]
- middle = example[boundaries[0] : boundaries[1]]
- suffix = example[boundaries[1] :]
-
- if args.truncate_or_pad:
- total_length = len(prefix) + len(middle) + len(suffix) + 3
- diff = total_length - len(example)
- if diff > 0:
- suffix = suffix[: max(0, len(suffix) - diff)]
- elif diff < 0:
- suffix.extend([pad_tok_id] * (-diff))
-
- if np_rng.binomial(1, args.fim_spm_rate):
- # Apply Suffix-Prefix-Middle (SPM) transformation
- transformed_example = [prefix_tok_id, suffix_tok_id] + suffix + [middle_tok_id] + prefix + middle
- else:
- # Apply Prefix-Suffix-Middle (PSM) transformation
- transformed_example = [prefix_tok_id] + prefix + [suffix_tok_id] + suffix + [middle_tok_id] + middle
- else:
- transformed_example = example
-
- return transformed_example
-
- # Below function is the one you are supposed to call in the .map() function
- def apply_fim(examples):
- """
- Apply FIM transformation to a batch of examples
- """
- fim_transform_ids = [fim_transform(ids) for ids in examples["input_ids"]]
- examples["input_ids"] = fim_transform_ids
- examples["labels"] = fim_transform_ids
- # If your application requires custom attention mask, please adjust this function's below line.
- # Since FIM transformation increases the number of tokens in input_ids and labels
- # but leaves the number of tokens unchanged in attention_masks which would cause problems
- examples["attention_mask"] = [[1] * len(mask) for mask in examples["input_ids"]]
- return examples
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a remainder
- # for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value might be slower
- # to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- # FIM transformations are only supposed to be applied before group_texts processing otherwise some sentences will
- # have 3-4 more tokens than others due to probabilistic addition of FIM-specific tokens which will raise errors
- with accelerator.main_process_first():
- fim_datasets = tokenized_datasets.map(
- apply_fim,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- load_from_cache_file=not args.overwrite_cache,
- desc="Performing FIM transformation",
- )
- lm_datasets = fim_datasets.map(
- group_texts,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- load_from_cache_file=not args.overwrite_cache,
- desc=f"Grouping texts in chunks of {block_size}",
- )
-
- train_dataset = lm_datasets["train"]
- eval_dataset = lm_datasets["validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(
- eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * args.gradient_accumulation_steps,
- num_training_steps=args.max_train_steps * args.gradient_accumulation_steps,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
- if accelerator.distributed_type == DistributedType.TPU:
- model.tie_weights()
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("fim_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- losses = []
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
-
- loss = outputs.loss
- losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
-
- losses = torch.cat(losses)
- try:
- eval_loss = torch.mean(losses)
- perplexity = math.exp(eval_loss)
- except OverflowError:
- perplexity = float("inf")
-
- logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "perplexity": perplexity,
- "eval_loss": eval_loss,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- repo.push_to_hub(
- commit_message=f"Training in progress epoch {epoch}", blocking=False, auto_lfs_prune=True
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- repo.push_to_hub(commit_message="End of training", auto_lfs_prune=True)
-
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump({"perplexity": perplexity}, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_mlm.py b/examples/pytorch/language-modeling/run_mlm.py
deleted file mode 100755
index 129a2f7952cb..000000000000
--- a/examples/pytorch/language-modeling/run_mlm.py
+++ /dev/null
@@ -1,670 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...) on a text file or a dataset.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=fill-mask
-"""
-# You can also adapt this script on your own masked language modeling task. Pointers for this are left as comments.
-
-import logging
-import math
-import os
-import sys
-from dataclasses import dataclass, field
-from itertools import chain
-
-import datasets
-import evaluate
-import torch
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_FOR_MASKED_LM_MAPPING,
- AutoConfig,
- AutoModelForMaskedLM,
- AutoTokenizer,
- DataCollatorForLanguageModeling,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- is_torch_xla_available,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-logger = logging.getLogger(__name__)
-MODEL_CONFIG_CLASSES = list(MODEL_FOR_MASKED_LM_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
- """
-
- model_name_or_path: str | None = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
- )
- },
- )
- model_type: str | None = field(
- default=None,
- metadata={"help": "If training from scratch, pass a model type from the list: " + ", ".join(MODEL_TYPES)},
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- dtype: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override the default `torch.dtype` and load the model under this dtype. If `auto` is passed, the "
- "dtype will be automatically derived from the model's weights."
- ),
- "choices": ["auto", "bfloat16", "float16", "float32"],
- },
- )
-
- def __post_init__(self):
- if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
- raise ValueError(
- "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- validation_split_percentage: int | None = field(
- default=5,
- metadata={
- "help": "The percentage of the train set used as validation set in case there's no validation split"
- },
- )
- max_seq_length: int | None = field(
- default=None,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated."
- )
- },
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- mlm_probability: float = field(
- default=0.15, metadata={"help": "Ratio of tokens to mask for masked language modeling loss"}
- )
- line_by_line: bool = field(
- default=False,
- metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- streaming: bool = field(default=False, metadata={"help": "Enable streaming mode"})
-
- def __post_init__(self):
- if self.streaming:
- require_version("datasets>=2.0.0", "The streaming feature requires `datasets>=2.0.0`")
-
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`train_file` should be a csv, a json or a txt file.")
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`validation_file` should be a csv, a json or a txt file.")
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- # Set the verbosity to info of the Transformers logger (on main process only):
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column. You can easily tweak this
- # behavior (see below)
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- streaming=data_args.streaming,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if extension == "txt":
- extension = "text"
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
-
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.config_name:
- config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
- elif model_args.model_name_or_path:
- config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = CONFIG_MAPPING[model_args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- tokenizer_kwargs = {
- "cache_dir": model_args.cache_dir,
- "use_fast": model_args.use_fast_tokenizer,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- if model_args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
- elif model_args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if model_args.model_name_or_path:
- dtype = model_args.dtype if model_args.dtype in ["auto", None] else getattr(torch, model_args.dtype)
- model = AutoModelForMaskedLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- dtype=dtype,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForMaskedLM.from_config(config, trust_remote_code=model_args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- if training_args.do_train:
- column_names = list(raw_datasets["train"].features)
- else:
- column_names = list(raw_datasets["validation"].features)
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- if data_args.max_seq_length is None:
- max_seq_length = tokenizer.model_max_length
- if max_seq_length > 1024:
- logger.warning(
- "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
- " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
- " override this default with `--block_size xxx`."
- )
- max_seq_length = 1024
- else:
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- if data_args.line_by_line:
- # When using line_by_line, we just tokenize each nonempty line.
- padding = "max_length" if data_args.pad_to_max_length else False
-
- def tokenize_function(examples):
- # Remove empty lines
- examples[text_column_name] = [
- line for line in examples[text_column_name] if len(line) > 0 and not line.isspace()
- ]
- return tokenizer(
- examples[text_column_name],
- padding=padding,
- truncation=True,
- max_length=max_seq_length,
- # We use this option because DataCollatorForLanguageModeling (see below) is more efficient when it
- # receives the `special_tokens_mask`.
- return_special_tokens_mask=True,
- )
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- if not data_args.streaming:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=[text_column_name],
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset line_by_line",
- )
- else:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- remove_columns=[text_column_name],
- )
- else:
- # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
- # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
- # efficient when it receives the `special_tokens_mask`.
- def tokenize_function(examples):
- return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- if not data_args.streaming:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on every text in dataset",
- )
- else:
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- remove_columns=column_names,
- )
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of
- # max_seq_length.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // max_seq_length) * max_seq_length
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
- for k, t in concatenated_examples.items()
- }
- return result
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
- # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
- # might be slower to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- with training_args.main_process_first(desc="grouping texts together"):
- if not data_args.streaming:
- tokenized_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc=f"Grouping texts in chunks of {max_seq_length}",
- )
- else:
- tokenized_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- )
-
- if training_args.do_train:
- if "train" not in tokenized_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = tokenized_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in tokenized_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = tokenized_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- def preprocess_logits_for_metrics(logits, labels):
- if isinstance(logits, tuple):
- # Depending on the model and config, logits may contain extra tensors,
- # like past_key_values, but logits always come first
- logits = logits[0]
- return logits.argmax(dim=-1)
-
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
-
- def compute_metrics(eval_preds):
- preds, labels = eval_preds
- # preds have the same shape as the labels, after the argmax(-1) has been calculated
- # by preprocess_logits_for_metrics
- labels = labels.reshape(-1)
- preds = preds.reshape(-1)
- mask = labels != -100
- labels = labels[mask]
- preds = preds[mask]
- return metric.compute(predictions=preds, references=labels)
-
- # Data collator
- # This one will take care of randomly masking the tokens.
- pad_to_multiple_of_8 = data_args.line_by_line and training_args.fp16 and not data_args.pad_to_max_length
- data_collator = DataCollatorForLanguageModeling(
- tokenizer=tokenizer,
- mlm_probability=data_args.mlm_probability,
- pad_to_multiple_of=8 if pad_to_multiple_of_8 else None,
- )
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics if training_args.do_eval and not is_torch_xla_available() else None,
- preprocess_logits_for_metrics=preprocess_logits_for_metrics
- if training_args.do_eval and not is_torch_xla_available()
- else None,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
- try:
- perplexity = math.exp(metrics["eval_loss"])
- except OverflowError:
- perplexity = float("inf")
- metrics["perplexity"] = perplexity
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "fill-mask"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_mlm_no_trainer.py b/examples/pytorch/language-modeling/run_mlm_no_trainer.py
deleted file mode 100755
index 714abf6acd55..000000000000
--- a/examples/pytorch/language-modeling/run_mlm_no_trainer.py
+++ /dev/null
@@ -1,767 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for masked language modeling (BERT, ALBERT, RoBERTa...)
-on a text file or a dataset without using HuggingFace Trainer.
-
-Here is the full list of checkpoints on the hub that can be fine-tuned by this script:
-https://huggingface.co/models?filter=fill-mask
-"""
-# You can also adapt this script on your own mlm task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from itertools import chain
-from pathlib import Path
-
-import datasets
-import torch
-from accelerate import Accelerator, DistributedType
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForMaskedLM,
- AutoTokenizer,
- DataCollatorForLanguageModeling,
- SchedulerType,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a Masked Language Modeling task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--validation_split_percentage",
- default=5,
- help="The percentage of the train set used as validation set in case there's no validation split",
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument(
- "--max_seq_length",
- type=int,
- default=None,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated."
- ),
- )
- parser.add_argument(
- "--line_by_line",
- type=bool,
- default=False,
- help="Whether distinct lines of text in the dataset are to be handled as distinct sequences.",
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--mlm_probability", type=float, default=0.15, help="Ratio of tokens to mask for masked language modeling loss"
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.dataset_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`train_file` should be a csv, json or txt file.")
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- if extension not in ["csv", "json", "txt"]:
- raise ValueError("`validation_file` should be a csv, json or txt file.")
-
- if args.push_to_hub:
- if args.output_dir is None:
- raise ValueError("Need an `output_dir` to create a repo when `--push_to_hub` is passed.")
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[:{args.validation_split_percentage}%]",
- trust_remote_code=args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- args.dataset_name,
- args.dataset_config_name,
- split=f"train[{args.validation_split_percentage}%:]",
- trust_remote_code=args.trust_remote_code,
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- if extension == "txt":
- extension = "text"
- raw_datasets = load_dataset(extension, data_files=data_files)
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{args.validation_split_percentage}%]",
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{args.validation_split_percentage}%:]",
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForMaskedLM.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForMaskedLM.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- column_names = raw_datasets["train"].column_names
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- if args.max_seq_length is None:
- max_seq_length = tokenizer.model_max_length
- if max_seq_length > 1024:
- logger.warning(
- "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
- " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
- " override this default with `--block_size xxx`."
- )
- max_seq_length = 1024
- else:
- if args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
-
- if args.line_by_line:
- # When using line_by_line, we just tokenize each nonempty line.
- padding = "max_length" if args.pad_to_max_length else False
-
- def tokenize_function(examples):
- # Remove empty lines
- examples[text_column_name] = [
- line for line in examples[text_column_name] if len(line) > 0 and not line.isspace()
- ]
- return tokenizer(
- examples[text_column_name],
- padding=padding,
- truncation=True,
- max_length=max_seq_length,
- # We use this option because DataCollatorForLanguageModeling (see below) is more efficient when it
- # receives the `special_tokens_mask`.
- return_special_tokens_mask=True,
- )
-
- with accelerator.main_process_first():
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=[text_column_name],
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset line_by_line",
- )
- else:
- # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
- # We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
- # efficient when it receives the `special_tokens_mask`.
- def tokenize_function(examples):
- return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
-
- with accelerator.main_process_first():
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on every text in dataset",
- )
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of
- # max_seq_length.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // max_seq_length) * max_seq_length
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
- for k, t in concatenated_examples.items()
- }
- return result
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
- # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
- # might be slower to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- with accelerator.main_process_first():
- tokenized_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- load_from_cache_file=not args.overwrite_cache,
- desc=f"Grouping texts in chunks of {max_seq_length}",
- )
-
- train_dataset = tokenized_datasets["train"]
- eval_dataset = tokenized_datasets["validation"]
-
- # Conditional for small test subsets
- if len(train_dataset) > 3:
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # Data collator
- # This one will take care of randomly masking the tokens.
- data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=args.mlm_probability)
-
- # DataLoaders creation:
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Note -> the training dataloader needs to be prepared before we grab his length below (cause its length will be
- # shorter in multiprocess)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # On TPU, the tie weights in our model have been disconnected, so we need to restore the ties.
- if accelerator.distributed_type == DistributedType.TPU:
- model.tie_weights()
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("mlm_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- losses = []
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
-
- loss = outputs.loss
- losses.append(accelerator.gather_for_metrics(loss.repeat(args.per_device_eval_batch_size)))
-
- losses = torch.cat(losses)
- try:
- eval_loss = torch.mean(losses)
- perplexity = math.exp(eval_loss)
- except OverflowError:
- perplexity = float("inf")
-
- logger.info(f"epoch {epoch}: perplexity: {perplexity} eval_loss: {eval_loss}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "perplexity": perplexity,
- "eval_loss": eval_loss,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump({"perplexity": perplexity}, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/language-modeling/run_plm.py b/examples/pytorch/language-modeling/run_plm.py
deleted file mode 100755
index 709ba74ce985..000000000000
--- a/examples/pytorch/language-modeling/run_plm.py
+++ /dev/null
@@ -1,567 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "accelerate >= 0.12.0",
-# "torch >= 1.3",
-# "datasets >= 2.14.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "evaluate",
-# "scikit-learn",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for permutation language modeling.
-"""
-# You can also adapt this script on your own permutation language modeling task. Pointers for this are left as comments.
-
-import logging
-import math
-import os
-import sys
-from dataclasses import dataclass, field
-from itertools import chain
-
-import datasets
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoTokenizer,
- DataCollatorForPermutationLanguageModeling,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- XLNetConfig,
- XLNetLMHeadModel,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.14.0", "To fix: pip install -r examples/pytorch/language-modeling/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune, or train from scratch.
- """
-
- model_name_or_path: str | None = field(
- default=None,
- metadata={
- "help": (
- "The model checkpoint for weights initialization. Don't set if you want to train a model from scratch."
- )
- },
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- config_overrides: str | None = field(
- default=None,
- metadata={
- "help": (
- "Override some existing default config settings when a model is trained from scratch. Example: "
- "n_embd=10,resid_pdrop=0.2,scale_attn_weights=false,summary_type=cls_index"
- )
- },
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
-
- def __post_init__(self):
- if self.config_overrides is not None and (self.config_name is not None or self.model_name_or_path is not None):
- raise ValueError(
- "--config_overrides can't be used in combination with --config_name or --model_name_or_path"
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- validation_split_percentage: int | None = field(
- default=5,
- metadata={
- "help": "The percentage of the train set used as validation set in case there's no validation split"
- },
- )
- max_seq_length: int = field(
- default=512,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated."
- )
- },
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- plm_probability: float = field(
- default=1 / 6,
- metadata={
- "help": (
- "Ratio of length of a span of masked tokens to surrounding context length for "
- "permutation language modeling."
- )
- },
- )
- max_span_length: int = field(
- default=5, metadata={"help": "Maximum length of a span of masked tokens for permutation language modeling."}
- )
- line_by_line: bool = field(
- default=False,
- metadata={"help": "Whether distinct lines of text in the dataset are to be handled as distinct sequences."},
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
-
- def __post_init__(self):
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`train_file` should be a csv, a json or a txt file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json", "txt"], "`validation_file` should be a csv, a json or a txt file."
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if extension == "txt":
- extension = "text"
- raw_datasets = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
- # If no validation data is there, validation_split_percentage will be used to divide the dataset.
- if "validation" not in raw_datasets:
- raw_datasets["validation"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[:{data_args.validation_split_percentage}%]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- raw_datasets["train"] = load_dataset(
- extension,
- data_files=data_files,
- split=f"train[{data_args.validation_split_percentage}%:]",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
-
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config_kwargs = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- }
- if model_args.config_name:
- config = AutoConfig.from_pretrained(model_args.config_name, **config_kwargs)
- elif model_args.model_name_or_path:
- config = AutoConfig.from_pretrained(model_args.model_name_or_path, **config_kwargs)
- else:
- config = XLNetConfig()
- logger.warning("You are instantiating a new config instance from scratch.")
- if model_args.config_overrides is not None:
- logger.info(f"Overriding config: {model_args.config_overrides}")
- config.update_from_string(model_args.config_overrides)
- logger.info(f"New config: {config}")
-
- tokenizer_kwargs = {
- "cache_dir": model_args.cache_dir,
- "use_fast": model_args.use_fast_tokenizer,
- "revision": model_args.model_revision,
- "token": model_args.token,
- }
- if model_args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(model_args.tokenizer_name, **tokenizer_kwargs)
- elif model_args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(model_args.model_name_or_path, **tokenizer_kwargs)
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if model_args.model_name_or_path:
- model = XLNetLMHeadModel.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- )
- else:
- logger.info("Training new model from scratch")
- model = XLNetLMHeadModel(config)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- else:
- column_names = raw_datasets["validation"].column_names
- text_column_name = "text" if "text" in column_names else column_names[0]
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- if data_args.line_by_line:
- # When using line_by_line, we just tokenize each nonempty line.
- padding = "max_length" if data_args.pad_to_max_length else False
-
- def tokenize_function(examples):
- # Remove empty lines
- examples["text"] = [line for line in examples["text"] if len(line) > 0 and not line.isspace()]
- return tokenizer(examples["text"], padding=padding, truncation=True, max_length=max_seq_length)
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=[text_column_name],
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset line_by_line",
- )
- else:
- # Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
- def tokenize_function(examples):
- return tokenizer(examples[text_column_name])
-
- with training_args.main_process_first(desc="dataset map tokenization"):
- tokenized_datasets = raw_datasets.map(
- tokenize_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on every text in dataset",
- )
-
- # Main data processing function that will concatenate all texts from our dataset and generate chunks of
- # max_seq_length.
- def group_texts(examples):
- # Concatenate all texts.
- concatenated_examples = {k: list(chain(*examples[k])) for k in examples}
- total_length = len(concatenated_examples[list(examples.keys())[0]])
- # We drop the small remainder, and if the total_length < max_seq_length we exclude this batch and return an empty dict.
- # We could add padding if the model supported it instead of this drop, you can customize this part to your needs.
- total_length = (total_length // max_seq_length) * max_seq_length
- # Split by chunks of max_len.
- result = {
- k: [t[i : i + max_seq_length] for i in range(0, total_length, max_seq_length)]
- for k, t in concatenated_examples.items()
- }
- return result
-
- # Note that with `batched=True`, this map processes 1,000 texts together, so group_texts throws away a
- # remainder for each of those groups of 1,000 texts. You can adjust that batch_size here but a higher value
- # might be slower to preprocess.
- #
- # To speed up this part, we use multiprocessing. See the documentation of the map method for more information:
- # https://huggingface.co/docs/datasets/process#map
-
- with training_args.main_process_first(desc="grouping texts together"):
- tokenized_datasets = tokenized_datasets.map(
- group_texts,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc=f"Grouping texts in chunks of {max_seq_length}",
- )
-
- if training_args.do_train:
- if "train" not in tokenized_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = tokenized_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in tokenized_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = tokenized_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- # Data collator
- data_collator = DataCollatorForPermutationLanguageModeling(
- tokenizer=tokenizer,
- plm_probability=data_args.plm_probability,
- max_span_length=data_args.max_span_length,
- )
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_classtokenizer=tokenizer,
- data_collator=data_collator,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
- try:
- perplexity = math.exp(metrics["eval_loss"])
- except OverflowError:
- perplexity = float("inf")
- metrics["perplexity"] = perplexity
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "language-modeling"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/multiple-choice/README.md b/examples/pytorch/multiple-choice/README.md
deleted file mode 100644
index 59b2ba7b81e6..000000000000
--- a/examples/pytorch/multiple-choice/README.md
+++ /dev/null
@@ -1,108 +0,0 @@
-
-
-# Multiple Choice
-
-## Fine-tuning on SWAG with the Trainer
-
-`run_swag` allows you to fine-tune any model from our [hub](https://huggingface.co/models) (as long as its architecture as a `ForMultipleChoice` version in the library) on the SWAG dataset or your own csv/jsonlines files as long as they are structured the same way. To make it works on another dataset, you will need to tweak the `preprocess_function` inside the script.
-
-```bash
-python run_swag.py \
---model_name_or_path FacebookAI/roberta-base \
---do_train \
---do_eval \
---learning_rate 5e-5 \
---num_train_epochs 3 \
---output_dir /tmp/swag_base \
---per_device_eval_batch_size=16 \
---per_device_train_batch_size=16 \
---overwrite_output
-```
-Training with the defined hyper-parameters yields the following results:
-```
-***** Eval results *****
-eval_acc = 0.8338998300509847
-eval_loss = 0.44457291918821606
-```
-
-## With Accelerate
-
-Based on the script [run_swag_no_trainer.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/multiple-choice/run_swag_no_trainer.py).
-
-Like `run_swag.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) (as long as its architecture as a `ForMultipleChoice` version in the library) on
-the SWAG dataset or your own data in a csv or a JSON file. The main difference is that this
-script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (but you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
-the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-export DATASET_NAME=allenai/swag
-
-python run_swag_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --dataset_name $DATASET_NAME \
- --max_seq_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$DATASET_NAME/
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-export DATASET_NAME=allenai/swag
-
-accelerate launch run_swag_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --dataset_name $DATASET_NAME \
- --max_seq_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$DATASET_NAME/
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/examples/pytorch/multiple-choice/requirements.txt b/examples/pytorch/multiple-choice/requirements.txt
deleted file mode 100644
index 3bbfaef38eab..000000000000
--- a/examples/pytorch/multiple-choice/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-accelerate >= 0.12.0
-sentencepiece != 0.1.92
-protobuf
-torch >= 1.3
-evaluate
diff --git a/examples/pytorch/multiple-choice/run_no_trainer.sh b/examples/pytorch/multiple-choice/run_no_trainer.sh
deleted file mode 100755
index ed07f25e8265..000000000000
--- a/examples/pytorch/multiple-choice/run_no_trainer.sh
+++ /dev/null
@@ -1,19 +0,0 @@
-# Copyright 2020 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-accelerate launch run_swag_no_trainer.py \
- --model_name_or_path bert-base-uncased \
- --dataset_name allenai/swag \
- --output_dir /tmp/test-swag-no-trainer \
- --pad_to_max_length
diff --git a/examples/pytorch/multiple-choice/run_swag.py b/examples/pytorch/multiple-choice/run_swag.py
deleted file mode 100755
index 3c2f9ebf5a25..000000000000
--- a/examples/pytorch/multiple-choice/run_swag.py
+++ /dev/null
@@ -1,434 +0,0 @@
-#!/usr/bin/env python
-# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for multiple choice.
-"""
-# You can also adapt this script on your own multiple choice task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-from itertools import chain
-
-import datasets
-import numpy as np
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForMultipleChoice,
- AutoTokenizer,
- DataCollatorForMultipleChoice,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
- "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
- "execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_seq_length: int | None = field(
- default=None,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. If passed, sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to the maximum sentence length. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
- "efficient on GPU but very bad for TPU."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
-
- def __post_init__(self):
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
-
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
-
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.train_file is not None or data_args.validation_file is not None:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- else:
- # Downloading and loading the swag dataset from the hub.
- raw_datasets = load_dataset(
- "allenai/swag",
- "regular",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
-
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForMultipleChoice.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # When using your own dataset or a different dataset from swag, you will probably need to change this.
- ending_names = [f"ending{i}" for i in range(4)]
- context_name = "sent1"
- question_header_name = "sent2"
-
- if data_args.max_seq_length is None:
- max_seq_length = tokenizer.model_max_length
- if max_seq_length > 1024:
- logger.warning(
- "The chosen tokenizer supports a `model_max_length` that is longer than the default `block_size` value"
- " of 1024. If you would like to use a longer `block_size` up to `tokenizer.model_max_length` you can"
- " override this default with `--block_size xxx`."
- )
- max_seq_length = 1024
- else:
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- # Preprocessing the datasets.
- def preprocess_function(examples):
- first_sentences = [[context] * 4 for context in examples[context_name]]
- question_headers = examples[question_header_name]
- second_sentences = [
- [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
- ]
-
- # Flatten out
- first_sentences = list(chain(*first_sentences))
- second_sentences = list(chain(*second_sentences))
-
- # Tokenize
- tokenized_examples = tokenizer(
- first_sentences,
- second_sentences,
- truncation=True,
- max_length=max_seq_length,
- padding="max_length" if data_args.pad_to_max_length else False,
- )
- # Un-flatten
- return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- )
-
- if training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- )
-
- # Data collator
- data_collator = (
- default_data_collator
- if data_args.pad_to_max_length
- else DataCollatorForMultipleChoice(
- tokenizer=tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None, return_tensors="pt"
- )
- )
-
- # Metric
- def compute_metrics(eval_predictions):
- predictions, label_ids = eval_predictions
- preds = np.argmax(predictions, axis=1)
- return {"accuracy": (preds == label_ids).astype(np.float32).mean().item()}
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "multiple-choice",
- "dataset_tags": "swag",
- "dataset_args": "regular",
- "dataset": "SWAG",
- "language": "en",
- }
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/multiple-choice/run_swag_no_trainer.py b/examples/pytorch/multiple-choice/run_swag_no_trainer.py
deleted file mode 100755
index 070c39b61642..000000000000
--- a/examples/pytorch/multiple-choice/run_swag_no_trainer.py
+++ /dev/null
@@ -1,661 +0,0 @@
-#!/usr/bin/env python
-# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning a 🤗 Transformers model on multiple choice relying on the accelerate library without using a Trainer.
-"""
-# You can also adapt this script on your own multiple choice task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from itertools import chain
-from pathlib import Path
-
-import datasets
-import evaluate
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForMultipleChoice,
- AutoTokenizer,
- DataCollatorForMultipleChoice,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-# You should update this to your particular problem to have better documentation of `model_type`
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a multiple choice task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--max_seq_length",
- type=int,
- default=128,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the HuggingFace Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument(
- "--debug",
- action="store_true",
- help="Activate debug mode and run training only with a subset of data.",
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files)
- # Trim a number of training examples
- if args.debug:
- for split in raw_datasets:
- raw_datasets[split] = raw_datasets[split].select(range(100))
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- if raw_datasets["train"] is not None:
- column_names = raw_datasets["train"].column_names
- else:
- column_names = raw_datasets["validation"].column_names
-
- # When using your own dataset or a different dataset from swag, you will probably need to change this.
- ending_names = [f"ending{i}" for i in range(4)]
- context_name = "sent1"
- question_header_name = "sent2"
- label_column_name = "label" if "label" in column_names else "labels"
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForMultipleChoice.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForMultipleChoice.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- padding = "max_length" if args.pad_to_max_length else False
-
- def preprocess_function(examples):
- first_sentences = [[context] * 4 for context in examples[context_name]]
- question_headers = examples[question_header_name]
- second_sentences = [
- [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
- ]
- labels = examples[label_column_name]
-
- # Flatten out
- first_sentences = list(chain(*first_sentences))
- second_sentences = list(chain(*second_sentences))
-
- # Tokenize
- tokenized_examples = tokenizer(
- first_sentences,
- second_sentences,
- max_length=args.max_seq_length,
- padding=padding,
- truncation=True,
- )
- # Un-flatten
- tokenized_inputs = {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
- tokenized_inputs["labels"] = labels
- return tokenized_inputs
-
- with accelerator.main_process_first():
- processed_datasets = raw_datasets.map(
- preprocess_function, batched=True, remove_columns=raw_datasets["train"].column_names
- )
-
- train_dataset = processed_datasets["train"]
- eval_dataset = processed_datasets["validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorForMultipleChoice(
- tokenizer, pad_to_multiple_of=pad_to_multiple_of, return_tensors="pt"
- )
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Use the device given by the `accelerator` object.
- device = accelerator.device
- model.to(device)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("swag_no_trainer", experiment_config)
-
- # Metrics
- metric = evaluate.load("accuracy")
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- predictions = outputs.logits.argmax(dim=-1)
- predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
- metric.add_batch(
- predictions=predictions,
- references=references,
- )
-
- eval_metric = metric.compute()
- accelerator.print(f"epoch {epoch}: {eval_metric}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "accuracy": eval_metric,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(all_results, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/object-detection/README.md b/examples/pytorch/object-detection/README.md
deleted file mode 100644
index cdbc6c5f8a9f..000000000000
--- a/examples/pytorch/object-detection/README.md
+++ /dev/null
@@ -1,233 +0,0 @@
-
-
-# Object detection examples
-
-This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForObjectDetection` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForObjectDetection) (such as [DETR](https://huggingface.co/docs/transformers/main/en/model_doc/detr), [DETA](https://huggingface.co/docs/transformers/main/en/model_doc/deta), [Deformable DETR](https://huggingface.co/docs/transformers/main/en/model_doc/deformable_detr)) using PyTorch.
-
-Content:
-* [PyTorch version, Trainer](#pytorch-version-trainer)
-* [PyTorch version, no Trainer](#pytorch-version-no-trainer)
-* [Reload and perform inference](#reload-and-perform-inference)
-* [Note on custom data](#note-on-custom-data)
-
-
-## PyTorch version, Trainer
-
-Based on the script [`run_object_detection.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/object-detection/run_object_detection.py).
-
-The script leverages the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to automatically take care of the training for you, running on distributed environments right away.
-
-Here we show how to fine-tune a [DETR](https://huggingface.co/facebook/detr-resnet-50) model on the [CPPE-5](https://huggingface.co/datasets/rishitdagli/cppe-5) dataset:
-
-```bash
-python run_object_detection.py \
- --model_name_or_path facebook/detr-resnet-50 \
- --dataset_name rishitdagli/cppe-5 \
- --do_train true \
- --do_eval true \
- --output_dir detr-finetuned-cppe-5-10k-steps \
- --num_train_epochs 100 \
- --image_square_size 600 \
- --fp16 true \
- --learning_rate 5e-5 \
- --weight_decay 1e-4 \
- --dataloader_num_workers 4 \
- --dataloader_prefetch_factor 2 \
- --per_device_train_batch_size 8 \
- --gradient_accumulation_steps 1 \
- --remove_unused_columns false \
- --eval_do_concat_batches false \
- --ignore_mismatched_sizes true \
- --metric_for_best_model eval_map \
- --greater_is_better true \
- --load_best_model_at_end true \
- --logging_strategy epoch \
- --eval_strategy epoch \
- --save_strategy epoch \
- --save_total_limit 2 \
- --push_to_hub true \
- --push_to_hub_model_id detr-finetuned-cppe-5-10k-steps \
- --hub_strategy end \
- --seed 1337
-```
-
-> Note:
-`--eval_do_concat_batches false` is required for correct evaluation of detection models;
-`--ignore_mismatched_sizes true` is required to load detection model for finetuning with different number of classes.
-
-The resulting model can be seen here: https://huggingface.co/qubvel-hf/qubvel-hf/detr-resnet-50-finetuned-10k-cppe5. The corresponding Weights and Biases report [here](https://api.wandb.ai/links/qubvel-hf-co/bnm0r5ex). Note that it's always advised to check the original paper to know the details regarding training hyperparameters. Hyperparameters for current example were not tuned. To improve model quality you could try:
- - changing image size parameters (`--shortest_edge`/`--longest_edge`)
- - changing training parameters, such as learning rate, batch size, warmup, optimizer and many more (see [TrainingArguments](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments))
- - adding more image augmentations (we created a helpful [HF Space](https://huggingface.co/spaces/qubvel-hf/albumentations-demo) to choose some)
-
-Note that you can replace the model and dataset by simply setting the `model_name_or_path` and `dataset_name` arguments respectively, with model or dataset from the [hub](https://huggingface.co/).
-For dataset, make sure it provides labels in the same format as [CPPE-5](https://huggingface.co/datasets/rishitdagli/cppe-5) dataset and boxes are provided in [COCO format](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco).
-
-
-
-
-## PyTorch version, no Trainer
-
-Based on the script [`run_object_detection_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/object-detection/run_object_detection.py).
-
-The script leverages [🤗 `Accelerate`](https://github.com/huggingface/accelerate), which allows to write your own training loop in PyTorch, but have it run instantly on any (distributed) environment, including CPU, multi-CPU, GPU, multi-GPU and TPU. It also supports mixed precision.
-
-First, run:
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked regarding the environment on which you'd like to train. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_object_detection_no_trainer.py \
- --model_name_or_path "facebook/detr-resnet-50" \
- --dataset_name rishitdagli/cppe-5 \
- --output_dir "detr-resnet-50-finetuned" \
- --num_train_epochs 100 \
- --image_square_size 600 \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --checkpointing_steps epoch \
- --learning_rate 5e-5 \
- --ignore_mismatched_sizes \
- --with_tracking \
- --push_to_hub
-```
-
-and boom, you're training, possibly on multiple GPUs, logging everything to all trackers found in your environment (like Weights and Biases, Tensorboard) and regularly pushing your model to the hub (with the repo name being equal to `args.output_dir` at your HF username) 🤗
-
-With the default settings, the script fine-tunes a [DETR](https://huggingface.co/facebook/detr-resnet-50) model on the [CPPE-5](https://huggingface.co/datasets/rishitdagli/cppe-5) dataset. The resulting model can be seen here: https://huggingface.co/qubvel-hf/detr-resnet-50-finetuned-10k-cppe5-no-trainer.
-
-
-## Reload and perform inference
-
-This means that after training, you can easily load your trained model and perform inference as follows::
-
-```python
-import requests
-import torch
-
-from PIL import Image
-from transformers import AutoImageProcessor, AutoModelForObjectDetection
-
-# Name of repo on the hub or path to a local folder
-model_name = "qubvel-hf/detr-resnet-50-finetuned-10k-cppe5"
-
-image_processor = AutoImageProcessor.from_pretrained(model_name)
-model = AutoModelForObjectDetection.from_pretrained(model_name)
-
-# Load image for inference
-url = "https://images.pexels.com/photos/8413299/pexels-photo-8413299.jpeg?auto=compress&cs=tinysrgb&w=630&h=375&dpr=2"
-image = Image.open(requests.get(url, stream=True).raw)
-
-# Prepare image for the model
-inputs = image_processor(images=image, return_tensors="pt")
-
-with torch.no_grad():
- outputs = model(**inputs)
-
-# Post process model predictions
-# this include conversion to Pascal VOC format and filtering non confident boxes
-width, height = image.size
-target_sizes = torch.tensor([height, width]).unsqueeze(0) # add batch dim
-results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
-
-for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
- box = [round(i, 2) for i in box.tolist()]
- print(
- f"Detected {model.config.id2label[label.item()]} with confidence "
- f"{round(score.item(), 3)} at location {box}"
- )
-```
-
-And visualize with the following code:
-```python
-from PIL import ImageDraw
-draw = ImageDraw.Draw(image)
-
-for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
- box = [round(i, 2) for i in box.tolist()]
- x, y, x2, y2 = tuple(box)
- draw.rectangle((x, y, x2, y2), outline="red", width=1)
- draw.text((x, y), model.config.id2label[label.item()], fill="white")
-
-image
-```
-
-
-## Note on custom data
-
-In case you'd like to use the script with custom data, you could prepare your data with the following way:
-
-```bash
-custom_dataset/
-└── train
- ├── 0001.jpg
- ├── 0002.jpg
- ├── ...
- └── metadata.jsonl
-└── validation
- └── ...
-└── test
- └── ...
-```
-
-Where `metadata.jsonl` is a file with the following structure:
-```json
-{"file_name": "0001.jpg", "objects": {"bbox": [[302.0, 109.0, 73.0, 52.0]], "categories": [0], "id": [1], "area": [50.0]}}
-{"file_name": "0002.jpg", "objects": {"bbox": [[810.0, 100.0, 57.0, 28.0]], "categories": [1], "id": [2], "area": [40.0]}}
-...
-```
-Trining script support bounding boxes in COCO format (x_min, y_min, width, height).
-
-Then, you cat load the dataset with just a few lines of code:
-
-```python
-from datasets import load_dataset
-
-# Load dataset
-dataset = load_dataset("imagefolder", data_dir="custom_dataset/")
-
-# >>> DatasetDict({
-# ... train: Dataset({
-# ... features: ['image', 'objects'],
-# ... num_rows: 2
-# ... })
-# ... })
-
-# Push to hub (assumes you have ran the hf auth login command in a terminal/notebook)
-dataset.push_to_hub("name of repo on the hub")
-
-# optionally, you can push to a private repo on the hub
-# dataset.push_to_hub("name of repo on the hub", private=True)
-```
-
-And the final step, for training you should provide id2label mapping in the following way:
-```python
-id2label = {0: "Car", 1: "Bird", ...}
-```
-Just find it in code and replace for simplicity, or save `json` locally and with the dataset on the hub!
-
-See also: [Dataset Creation Guide](https://huggingface.co/docs/datasets/image_dataset#create-an-image-dataset)
diff --git a/examples/pytorch/object-detection/requirements.txt b/examples/pytorch/object-detection/requirements.txt
deleted file mode 100644
index 8a9ba6ddcd16..000000000000
--- a/examples/pytorch/object-detection/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-albumentations >= 1.4.16
-timm
-datasets>=4.0
-torchmetrics
-pycocotools
diff --git a/examples/pytorch/object-detection/run_object_detection.py b/examples/pytorch/object-detection/run_object_detection.py
deleted file mode 100644
index 602245da1756..000000000000
--- a/examples/pytorch/object-detection/run_object_detection.py
+++ /dev/null
@@ -1,522 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "timm",
-# "datasets>=4.0",
-# "torchmetrics",
-# "pycocotools",
-# ]
-# ///
-
-"""Finetuning any 🤗 Transformers model supported by AutoModelForObjectDetection for object detection leveraging the Trainer API."""
-
-import logging
-import os
-import sys
-from collections.abc import Mapping
-from dataclasses import dataclass, field
-from functools import partial
-from typing import Any
-
-import albumentations as A
-import numpy as np
-import torch
-from datasets import load_dataset
-from torchmetrics.detection.mean_ap import MeanAveragePrecision
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoImageProcessor,
- AutoModelForObjectDetection,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
-)
-from transformers.image_processing_utils import BatchFeature
-from transformers.image_transforms import center_to_corners_format
-from transformers.trainer import EvalPrediction
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/object-detection/requirements.txt")
-
-
-@dataclass
-class ModelOutput:
- logits: torch.Tensor
- pred_boxes: torch.Tensor
-
-
-def format_image_annotations_as_coco(
- image_id: str, categories: list[int], areas: list[float], bboxes: list[tuple[float]]
-) -> dict:
- """Format one set of image annotations to the COCO format
-
- Args:
- image_id (str): image id. e.g. "0001"
- categories (list[int]): list of categories/class labels corresponding to provided bounding boxes
- areas (list[float]): list of corresponding areas to provided bounding boxes
- bboxes (list[tuple[float]]): list of bounding boxes provided in COCO format
- ([center_x, center_y, width, height] in absolute coordinates)
-
- Returns:
- dict: {
- "image_id": image id,
- "annotations": list of formatted annotations
- }
- """
- annotations = []
- for category, area, bbox in zip(categories, areas, bboxes):
- formatted_annotation = {
- "image_id": image_id,
- "category_id": category,
- "iscrowd": 0,
- "area": area,
- "bbox": list(bbox),
- }
- annotations.append(formatted_annotation)
-
- return {
- "image_id": image_id,
- "annotations": annotations,
- }
-
-
-def convert_bbox_yolo_to_pascal(boxes: torch.Tensor, image_size: tuple[int, int]) -> torch.Tensor:
- """
- Convert bounding boxes from YOLO format (x_center, y_center, width, height) in range [0, 1]
- to Pascal VOC format (x_min, y_min, x_max, y_max) in absolute coordinates.
-
- Args:
- boxes (torch.Tensor): Bounding boxes in YOLO format
- image_size (tuple[int, int]): Image size in format (height, width)
-
- Returns:
- torch.Tensor: Bounding boxes in Pascal VOC format (x_min, y_min, x_max, y_max)
- """
- # convert center to corners format
- boxes = center_to_corners_format(boxes)
-
- # convert to absolute coordinates
- height, width = image_size
- boxes = boxes * torch.tensor([[width, height, width, height]])
-
- return boxes
-
-
-def augment_and_transform_batch(
- examples: Mapping[str, Any],
- transform: A.Compose,
- image_processor: AutoImageProcessor,
- return_pixel_mask: bool = False,
-) -> BatchFeature:
- """Apply augmentations and format annotations in COCO format for object detection task"""
-
- images = []
- annotations = []
- for image_id, image, objects in zip(examples["image_id"], examples["image"], examples["objects"]):
- image = np.array(image.convert("RGB"))
-
- # apply augmentations
- output = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
- images.append(output["image"])
-
- # format annotations in COCO format
- formatted_annotations = format_image_annotations_as_coco(
- image_id, output["category"], objects["area"], output["bboxes"]
- )
- annotations.append(formatted_annotations)
-
- # Apply the image processor transformations: resizing, rescaling, normalization
- result = image_processor(images=images, annotations=annotations, return_tensors="pt")
-
- if not return_pixel_mask:
- result.pop("pixel_mask", None)
-
- return result
-
-
-def collate_fn(batch: list[BatchFeature]) -> Mapping[str, torch.Tensor | list[Any]]:
- data = {}
- data["pixel_values"] = torch.stack([x["pixel_values"] for x in batch])
- data["labels"] = [x["labels"] for x in batch]
- if "pixel_mask" in batch[0]:
- data["pixel_mask"] = torch.stack([x["pixel_mask"] for x in batch])
- return data
-
-
-@torch.no_grad()
-def compute_metrics(
- evaluation_results: EvalPrediction,
- image_processor: AutoImageProcessor,
- threshold: float = 0.0,
- id2label: Mapping[int, str] | None = None,
-) -> Mapping[str, float]:
- """
- Compute mean average mAP, mAR and their variants for the object detection task.
-
- Args:
- evaluation_results (EvalPrediction): Predictions and targets from evaluation.
- threshold (float, optional): Threshold to filter predicted boxes by confidence. Defaults to 0.0.
- id2label (Optional[dict], optional): Mapping from class id to class name. Defaults to None.
-
- Returns:
- Mapping[str, float]: Metrics in a form of dictionary {: }
- """
-
- predictions, targets = evaluation_results.predictions, evaluation_results.label_ids
-
- # For metric computation we need to provide:
- # - targets in a form of list of dictionaries with keys "boxes", "labels"
- # - predictions in a form of list of dictionaries with keys "boxes", "scores", "labels"
-
- image_sizes = []
- post_processed_targets = []
- post_processed_predictions = []
-
- # Collect targets in the required format for metric computation
- for batch in targets:
- # collect image sizes, we will need them for predictions post processing
- batch_image_sizes = torch.tensor([x["orig_size"] for x in batch])
- image_sizes.append(batch_image_sizes)
- # collect targets in the required format for metric computation
- # boxes were converted to YOLO format needed for model training
- # here we will convert them to Pascal VOC format (x_min, y_min, x_max, y_max)
- for image_target in batch:
- boxes = torch.tensor(image_target["boxes"])
- boxes = convert_bbox_yolo_to_pascal(boxes, image_target["orig_size"])
- labels = torch.tensor(image_target["class_labels"])
- post_processed_targets.append({"boxes": boxes, "labels": labels})
-
- # Collect predictions in the required format for metric computation,
- # model produce boxes in YOLO format, then image_processor convert them to Pascal VOC format
- for batch, target_sizes in zip(predictions, image_sizes):
- batch_logits, batch_boxes = batch[1], batch[2]
- output = ModelOutput(logits=torch.tensor(batch_logits), pred_boxes=torch.tensor(batch_boxes))
- post_processed_output = image_processor.post_process_object_detection(
- output, threshold=threshold, target_sizes=target_sizes
- )
- post_processed_predictions.extend(post_processed_output)
-
- # Compute metrics
- metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
- metric.update(post_processed_predictions, post_processed_targets)
- metrics = metric.compute()
-
- # Replace list of per class metrics with separate metric for each class
- classes = metrics.pop("classes")
- map_per_class = metrics.pop("map_per_class")
- mar_100_per_class = metrics.pop("mar_100_per_class")
- for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
- class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
- metrics[f"map_{class_name}"] = class_map
- metrics[f"mar_100_{class_name}"] = class_mar
-
- metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
-
- return metrics
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
- them on the command line.
- """
-
- dataset_name: str = field(
- default="rishitdagli/cppe-5",
- metadata={
- "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
- },
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_val_split: float | None = field(
- default=0.15, metadata={"help": "Percent to split off of train for validation."}
- )
- image_square_size: int | None = field(
- default=600,
- metadata={"help": "Image longest size will be resized to this value, then image will be padded to square."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- use_fast: bool | None = field(
- default=True,
- metadata={"help": "Use a fast torchvision-base image processor if it is supported for a given model."},
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- default="facebook/detr-resnet-50",
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={
- "help": "Whether or not to raise an error if some of the weights from the checkpoint do not have the same size as the weights of the model (if for instance, you are instantiating a model with 10 labels from a checkpoint with 3 labels)."
- },
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # ------------------------------------------------------------------------------------------------
- # Load dataset, prepare splits
- # ------------------------------------------------------------------------------------------------
-
- dataset = load_dataset(
- data_args.dataset_name, cache_dir=model_args.cache_dir, trust_remote_code=model_args.trust_remote_code
- )
-
- # If we don't have a validation split, split off a percentage of train as validation
- data_args.train_val_split = None if "validation" in dataset else data_args.train_val_split
- if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(data_args.train_val_split, seed=training_args.seed)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Get dataset categories and prepare mappings for label_name <-> label_id
- if isinstance(dataset["train"].features["objects"], dict):
- categories = dataset["train"].features["objects"]["category"].feature.names
- else: # (for old versions of `datasets` that used Sequence({...}) of the objects)
- categories = dataset["train"].features["objects"].feature["category"].names
- id2label = dict(enumerate(categories))
- label2id = {v: k for k, v in id2label.items()}
-
- # ------------------------------------------------------------------------------------------------
- # Load pretrained config, model and image processor
- # ------------------------------------------------------------------------------------------------
-
- common_pretrained_args = {
- "cache_dir": model_args.cache_dir,
- "revision": model_args.model_revision,
- "token": model_args.token,
- "trust_remote_code": model_args.trust_remote_code,
- }
- config = AutoConfig.from_pretrained(
- model_args.config_name or model_args.model_name_or_path,
- label2id=label2id,
- id2label=id2label,
- **common_pretrained_args,
- )
- model = AutoModelForObjectDetection.from_pretrained(
- model_args.model_name_or_path,
- config=config,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- **common_pretrained_args,
- )
- image_processor = AutoImageProcessor.from_pretrained(
- model_args.image_processor_name or model_args.model_name_or_path,
- do_resize=True,
- size={"max_height": data_args.image_square_size, "max_width": data_args.image_square_size},
- do_pad=True,
- pad_size={"height": data_args.image_square_size, "width": data_args.image_square_size},
- use_fast=data_args.use_fast,
- **common_pretrained_args,
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define image augmentations and dataset transforms
- # ------------------------------------------------------------------------------------------------
- max_size = data_args.image_square_size
- train_augment_and_transform = A.Compose(
- [
- A.Compose(
- [
- A.SmallestMaxSize(max_size=max_size, p=1.0),
- A.RandomSizedBBoxSafeCrop(height=max_size, width=max_size, p=1.0),
- ],
- p=0.2,
- ),
- A.OneOf(
- [
- A.Blur(blur_limit=7, p=0.5),
- A.MotionBlur(blur_limit=7, p=0.5),
- A.Defocus(radius=(1, 5), alias_blur=(0.1, 0.25), p=0.1),
- ],
- p=0.1,
- ),
- A.Perspective(p=0.1),
- A.HorizontalFlip(p=0.5),
- A.RandomBrightnessContrast(p=0.5),
- A.HueSaturationValue(p=0.1),
- ],
- bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True, min_area=25),
- )
- validation_transform = A.Compose(
- [A.NoOp()],
- bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True),
- )
-
- # Make transform functions for batch and apply for dataset splits
- train_transform_batch = partial(
- augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
- )
- validation_transform_batch = partial(
- augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
- )
-
- dataset["train"] = dataset["train"].with_transform(train_transform_batch)
- dataset["validation"] = dataset["validation"].with_transform(validation_transform_batch)
- dataset["test"] = dataset["test"].with_transform(validation_transform_batch)
-
- # ------------------------------------------------------------------------------------------------
- # Model training and evaluation with Trainer API
- # ------------------------------------------------------------------------------------------------
-
- eval_compute_metrics_fn = partial(
- compute_metrics, image_processor=image_processor, id2label=id2label, threshold=0.0
- )
-
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=dataset["train"] if training_args.do_train else None,
- eval_dataset=dataset["validation"] if training_args.do_eval else None,
- processing_class=image_processor,
- data_collator=collate_fn,
- compute_metrics=eval_compute_metrics_fn,
- )
-
- # Training
- if training_args.do_train:
- train_result = trainer.train(resume_from_checkpoint=training_args.resume_from_checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Final evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate(eval_dataset=dataset["test"], metric_key_prefix="test")
- trainer.log_metrics("test", metrics)
- trainer.save_metrics("test", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "dataset": data_args.dataset_name,
- "tags": ["object-detection", "vision"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/object-detection/run_object_detection_no_trainer.py b/examples/pytorch/object-detection/run_object_detection_no_trainer.py
deleted file mode 100644
index a5ecc56add20..000000000000
--- a/examples/pytorch/object-detection/run_object_detection_no_trainer.py
+++ /dev/null
@@ -1,795 +0,0 @@
-# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "albumentations >= 1.4.16",
-# "timm",
-# "datasets>=4.0",
-# "torchmetrics",
-# "pycocotools",
-# ]
-# ///
-
-"""Finetuning 🤗 Transformers model for object detection with Accelerate."""
-
-import argparse
-import json
-import logging
-import math
-import os
-from collections.abc import Mapping
-from functools import partial
-from pathlib import Path
-from typing import Any
-
-import albumentations as A
-import datasets
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch.utils.data import DataLoader
-from torchmetrics.detection.mean_ap import MeanAveragePrecision
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoImageProcessor,
- AutoModelForObjectDetection,
- SchedulerType,
- get_scheduler,
-)
-from transformers.image_processing_utils import BatchFeature
-from transformers.image_transforms import center_to_corners_format
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logging.basicConfig(level=logging.INFO)
-logger = get_logger(__name__)
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
-
-
-# Copied from examples/pytorch/object-detection/run_object_detection.format_image_annotations_as_coco
-def format_image_annotations_as_coco(
- image_id: str, categories: list[int], areas: list[float], bboxes: list[tuple[float]]
-) -> dict:
- """Format one set of image annotations to the COCO format
-
- Args:
- image_id (str): image id. e.g. "0001"
- categories (list[int]): list of categories/class labels corresponding to provided bounding boxes
- areas (list[float]): list of corresponding areas to provided bounding boxes
- bboxes (list[tuple[float]]): list of bounding boxes provided in COCO format
- ([center_x, center_y, width, height] in absolute coordinates)
-
- Returns:
- dict: {
- "image_id": image id,
- "annotations": list of formatted annotations
- }
- """
- annotations = []
- for category, area, bbox in zip(categories, areas, bboxes):
- formatted_annotation = {
- "image_id": image_id,
- "category_id": category,
- "iscrowd": 0,
- "area": area,
- "bbox": list(bbox),
- }
- annotations.append(formatted_annotation)
-
- return {
- "image_id": image_id,
- "annotations": annotations,
- }
-
-
-# Copied from examples/pytorch/object-detection/run_object_detection.convert_bbox_yolo_to_pascal
-def convert_bbox_yolo_to_pascal(boxes: torch.Tensor, image_size: tuple[int, int]) -> torch.Tensor:
- """
- Convert bounding boxes from YOLO format (x_center, y_center, width, height) in range [0, 1]
- to Pascal VOC format (x_min, y_min, x_max, y_max) in absolute coordinates.
-
- Args:
- boxes (torch.Tensor): Bounding boxes in YOLO format
- image_size (tuple[int, int]): Image size in format (height, width)
-
- Returns:
- torch.Tensor: Bounding boxes in Pascal VOC format (x_min, y_min, x_max, y_max)
- """
- # convert center to corners format
- boxes = center_to_corners_format(boxes)
-
- # convert to absolute coordinates
- height, width = image_size
- boxes = boxes * torch.tensor([[width, height, width, height]])
-
- return boxes
-
-
-# Copied from examples/pytorch/object-detection/run_object_detection.augment_and_transform_batch
-def augment_and_transform_batch(
- examples: Mapping[str, Any],
- transform: A.Compose,
- image_processor: AutoImageProcessor,
- return_pixel_mask: bool = False,
-) -> BatchFeature:
- """Apply augmentations and format annotations in COCO format for object detection task"""
-
- images = []
- annotations = []
- for image_id, image, objects in zip(examples["image_id"], examples["image"], examples["objects"]):
- image = np.array(image.convert("RGB"))
-
- # apply augmentations
- output = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
- images.append(output["image"])
-
- # format annotations in COCO format
- formatted_annotations = format_image_annotations_as_coco(
- image_id, output["category"], objects["area"], output["bboxes"]
- )
- annotations.append(formatted_annotations)
-
- # Apply the image processor transformations: resizing, rescaling, normalization
- result = image_processor(images=images, annotations=annotations, return_tensors="pt")
-
- if not return_pixel_mask:
- result.pop("pixel_mask", None)
-
- return result
-
-
-# Copied from examples/pytorch/object-detection/run_object_detection.collate_fn
-def collate_fn(batch: list[BatchFeature]) -> Mapping[str, torch.Tensor | list[Any]]:
- data = {}
- data["pixel_values"] = torch.stack([x["pixel_values"] for x in batch])
- data["labels"] = [x["labels"] for x in batch]
- if "pixel_mask" in batch[0]:
- data["pixel_mask"] = torch.stack([x["pixel_mask"] for x in batch])
- return data
-
-
-def nested_to_cpu(objects):
- """Move nested tesnors in objects to CPU if they are on GPU"""
- if isinstance(objects, torch.Tensor):
- return objects.cpu()
- elif isinstance(objects, Mapping):
- return type(objects)({k: nested_to_cpu(v) for k, v in objects.items()})
- elif isinstance(objects, (list, tuple)):
- return type(objects)([nested_to_cpu(v) for v in objects])
- elif isinstance(objects, (np.ndarray, str, int, float, bool)):
- return objects
- raise ValueError(f"Unsupported type {type(objects)}")
-
-
-def evaluation_loop(
- model: torch.nn.Module,
- image_processor: AutoImageProcessor,
- accelerator: Accelerator,
- dataloader: DataLoader,
- id2label: Mapping[int, str],
-) -> dict:
- model.eval()
- metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
-
- for step, batch in enumerate(tqdm(dataloader, disable=not accelerator.is_local_main_process)):
- with torch.no_grad():
- outputs = model(**batch)
-
- # For metric computation we need to collect ground truth and predicted boxes in the same format
-
- # 1. Collect predicted boxes, classes, scores
- # image_processor convert boxes from YOLO format to Pascal VOC format
- # ([x_min, y_min, x_max, y_max] in absolute coordinates)
- image_size = torch.stack([example["orig_size"] for example in batch["labels"]], dim=0)
- predictions = image_processor.post_process_object_detection(outputs, threshold=0.0, target_sizes=image_size)
- predictions = nested_to_cpu(predictions)
-
- # 2. Collect ground truth boxes in the same format for metric computation
- # Do the same, convert YOLO boxes to Pascal VOC format
- target = []
- for label in batch["labels"]:
- label = nested_to_cpu(label)
- boxes = convert_bbox_yolo_to_pascal(label["boxes"], label["orig_size"])
- labels = label["class_labels"]
- target.append({"boxes": boxes, "labels": labels})
-
- metric.update(predictions, target)
-
- metrics = metric.compute()
-
- # Replace list of per class metrics with separate metric for each class
- classes = metrics.pop("classes")
- map_per_class = metrics.pop("map_per_class")
- mar_100_per_class = metrics.pop("mar_100_per_class")
- for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
- class_name = id2label[class_id.item()]
- metrics[f"map_{class_name}"] = class_map
- metrics[f"mar_100_{class_name}"] = class_mar
-
- # Convert metrics to float
- metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
-
- return metrics
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model for object detection task")
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to a pretrained model or model identifier from huggingface.co/models.",
- default="facebook/detr-resnet-50",
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- help="Name of the dataset on the hub.",
- default="rishitdagli/cppe-5",
- )
- parser.add_argument(
- "--train_val_split",
- type=float,
- default=0.15,
- help="Fraction of the dataset to be used for validation.",
- )
- parser.add_argument(
- "--ignore_mismatched_sizes",
- action="store_true",
- help="Ignore mismatched sizes between the model and the dataset.",
- )
- parser.add_argument(
- "--image_square_size",
- type=int,
- default=1333,
- help="Image longest size will be resized to this value, then image will be padded to square.",
- )
- parser.add_argument(
- "--use_fast",
- type=bool,
- default=True,
- help="Use a fast torchvision-base image processor if it is supported for a given model.",
- )
- parser.add_argument(
- "--cache_dir",
- type=str,
- help="Path to a folder in which the model and dataset will be cached.",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--dataloader_num_workers",
- type=int,
- default=4,
- help="Number of workers to use for the dataloaders.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument(
- "--adam_beta1",
- type=float,
- default=0.9,
- help="Beta1 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_beta2",
- type=float,
- default=0.999,
- help="Beta2 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_epsilon",
- type=float,
- default=1e-8,
- help="Epsilon for AdamW optimizer",
- )
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- required=False,
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.push_to_hub or args.with_tracking:
- if args.output_dir is None:
- raise ValueError(
- "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
- )
-
- if args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- # We set device_specific to True as we want different data augmentation per device.
- if args.seed is not None:
- set_seed(args.seed, device_specific=True)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Load dataset
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
-
- # If we don't have a validation split, split off a percentage of train as validation.
- args.train_val_split = None if "validation" in dataset else args.train_val_split
- if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(args.train_val_split, seed=args.seed)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Get dataset categories and prepare mappings for label_name <-> label_id
- if isinstance(dataset["train"].features["objects"], dict):
- categories = dataset["train"].features["objects"]["category"].feature.names
- else: # (for old versions of `datasets` that used Sequence({...}) of the objects)
- categories = dataset["train"].features["objects"].feature["category"].names
- id2label = dict(enumerate(categories))
- label2id = {v: k for k, v in id2label.items()}
-
- # ------------------------------------------------------------------------------------------------
- # Load pretrained config, model and image processor
- # ------------------------------------------------------------------------------------------------
-
- common_pretrained_args = {
- "cache_dir": args.cache_dir,
- "token": args.hub_token,
- "trust_remote_code": args.trust_remote_code,
- }
- config = AutoConfig.from_pretrained(
- args.model_name_or_path, label2id=label2id, id2label=id2label, **common_pretrained_args
- )
- model = AutoModelForObjectDetection.from_pretrained(
- args.model_name_or_path,
- config=config,
- ignore_mismatched_sizes=args.ignore_mismatched_sizes,
- **common_pretrained_args,
- )
- image_processor = AutoImageProcessor.from_pretrained(
- args.model_name_or_path,
- do_resize=True,
- size={"max_height": args.image_square_size, "max_width": args.image_square_size},
- do_pad=True,
- pad_size={"height": args.image_square_size, "width": args.image_square_size},
- use_fast=args.use_fast,
- **common_pretrained_args,
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define image augmentations and dataset transforms
- # ------------------------------------------------------------------------------------------------
- max_size = args.image_square_size
- train_augment_and_transform = A.Compose(
- [
- A.Compose(
- [
- A.SmallestMaxSize(max_size=max_size, p=1.0),
- A.RandomSizedBBoxSafeCrop(height=max_size, width=max_size, p=1.0),
- ],
- p=0.2,
- ),
- A.OneOf(
- [
- A.Blur(blur_limit=7, p=0.5),
- A.MotionBlur(blur_limit=7, p=0.5),
- A.Defocus(radius=(1, 5), alias_blur=(0.1, 0.25), p=0.1),
- ],
- p=0.1,
- ),
- A.Perspective(p=0.1),
- A.HorizontalFlip(p=0.5),
- A.RandomBrightnessContrast(p=0.5),
- A.HueSaturationValue(p=0.1),
- ],
- bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True, min_area=25),
- )
- validation_transform = A.Compose(
- [A.NoOp()],
- bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True),
- )
-
- # Make transform functions for batch and apply for dataset splits
- train_transform_batch = partial(
- augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
- )
- validation_transform_batch = partial(
- augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
- )
-
- with accelerator.main_process_first():
- train_dataset = dataset["train"].with_transform(train_transform_batch)
- valid_dataset = dataset["validation"].with_transform(validation_transform_batch)
- test_dataset = dataset["test"].with_transform(validation_transform_batch)
-
- dataloader_common_args = {
- "num_workers": args.dataloader_num_workers,
- "collate_fn": collate_fn,
- }
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, batch_size=args.per_device_train_batch_size, **dataloader_common_args
- )
- valid_dataloader = DataLoader(
- valid_dataset, shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
- )
- test_dataloader = DataLoader(
- test_dataset, shuffle=False, batch_size=args.per_device_eval_batch_size, **dataloader_common_args
- )
-
- # ------------------------------------------------------------------------------------------------
- # Define optimizer, scheduler and prepare everything with the accelerator
- # ------------------------------------------------------------------------------------------------
-
- # Optimizer
- optimizer = torch.optim.AdamW(
- list(model.parameters()),
- lr=args.learning_rate,
- betas=[args.adam_beta1, args.adam_beta2],
- eps=args.adam_epsilon,
- )
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, valid_dataloader, test_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, valid_dataloader, test_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("object_detection_no_trainer", experiment_config)
-
- # ------------------------------------------------------------------------------------------------
- # Run training with evaluation on each epoch
- # ------------------------------------------------------------------------------------------------
-
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
-
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
-
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir,
- is_main_process=accelerator.is_main_process,
- save_function=accelerator.save,
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if completed_steps >= args.max_train_steps:
- break
-
- logger.info("***** Running evaluation *****")
- metrics = evaluation_loop(model, image_processor, accelerator, valid_dataloader, id2label)
-
- logger.info(f"epoch {epoch}: {metrics}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "train_loss": total_loss.item() / len(train_dataloader),
- **metrics,
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- # ------------------------------------------------------------------------------------------------
- # Run evaluation on test dataset and save the model
- # ------------------------------------------------------------------------------------------------
-
- logger.info("***** Running evaluation on test dataset *****")
- metrics = evaluation_loop(model, image_processor, accelerator, test_dataloader, id2label)
- metrics = {f"test_{k}": v for k, v in metrics.items()}
-
- logger.info(f"Test metrics: {metrics}")
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(metrics, f, indent=2)
-
- image_processor.save_pretrained(args.output_dir)
-
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- ignore_patterns=["epoch_*"],
- )
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/old_test_xla_examples.py b/examples/pytorch/old_test_xla_examples.py
deleted file mode 100644
index 320182d19499..000000000000
--- a/examples/pytorch/old_test_xla_examples.py
+++ /dev/null
@@ -1,92 +0,0 @@
-# Copyright 2018 HuggingFace Inc..
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-
-import json
-import logging
-import os
-import sys
-from time import time
-from unittest.mock import patch
-
-from transformers.testing_utils import TestCasePlus, require_torch_xla
-
-
-logging.basicConfig(level=logging.DEBUG)
-
-logger = logging.getLogger()
-
-
-def get_results(output_dir):
- results = {}
- path = os.path.join(output_dir, "all_results.json")
- if os.path.exists(path):
- with open(path, encoding="utf-8") as f:
- results = json.load(f)
- else:
- raise ValueError(f"can't find {path}")
- return results
-
-
-stream_handler = logging.StreamHandler(sys.stdout)
-logger.addHandler(stream_handler)
-
-
-@require_torch_xla
-class TorchXLAExamplesTests(TestCasePlus):
- def test_run_glue(self):
- import xla_spawn
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- ./examples/pytorch/text-classification/run_glue.py
- --num_cores=8
- ./examples/pytorch/text-classification/run_glue.py
- --model_name_or_path distilbert/distilbert-base-uncased
- --output_dir {tmp_dir}
- --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
- --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
- --do_train
- --do_eval
- --debug tpu_metrics_debug
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --learning_rate=1e-4
- --max_steps=10
- --warmup_steps=2
- --seed=42
- --max_seq_length=128
- """.split()
-
- with patch.object(sys, "argv", testargs):
- start = time()
- xla_spawn.main()
- end = time()
-
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.75)
-
- # Assert that the script takes less than 500 seconds to make sure it doesn't hang.
- self.assertLess(end - start, 500)
-
- def test_trainer_tpu(self):
- import xla_spawn
-
- testargs = """
- ./tests/test_trainer_tpu.py
- --num_cores=8
- ./tests/test_trainer_tpu.py
- """.split()
- with patch.object(sys, "argv", testargs):
- xla_spawn.main()
diff --git a/examples/pytorch/question-answering/README.md b/examples/pytorch/question-answering/README.md
deleted file mode 100644
index 75f47a3dae65..000000000000
--- a/examples/pytorch/question-answering/README.md
+++ /dev/null
@@ -1,183 +0,0 @@
-
-
-# Question answering
-
-This folder contains several scripts that showcase how to fine-tune a 🤗 Transformers model on a question answering dataset,
-like SQuAD.
-
-## Trainer-based scripts
-
-The [`run_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa.py),
-[`run_qa_beam_search.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_beam_search.py) and [`run_seq2seq_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_seq2seq_qa.py) leverage the 🤗 [Trainer](https://huggingface.co/transformers/main_classes/trainer.html) for fine-tuning.
-
-### Fine-tuning BERT on SQuAD1.0
-
-The [`run_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa.py) script
-allows to fine-tune any model from our [hub](https://huggingface.co/models) (as long as its architecture has a `ForQuestionAnswering` version in the library) on a question-answering dataset (such as SQuAD, or any other QA dataset available in the `datasets` library, or your own csv/jsonlines files) as long as they are structured the same way as SQuAD. You might need to tweak the data processing inside the script if your data is structured differently.
-
-**Note:** This script only works with models that have a fast tokenizer (backed by the 🤗 Tokenizers library) as it
-uses special features of those tokenizers. You can check if your favorite model has a fast tokenizer in
-[this table](https://huggingface.co/transformers/index.html#supported-frameworks), if it doesn't you can still use the old version of the script which can be found [here](https://github.com/huggingface/transformers/tree/main/examples/legacy/question-answering).
-
-Note that if your dataset contains samples with no possible answers (like SQuAD version 2), you need to pass along the flag `--version_2_with_negative`.
-
-This example code fine-tunes BERT on the SQuAD1.0 dataset. It runs in 24 min (with BERT-base) or 68 min (with BERT-large)
-on a single tesla V100 16GB.
-
-```bash
-python run_qa.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name rajpurkar/squad \
- --do_train \
- --do_eval \
- --per_device_train_batch_size 12 \
- --learning_rate 3e-5 \
- --num_train_epochs 2 \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir /tmp/debug_squad/
-```
-
-Training with the previously defined hyper-parameters yields the following results:
-
-```bash
-f1 = 88.52
-exact_match = 81.22
-```
-
-### Fine-tuning XLNet with beam search on SQuAD
-
-The [`run_qa_beam_search.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa_beam_search.py) script is only meant to fine-tune XLNet, which is a special encoder-only Transformer model. The example code below fine-tunes XLNet on the SQuAD1.0 and SQuAD2.0 datasets.
-
-#### Command for SQuAD1.0:
-
-```bash
-python run_qa_beam_search.py \
- --model_name_or_path xlnet/xlnet-large-cased \
- --dataset_name rajpurkar/squad \
- --do_train \
- --do_eval \
- --learning_rate 3e-5 \
- --num_train_epochs 2 \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir ./wwm_cased_finetuned_squad/ \
- --per_device_eval_batch_size=4 \
- --per_device_train_batch_size=4 \
- --save_steps 5000
-```
-
-#### Command for SQuAD2.0:
-
-```bash
-export SQUAD_DIR=/path/to/SQUAD
-
-python run_qa_beam_search.py \
- --model_name_or_path xlnet/xlnet-large-cased \
- --dataset_name rajpurkar/squad_v2 \
- --do_train \
- --do_eval \
- --version_2_with_negative \
- --learning_rate 3e-5 \
- --num_train_epochs 4 \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir ./wwm_cased_finetuned_squad/ \
- --per_device_eval_batch_size=2 \
- --per_device_train_batch_size=2 \
- --save_steps 5000
-```
-
-### Fine-tuning T5 on SQuAD2.0
-
-The [`run_seq2seq_qa.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_seq2seq_qa.py) script is meant for encoder-decoder (also called seq2seq) Transformer models, such as T5 or BART. These
-models are generative, rather than discriminative. This means that they learn to generate the correct answer, rather than predicting the start and end position of the tokens of the answer.
-
-This example code fine-tunes T5 on the SQuAD2.0 dataset.
-
-```bash
-python run_seq2seq_qa.py \
- --model_name_or_path google-t5/t5-small \
- --dataset_name rajpurkar/squad_v2 \
- --context_column context \
- --question_column question \
- --answer_column answers \
- --do_train \
- --do_eval \
- --per_device_train_batch_size 12 \
- --learning_rate 3e-5 \
- --num_train_epochs 2 \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir /tmp/debug_seq2seq_squad/
-```
-
-## Accelerate-based scripts
-
-Based on the scripts `run_qa_no_trainer.py` and `run_qa_beam_search_no_trainer.py`.
-
-Like `run_qa.py` and `run_qa_beam_search.py`, these scripts allow you to fine-tune any of the models supported on a
-SQuAD or a similar dataset, the main difference is that this script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like. It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer or the dataloaders directly in the script), but still run in a distributed setup, on TPU and supports mixed precision by leveraging the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library.
-
-You can use the script normally after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-python run_qa_no_trainer.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name rajpurkar/squad \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir ~/tmp/debug_squad
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_qa_no_trainer.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name rajpurkar/squad \
- --max_seq_length 384 \
- --doc_stride 128 \
- --output_dir ~/tmp/debug_squad
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/examples/pytorch/question-answering/requirements.txt b/examples/pytorch/question-answering/requirements.txt
deleted file mode 100644
index c8200d867ec4..000000000000
--- a/examples/pytorch/question-answering/requirements.txt
+++ /dev/null
@@ -1,4 +0,0 @@
-accelerate >= 0.12.0
-datasets >= 1.8.0
-torch >= 1.3.0
-evaluate
\ No newline at end of file
diff --git a/examples/pytorch/question-answering/run_qa.py b/examples/pytorch/question-answering/run_qa.py
deleted file mode 100755
index e1945f4f7727..000000000000
--- a/examples/pytorch/question-answering/run_qa.py
+++ /dev/null
@@ -1,693 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Fine-tuning the library models for question answering using a slightly adapted version of the 🤗 Trainer.
-"""
-# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-import warnings
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-from datasets import load_dataset
-from trainer_qa import QuestionAnsweringTrainer
-from utils_qa import postprocess_qa_predictions
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForQuestionAnswering,
- AutoTokenizer,
- DataCollatorWithPadding,
- EvalPrediction,
- HfArgumentParser,
- TrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Path to directory to store the pretrained models downloaded from huggingface.co"},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- test_file: str | None = field(
- default=None,
- metadata={"help": "An optional input test data file to evaluate the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_seq_length: int = field(
- default=384,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
- " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- version_2_with_negative: bool = field(
- default=False, metadata={"help": "If true, some of the examples do not have an answer."}
- )
- null_score_diff_threshold: float = field(
- default=0.0,
- metadata={
- "help": (
- "The threshold used to select the null answer: if the best answer has a score that is less than "
- "the score of the null answer minus this threshold, the null answer is selected for this example. "
- "Only useful when `version_2_with_negative=True`."
- )
- },
- )
- doc_stride: int = field(
- default=128,
- metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
- )
- n_best_size: int = field(
- default=20,
- metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
- )
- max_answer_length: int = field(
- default=30,
- metadata={
- "help": (
- "The maximum length of an answer that can be generated. This is needed because the start "
- "and end predictions are not conditioned on one another."
- )
- },
- )
-
- def __post_init__(self):
- if (
- self.dataset_name is None
- and self.train_file is None
- and self.validation_file is None
- and self.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training/validation file/test_file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if self.test_file is not None:
- extension = self.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
-
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- field="data",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=True,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForQuestionAnswering.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # Tokenizer check: this script requires a fast tokenizer.
- # Check if tokenizer has _tokenizer attribute (from tokenizers library) or is_fast property
- if not (hasattr(tokenizer, "_tokenizer") or getattr(tokenizer, "is_fast", False)):
- raise TypeError(
- "This example script only works for models that have a fast tokenizer. Check out the big table of models at"
- " https://huggingface.co/transformers/index.html#supported-frameworks to find the model types that meet"
- " this requirement"
- )
-
- # Preprocessing the datasets.
- # Preprocessing is slightly different for training and evaluation.
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- elif training_args.do_eval:
- column_names = raw_datasets["validation"].column_names
- else:
- column_names = raw_datasets["test"].column_names
- question_column_name = "question" if "question" in column_names else column_names[0]
- context_column_name = "context" if "context" in column_names else column_names[1]
- answer_column_name = "answers" if "answers" in column_names else column_names[2]
-
- # Padding side determines if we do (question|context) or (context|question).
- pad_on_right = tokenizer.padding_side == "right"
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- # Training preprocessing
- def prepare_train_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=data_args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- padding="max_length" if data_args.pad_to_max_length else False,
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
- # The offset mappings will give us a map from token to character position in the original context. This will
- # help us compute the start_positions and end_positions.
- offset_mapping = tokenized_examples.pop("offset_mapping")
-
- # Let's label those examples!
- tokenized_examples["start_positions"] = []
- tokenized_examples["end_positions"] = []
-
- for i, offsets in enumerate(offset_mapping):
- # We will label impossible answers with the index of the CLS token.
- input_ids = tokenized_examples["input_ids"][i]
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples.sequence_ids(i)
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- answers = examples[answer_column_name][sample_index]
- # If no answers are given, set the cls_index as answer.
- if len(answers["answer_start"]) == 0:
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- else:
- # Start/end character index of the answer in the text.
- start_char = answers["answer_start"][0]
- end_char = start_char + len(answers["text"][0])
-
- # Start token index of the current span in the text.
- token_start_index = 0
- while sequence_ids[token_start_index] != (1 if pad_on_right else 0):
- token_start_index += 1
-
- # End token index of the current span in the text.
- token_end_index = len(input_ids) - 1
- while sequence_ids[token_end_index] != (1 if pad_on_right else 0):
- token_end_index -= 1
-
- # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
- if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- else:
- # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
- # Note: we could go after the last offset if the answer is the last word (edge case).
- while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
- token_start_index += 1
- tokenized_examples["start_positions"].append(token_start_index - 1)
- while offsets[token_end_index][1] >= end_char:
- token_end_index -= 1
- tokenized_examples["end_positions"].append(token_end_index + 1)
-
- return tokenized_examples
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- # We will select sample from whole data if argument is specified
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- # Create train feature from dataset
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- prepare_train_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- if data_args.max_train_samples is not None:
- # Number of samples might increase during Feature Creation, We select only specified max samples
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- # Validation preprocessing
- def prepare_validation_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=data_args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- padding="max_length" if data_args.pad_to_max_length else False,
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
-
- # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
- # corresponding example_id and we will store the offset mappings.
- tokenized_examples["example_id"] = []
-
- for i in range(len(tokenized_examples["input_ids"])):
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples.sequence_ids(i)
- context_index = 1 if pad_on_right else 0
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- tokenized_examples["example_id"].append(examples["id"][sample_index])
-
- # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
- # position is part of the context or not.
- tokenized_examples["offset_mapping"][i] = [
- (o if sequence_ids[k] == context_index else None)
- for k, o in enumerate(tokenized_examples["offset_mapping"][i])
- ]
-
- return tokenized_examples
-
- if training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_examples = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- # We will select sample from whole data
- max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
- eval_examples = eval_examples.select(range(max_eval_samples))
- # Validation Feature Creation
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
- if data_args.max_eval_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- if training_args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_examples = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- # We will select sample from whole data
- predict_examples = predict_examples.select(range(data_args.max_predict_samples))
- # Predict Feature Creation
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
- if data_args.max_predict_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
-
- # Data collator
- # We have already padded to max length if the corresponding flag is True, otherwise we need to pad in the data
- # collator.
- data_collator = (
- default_data_collator
- if data_args.pad_to_max_length
- else DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
- )
-
- # Post-processing:
- def post_processing_function(examples, features, predictions, stage="eval"):
- # Post-processing: we match the start logits and end logits to answers in the original context.
- predictions = postprocess_qa_predictions(
- examples=examples,
- features=features,
- predictions=predictions,
- version_2_with_negative=data_args.version_2_with_negative,
- n_best_size=data_args.n_best_size,
- max_answer_length=data_args.max_answer_length,
- null_score_diff_threshold=data_args.null_score_diff_threshold,
- output_dir=training_args.output_dir,
- log_level=log_level,
- prefix=stage,
- )
- # Format the result to the format the metric expects.
- if data_args.version_2_with_negative:
- formatted_predictions = [
- {"id": str(k), "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
- ]
- else:
- formatted_predictions = [{"id": str(k), "prediction_text": v} for k, v in predictions.items()]
-
- references = [{"id": str(ex["id"]), "answers": ex[answer_column_name]} for ex in examples]
- return EvalPrediction(predictions=formatted_predictions, label_ids=references)
-
- if data_args.version_2_with_negative:
- accepted_best_metrics = ("exact", "f1", "HasAns_exact", "HasAns_f1")
- else:
- accepted_best_metrics = ("exact_match", "f1")
-
- if training_args.load_best_model_at_end and training_args.metric_for_best_model not in accepted_best_metrics:
- warnings.warn(f"--metric_for_best_model should be set to one of {accepted_best_metrics}")
-
- metric = evaluate.load(
- "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
- )
-
- def compute_metrics(p: EvalPrediction):
- return metric.compute(predictions=p.predictions, references=p.label_ids)
-
- # Initialize our Trainer
- trainer = QuestionAnsweringTrainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- eval_examples=eval_examples if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- post_process_function=post_processing_function,
- compute_metrics=compute_metrics,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Prediction
- if training_args.do_predict:
- logger.info("*** Predict ***")
- results = trainer.predict(predict_dataset, predict_examples)
- metrics = results.metrics
-
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/question-answering/run_qa_beam_search.py b/examples/pytorch/question-answering/run_qa_beam_search.py
deleted file mode 100755
index 592cf78a39e6..000000000000
--- a/examples/pytorch/question-answering/run_qa_beam_search.py
+++ /dev/null
@@ -1,720 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Fine-tuning XLNet for question answering with beam search using a slightly adapted version of the 🤗 Trainer.
-"""
-# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-from datasets import load_dataset
-from trainer_qa import QuestionAnsweringTrainer
-from utils_qa import postprocess_qa_predictions_with_beam_search
-
-import transformers
-from transformers import (
- DataCollatorWithPadding,
- EvalPrediction,
- HfArgumentParser,
- TrainingArguments,
- XLNetConfig,
- XLNetForQuestionAnswering,
- XLNetTokenizerFast,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- test_file: str | None = field(
- default=None,
- metadata={"help": "An optional input test data file to test the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_seq_length: int = field(
- default=384,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
- " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- version_2_with_negative: bool = field(
- default=False, metadata={"help": "If true, some of the examples do not have an answer."}
- )
- null_score_diff_threshold: float = field(
- default=0.0,
- metadata={
- "help": (
- "The threshold used to select the null answer: if the best answer has a score that is less than "
- "the score of the null answer minus this threshold, the null answer is selected for this example. "
- "Only useful when `version_2_with_negative=True`."
- )
- },
- )
- doc_stride: int = field(
- default=128,
- metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
- )
- n_best_size: int = field(
- default=20,
- metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
- )
- max_answer_length: int = field(
- default=30,
- metadata={
- "help": (
- "The maximum length of an answer that can be generated. This is needed because the start "
- "and end predictions are not conditioned on one another."
- )
- },
- )
-
- def __post_init__(self):
- if (
- self.dataset_name is None
- and self.train_file is None
- and self.validation_file is None
- and self.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training/validation/test file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if self.test_file is not None:
- extension = self.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- field="data",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = XLNetConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- )
- tokenizer = XLNetTokenizerFast.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- )
- model = XLNetForQuestionAnswering.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- )
-
- # Preprocessing the datasets.
- # Preprocessing is slightly different for training and evaluation.
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- elif training_args.do_eval:
- column_names = raw_datasets["validation"].column_names
- else:
- column_names = raw_datasets["test"].column_names
- question_column_name = "question" if "question" in column_names else column_names[0]
- context_column_name = "context" if "context" in column_names else column_names[1]
- answer_column_name = "answers" if "answers" in column_names else column_names[2]
-
- # Padding side determines if we do (question|context) or (context|question).
- pad_on_right = tokenizer.padding_side == "right"
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- # Training preprocessing
- def prepare_train_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=data_args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- return_special_tokens_mask=True,
- return_token_type_ids=True,
- padding="max_length",
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
- # The offset mappings will give us a map from token to character position in the original context. This will
- # help us compute the start_positions and end_positions.
- offset_mapping = tokenized_examples.pop("offset_mapping")
- # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
- special_tokens = tokenized_examples.pop("special_tokens_mask")
-
- # Let's label those examples!
- tokenized_examples["start_positions"] = []
- tokenized_examples["end_positions"] = []
- tokenized_examples["is_impossible"] = []
- tokenized_examples["cls_index"] = []
- tokenized_examples["p_mask"] = []
-
- for i, offsets in enumerate(offset_mapping):
- # We will label impossible answers with the index of the CLS token.
- input_ids = tokenized_examples["input_ids"][i]
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
- tokenized_examples["cls_index"].append(cls_index)
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples["token_type_ids"][i]
- for k, s in enumerate(special_tokens[i]):
- if s:
- sequence_ids[k] = 3
- context_idx = 1 if pad_on_right else 0
-
- # Build the p_mask: non special tokens and context gets 0.0, the others get 1.0.
- # The cls token gets 1.0 too (for predictions of empty answers).
- tokenized_examples["p_mask"].append(
- [
- 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
- for k, s in enumerate(sequence_ids)
- ]
- )
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- answers = examples[answer_column_name][sample_index]
- # If no answers are given, set the cls_index as answer.
- if len(answers["answer_start"]) == 0:
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- tokenized_examples["is_impossible"].append(1.0)
- else:
- # Start/end character index of the answer in the text.
- start_char = answers["answer_start"][0]
- end_char = start_char + len(answers["text"][0])
-
- # Start token index of the current span in the text.
- token_start_index = 0
- while sequence_ids[token_start_index] != context_idx:
- token_start_index += 1
-
- # End token index of the current span in the text.
- token_end_index = len(input_ids) - 1
- while sequence_ids[token_end_index] != context_idx:
- token_end_index -= 1
- # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
- if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- tokenized_examples["is_impossible"].append(1.0)
- else:
- # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
- # Note: we could go after the last offset if the answer is the last word (edge case).
- while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
- token_start_index += 1
- tokenized_examples["start_positions"].append(token_start_index - 1)
- while offsets[token_end_index][1] >= end_char:
- token_end_index -= 1
- tokenized_examples["end_positions"].append(token_end_index + 1)
- tokenized_examples["is_impossible"].append(0.0)
-
- return tokenized_examples
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- # Select samples from Dataset, This will help to decrease processing time
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- # Create Training Features
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- prepare_train_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- if data_args.max_train_samples is not None:
- # Select samples from dataset again since Feature Creation might increase number of features
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- # Validation preprocessing
- def prepare_validation_features(examples):
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=data_args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- return_special_tokens_mask=True,
- return_token_type_ids=True,
- padding="max_length",
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
-
- # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
- special_tokens = tokenized_examples.pop("special_tokens_mask")
-
- # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
- # corresponding example_id and we will store the offset mappings.
- tokenized_examples["example_id"] = []
-
- # We still provide the index of the CLS token and the p_mask to the model, but not the is_impossible label.
- tokenized_examples["cls_index"] = []
- tokenized_examples["p_mask"] = []
-
- for i, input_ids in enumerate(tokenized_examples["input_ids"]):
- # Find the CLS token in the input ids.
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
- tokenized_examples["cls_index"].append(cls_index)
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples["token_type_ids"][i]
- for k, s in enumerate(special_tokens[i]):
- if s:
- sequence_ids[k] = 3
- context_idx = 1 if pad_on_right else 0
-
- # Build the p_mask: non special tokens and context gets 0.0, the others 1.0.
- tokenized_examples["p_mask"].append(
- [
- 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
- for k, s in enumerate(sequence_ids)
- ]
- )
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- tokenized_examples["example_id"].append(examples["id"][sample_index])
-
- # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
- # position is part of the context or not.
- tokenized_examples["offset_mapping"][i] = [
- (o if sequence_ids[k] == context_idx else None)
- for k, o in enumerate(tokenized_examples["offset_mapping"][i])
- ]
-
- return tokenized_examples
-
- if training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_examples = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- # Selecting Eval Samples from Dataset
- max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
- eval_examples = eval_examples.select(range(max_eval_samples))
- # Create Features from Eval Dataset
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
- if data_args.max_eval_samples is not None:
- # Selecting Samples from Dataset again since Feature Creation might increase samples size
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- if training_args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_examples = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- # We will select sample from whole data
- predict_examples = predict_examples.select(range(data_args.max_predict_samples))
- # Test Feature Creation
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
- if data_args.max_predict_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
-
- # Data collator
- # We have already padded to max length if the corresponding flag is True, otherwise we need to pad in the data
- # collator.
- data_collator = (
- default_data_collator
- if data_args.pad_to_max_length
- else DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
- )
-
- # Post-processing:
- def post_processing_function(examples, features, predictions, stage="eval"):
- # Post-processing: we match the start logits and end logits to answers in the original context.
- predictions, scores_diff_json = postprocess_qa_predictions_with_beam_search(
- examples=examples,
- features=features,
- predictions=predictions,
- version_2_with_negative=data_args.version_2_with_negative,
- n_best_size=data_args.n_best_size,
- max_answer_length=data_args.max_answer_length,
- start_n_top=model.config.start_n_top,
- end_n_top=model.config.end_n_top,
- output_dir=training_args.output_dir,
- log_level=log_level,
- prefix=stage,
- )
- # Format the result to the format the metric expects.
- if data_args.version_2_with_negative:
- formatted_predictions = [
- {"id": k, "prediction_text": v, "no_answer_probability": scores_diff_json[k]}
- for k, v in predictions.items()
- ]
- else:
- formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
-
- references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
- return EvalPrediction(predictions=formatted_predictions, label_ids=references)
-
- metric = evaluate.load(
- "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
- )
-
- def compute_metrics(p: EvalPrediction):
- return metric.compute(predictions=p.predictions, references=p.label_ids)
-
- # Initialize our Trainer
- trainer = QuestionAnsweringTrainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- eval_examples=eval_examples if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- post_process_function=post_processing_function,
- compute_metrics=compute_metrics,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Prediction
- if training_args.do_predict:
- logger.info("*** Predict ***")
- results = trainer.predict(predict_dataset, predict_examples)
- metrics = results.metrics
-
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py b/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py
deleted file mode 100644
index 1af4d95f065b..000000000000
--- a/examples/pytorch/question-answering/run_qa_beam_search_no_trainer.py
+++ /dev/null
@@ -1,1064 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Fine-tuning XLNet for question answering with beam search using 🤗 Accelerate.
-"""
-# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-from utils_qa import postprocess_qa_predictions_with_beam_search
-
-import transformers
-from transformers import (
- DataCollatorWithPadding,
- EvalPrediction,
- SchedulerType,
- XLNetConfig,
- XLNetForQuestionAnswering,
- XLNetTokenizerFast,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
-
-logger = get_logger(__name__)
-
-
-def save_prefixed_metrics(results, output_dir, file_name: str = "all_results.json", metric_key_prefix: str = "eval"):
- """
- Save results while prefixing metric names.
-
- Args:
- results: (:obj:`dict`):
- A dictionary of results.
- output_dir: (:obj:`str`):
- An output directory.
- file_name: (:obj:`str`, `optional`, defaults to :obj:`all_results.json`):
- An output file name.
- metric_key_prefix: (:obj:`str`, `optional`, defaults to :obj:`eval`):
- A metric name prefix.
- """
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(results.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- results[f"{metric_key_prefix}_{key}"] = results.pop(key)
-
- with open(os.path.join(output_dir, file_name), "w", encoding="utf-8") as f:
- json.dump(results, f, indent=4)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a Question Answering task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--preprocessing_num_workers", type=int, default=1, help="A csv or a json file containing the training data."
- )
- parser.add_argument("--do_predict", action="store_true", help="Eval the question answering model")
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--test_file", type=str, default=None, help="A csv or a json file containing the Prediction data."
- )
- parser.add_argument(
- "--max_seq_length",
- type=int,
- default=384,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_seq_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=True,
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--doc_stride",
- type=int,
- default=128,
- help="When splitting up a long document into chunks how much stride to take between chunks.",
- )
- parser.add_argument(
- "--n_best_size",
- type=int,
- default=20,
- help="The total number of n-best predictions to generate when looking for an answer.",
- )
- parser.add_argument(
- "--null_score_diff_threshold",
- type=float,
- default=0.0,
- help=(
- "The threshold used to select the null answer: if the best answer has a score that is less than "
- "the score of the null answer minus this threshold, the null answer is selected for this example. "
- "Only useful when `version_2_with_negative=True`."
- ),
- )
- parser.add_argument(
- "--version_2_with_negative",
- action="store_true",
- help="If true, some of the examples do not have an answer.",
- )
- parser.add_argument(
- "--max_answer_length",
- type=int,
- default=30,
- help=(
- "The maximum length of an answer that can be generated. This is needed because the start "
- "and end predictions are not conditioned on one another."
- ),
- )
- parser.add_argument(
- "--max_train_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--max_eval_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--max_predict_samples",
- type=int,
- default=None,
- help="For debugging purposes or quicker training, truncate the number of prediction examples to this",
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to load in all available experiment trackers from the environment and use them for logging.",
- )
- args = parser.parse_args()
-
- # Sanity checks
- if (
- args.dataset_name is None
- and args.train_file is None
- and args.validation_file is None
- and args.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training/validation/test file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if args.test_file is not None:
- extension = args.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- if args.test_file is not None:
- data_files["test"] = args.test_file
- extension = args.test_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files, field="data")
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
-
- config = XLNetConfig.from_pretrained(args.model_name_or_path)
- tokenizer = XLNetTokenizerFast.from_pretrained(args.model_name_or_path)
- model = XLNetForQuestionAnswering.from_pretrained(
- args.model_name_or_path, from_tf=bool(".ckpt" in args.model_name_or_path), config=config
- )
-
- # Preprocessing the datasets.
- # Preprocessing is slightly different for training and evaluation.
- column_names = raw_datasets["train"].column_names
-
- question_column_name = "question" if "question" in column_names else column_names[0]
- context_column_name = "context" if "context" in column_names else column_names[1]
- answer_column_name = "answers" if "answers" in column_names else column_names[2]
-
- # Padding side determines if we do (question|context) or (context|question).
- pad_on_right = tokenizer.padding_side == "right"
-
- if args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
-
- max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
-
- # Training preprocessing
- def prepare_train_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- return_special_tokens_mask=True,
- return_token_type_ids=True,
- padding="max_length",
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
- # The offset mappings will give us a map from token to character position in the original context. This will
- # help us compute the start_positions and end_positions.
- offset_mapping = tokenized_examples.pop("offset_mapping")
- # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
- special_tokens = tokenized_examples.pop("special_tokens_mask")
-
- # Let's label those examples!
- tokenized_examples["start_positions"] = []
- tokenized_examples["end_positions"] = []
- tokenized_examples["is_impossible"] = []
- tokenized_examples["cls_index"] = []
- tokenized_examples["p_mask"] = []
-
- for i, offsets in enumerate(offset_mapping):
- # We will label impossible answers with the index of the CLS token.
- input_ids = tokenized_examples["input_ids"][i]
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
- tokenized_examples["cls_index"].append(cls_index)
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples["token_type_ids"][i]
- for k, s in enumerate(special_tokens[i]):
- if s:
- sequence_ids[k] = 3
- context_idx = 1 if pad_on_right else 0
-
- # Build the p_mask: non special tokens and context gets 0.0, the others get 1.0.
- # The cls token gets 1.0 too (for predictions of empty answers).
- tokenized_examples["p_mask"].append(
- [
- 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
- for k, s in enumerate(sequence_ids)
- ]
- )
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- answers = examples[answer_column_name][sample_index]
- # If no answers are given, set the cls_index as answer.
- if len(answers["answer_start"]) == 0:
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- tokenized_examples["is_impossible"].append(1.0)
- else:
- # Start/end character index of the answer in the text.
- start_char = answers["answer_start"][0]
- end_char = start_char + len(answers["text"][0])
-
- # Start token index of the current span in the text.
- token_start_index = 0
- while sequence_ids[token_start_index] != context_idx:
- token_start_index += 1
-
- # End token index of the current span in the text.
- token_end_index = len(input_ids) - 1
- while sequence_ids[token_end_index] != context_idx:
- token_end_index -= 1
- # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
- if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- tokenized_examples["is_impossible"].append(1.0)
- else:
- # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
- # Note: we could go after the last offset if the answer is the last word (edge case).
- while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
- token_start_index += 1
- tokenized_examples["start_positions"].append(token_start_index - 1)
- while offsets[token_end_index][1] >= end_char:
- token_end_index -= 1
- tokenized_examples["end_positions"].append(token_end_index + 1)
- tokenized_examples["is_impossible"].append(0.0)
-
- return tokenized_examples
-
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if args.max_train_samples is not None:
- # We will select sample from whole data if argument is specified
- train_dataset = train_dataset.select(range(args.max_train_samples))
- # Create train feature from dataset
- with accelerator.main_process_first():
- train_dataset = train_dataset.map(
- prepare_train_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- if args.max_train_samples is not None:
- # Number of samples might increase during Feature Creation, We select only specified max samples
- train_dataset = train_dataset.select(range(args.max_train_samples))
-
- # Validation preprocessing
- def prepare_validation_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- return_special_tokens_mask=True,
- return_token_type_ids=True,
- padding="max_length",
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
-
- # The special tokens will help us build the p_mask (which indicates the tokens that can't be in answers).
- special_tokens = tokenized_examples.pop("special_tokens_mask")
-
- # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
- # corresponding example_id and we will store the offset mappings.
- tokenized_examples["example_id"] = []
-
- # We still provide the index of the CLS token and the p_mask to the model, but not the is_impossible label.
- tokenized_examples["cls_index"] = []
- tokenized_examples["p_mask"] = []
-
- for i, input_ids in enumerate(tokenized_examples["input_ids"]):
- # Find the CLS token in the input ids.
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
- tokenized_examples["cls_index"].append(cls_index)
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples["token_type_ids"][i]
- for k, s in enumerate(special_tokens[i]):
- if s:
- sequence_ids[k] = 3
- context_idx = 1 if pad_on_right else 0
-
- # Build the p_mask: non special tokens and context gets 0.0, the others 1.0.
- tokenized_examples["p_mask"].append(
- [
- 0.0 if (not special_tokens[i][k] and s == context_idx) or k == cls_index else 1.0
- for k, s in enumerate(sequence_ids)
- ]
- )
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- tokenized_examples["example_id"].append(examples["id"][sample_index])
-
- # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
- # position is part of the context or not.
- tokenized_examples["offset_mapping"][i] = [
- (o if sequence_ids[k] == context_idx else None)
- for k, o in enumerate(tokenized_examples["offset_mapping"][i])
- ]
-
- return tokenized_examples
-
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_examples = raw_datasets["validation"]
- if args.max_eval_samples is not None:
- # We will select sample from whole data
- eval_examples = eval_examples.select(range(args.max_eval_samples))
- # Validation Feature Creation
- with accelerator.main_process_first():
- eval_dataset = eval_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if args.max_eval_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- eval_dataset = eval_dataset.select(range(args.max_eval_samples))
-
- if args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_examples = raw_datasets["test"]
- if args.max_predict_samples is not None:
- # We will select sample from whole data
- predict_examples = predict_examples.select(range(args.max_predict_samples))
- # Predict Feature Creation
- with accelerator.main_process_first():
- predict_dataset = predict_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
- if args.max_predict_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- predict_dataset = predict_dataset.select(range(args.max_predict_samples))
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
-
- eval_dataset_for_model = eval_dataset.remove_columns(["example_id", "offset_mapping"])
- eval_dataloader = DataLoader(
- eval_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- if args.do_predict:
- predict_dataset_for_model = predict_dataset.remove_columns(["example_id", "offset_mapping"])
- predict_dataloader = DataLoader(
- predict_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Post-processing:
- def post_processing_function(examples, features, predictions, stage="eval"):
- # Post-processing: we match the start logits and end logits to answers in the original context.
- predictions, scores_diff_json = postprocess_qa_predictions_with_beam_search(
- examples=examples,
- features=features,
- predictions=predictions,
- version_2_with_negative=args.version_2_with_negative,
- n_best_size=args.n_best_size,
- max_answer_length=args.max_answer_length,
- start_n_top=model.config.start_n_top,
- end_n_top=model.config.end_n_top,
- output_dir=args.output_dir,
- prefix=stage,
- )
- # Format the result to the format the metric expects.
- if args.version_2_with_negative:
- formatted_predictions = [
- {"id": k, "prediction_text": v, "no_answer_probability": scores_diff_json[k]}
- for k, v in predictions.items()
- ]
- else:
- formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
-
- references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
- return EvalPrediction(predictions=formatted_predictions, label_ids=references)
-
- metric = evaluate.load("squad_v2" if args.version_2_with_negative else "squad")
-
- def create_and_fill_np_array(start_or_end_logits, dataset, max_len):
- """
- Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
-
- Args:
- start_or_end_logits(:obj:`tensor`):
- This is the output predictions of the model. We can only enter either start or end logits.
- eval_dataset: Evaluation dataset
- max_len(:obj:`int`):
- The maximum length of the output tensor. ( See the model.eval() part for more details )
- """
-
- step = 0
- # create a numpy array and fill it with -100.
- logits_concat = np.full((len(dataset), max_len), -100, dtype=np.float32)
- # Now since we have create an array now we will populate it with the outputs gathered using accelerator.gather_for_metrics
- for i, output_logit in enumerate(start_or_end_logits): # populate columns
- # We have to fill it such that we have to take the whole tensor and replace it on the newly created array
- # And after every iteration we have to change the step
-
- batch_size = output_logit.shape[0]
- cols = output_logit.shape[1]
- if step + batch_size < len(dataset):
- logits_concat[step : step + batch_size, :cols] = output_logit
- else:
- logits_concat[step:, :cols] = output_logit[: len(dataset) - step]
-
- step += batch_size
-
- return logits_concat
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("qa_beam_search_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
-
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
-
- accelerator.backward(loss)
-
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- accelerator.save_state(f"step_{completed_steps}")
-
- if completed_steps >= args.max_train_steps:
- break
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- # initialize all lists to collect the batches
- all_start_top_log_probs = []
- all_start_top_index = []
- all_end_top_log_probs = []
- all_end_top_index = []
- all_cls_logits = []
-
- model.eval()
-
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- start_top_log_probs = outputs.start_top_log_probs
- start_top_index = outputs.start_top_index
- end_top_log_probs = outputs.end_top_log_probs
- end_top_index = outputs.end_top_index
- cls_logits = outputs.cls_logits
-
- if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
- start_top_log_probs = accelerator.pad_across_processes(start_top_log_probs, dim=1, pad_index=-100)
- start_top_index = accelerator.pad_across_processes(start_top_index, dim=1, pad_index=-100)
- end_top_log_probs = accelerator.pad_across_processes(end_top_log_probs, dim=1, pad_index=-100)
- end_top_index = accelerator.pad_across_processes(end_top_index, dim=1, pad_index=-100)
- cls_logits = accelerator.pad_across_processes(cls_logits, dim=1, pad_index=-100)
-
- all_start_top_log_probs.append(accelerator.gather_for_metrics(start_top_log_probs).cpu().numpy())
- all_start_top_index.append(accelerator.gather_for_metrics(start_top_index).cpu().numpy())
- all_end_top_log_probs.append(accelerator.gather_for_metrics(end_top_log_probs).cpu().numpy())
- all_end_top_index.append(accelerator.gather_for_metrics(end_top_index).cpu().numpy())
- all_cls_logits.append(accelerator.gather_for_metrics(cls_logits).cpu().numpy())
-
- max_len = max(x.shape[1] for x in all_end_top_log_probs) # Get the max_length of the tensor
-
- # concatenate all numpy arrays collected above
- start_top_log_probs_concat = create_and_fill_np_array(all_start_top_log_probs, eval_dataset, max_len)
- start_top_index_concat = create_and_fill_np_array(all_start_top_index, eval_dataset, max_len)
- end_top_log_probs_concat = create_and_fill_np_array(all_end_top_log_probs, eval_dataset, max_len)
- end_top_index_concat = create_and_fill_np_array(all_end_top_index, eval_dataset, max_len)
- cls_logits_concat = np.concatenate(all_cls_logits, axis=0)
-
- # delete the list of numpy arrays
- del start_top_log_probs
- del start_top_index
- del end_top_log_probs
- del end_top_index
- del cls_logits
-
- outputs_numpy = (
- start_top_log_probs_concat,
- start_top_index_concat,
- end_top_log_probs_concat,
- end_top_index_concat,
- cls_logits_concat,
- )
- prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
- eval_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
- logger.info(f"Evaluation metrics: {eval_metric}")
-
- if args.do_predict:
- # initialize all lists to collect the batches
-
- all_start_top_log_probs = []
- all_start_top_index = []
- all_end_top_log_probs = []
- all_end_top_index = []
- all_cls_logits = []
-
- model.eval()
-
- for step, batch in enumerate(predict_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- start_top_log_probs = outputs.start_top_log_probs
- start_top_index = outputs.start_top_index
- end_top_log_probs = outputs.end_top_log_probs
- end_top_index = outputs.end_top_index
- cls_logits = outputs.cls_logits
-
- if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
- start_top_log_probs = accelerator.pad_across_processes(start_top_log_probs, dim=1, pad_index=-100)
- start_top_index = accelerator.pad_across_processes(start_top_index, dim=1, pad_index=-100)
- end_top_log_probs = accelerator.pad_across_processes(end_top_log_probs, dim=1, pad_index=-100)
- end_top_index = accelerator.pad_across_processes(end_top_index, dim=1, pad_index=-100)
- cls_logits = accelerator.pad_across_processes(cls_logits, dim=1, pad_index=-100)
-
- all_start_top_log_probs.append(accelerator.gather_for_metrics(start_top_log_probs).cpu().numpy())
- all_start_top_index.append(accelerator.gather_for_metrics(start_top_index).cpu().numpy())
- all_end_top_log_probs.append(accelerator.gather_for_metrics(end_top_log_probs).cpu().numpy())
- all_end_top_index.append(accelerator.gather_for_metrics(end_top_index).cpu().numpy())
- all_cls_logits.append(accelerator.gather_for_metrics(cls_logits).cpu().numpy())
-
- max_len = max(x.shape[1] for x in all_end_top_log_probs) # Get the max_length of the tensor
-
- # concatenate all numpy arrays collected above
- start_top_log_probs_concat = create_and_fill_np_array(all_start_top_log_probs, predict_dataset, max_len)
- start_top_index_concat = create_and_fill_np_array(all_start_top_index, predict_dataset, max_len)
- end_top_log_probs_concat = create_and_fill_np_array(all_end_top_log_probs, predict_dataset, max_len)
- end_top_index_concat = create_and_fill_np_array(all_end_top_index, predict_dataset, max_len)
- cls_logits_concat = np.concatenate(all_cls_logits, axis=0)
-
- # delete the list of numpy arrays
- del start_top_log_probs
- del start_top_index
- del end_top_log_probs
- del end_top_index
- del cls_logits
-
- outputs_numpy = (
- start_top_log_probs_concat,
- start_top_index_concat,
- end_top_log_probs_concat,
- end_top_index_concat,
- cls_logits_concat,
- )
-
- prediction = post_processing_function(predict_examples, predict_dataset, outputs_numpy)
- predict_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
- logger.info(f"Predict metrics: {predict_metric}")
-
- if args.with_tracking:
- log = {
- "squad_v2" if args.version_2_with_negative else "squad": eval_metric,
- "train_loss": total_loss,
- "epoch": epoch,
- "step": completed_steps,
- }
- if args.do_predict:
- log["squad_v2_predict" if args.version_2_with_negative else "squad_predict"] = predict_metric
-
- accelerator.log(log)
-
- if args.checkpointing_steps == "epoch":
- accelerator.save_state(f"epoch_{epoch}")
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- logger.info(json.dumps(eval_metric, indent=4))
- save_prefixed_metrics(eval_metric, args.output_dir)
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/question-answering/run_qa_no_trainer.py b/examples/pytorch/question-answering/run_qa_no_trainer.py
deleted file mode 100755
index 517cab8d21b9..000000000000
--- a/examples/pytorch/question-answering/run_qa_no_trainer.py
+++ /dev/null
@@ -1,1042 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Fine-tuning a 🤗 Transformers model for question answering using 🤗 Accelerate.
-"""
-# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-from utils_qa import postprocess_qa_predictions
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForQuestionAnswering,
- AutoTokenizer,
- DataCollatorWithPadding,
- EvalPrediction,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
-
-logger = get_logger(__name__)
-# You should update this to your particular problem to have better documentation of `model_type`
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def save_prefixed_metrics(results, output_dir, file_name: str = "all_results.json", metric_key_prefix: str = "eval"):
- """
- Save results while prefixing metric names.
-
- Args:
- results: (:obj:`dict`):
- A dictionary of results.
- output_dir: (:obj:`str`):
- An output directory.
- file_name: (:obj:`str`, `optional`, defaults to :obj:`all_results.json`):
- An output file name.
- metric_key_prefix: (:obj:`str`, `optional`, defaults to :obj:`eval`):
- A metric name prefix.
- """
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(results.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- results[f"{metric_key_prefix}_{key}"] = results.pop(key)
-
- with open(os.path.join(output_dir, file_name), "w", encoding="utf-8") as f:
- json.dump(results, f, indent=4)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a Question Answering task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--preprocessing_num_workers", type=int, default=1, help="A csv or a json file containing the training data."
- )
- parser.add_argument("--do_predict", action="store_true", help="To do prediction on the question answering model")
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--test_file", type=str, default=None, help="A csv or a json file containing the Prediction data."
- )
- parser.add_argument(
- "--max_seq_length",
- type=int,
- default=384,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_seq_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--doc_stride",
- type=int,
- default=128,
- help="When splitting up a long document into chunks how much stride to take between chunks.",
- )
- parser.add_argument(
- "--n_best_size",
- type=int,
- default=20,
- help="The total number of n-best predictions to generate when looking for an answer.",
- )
- parser.add_argument(
- "--null_score_diff_threshold",
- type=float,
- default=0.0,
- help=(
- "The threshold used to select the null answer: if the best answer has a score that is less than "
- "the score of the null answer minus this threshold, the null answer is selected for this example. "
- "Only useful when `version_2_with_negative=True`."
- ),
- )
- parser.add_argument(
- "--version_2_with_negative",
- action="store_true",
- help="If true, some of the examples do not have an answer.",
- )
- parser.add_argument(
- "--max_answer_length",
- type=int,
- default=30,
- help=(
- "The maximum length of an answer that can be generated. This is needed because the start "
- "and end predictions are not conditioned on one another."
- ),
- )
- parser.add_argument(
- "--max_train_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--max_eval_samples",
- type=int,
- default=None,
- help=(
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- ),
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--max_predict_samples",
- type=int,
- default=None,
- help="For debugging purposes or quicker training, truncate the number of prediction examples to this",
- )
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if (
- args.dataset_name is None
- and args.train_file is None
- and args.validation_file is None
- and args.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training/validation/test file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if args.test_file is not None:
- extension = args.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- if args.test_file is not None:
- data_files["test"] = args.test_file
- extension = args.test_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files, field="data")
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
-
- if args.config_name:
- config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=True, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=True, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForQuestionAnswering.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForQuestionAnswering.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # Preprocessing the datasets.
- # Preprocessing is slightly different for training and evaluation.
-
- column_names = raw_datasets["train"].column_names
-
- question_column_name = "question" if "question" in column_names else column_names[0]
- context_column_name = "context" if "context" in column_names else column_names[1]
- answer_column_name = "answers" if "answers" in column_names else column_names[2]
-
- # Padding side determines if we do (question|context) or (context|question).
- pad_on_right = tokenizer.padding_side == "right"
-
- if args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
-
- max_seq_length = min(args.max_seq_length, tokenizer.model_max_length)
-
- # Training preprocessing
- def prepare_train_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- padding="max_length" if args.pad_to_max_length else False,
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
- # The offset mappings will give us a map from token to character position in the original context. This will
- # help us compute the start_positions and end_positions.
- offset_mapping = tokenized_examples.pop("offset_mapping")
-
- # Let's label those examples!
- tokenized_examples["start_positions"] = []
- tokenized_examples["end_positions"] = []
-
- for i, offsets in enumerate(offset_mapping):
- # We will label impossible answers with the index of the CLS token.
- input_ids = tokenized_examples["input_ids"][i]
- if tokenizer.cls_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.cls_token_id)
- elif tokenizer.bos_token_id in input_ids:
- cls_index = input_ids.index(tokenizer.bos_token_id)
- else:
- cls_index = 0
-
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples.sequence_ids(i)
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- answers = examples[answer_column_name][sample_index]
- # If no answers are given, set the cls_index as answer.
- if len(answers["answer_start"]) == 0:
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- else:
- # Start/end character index of the answer in the text.
- start_char = answers["answer_start"][0]
- end_char = start_char + len(answers["text"][0])
-
- # Start token index of the current span in the text.
- token_start_index = 0
- while sequence_ids[token_start_index] != (1 if pad_on_right else 0):
- token_start_index += 1
-
- # End token index of the current span in the text.
- token_end_index = len(input_ids) - 1
- while sequence_ids[token_end_index] != (1 if pad_on_right else 0):
- token_end_index -= 1
-
- # Detect if the answer is out of the span (in which case this feature is labeled with the CLS index).
- if not (offsets[token_start_index][0] <= start_char and offsets[token_end_index][1] >= end_char):
- tokenized_examples["start_positions"].append(cls_index)
- tokenized_examples["end_positions"].append(cls_index)
- else:
- # Otherwise move the token_start_index and token_end_index to the two ends of the answer.
- # Note: we could go after the last offset if the answer is the last word (edge case).
- while token_start_index < len(offsets) and offsets[token_start_index][0] <= start_char:
- token_start_index += 1
- tokenized_examples["start_positions"].append(token_start_index - 1)
- while offsets[token_end_index][1] >= end_char:
- token_end_index -= 1
- tokenized_examples["end_positions"].append(token_end_index + 1)
-
- return tokenized_examples
-
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if args.max_train_samples is not None:
- # We will select sample from whole data if argument is specified
- train_dataset = train_dataset.select(range(args.max_train_samples))
-
- # Create train feature from dataset
- with accelerator.main_process_first():
- train_dataset = train_dataset.map(
- prepare_train_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- if args.max_train_samples is not None:
- # Number of samples might increase during Feature Creation, We select only specified max samples
- train_dataset = train_dataset.select(range(args.max_train_samples))
-
- # Validation preprocessing
- def prepare_validation_features(examples):
- # Some of the questions have lots of whitespace on the left, which is not useful and will make the
- # truncation of the context fail (the tokenized question will take a lots of space). So we remove that
- # left whitespace
- examples[question_column_name] = [q.lstrip() for q in examples[question_column_name]]
-
- # Tokenize our examples with truncation and maybe padding, but keep the overflows using a stride. This results
- # in one example possible giving several features when a context is long, each of those features having a
- # context that overlaps a bit the context of the previous feature.
- tokenized_examples = tokenizer(
- examples[question_column_name if pad_on_right else context_column_name],
- examples[context_column_name if pad_on_right else question_column_name],
- truncation="only_second" if pad_on_right else "only_first",
- max_length=max_seq_length,
- stride=args.doc_stride,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- padding="max_length" if args.pad_to_max_length else False,
- )
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = tokenized_examples.pop("overflow_to_sample_mapping")
-
- # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
- # corresponding example_id and we will store the offset mappings.
- tokenized_examples["example_id"] = []
-
- for i in range(len(tokenized_examples["input_ids"])):
- # Grab the sequence corresponding to that example (to know what is the context and what is the question).
- sequence_ids = tokenized_examples.sequence_ids(i)
- context_index = 1 if pad_on_right else 0
-
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- tokenized_examples["example_id"].append(examples["id"][sample_index])
-
- # Set to None the offset_mapping that are not part of the context so it's easy to determine if a token
- # position is part of the context or not.
- tokenized_examples["offset_mapping"][i] = [
- (o if sequence_ids[k] == context_index else None)
- for k, o in enumerate(tokenized_examples["offset_mapping"][i])
- ]
-
- return tokenized_examples
-
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_examples = raw_datasets["validation"]
- if args.max_eval_samples is not None:
- # We will select sample from whole data
- eval_examples = eval_examples.select(range(args.max_eval_samples))
- # Validation Feature Creation
- with accelerator.main_process_first():
- eval_dataset = eval_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if args.max_eval_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- eval_dataset = eval_dataset.select(range(args.max_eval_samples))
-
- if args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_examples = raw_datasets["test"]
- if args.max_predict_samples is not None:
- # We will select sample from whole data
- predict_examples = predict_examples.select(range(args.max_predict_samples))
- # Predict Feature Creation
- with accelerator.main_process_first():
- predict_dataset = predict_examples.map(
- prepare_validation_features,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
- if args.max_predict_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- predict_dataset = predict_dataset.select(range(args.max_predict_samples))
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
-
- eval_dataset_for_model = eval_dataset.remove_columns(["example_id", "offset_mapping"])
- eval_dataloader = DataLoader(
- eval_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- if args.do_predict:
- predict_dataset_for_model = predict_dataset.remove_columns(["example_id", "offset_mapping"])
- predict_dataloader = DataLoader(
- predict_dataset_for_model, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Post-processing:
- def post_processing_function(examples, features, predictions, stage="eval"):
- # Post-processing: we match the start logits and end logits to answers in the original context.
- predictions = postprocess_qa_predictions(
- examples=examples,
- features=features,
- predictions=predictions,
- version_2_with_negative=args.version_2_with_negative,
- n_best_size=args.n_best_size,
- max_answer_length=args.max_answer_length,
- null_score_diff_threshold=args.null_score_diff_threshold,
- output_dir=args.output_dir,
- prefix=stage,
- )
- # Format the result to the format the metric expects.
- if args.version_2_with_negative:
- formatted_predictions = [
- {"id": k, "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
- ]
- else:
- formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
-
- references = [{"id": ex["id"], "answers": ex[answer_column_name]} for ex in examples]
- return EvalPrediction(predictions=formatted_predictions, label_ids=references)
-
- metric = evaluate.load("squad_v2" if args.version_2_with_negative else "squad")
-
- # Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
- def create_and_fill_np_array(start_or_end_logits, dataset, max_len):
- """
- Create and fill numpy array of size len_of_validation_data * max_length_of_output_tensor
-
- Args:
- start_or_end_logits(:obj:`tensor`):
- This is the output predictions of the model. We can only enter either start or end logits.
- eval_dataset: Evaluation dataset
- max_len(:obj:`int`):
- The maximum length of the output tensor. ( See the model.eval() part for more details )
- """
-
- step = 0
- # create a numpy array and fill it with -100.
- logits_concat = np.full((len(dataset), max_len), -100, dtype=np.float64)
- # Now since we have create an array now we will populate it with the outputs gathered using accelerator.gather_for_metrics
- for i, output_logit in enumerate(start_or_end_logits): # populate columns
- # We have to fill it such that we have to take the whole tensor and replace it on the newly created array
- # And after every iteration we have to change the step
-
- batch_size = output_logit.shape[0]
- cols = output_logit.shape[1]
-
- if step + batch_size < len(dataset):
- logits_concat[step : step + batch_size, :cols] = output_logit
- else:
- logits_concat[step:, :cols] = output_logit[: len(dataset) - step]
-
- step += batch_size
-
- return logits_concat
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("qa_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
-
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
-
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- # Evaluation
- logger.info("***** Running Evaluation *****")
- logger.info(f" Num examples = {len(eval_dataset)}")
- logger.info(f" Batch size = {args.per_device_eval_batch_size}")
-
- all_start_logits = []
- all_end_logits = []
-
- model.eval()
-
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- start_logits = outputs.start_logits
- end_logits = outputs.end_logits
-
- if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
- start_logits = accelerator.pad_across_processes(start_logits, dim=1, pad_index=-100)
- end_logits = accelerator.pad_across_processes(end_logits, dim=1, pad_index=-100)
-
- all_start_logits.append(accelerator.gather_for_metrics(start_logits).cpu().numpy())
- all_end_logits.append(accelerator.gather_for_metrics(end_logits).cpu().numpy())
-
- max_len = max(x.shape[1] for x in all_start_logits) # Get the max_length of the tensor
-
- # concatenate the numpy array
- start_logits_concat = create_and_fill_np_array(all_start_logits, eval_dataset, max_len)
- end_logits_concat = create_and_fill_np_array(all_end_logits, eval_dataset, max_len)
-
- # delete the list of numpy arrays
- del all_start_logits
- del all_end_logits
-
- outputs_numpy = (start_logits_concat, end_logits_concat)
- prediction = post_processing_function(eval_examples, eval_dataset, outputs_numpy)
- eval_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
- logger.info(f"Evaluation metrics: {eval_metric}")
-
- # Prediction
- if args.do_predict:
- logger.info("***** Running Prediction *****")
- logger.info(f" Num examples = {len(predict_dataset)}")
- logger.info(f" Batch size = {args.per_device_eval_batch_size}")
-
- all_start_logits = []
- all_end_logits = []
-
- model.eval()
-
- for step, batch in enumerate(predict_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- start_logits = outputs.start_logits
- end_logits = outputs.end_logits
-
- if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
- start_logits = accelerator.pad_across_processes(start_logits, dim=1, pad_index=-100)
- end_logits = accelerator.pad_across_processes(end_logits, dim=1, pad_index=-100)
-
- all_start_logits.append(accelerator.gather_for_metrics(start_logits).cpu().numpy())
- all_end_logits.append(accelerator.gather_for_metrics(end_logits).cpu().numpy())
-
- max_len = max(x.shape[1] for x in all_start_logits) # Get the max_length of the tensor
- # concatenate the numpy array
- start_logits_concat = create_and_fill_np_array(all_start_logits, predict_dataset, max_len)
- end_logits_concat = create_and_fill_np_array(all_end_logits, predict_dataset, max_len)
-
- # delete the list of numpy arrays
- del all_start_logits
- del all_end_logits
-
- outputs_numpy = (start_logits_concat, end_logits_concat)
- prediction = post_processing_function(predict_examples, predict_dataset, outputs_numpy)
- predict_metric = metric.compute(predictions=prediction.predictions, references=prediction.label_ids)
- logger.info(f"Predict metrics: {predict_metric}")
-
- if args.with_tracking:
- log = {
- "squad_v2" if args.version_2_with_negative else "squad": eval_metric,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- }
- if args.do_predict:
- log["squad_v2_predict" if args.version_2_with_negative else "squad_predict"] = predict_metric
-
- accelerator.log(log, step=completed_steps)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- logger.info(json.dumps(eval_metric, indent=4))
- save_prefixed_metrics(eval_metric, args.output_dir)
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/question-answering/run_seq2seq_qa.py b/examples/pytorch/question-answering/run_seq2seq_qa.py
deleted file mode 100644
index f220e8eaa2dc..000000000000
--- a/examples/pytorch/question-answering/run_seq2seq_qa.py
+++ /dev/null
@@ -1,722 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Fine-tuning the library's seq2seq models for question answering using the 🤗 Seq2SeqTrainer.
-"""
-# You can also adapt this script on your own question answering task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import load_dataset
-from trainer_seq2seq_qa import QuestionAnsweringSeq2SeqTrainer
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSeq2SeqLM,
- AutoTokenizer,
- DataCollatorForSeq2Seq,
- HfArgumentParser,
- Seq2SeqTrainingArguments,
- set_seed,
-)
-from transformers.trainer_utils import EvalLoopOutput, EvalPrediction
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/question-answering/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Path to directory to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- context_column: str | None = field(
- default="context",
- metadata={"help": "The name of the column in the datasets containing the contexts (for question answering)."},
- )
- question_column: str | None = field(
- default="question",
- metadata={"help": "The name of the column in the datasets containing the questions (for question answering)."},
- )
- answer_column: str | None = field(
- default="answers",
- metadata={"help": "The name of the column in the datasets containing the answers (for question answering)."},
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a text file)."})
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate the perplexity on (a text file)."},
- )
- test_file: str | None = field(
- default=None,
- metadata={"help": "An optional input test data file to evaluate the perplexity on (a text file)."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_seq_length: int = field(
- default=384,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- max_answer_length: int = field(
- default=30,
- metadata={
- "help": (
- "The maximum length of an answer that can be generated. This is needed because the start "
- "and end predictions are not conditioned on one another."
- )
- },
- )
- val_max_answer_length: int | None = field(
- default=None,
- metadata={
- "help": (
- "The maximum total sequence length for validation target text after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded. Will default to `max_answer_length`. "
- "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
- "during ``evaluate`` and ``predict``."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. If False, will pad the samples dynamically when"
- " batching to the maximum length in the batch (which can be faster on GPU but will be slower on TPU)."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- version_2_with_negative: bool = field(
- default=False, metadata={"help": "If true, some of the examples do not have an answer."}
- )
- null_score_diff_threshold: float = field(
- default=0.0,
- metadata={
- "help": (
- "The threshold used to select the null answer: if the best answer has a score that is less than "
- "the score of the null answer minus this threshold, the null answer is selected for this example. "
- "Only useful when `version_2_with_negative=True`."
- )
- },
- )
- doc_stride: int = field(
- default=128,
- metadata={"help": "When splitting up a long document into chunks, how much stride to take between chunks."},
- )
- n_best_size: int = field(
- default=20,
- metadata={"help": "The total number of n-best predictions to generate when looking for an answer."},
- )
- num_beams: int | None = field(
- default=None,
- metadata={
- "help": (
- "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
- "which is used during ``evaluate`` and ``predict``."
- )
- },
- )
- ignore_pad_token_for_loss: bool = field(
- default=True,
- metadata={
- "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
- },
- )
-
- def __post_init__(self):
- if (
- self.dataset_name is None
- and self.train_file is None
- and self.validation_file is None
- and self.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training/validation file/test_file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if self.test_file is not None:
- extension = self.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
- if self.val_max_answer_length is None:
- self.val_max_answer_length = self.max_answer_length
-
-
-question_answering_column_name_mapping = {
- "squad_v2": ("question", "context", "answer"),
-}
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- field="data",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSeq2SeqLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- # Preprocessing the datasets.
- # We need to generate and tokenize inputs and targets.
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- elif training_args.do_eval:
- column_names = raw_datasets["validation"].column_names
- elif training_args.do_predict:
- column_names = raw_datasets["test"].column_names
- else:
- logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
- return
-
- # Get the column names for input/target.
- dataset_columns = question_answering_column_name_mapping.get(data_args.dataset_name)
- if data_args.question_column is None:
- question_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
- else:
- question_column = data_args.question_column
- if question_column not in column_names:
- raise ValueError(
- f"--question_column' value '{data_args.question_column}' needs to be one of: {', '.join(column_names)}"
- )
- if data_args.context_column is None:
- context_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
- else:
- context_column = data_args.context_column
- if context_column not in column_names:
- raise ValueError(
- f"--context_column' value '{data_args.context_column}' needs to be one of: {', '.join(column_names)}"
- )
- if data_args.answer_column is None:
- answer_column = dataset_columns[2] if dataset_columns is not None else column_names[2]
- else:
- answer_column = data_args.answer_column
- if answer_column not in column_names:
- raise ValueError(
- f"--answer_column' value '{data_args.answer_column}' needs to be one of: {', '.join(column_names)}"
- )
-
- # Temporarily set max_answer_length for training.
- max_answer_length = data_args.max_answer_length
- padding = "max_length" if data_args.pad_to_max_length else False
-
- if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
- logger.warning(
- "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
- f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
- )
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- def preprocess_squad_batch(
- examples,
- question_column: str,
- context_column: str,
- answer_column: str,
- ) -> tuple[list[str], list[str]]:
- questions = examples[question_column]
- contexts = examples[context_column]
- answers = examples[answer_column]
-
- def generate_input(_question, _context):
- return " ".join(["question:", _question.lstrip(), "context:", _context.lstrip()])
-
- inputs = [generate_input(question, context) for question, context in zip(questions, contexts)]
- targets = [answer["text"][0] if len(answer["text"]) > 0 else "" for answer in answers]
- return inputs, targets
-
- def preprocess_function(examples):
- inputs, targets = preprocess_squad_batch(examples, question_column, context_column, answer_column)
-
- model_inputs = tokenizer(inputs, max_length=max_seq_length, padding=padding, truncation=True)
- # Tokenize targets with text_target=...
- labels = tokenizer(text_target=targets, max_length=max_answer_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and data_args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- model_inputs["labels"] = labels["input_ids"]
- return model_inputs
-
- # Validation preprocessing
- def preprocess_validation_function(examples):
- inputs, targets = preprocess_squad_batch(examples, question_column, context_column, answer_column)
-
- model_inputs = tokenizer(
- inputs,
- max_length=max_seq_length,
- padding=padding,
- truncation=True,
- return_overflowing_tokens=True,
- return_offsets_mapping=True,
- )
- # Tokenize targets with the `text_target` keyword argument
- labels = tokenizer(text_target=targets, max_length=max_answer_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and data_args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- # Since one example might give us several features if it has a long context, we need a map from a feature to
- # its corresponding example. This key gives us just that.
- sample_mapping = model_inputs.pop("overflow_to_sample_mapping")
-
- # For evaluation, we will need to convert our predictions to substrings of the context, so we keep the
- # corresponding example_id and we will store the offset mappings.
- model_inputs["example_id"] = []
- # Augment the overflowing tokens to the labels
- labels_out = []
-
- for i in range(len(model_inputs["input_ids"])):
- # One example can give several spans, this is the index of the example containing this span of text.
- sample_index = sample_mapping[i]
- model_inputs["example_id"].append(examples["id"][sample_index])
- labels_out.append(labels["input_ids"][sample_index])
-
- model_inputs["labels"] = labels_out
- return model_inputs
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- # We will select sample from whole data if argument is specified
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- # Create train feature from dataset
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- if data_args.max_train_samples is not None:
- # Number of samples might increase during Feature Creation, We select only specified max samples
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_examples = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- # We will select sample from whole data
- max_eval_samples = min(len(eval_examples), data_args.max_eval_samples)
- eval_examples = eval_examples.select(range(max_eval_samples))
- # Validation Feature Creation
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_examples.map(
- preprocess_validation_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
- if data_args.max_eval_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- if training_args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_examples = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- # We will select sample from whole data
- predict_examples = predict_examples.select(range(data_args.max_predict_samples))
- # Predict Feature Creation
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_examples.map(
- preprocess_validation_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
- if data_args.max_predict_samples is not None:
- # During Feature creation dataset samples might increase, we will select required samples again
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
-
- # Data collator
- label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
- data_collator = DataCollatorForSeq2Seq(
- tokenizer,
- model=model,
- label_pad_token_id=label_pad_token_id,
- pad_to_multiple_of=8 if training_args.fp16 else None,
- )
-
- metric = evaluate.load(
- "squad_v2" if data_args.version_2_with_negative else "squad", cache_dir=model_args.cache_dir
- )
-
- def compute_metrics(p: EvalPrediction):
- return metric.compute(predictions=p.predictions, references=p.label_ids)
-
- # Post-processing:
- def post_processing_function(
- examples: datasets.Dataset, features: datasets.Dataset, outputs: EvalLoopOutput, stage="eval"
- ):
- # Decode the predicted tokens.
- preds = outputs.predictions
- if isinstance(preds, tuple):
- preds = preds[0]
- # Replace -100s used for padding as we can't decode them
- preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
- decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
-
- # Build a map example to its corresponding features.
- example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
- feature_per_example = {example_id_to_index[feature["example_id"]]: i for i, feature in enumerate(features)}
- predictions = {}
- # Let's loop over all the examples!
- for example_index, example in enumerate(examples):
- # This is the index of the feature associated to the current example.
- feature_index = feature_per_example[example_index]
- predictions[example["id"]] = decoded_preds[feature_index]
-
- # Format the result to the format the metric expects.
- if data_args.version_2_with_negative:
- formatted_predictions = [
- {"id": k, "prediction_text": v, "no_answer_probability": 0.0} for k, v in predictions.items()
- ]
- else:
- formatted_predictions = [{"id": k, "prediction_text": v} for k, v in predictions.items()]
-
- references = [{"id": ex["id"], "answers": ex[answer_column]} for ex in examples]
- return EvalPrediction(predictions=formatted_predictions, label_ids=references)
-
- # Initialize our Trainer
- trainer = QuestionAnsweringSeq2SeqTrainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- eval_examples=eval_examples if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics if training_args.predict_with_generate else None,
- post_process_function=post_processing_function,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- results = {}
- max_length = (
- training_args.generation_max_length
- if training_args.generation_max_length is not None
- else data_args.val_max_answer_length
- )
- num_beams = data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate(max_length=max_length, num_beams=num_beams, metric_key_prefix="eval")
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Prediction
- if training_args.do_predict:
- logger.info("*** Predict ***")
- results = trainer.predict(predict_dataset, predict_examples)
- metrics = results.metrics
-
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- if training_args.push_to_hub:
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "question-answering"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- trainer.push_to_hub(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/question-answering/trainer_qa.py b/examples/pytorch/question-answering/trainer_qa.py
deleted file mode 100644
index de6a1d76734c..000000000000
--- a/examples/pytorch/question-answering/trainer_qa.py
+++ /dev/null
@@ -1,130 +0,0 @@
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-A subclass of `Trainer` specific to Question-Answering tasks
-"""
-
-import math
-import time
-
-from transformers import Trainer, is_torch_xla_available
-from transformers.trainer_utils import PredictionOutput, speed_metrics
-
-
-if is_torch_xla_available():
- import torch_xla.core.xla_model as xm
- import torch_xla.debug.metrics as met
-
-
-class QuestionAnsweringTrainer(Trainer):
- def __init__(self, *args, eval_examples=None, post_process_function=None, **kwargs):
- super().__init__(*args, **kwargs)
- self.eval_examples = eval_examples
- self.post_process_function = post_process_function
-
- def evaluate(self, eval_dataset=None, eval_examples=None, ignore_keys=None, metric_key_prefix: str = "eval"):
- eval_dataset = self.eval_dataset if eval_dataset is None else eval_dataset
- eval_dataloader = self.get_eval_dataloader(eval_dataset)
- eval_examples = self.eval_examples if eval_examples is None else eval_examples
-
- # Temporarily disable metric computation, we will do it in the loop here.
- compute_metrics = self.compute_metrics
- self.compute_metrics = None
- start_time = time.time()
- try:
- output = self.evaluation_loop(
- eval_dataloader,
- description="Evaluation",
- # No point gathering the predictions if there are no metrics, otherwise we defer to
- # self.args.prediction_loss_only
- prediction_loss_only=True if compute_metrics is None else None,
- ignore_keys=ignore_keys,
- metric_key_prefix=metric_key_prefix,
- )
- finally:
- self.compute_metrics = compute_metrics
- total_batch_size = self.args.eval_batch_size * self.args.world_size
- output.metrics.update(
- speed_metrics(
- metric_key_prefix,
- start_time,
- num_samples=output.num_samples,
- num_steps=math.ceil(output.num_samples / total_batch_size),
- )
- )
- if self.post_process_function is not None and self.compute_metrics is not None and self.args.should_save:
- # Only the main node write the results by default
- eval_preds = self.post_process_function(eval_examples, eval_dataset, output.predictions)
- metrics = self.compute_metrics(eval_preds)
-
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(metrics.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
- metrics.update(output.metrics)
- else:
- metrics = output.metrics
-
- if self.args.should_log:
- # Only the main node log the results by default
- self.log(metrics)
-
- if self.args.debug:
- # tpu-comment: Logging debug metrics for PyTorch/XLA (compile, execute times, ops, etc.)
- xm.master_print(met.metrics_report())
-
- self.control = self.callback_handler.on_evaluate(self.args, self.state, self.control, metrics)
- return metrics
-
- def predict(self, predict_dataset, predict_examples, ignore_keys=None, metric_key_prefix: str = "test"):
- predict_dataloader = self.get_test_dataloader(predict_dataset)
-
- # Temporarily disable metric computation, we will do it in the loop here.
- compute_metrics = self.compute_metrics
- self.compute_metrics = None
- start_time = time.time()
- try:
- output = self.evaluation_loop(
- predict_dataloader,
- description="Prediction",
- # No point gathering the predictions if there are no metrics, otherwise we defer to
- # self.args.prediction_loss_only
- prediction_loss_only=True if compute_metrics is None else None,
- ignore_keys=ignore_keys,
- metric_key_prefix=metric_key_prefix,
- )
- finally:
- self.compute_metrics = compute_metrics
- total_batch_size = self.args.eval_batch_size * self.args.world_size
- output.metrics.update(
- speed_metrics(
- metric_key_prefix,
- start_time,
- num_samples=output.num_samples,
- num_steps=math.ceil(output.num_samples / total_batch_size),
- )
- )
-
- if self.post_process_function is None or self.compute_metrics is None:
- return output
-
- predictions = self.post_process_function(predict_examples, predict_dataset, output.predictions, "predict")
- metrics = self.compute_metrics(predictions)
-
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(metrics.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
- metrics.update(output.metrics)
- return PredictionOutput(predictions=predictions.predictions, label_ids=predictions.label_ids, metrics=metrics)
diff --git a/examples/pytorch/question-answering/trainer_seq2seq_qa.py b/examples/pytorch/question-answering/trainer_seq2seq_qa.py
deleted file mode 100644
index 8de1fa009479..000000000000
--- a/examples/pytorch/question-answering/trainer_seq2seq_qa.py
+++ /dev/null
@@ -1,156 +0,0 @@
-# Copyright 2021 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-A subclass of `Trainer` specific to Question-Answering tasks
-"""
-
-import math
-import time
-
-from torch.utils.data import Dataset
-
-from transformers import Seq2SeqTrainer, is_torch_xla_available
-from transformers.trainer_utils import PredictionOutput, speed_metrics
-
-
-if is_torch_xla_available():
- import torch_xla.core.xla_model as xm
- import torch_xla.debug.metrics as met
-
-
-class QuestionAnsweringSeq2SeqTrainer(Seq2SeqTrainer):
- def __init__(self, *args, eval_examples=None, post_process_function=None, **kwargs):
- super().__init__(*args, **kwargs)
- self.eval_examples = eval_examples
- self.post_process_function = post_process_function
-
- # def evaluate(self, eval_dataset=None, eval_examples=None, ignore_keys=None, metric_key_prefix: str = "eval"):
- def evaluate(
- self,
- eval_dataset: Dataset | None = None,
- eval_examples=None,
- ignore_keys: list[str] | None = None,
- metric_key_prefix: str = "eval",
- **gen_kwargs,
- ) -> dict[str, float]:
- gen_kwargs = gen_kwargs.copy()
-
- # Use legacy argument setting if a) the option is not explicitly passed; and b) the argument is set in the
- # training args
- if gen_kwargs.get("max_length") is None and self.args.generation_max_length is not None:
- gen_kwargs["max_length"] = self.args.generation_max_length
- if gen_kwargs.get("num_beams") is None and self.args.generation_num_beams is not None:
- gen_kwargs["num_beams"] = self.args.generation_num_beams
- self._gen_kwargs = gen_kwargs
-
- eval_dataset = self.eval_dataset if eval_dataset is None else eval_dataset
- eval_dataloader = self.get_eval_dataloader(eval_dataset)
- eval_examples = self.eval_examples if eval_examples is None else eval_examples
-
- # Temporarily disable metric computation, we will do it in the loop here.
- compute_metrics = self.compute_metrics
- self.compute_metrics = None
- start_time = time.time()
- try:
- output = self.evaluation_loop(
- eval_dataloader,
- description="Evaluation",
- # No point gathering the predictions if there are no metrics, otherwise we defer to
- # self.args.prediction_loss_only
- prediction_loss_only=True if compute_metrics is None else None,
- ignore_keys=ignore_keys,
- metric_key_prefix=metric_key_prefix,
- )
- finally:
- self.compute_metrics = compute_metrics
- total_batch_size = self.args.eval_batch_size * self.args.world_size
- output.metrics.update(
- speed_metrics(
- metric_key_prefix,
- start_time,
- num_samples=output.num_samples,
- num_steps=math.ceil(output.num_samples / total_batch_size),
- )
- )
-
- if self.post_process_function is not None and self.compute_metrics is not None and self.args.should_save:
- # Only the main node write the results by default
- eval_preds = self.post_process_function(eval_examples, eval_dataset, output)
- metrics = self.compute_metrics(eval_preds)
-
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(metrics.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
-
- metrics.update(output.metrics)
- else:
- metrics = output.metrics
-
- if self.args.should_log:
- # Only the main node log the results by default
- self.log(metrics)
-
- if self.args.debug:
- # tpu-comment: Logging debug metrics for PyTorch/XLA (compile, execute times, ops, etc.)
- xm.master_print(met.metrics_report())
-
- self.control = self.callback_handler.on_evaluate(self.args, self.state, self.control, metrics)
- return metrics
-
- def predict(
- self, predict_dataset, predict_examples, ignore_keys=None, metric_key_prefix: str = "test", **gen_kwargs
- ):
- self._gen_kwargs = gen_kwargs.copy()
-
- predict_dataloader = self.get_test_dataloader(predict_dataset)
-
- # Temporarily disable metric computation, we will do it in the loop here.
- compute_metrics = self.compute_metrics
- self.compute_metrics = None
- start_time = time.time()
- try:
- output = self.evaluation_loop(
- predict_dataloader,
- description="Prediction",
- # No point gathering the predictions if there are no metrics, otherwise we defer to
- # self.args.prediction_loss_only
- prediction_loss_only=True if compute_metrics is None else None,
- ignore_keys=ignore_keys,
- metric_key_prefix=metric_key_prefix,
- )
- finally:
- self.compute_metrics = compute_metrics
-
- total_batch_size = self.args.eval_batch_size * self.args.world_size
- output.metrics.update(
- speed_metrics(
- metric_key_prefix,
- start_time,
- num_samples=output.num_samples,
- num_steps=math.ceil(output.num_samples / total_batch_size),
- )
- )
- if self.post_process_function is None or self.compute_metrics is None:
- return output
-
- predictions = self.post_process_function(predict_examples, predict_dataset, output, "predict")
- metrics = self.compute_metrics(predictions)
-
- # Prefix all keys with metric_key_prefix + '_'
- for key in list(metrics.keys()):
- if not key.startswith(f"{metric_key_prefix}_"):
- metrics[f"{metric_key_prefix}_{key}"] = metrics.pop(key)
- metrics.update(output.metrics)
- return PredictionOutput(predictions=predictions.predictions, label_ids=predictions.label_ids, metrics=metrics)
diff --git a/examples/pytorch/question-answering/utils_qa.py b/examples/pytorch/question-answering/utils_qa.py
deleted file mode 100644
index 84a0b503da0c..000000000000
--- a/examples/pytorch/question-answering/utils_qa.py
+++ /dev/null
@@ -1,442 +0,0 @@
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-Post-processing utilities for question answering.
-"""
-
-import collections
-import json
-import logging
-import os
-
-import numpy as np
-from tqdm.auto import tqdm
-
-
-logger = logging.getLogger(__name__)
-
-
-def postprocess_qa_predictions(
- examples,
- features,
- predictions: tuple[np.ndarray, np.ndarray],
- version_2_with_negative: bool = False,
- n_best_size: int = 20,
- max_answer_length: int = 30,
- null_score_diff_threshold: float = 0.0,
- output_dir: str | None = None,
- prefix: str | None = None,
- log_level: int | None = logging.WARNING,
-):
- """
- Post-processes the predictions of a question-answering model to convert them to answers that are substrings of the
- original contexts. This is the base postprocessing functions for models that only return start and end logits.
-
- Args:
- examples: The non-preprocessed dataset (see the main script for more information).
- features: The processed dataset (see the main script for more information).
- predictions (:obj:`tuple[np.ndarray, np.ndarray]`):
- The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
- first dimension must match the number of elements of :obj:`features`.
- version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
- Whether or not the underlying dataset contains examples with no answers.
- n_best_size (:obj:`int`, `optional`, defaults to 20):
- The total number of n-best predictions to generate when looking for an answer.
- max_answer_length (:obj:`int`, `optional`, defaults to 30):
- The maximum length of an answer that can be generated. This is needed because the start and end predictions
- are not conditioned on one another.
- null_score_diff_threshold (:obj:`float`, `optional`, defaults to 0):
- The threshold used to select the null answer: if the best answer has a score that is less than the score of
- the null answer minus this threshold, the null answer is selected for this example (note that the score of
- the null answer for an example giving several features is the minimum of the scores for the null answer on
- each feature: all features must be aligned on the fact they `want` to predict a null answer).
-
- Only useful when :obj:`version_2_with_negative` is :obj:`True`.
- output_dir (:obj:`str`, `optional`):
- If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
- :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
- answers, are saved in `output_dir`.
- prefix (:obj:`str`, `optional`):
- If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
- log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
- ``logging`` log level (e.g., ``logging.WARNING``)
- """
- if len(predictions) != 2:
- raise ValueError("`predictions` should be a tuple with two elements (start_logits, end_logits).")
- all_start_logits, all_end_logits = predictions
-
- if len(predictions[0]) != len(features):
- raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
-
- # Build a map example to its corresponding features.
- example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
- features_per_example = collections.defaultdict(list)
- for i, feature in enumerate(features):
- features_per_example[example_id_to_index[feature["example_id"]]].append(i)
-
- # The dictionaries we have to fill.
- all_predictions = collections.OrderedDict()
- all_nbest_json = collections.OrderedDict()
- if version_2_with_negative:
- scores_diff_json = collections.OrderedDict()
-
- # Logging.
- logger.setLevel(log_level)
- logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
-
- # Let's loop over all the examples!
- for example_index, example in enumerate(tqdm(examples)):
- # Those are the indices of the features associated to the current example.
- feature_indices = features_per_example[example_index]
-
- min_null_prediction = None
- prelim_predictions = []
-
- # Looping through all the features associated to the current example.
- for feature_index in feature_indices:
- # We grab the predictions of the model for this feature.
- start_logits = all_start_logits[feature_index]
- end_logits = all_end_logits[feature_index]
- # This is what will allow us to map some the positions in our logits to span of texts in the original
- # context.
- offset_mapping = features[feature_index]["offset_mapping"]
- # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
- # available in the current feature.
- token_is_max_context = features[feature_index].get("token_is_max_context", None)
-
- # Update minimum null prediction.
- feature_null_score = start_logits[0] + end_logits[0]
- if min_null_prediction is None or min_null_prediction["score"] > feature_null_score:
- min_null_prediction = {
- "offsets": (0, 0),
- "score": feature_null_score,
- "start_logit": start_logits[0],
- "end_logit": end_logits[0],
- }
-
- # Go through all possibilities for the `n_best_size` greater start and end logits.
- start_indexes = np.argsort(start_logits)[-1 : -n_best_size - 1 : -1].tolist()
- end_indexes = np.argsort(end_logits)[-1 : -n_best_size - 1 : -1].tolist()
- for start_index in start_indexes:
- for end_index in end_indexes:
- # Don't consider out-of-scope answers, either because the indices are out of bounds or correspond
- # to part of the input_ids that are not in the context.
- if (
- start_index >= len(offset_mapping)
- or end_index >= len(offset_mapping)
- or offset_mapping[start_index] is None
- or len(offset_mapping[start_index]) < 2
- or offset_mapping[end_index] is None
- or len(offset_mapping[end_index]) < 2
- ):
- continue
- # Don't consider answers with a length that is either < 0 or > max_answer_length.
- if end_index < start_index or end_index - start_index + 1 > max_answer_length:
- continue
- # Don't consider answer that don't have the maximum context available (if such information is
- # provided).
- if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
- continue
-
- prelim_predictions.append(
- {
- "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
- "score": start_logits[start_index] + end_logits[end_index],
- "start_logit": start_logits[start_index],
- "end_logit": end_logits[end_index],
- }
- )
- if version_2_with_negative and min_null_prediction is not None:
- # Add the minimum null prediction
- prelim_predictions.append(min_null_prediction)
- null_score = min_null_prediction["score"]
-
- # Only keep the best `n_best_size` predictions.
- predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
-
- # Add back the minimum null prediction if it was removed because of its low score.
- if (
- version_2_with_negative
- and min_null_prediction is not None
- and not any(p["offsets"] == (0, 0) for p in predictions)
- ):
- predictions.append(min_null_prediction)
-
- # Use the offsets to gather the answer text in the original context.
- context = example["context"]
- for pred in predictions:
- offsets = pred.pop("offsets")
- pred["text"] = context[offsets[0] : offsets[1]]
-
- # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
- # failure.
- if len(predictions) == 0 or (len(predictions) == 1 and predictions[0]["text"] == ""):
- predictions.insert(0, {"text": "empty", "start_logit": 0.0, "end_logit": 0.0, "score": 0.0})
-
- # Compute the softmax of all scores (we do it with numpy to stay independent from torch in this file, using
- # the LogSumExp trick).
- scores = np.array([pred.pop("score") for pred in predictions])
- exp_scores = np.exp(scores - np.max(scores))
- probs = exp_scores / exp_scores.sum()
-
- # Include the probabilities in our predictions.
- for prob, pred in zip(probs, predictions):
- pred["probability"] = prob
-
- # Pick the best prediction. If the null answer is not possible, this is easy.
- if not version_2_with_negative:
- all_predictions[example["id"]] = predictions[0]["text"]
- else:
- # Otherwise we first need to find the best non-empty prediction.
- i = 0
- while predictions[i]["text"] == "":
- i += 1
- best_non_null_pred = predictions[i]
-
- # Then we compare to the null prediction using the threshold.
- score_diff = null_score - best_non_null_pred["start_logit"] - best_non_null_pred["end_logit"]
- scores_diff_json[example["id"]] = float(score_diff) # To be JSON-serializable.
- if score_diff > null_score_diff_threshold:
- all_predictions[example["id"]] = ""
- else:
- all_predictions[example["id"]] = best_non_null_pred["text"]
-
- # Make `predictions` JSON-serializable by casting np.float back to float.
- all_nbest_json[example["id"]] = [
- {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
- for pred in predictions
- ]
-
- # If we have an output_dir, let's save all those dicts.
- if output_dir is not None:
- if not os.path.isdir(output_dir):
- raise OSError(f"{output_dir} is not a directory.")
-
- prediction_file = os.path.join(
- output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
- )
- nbest_file = os.path.join(
- output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
- )
- if version_2_with_negative:
- null_odds_file = os.path.join(
- output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
- )
-
- logger.info(f"Saving predictions to {prediction_file}.")
- with open(prediction_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(all_predictions, indent=4) + "\n")
- logger.info(f"Saving nbest_preds to {nbest_file}.")
- with open(nbest_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
- if version_2_with_negative:
- logger.info(f"Saving null_odds to {null_odds_file}.")
- with open(null_odds_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
-
- return all_predictions
-
-
-def postprocess_qa_predictions_with_beam_search(
- examples,
- features,
- predictions: tuple[np.ndarray, np.ndarray],
- version_2_with_negative: bool = False,
- n_best_size: int = 20,
- max_answer_length: int = 30,
- start_n_top: int = 5,
- end_n_top: int = 5,
- output_dir: str | None = None,
- prefix: str | None = None,
- log_level: int | None = logging.WARNING,
-):
- """
- Post-processes the predictions of a question-answering model with beam search to convert them to answers that are substrings of the
- original contexts. This is the postprocessing functions for models that return start and end logits, indices, as well as
- cls token predictions.
-
- Args:
- examples: The non-preprocessed dataset (see the main script for more information).
- features: The processed dataset (see the main script for more information).
- predictions (:obj:`tuple[np.ndarray, np.ndarray]`):
- The predictions of the model: two arrays containing the start logits and the end logits respectively. Its
- first dimension must match the number of elements of :obj:`features`.
- version_2_with_negative (:obj:`bool`, `optional`, defaults to :obj:`False`):
- Whether or not the underlying dataset contains examples with no answers.
- n_best_size (:obj:`int`, `optional`, defaults to 20):
- The total number of n-best predictions to generate when looking for an answer.
- max_answer_length (:obj:`int`, `optional`, defaults to 30):
- The maximum length of an answer that can be generated. This is needed because the start and end predictions
- are not conditioned on one another.
- start_n_top (:obj:`int`, `optional`, defaults to 5):
- The number of top start logits too keep when searching for the :obj:`n_best_size` predictions.
- end_n_top (:obj:`int`, `optional`, defaults to 5):
- The number of top end logits too keep when searching for the :obj:`n_best_size` predictions.
- output_dir (:obj:`str`, `optional`):
- If provided, the dictionaries of predictions, n_best predictions (with their scores and logits) and, if
- :obj:`version_2_with_negative=True`, the dictionary of the scores differences between best and null
- answers, are saved in `output_dir`.
- prefix (:obj:`str`, `optional`):
- If provided, the dictionaries mentioned above are saved with `prefix` added to their names.
- log_level (:obj:`int`, `optional`, defaults to ``logging.WARNING``):
- ``logging`` log level (e.g., ``logging.WARNING``)
- """
- if len(predictions) != 5:
- raise ValueError("`predictions` should be a tuple with five elements.")
- start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits = predictions
-
- if len(predictions[0]) != len(features):
- raise ValueError(f"Got {len(predictions[0])} predictions and {len(features)} features.")
-
- # Build a map example to its corresponding features.
- example_id_to_index = {k: i for i, k in enumerate(examples["id"])}
- features_per_example = collections.defaultdict(list)
- for i, feature in enumerate(features):
- features_per_example[example_id_to_index[feature["example_id"]]].append(i)
-
- # The dictionaries we have to fill.
- all_predictions = collections.OrderedDict()
- all_nbest_json = collections.OrderedDict()
- scores_diff_json = collections.OrderedDict() if version_2_with_negative else None
-
- # Logging.
- logger.setLevel(log_level)
- logger.info(f"Post-processing {len(examples)} example predictions split into {len(features)} features.")
-
- # Let's loop over all the examples!
- for example_index, example in enumerate(tqdm(examples)):
- # Those are the indices of the features associated to the current example.
- feature_indices = features_per_example[example_index]
-
- min_null_score = None
- prelim_predictions = []
-
- # Looping through all the features associated to the current example.
- for feature_index in feature_indices:
- # We grab the predictions of the model for this feature.
- start_log_prob = start_top_log_probs[feature_index]
- start_indexes = start_top_index[feature_index]
- end_log_prob = end_top_log_probs[feature_index]
- end_indexes = end_top_index[feature_index]
- feature_null_score = cls_logits[feature_index]
- # This is what will allow us to map some the positions in our logits to span of texts in the original
- # context.
- offset_mapping = features[feature_index]["offset_mapping"]
- # Optional `token_is_max_context`, if provided we will remove answers that do not have the maximum context
- # available in the current feature.
- token_is_max_context = features[feature_index].get("token_is_max_context", None)
-
- # Update minimum null prediction
- if min_null_score is None or feature_null_score < min_null_score:
- min_null_score = feature_null_score
-
- # Go through all possibilities for the `n_start_top`/`n_end_top` greater start and end logits.
- for i in range(start_n_top):
- for j in range(end_n_top):
- start_index = int(start_indexes[i])
- j_index = i * end_n_top + j
- end_index = int(end_indexes[j_index])
- # Don't consider out-of-scope answers (last part of the test should be unnecessary because of the
- # p_mask but let's not take any risk)
- if (
- start_index >= len(offset_mapping)
- or end_index >= len(offset_mapping)
- or offset_mapping[start_index] is None
- or len(offset_mapping[start_index]) < 2
- or offset_mapping[end_index] is None
- or len(offset_mapping[end_index]) < 2
- ):
- continue
-
- # Don't consider answers with a length negative or > max_answer_length.
- if end_index < start_index or end_index - start_index + 1 > max_answer_length:
- continue
- # Don't consider answer that don't have the maximum context available (if such information is
- # provided).
- if token_is_max_context is not None and not token_is_max_context.get(str(start_index), False):
- continue
- prelim_predictions.append(
- {
- "offsets": (offset_mapping[start_index][0], offset_mapping[end_index][1]),
- "score": start_log_prob[i] + end_log_prob[j_index],
- "start_log_prob": start_log_prob[i],
- "end_log_prob": end_log_prob[j_index],
- }
- )
-
- # Only keep the best `n_best_size` predictions.
- predictions = sorted(prelim_predictions, key=lambda x: x["score"], reverse=True)[:n_best_size]
-
- # Use the offsets to gather the answer text in the original context.
- context = example["context"]
- for pred in predictions:
- offsets = pred.pop("offsets")
- pred["text"] = context[offsets[0] : offsets[1]]
-
- # In the very rare edge case we have not a single non-null prediction, we create a fake prediction to avoid
- # failure.
- if len(predictions) == 0:
- # Without predictions min_null_score is going to be None and None will cause an exception later
- min_null_score = -2e-6
- predictions.insert(0, {"text": "", "start_logit": -1e-6, "end_logit": -1e-6, "score": min_null_score})
-
- # Compute the softmax of all scores (we do it with numpy to stay independent from torch in this file, using
- # the LogSumExp trick).
- scores = np.array([pred.pop("score") for pred in predictions])
- exp_scores = np.exp(scores - np.max(scores))
- probs = exp_scores / exp_scores.sum()
-
- # Include the probabilities in our predictions.
- for prob, pred in zip(probs, predictions):
- pred["probability"] = prob
-
- # Pick the best prediction and set the probability for the null answer.
- all_predictions[example["id"]] = predictions[0]["text"]
- if version_2_with_negative:
- scores_diff_json[example["id"]] = float(min_null_score)
-
- # Make `predictions` JSON-serializable by casting np.float back to float.
- all_nbest_json[example["id"]] = [
- {k: (float(v) if isinstance(v, (np.float16, np.float32, np.float64)) else v) for k, v in pred.items()}
- for pred in predictions
- ]
-
- # If we have an output_dir, let's save all those dicts.
- if output_dir is not None:
- if not os.path.isdir(output_dir):
- raise OSError(f"{output_dir} is not a directory.")
-
- prediction_file = os.path.join(
- output_dir, "predictions.json" if prefix is None else f"{prefix}_predictions.json"
- )
- nbest_file = os.path.join(
- output_dir, "nbest_predictions.json" if prefix is None else f"{prefix}_nbest_predictions.json"
- )
- if version_2_with_negative:
- null_odds_file = os.path.join(
- output_dir, "null_odds.json" if prefix is None else f"{prefix}_null_odds.json"
- )
-
- logger.info(f"Saving predictions to {prediction_file}.")
- with open(prediction_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(all_predictions, indent=4) + "\n")
- logger.info(f"Saving nbest_preds to {nbest_file}.")
- with open(nbest_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(all_nbest_json, indent=4) + "\n")
- if version_2_with_negative:
- logger.info(f"Saving null_odds to {null_odds_file}.")
- with open(null_odds_file, "w", encoding="utf-8") as writer:
- writer.write(json.dumps(scores_diff_json, indent=4) + "\n")
-
- return all_predictions, scores_diff_json
diff --git a/examples/pytorch/semantic-segmentation/README.md b/examples/pytorch/semantic-segmentation/README.md
deleted file mode 100644
index 5b53dd67bf37..000000000000
--- a/examples/pytorch/semantic-segmentation/README.md
+++ /dev/null
@@ -1,207 +0,0 @@
-
-
-# Semantic segmentation examples
-
-This directory contains 2 scripts that showcase how to fine-tune any model supported by the [`AutoModelForSemanticSegmentation` API](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForSemanticSegmentation) (such as [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer), [BEiT](https://huggingface.co/docs/transformers/main/en/model_doc/beit), [DPT](https://huggingface.co/docs/transformers/main/en/model_doc/dpt)) using PyTorch.
-
-
-
-Content:
-* [Note on custom data](#note-on-custom-data)
-* [PyTorch version, Trainer](#pytorch-version-trainer)
-* [PyTorch version, no Trainer](#pytorch-version-no-trainer)
-* [Reload and perform inference](#reload-and-perform-inference)
-* [Important notes](#important-notes)
-
-## Note on custom data
-
-In case you'd like to use the script with custom data, there are 2 things required: 1) creating a DatasetDict 2) creating an id2label mapping. Below, these are explained in more detail.
-
-### Creating a `DatasetDict`
-
-The script assumes that you have a `DatasetDict` with 2 columns, "image" and "label", both of type [Image](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Image). This can be created as follows:
-
-```python
-from datasets import Dataset, DatasetDict, Image
-
-# your images can of course have a different extension
-# semantic segmentation maps are typically stored in the png format
-image_paths_train = ["path/to/image_1.jpg/jpg", "path/to/image_2.jpg/jpg", ..., "path/to/image_n.jpg/jpg"]
-label_paths_train = ["path/to/annotation_1.png", "path/to/annotation_2.png", ..., "path/to/annotation_n.png"]
-
-# same for validation
-# image_paths_validation = [...]
-# label_paths_validation = [...]
-
-def create_dataset(image_paths, label_paths):
- dataset = Dataset.from_dict({"image": sorted(image_paths),
- "label": sorted(label_paths)})
- dataset = dataset.cast_column("image", Image())
- dataset = dataset.cast_column("label", Image())
-
- return dataset
-
-# step 1: create Dataset objects
-train_dataset = create_dataset(image_paths_train, label_paths_train)
-validation_dataset = create_dataset(image_paths_validation, label_paths_validation)
-
-# step 2: create DatasetDict
-dataset = DatasetDict({
- "train": train_dataset,
- "validation": validation_dataset,
- }
-)
-
-# step 3: push to hub (assumes you have ran the hf auth login command in a terminal/notebook)
-dataset.push_to_hub("name of repo on the hub")
-
-# optionally, you can push to a private repo on the hub
-# dataset.push_to_hub("name of repo on the hub", private=True)
-```
-
-An example of such a dataset can be seen at [nielsr/ade20k-demo](https://huggingface.co/datasets/nielsr/ade20k-demo).
-
-### Creating an id2label mapping
-
-Besides that, the script also assumes the existence of an `id2label.json` file in the repo, containing a mapping from integers to actual class names. An example of that can be seen [here](https://huggingface.co/datasets/nielsr/ade20k-demo/blob/main/id2label.json). This can be created in Python as follows:
-
-```python
-import json
-# simple example
-id2label = {0: 'cat', 1: 'dog'}
-with open('id2label.json', 'w') as fp:
- json.dump(id2label, fp)
-```
-
-You can easily upload this by clicking on "Add file" in the "Files and versions" tab of your repo on the hub.
-
-## PyTorch version, Trainer
-
-Based on the script [`run_semantic_segmentation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py).
-
-The script leverages the [🤗 Trainer API](https://huggingface.co/docs/transformers/main_classes/trainer) to automatically take care of the training for you, running on distributed environments right away.
-
-Here we show how to fine-tune a [SegFormer](https://huggingface.co/nvidia/mit-b0) model on the [segments/sidewalk-semantic](https://huggingface.co/datasets/segments/sidewalk-semantic) dataset:
-
-In order to use `segments/sidewalk-semantic`:
- - Log in to Hugging Face with `hf auth login` (token can be accessed [here](https://huggingface.co/settings/tokens)).
- - Accept terms of use for `sidewalk-semantic` on [dataset page](https://huggingface.co/datasets/segments/sidewalk-semantic).
-
-```bash
-python run_semantic_segmentation.py \
- --model_name_or_path nvidia/mit-b0 \
- --dataset_name segments/sidewalk-semantic \
- --output_dir ./segformer_outputs/ \
- --remove_unused_columns False \
- --do_train \
- --do_eval \
- --push_to_hub \
- --push_to_hub_model_id segformer-finetuned-sidewalk-10k-steps \
- --max_steps 10000 \
- --learning_rate 0.00006 \
- --lr_scheduler_type polynomial \
- --per_device_train_batch_size 8 \
- --per_device_eval_batch_size 8 \
- --logging_strategy steps \
- --logging_steps 100 \
- --eval_strategy epoch \
- --save_strategy epoch \
- --seed 1337
-```
-
-The resulting model can be seen here: https://huggingface.co/nielsr/segformer-finetuned-sidewalk-10k-steps. The corresponding Weights and Biases report [here](https://wandb.ai/nielsrogge/huggingface/reports/SegFormer-fine-tuning--VmlldzoxODY5NTQ2). Note that it's always advised to check the original paper to know the details regarding training hyperparameters. E.g. from the SegFormer paper:
-
-> We trained the models using AdamW optimizer for 160K iterations on ADE20K, Cityscapes, and 80K iterations on COCO-Stuff. (...) We used a batch size of 16 for ADE20K and COCO-Stuff, and a batch size of 8 for Cityscapes. The learning rate was set to an initial value of 0.00006 and then used a “poly” LR schedule with factor 1.0 by default.
-
-Note that you can replace the model and dataset by simply setting the `model_name_or_path` and `dataset_name` arguments respectively, with any model or dataset from the [hub](https://huggingface.co/). For an overview of all possible arguments, we refer to the [docs](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) of the `TrainingArguments`, which can be passed as flags.
-
-## PyTorch version, no Trainer
-
-Based on the script [`run_semantic_segmentation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py).
-
-The script leverages [🤗 `Accelerate`](https://github.com/huggingface/accelerate), which allows to write your own training loop in PyTorch, but have it run instantly on any (distributed) environment, including CPU, multi-CPU, GPU, multi-GPU and TPU. It also supports mixed precision.
-
-First, run:
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked regarding the environment on which you'd like to train. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_semantic_segmentation_no_trainer.py --output_dir segformer-finetuned-sidewalk --with_tracking --push_to_hub
-```
-
-and boom, you're training, possibly on multiple GPUs, logging everything to all trackers found in your environment (like Weights and Biases, Tensorboard) and regularly pushing your model to the hub (with the repo name being equal to `args.output_dir` at your HF username) 🤗
-
-With the default settings, the script fine-tunes a [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer) model on the [segments/sidewalk-semantic](https://huggingface.co/datasets/segments/sidewalk-semantic) dataset.
-
-The resulting model can be seen here: https://huggingface.co/nielsr/segformer-finetuned-sidewalk. Note that the script usually requires quite a few epochs to achieve great results, e.g. the SegFormer authors fine-tuned their model for 160k steps (batches) on [`scene_parse_150`](https://huggingface.co/datasets/merve/scene_parse_150).
-
-## Reload and perform inference
-
-This means that after training, you can easily load your trained model as follows:
-
-```python
-from transformers import AutoImageProcessor, AutoModelForSemanticSegmentation
-
-model_name = "name_of_repo_on_the_hub_or_path_to_local_folder"
-
-image_processor = AutoImageProcessor.from_pretrained(model_name)
-model = AutoModelForSemanticSegmentation.from_pretrained(model_name)
-```
-
-and perform inference as follows:
-
-```python
-from PIL import Image
-import requests
-import torch
-
-url = "http://images.cocodataset.org/val2017/000000039769.jpg"
-image = Image.open(requests.get(url, stream=True).raw)
-
-# prepare image for the model
-inputs = image_processor(images=image, return_tensors="pt")
-
-with torch.no_grad():
- outputs = model(**inputs)
- logits = outputs.logits
-
-# rescale logits to original image size
-logits = nn.functional.interpolate(outputs.logits.detach().cpu(),
- size=image.size[::-1], # (height, width)
- mode='bilinear',
- align_corners=False)
-
-predicted = logits.argmax(1)
-```
-
-For visualization of the segmentation maps, we refer to the [example notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SegFormer/Segformer_inference_notebook.ipynb).
-
-## Important notes
-
-Some datasets, like [`scene_parse_150`](https://huggingface.co/datasets/merve/scene_parse_150), contain a "background" label that is not part of the classes. The Scene Parse 150 dataset for instance contains labels between 0 and 150, with 0 being the background class, and 1 to 150 being actual class names (like "tree", "person", etc.). For these kind of datasets, one replaces the background label (0) by 255, which is the `ignore_index` of the PyTorch model's loss function, and reduces all labels by 1. This way, the `labels` are PyTorch tensors containing values between 0 and 149, and 255 for all background/padding.
-
-In case you're training on such a dataset, make sure to set the ``do_reduce_labels`` flag, which will take care of this.
diff --git a/examples/pytorch/semantic-segmentation/requirements.txt b/examples/pytorch/semantic-segmentation/requirements.txt
deleted file mode 100644
index 7d62aa141db3..000000000000
--- a/examples/pytorch/semantic-segmentation/requirements.txt
+++ /dev/null
@@ -1,6 +0,0 @@
-datasets >= 2.0.0
-torch >= 1.3
-accelerate
-evaluate
-Pillow
-albumentations >= 1.4.16
diff --git a/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py b/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py
deleted file mode 100644
index 69c2cb515c10..000000000000
--- a/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py
+++ /dev/null
@@ -1,421 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets >= 2.0.0",
-# "torch >= 1.3",
-# "accelerate",
-# "evaluate""
-# "Pillow",
-# "albumentations >= 1.4.16",
-# ]
-# ///
-
-import json
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-from functools import partial
-
-import albumentations as A
-import evaluate
-import numpy as np
-import torch
-from albumentations.pytorch import ToTensorV2
-from datasets import load_dataset
-from huggingface_hub import hf_hub_download
-from torch import nn
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoImageProcessor,
- AutoModelForSemanticSegmentation,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-""" Finetuning any 🤗 Transformers model supported by AutoModelForSemanticSegmentation for semantic segmentation leveraging the Trainer API."""
-
-logger = logging.getLogger(__name__)
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
-
-
-def reduce_labels_transform(labels: np.ndarray, **kwargs) -> np.ndarray:
- """Set `0` label as with value 255 and then reduce all other labels by 1.
-
- Example:
- Initial class labels: 0 - background; 1 - road; 2 - car;
- Transformed class labels: 255 - background; 0 - road; 1 - car;
-
- **kwargs are required to use this function with albumentations.
- """
- labels[labels == 0] = 255
- labels = labels - 1
- labels[labels == 254] = 255
- return labels
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- Using `HfArgumentParser` we can turn this class into argparse arguments to be able to specify
- them on the command line.
- """
-
- dataset_name: str | None = field(
- default="segments/sidewalk-semantic",
- metadata={
- "help": "Name of a dataset from the hub (could be your own, possibly private dataset hosted on the hub)."
- },
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_val_split: float | None = field(
- default=0.15, metadata={"help": "Percent to split off of train for validation."}
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- do_reduce_labels: bool | None = field(
- default=False,
- metadata={"help": "Whether or not to reduce all labels by 1 and replace background by 255."},
- )
-
- def __post_init__(self):
- if self.dataset_name is None and (self.train_dir is None and self.validation_dir is None):
- raise ValueError(
- "You must specify either a dataset name from the hub or a train and/or validation directory."
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- default="nvidia/mit-b0",
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"},
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- image_processor_name: str = field(default=None, metadata={"help": "Name or path of preprocessor config."})
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Load dataset
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- # TODO support datasets from local folders
- dataset = load_dataset(
- data_args.dataset_name, cache_dir=model_args.cache_dir, trust_remote_code=model_args.trust_remote_code
- )
-
- # Rename column names to standardized names (only "image" and "label" need to be present)
- if "pixel_values" in dataset["train"].column_names:
- dataset = dataset.rename_columns({"pixel_values": "image"})
- if "annotation" in dataset["train"].column_names:
- dataset = dataset.rename_columns({"annotation": "label"})
-
- # If we don't have a validation split, split off a percentage of train as validation.
- data_args.train_val_split = None if "validation" in dataset else data_args.train_val_split
- if isinstance(data_args.train_val_split, float) and data_args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(data_args.train_val_split)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Prepare label mappings.
- # We'll include these in the model's config to get human readable labels in the Inference API.
- if data_args.dataset_name == "scene_parse_150":
- repo_id = "huggingface/label-files"
- filename = "ade20k-id2label.json"
- else:
- repo_id = data_args.dataset_name
- filename = "id2label.json"
- id2label = json.load(open(hf_hub_download(repo_id, filename, repo_type="dataset"), encoding="utf-8"))
- id2label = {int(k): v for k, v in id2label.items()}
- label2id = {v: str(k) for k, v in id2label.items()}
-
- # Load the mean IoU metric from the evaluate package
- metric = evaluate.load("mean_iou", cache_dir=model_args.cache_dir)
-
- # Define our compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
- # predictions and label_ids field) and has to return a dictionary string to float.
- @torch.no_grad()
- def compute_metrics(eval_pred):
- logits, labels = eval_pred
- logits_tensor = torch.from_numpy(logits)
- # scale the logits to the size of the label
- logits_tensor = nn.functional.interpolate(
- logits_tensor,
- size=labels.shape[-2:],
- mode="bilinear",
- align_corners=False,
- ).argmax(dim=1)
-
- pred_labels = logits_tensor.detach().cpu().numpy()
- metrics = metric.compute(
- predictions=pred_labels,
- references=labels,
- num_labels=len(id2label),
- ignore_index=0,
- reduce_labels=image_processor.do_reduce_labels,
- )
- # add per category metrics as individual key-value pairs
- per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
- per_category_iou = metrics.pop("per_category_iou").tolist()
-
- metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
- metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
-
- return metrics
-
- config = AutoConfig.from_pretrained(
- model_args.config_name or model_args.model_name_or_path,
- label2id=label2id,
- id2label=id2label,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSemanticSegmentation.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- image_processor = AutoImageProcessor.from_pretrained(
- model_args.image_processor_name or model_args.model_name_or_path,
- do_reduce_labels=data_args.do_reduce_labels,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # Define transforms to be applied to each image and target.
- if "shortest_edge" in image_processor.size:
- # We instead set the target size as (shortest_edge, shortest_edge) to here to ensure all images are batchable.
- height, width = image_processor.size["shortest_edge"], image_processor.size["shortest_edge"]
- else:
- height, width = image_processor.size["height"], image_processor.size["width"]
- train_transforms = A.Compose(
- [
- A.Lambda(
- name="reduce_labels",
- mask=reduce_labels_transform if data_args.do_reduce_labels else None,
- p=1.0,
- ),
- # pad image with 255, because it is ignored by loss
- A.PadIfNeeded(min_height=height, min_width=width, border_mode=0, value=255, p=1.0),
- A.RandomCrop(height=height, width=width, p=1.0),
- A.HorizontalFlip(p=0.5),
- A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
- ToTensorV2(),
- ]
- )
- val_transforms = A.Compose(
- [
- A.Lambda(
- name="reduce_labels",
- mask=reduce_labels_transform if data_args.do_reduce_labels else None,
- p=1.0,
- ),
- A.Resize(height=height, width=width, p=1.0),
- A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
- ToTensorV2(),
- ]
- )
-
- def preprocess_batch(example_batch, transforms: A.Compose):
- pixel_values = []
- labels = []
- for image, target in zip(example_batch["image"], example_batch["label"]):
- transformed = transforms(image=np.array(image.convert("RGB")), mask=np.array(target))
- pixel_values.append(transformed["image"])
- labels.append(transformed["mask"])
-
- encoding = {}
- encoding["pixel_values"] = torch.stack(pixel_values).to(torch.float)
- encoding["labels"] = torch.stack(labels).to(torch.long)
-
- return encoding
-
- # Preprocess function for dataset should have only one argument,
- # so we use partial to pass the transforms
- preprocess_train_batch_fn = partial(preprocess_batch, transforms=train_transforms)
- preprocess_val_batch_fn = partial(preprocess_batch, transforms=val_transforms)
-
- if training_args.do_train:
- if "train" not in dataset:
- raise ValueError("--do_train requires a train dataset")
- if data_args.max_train_samples is not None:
- dataset["train"] = (
- dataset["train"].shuffle(seed=training_args.seed).select(range(data_args.max_train_samples))
- )
- # Set the training transforms
- dataset["train"].set_transform(preprocess_train_batch_fn)
-
- if training_args.do_eval:
- if "validation" not in dataset:
- raise ValueError("--do_eval requires a validation dataset")
- if data_args.max_eval_samples is not None:
- dataset["validation"] = (
- dataset["validation"].shuffle(seed=training_args.seed).select(range(data_args.max_eval_samples))
- )
- # Set the validation transforms
- dataset["validation"].set_transform(preprocess_val_batch_fn)
-
- # Initialize our trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=dataset["train"] if training_args.do_train else None,
- eval_dataset=dataset["validation"] if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=image_processor,
- data_collator=default_data_collator,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
- trainer.log_metrics("train", train_result.metrics)
- trainer.save_metrics("train", train_result.metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- metrics = trainer.evaluate()
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "dataset": data_args.dataset_name,
- "tags": ["image-segmentation", "vision"],
- }
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py b/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
deleted file mode 100644
index 75f2b7cb48ca..000000000000
--- a/examples/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
+++ /dev/null
@@ -1,622 +0,0 @@
-# Copyright 2022 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets >= 2.0.0",
-# "torch >= 1.3",
-# "accelerate",
-# "evaluate""
-# "Pillow",
-# "albumentations >= 1.4.16",
-# ]
-# ///
-
-"""Finetuning any 🤗 Transformers model supported by AutoModelForSemanticSegmentation for semantic segmentation."""
-
-import argparse
-import json
-import math
-import os
-from functools import partial
-from pathlib import Path
-
-import albumentations as A
-import datasets
-import evaluate
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from albumentations.pytorch import ToTensorV2
-from datasets import load_dataset
-from huggingface_hub import HfApi, hf_hub_download
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoImageProcessor,
- AutoModelForSemanticSegmentation,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-
-require_version("datasets>=2.0.0", "To fix: pip install -r examples/pytorch/semantic-segmentation/requirements.txt")
-
-
-def reduce_labels_transform(labels: np.ndarray, **kwargs) -> np.ndarray:
- """Set `0` label as with value 255 and then reduce all other labels by 1.
-
- Example:
- Initial class labels: 0 - background; 1 - road; 2 - car;
- Transformed class labels: 255 - background; 0 - road; 1 - car;
-
- **kwargs are required to use this function with albumentations.
- """
- labels[labels == 0] = 255
- labels = labels - 1
- labels[labels == 254] = 255
- return labels
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a image semantic segmentation task")
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to a pretrained model or model identifier from huggingface.co/models.",
- default="nvidia/mit-b0",
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- help="Name of the dataset on the hub.",
- default="segments/sidewalk-semantic",
- )
- parser.add_argument(
- "--do_reduce_labels",
- action="store_true",
- help="Whether or not to reduce all labels by 1 and replace background by 255.",
- )
- parser.add_argument(
- "--train_val_split",
- type=float,
- default=0.15,
- help="Fraction of the dataset to be used for validation.",
- )
- parser.add_argument(
- "--cache_dir",
- type=str,
- help="Path to a folder in which the model and dataset will be cached.",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument(
- "--adam_beta1",
- type=float,
- default=0.9,
- help="Beta1 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_beta2",
- type=float,
- default=0.999,
- help="Beta2 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_epsilon",
- type=float,
- default=1e-8,
- help="Epsilon for AdamW optimizer",
- )
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="polynomial",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- required=False,
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.push_to_hub or args.with_tracking:
- if args.output_dir is None:
- raise ValueError(
- "Need an `output_dir` to create a repo when `--push_to_hub` or `with_tracking` is specified."
- )
-
- if args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
-
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- # We set device_specific to True as we want different data augmentation per device.
- if args.seed is not None:
- set_seed(args.seed, device_specific=True)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Load dataset
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- # TODO support datasets from local folders
- dataset = load_dataset(args.dataset_name, cache_dir=args.cache_dir, trust_remote_code=args.trust_remote_code)
-
- # Rename column names to standardized names (only "image" and "label" need to be present)
- if "pixel_values" in dataset["train"].column_names:
- dataset = dataset.rename_columns({"pixel_values": "image"})
- if "annotation" in dataset["train"].column_names:
- dataset = dataset.rename_columns({"annotation": "label"})
-
- # If we don't have a validation split, split off a percentage of train as validation.
- args.train_val_split = None if "validation" in dataset else args.train_val_split
- if isinstance(args.train_val_split, float) and args.train_val_split > 0.0:
- split = dataset["train"].train_test_split(args.train_val_split)
- dataset["train"] = split["train"]
- dataset["validation"] = split["test"]
-
- # Prepare label mappings.
- # We'll include these in the model's config to get human readable labels in the Inference API.
- if args.dataset_name == "scene_parse_150":
- repo_id = "huggingface/label-files"
- filename = "ade20k-id2label.json"
- else:
- repo_id = args.dataset_name
- filename = "id2label.json"
- id2label = json.load(open(hf_hub_download(repo_id, filename, repo_type="dataset"), encoding="utf-8"))
- id2label = {int(k): v for k, v in id2label.items()}
- label2id = {v: k for k, v in id2label.items()}
-
- # Load pretrained model and image processor
- config = AutoConfig.from_pretrained(
- args.model_name_or_path, id2label=id2label, label2id=label2id, trust_remote_code=args.trust_remote_code
- )
- image_processor = AutoImageProcessor.from_pretrained(
- args.model_name_or_path, trust_remote_code=args.trust_remote_code, do_reduce_labels=args.do_reduce_labels
- )
- model = AutoModelForSemanticSegmentation.from_pretrained(
- args.model_name_or_path,
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
-
- # Define transforms to be applied to each image and target.
- if "shortest_edge" in image_processor.size:
- # We instead set the target size as (shortest_edge, shortest_edge) to here to ensure all images are batchable.
- height, width = image_processor.size["shortest_edge"], image_processor.size["shortest_edge"]
- else:
- height, width = image_processor.size["height"], image_processor.size["width"]
- train_transforms = A.Compose(
- [
- A.Lambda(name="reduce_labels", mask=reduce_labels_transform if args.do_reduce_labels else None, p=1.0),
- # pad image with 255, because it is ignored by loss
- A.PadIfNeeded(min_height=height, min_width=width, border_mode=0, value=255, p=1.0),
- A.RandomCrop(height=height, width=width, p=1.0),
- A.HorizontalFlip(p=0.5),
- A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
- ToTensorV2(),
- ]
- )
- val_transforms = A.Compose(
- [
- A.Lambda(name="reduce_labels", mask=reduce_labels_transform if args.do_reduce_labels else None, p=1.0),
- A.Resize(height=height, width=width, p=1.0),
- A.Normalize(mean=image_processor.image_mean, std=image_processor.image_std, max_pixel_value=255.0, p=1.0),
- ToTensorV2(),
- ]
- )
-
- def preprocess_batch(example_batch, transforms: A.Compose):
- pixel_values = []
- labels = []
- for image, target in zip(example_batch["image"], example_batch["label"]):
- transformed = transforms(image=np.array(image.convert("RGB")), mask=np.array(target))
- pixel_values.append(transformed["image"])
- labels.append(transformed["mask"])
-
- encoding = {}
- encoding["pixel_values"] = torch.stack(pixel_values).to(torch.float)
- encoding["labels"] = torch.stack(labels).to(torch.long)
-
- return encoding
-
- # Preprocess function for dataset should have only one input argument,
- # so we use partial to pass transforms
- preprocess_train_batch_fn = partial(preprocess_batch, transforms=train_transforms)
- preprocess_val_batch_fn = partial(preprocess_batch, transforms=val_transforms)
-
- with accelerator.main_process_first():
- train_dataset = dataset["train"].with_transform(preprocess_train_batch_fn)
- eval_dataset = dataset["validation"].with_transform(preprocess_val_batch_fn)
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=default_data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(
- eval_dataset, collate_fn=default_data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Optimizer
- optimizer = torch.optim.AdamW(
- list(model.parameters()),
- lr=args.learning_rate,
- betas=[args.adam_beta1, args.adam_beta2],
- eps=args.adam_epsilon,
- )
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Instantiate metric
- metric = evaluate.load("mean_iou", cache_dir=args.cache_dir)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("semantic_segmentation_no_trainer", experiment_config)
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir,
- is_main_process=accelerator.is_main_process,
- save_function=accelerator.save,
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if completed_steps >= args.max_train_steps:
- break
-
- logger.info("***** Running evaluation *****")
- model.eval()
- for step, batch in enumerate(tqdm(eval_dataloader, disable=not accelerator.is_local_main_process)):
- with torch.no_grad():
- outputs = model(**batch)
-
- upsampled_logits = torch.nn.functional.interpolate(
- outputs.logits, size=batch["labels"].shape[-2:], mode="bilinear", align_corners=False
- )
- predictions = upsampled_logits.argmax(dim=1)
-
- predictions, references = accelerator.gather_for_metrics((predictions, batch["labels"]))
-
- metric.add_batch(
- predictions=predictions,
- references=references,
- )
-
- eval_metrics = metric.compute(
- num_labels=len(id2label),
- ignore_index=255,
- reduce_labels=False, # we've already reduced the labels before
- )
- logger.info(f"epoch {epoch}: {eval_metrics}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "mean_iou": eval_metrics["mean_iou"],
- "mean_accuracy": eval_metrics["mean_accuracy"],
- "overall_accuracy": eval_metrics["overall_accuracy"],
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- image_processor.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- all_results = {
- f"eval_{k}": v.tolist() if isinstance(v, np.ndarray) else v for k, v in eval_metrics.items()
- }
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(all_results, f, indent=2)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/speech-pretraining/README.md b/examples/pytorch/speech-pretraining/README.md
deleted file mode 100644
index fe6ec176b505..000000000000
--- a/examples/pytorch/speech-pretraining/README.md
+++ /dev/null
@@ -1,161 +0,0 @@
-
-
-# Speech Recognition Pre-Training
-
-
-## Wav2Vec2 Speech Pre-Training
-
-The script [`run_speech_wav2vec2_pretraining_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py) can be used to pre-train a [Wav2Vec2](https://huggingface.co/transformers/model_doc/wav2vec2.html?highlight=wav2vec2) model from scratch.
-
-In the script [`run_speech_wav2vec2_pretraining_no_trainer`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py), a Wav2Vec2 model is pre-trained on audio data alone using [Wav2Vec2's contrastive loss objective](https://huggingface.co/papers/2006.11477).
-
-The following examples show how to fine-tune a `"base"`-sized Wav2Vec2 model as well as a `"large"`-sized Wav2Vec2 model using [`accelerate`](https://github.com/huggingface/accelerate).
-
-
----
-**NOTE 1**
-
-Wav2Vec2's pre-training is known to be quite unstable.
-It is advised to do a couple of test runs with a smaller dataset,
-*i.e.* `--dataset_config_names clean clean`, `--dataset_split_names validation test`
-to find good hyper-parameters for `learning_rate`, `batch_size`, `num_warmup_steps`,
-and the optimizer.
-A good metric to observe during training is the gradient norm which should ideally be between 0.5 and 2.
-
----
-
----
-**NOTE 2**
-
-When training a model on large datasets it is recommended to run the data preprocessing
-in a first run in a **non-distributed** mode via `--preprocessing_only` so that
-when running the model in **distributed** mode in a second step the preprocessed data
-can easily be loaded on each distributed device.
-
----
-
-### Demo
-
-In this demo run we pre-train a `"base-sized"` Wav2Vec2 model simply only on the validation
-and test data of [librispeech_asr](https://huggingface.co/datasets/openslr/librispeech_asr).
-
-The demo is run on two Titan RTX (24 GB RAM each). In case you have less RAM available
-per device, consider reducing `--batch_size` and/or the `--max_duration_in_seconds`.
-
-
-```bash
-accelerate launch run_wav2vec2_pretraining_no_trainer.py \
- --dataset_name="openslr/librispeech_asr" \
- --dataset_config_names clean clean \
- --dataset_split_names validation test \
- --model_name_or_path="patrickvonplaten/wav2vec2-base-v2" \
- --output_dir="./wav2vec2-pretrained-demo" \
- --max_train_steps="20000" \
- --num_warmup_steps="32000" \
- --gradient_accumulation_steps="8" \
- --learning_rate="0.005" \
- --weight_decay="0.01" \
- --max_duration_in_seconds="20.0" \
- --min_duration_in_seconds="2.0" \
- --logging_steps="1" \
- --saving_steps="10000" \
- --per_device_train_batch_size="8" \
- --per_device_eval_batch_size="8" \
- --adam_beta1="0.9" \
- --adam_beta2="0.98" \
- --adam_epsilon="1e-06" \
- --gradient_checkpointing \
- --mask_time_prob="0.65" \
- --mask_time_length="10"
-```
-
-The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/wav2vec2-pretrained-demo/reports/Wav2Vec2-PreTraining-Demo-Run--VmlldzoxMDk3MjAw?accessToken=oa05s1y57lizo2ocxy3k01g6db1u4pt8m6ur2n8nl4cb0ug02ms2cw313kb8ruch).
-
-### Base
-
-To pre-train `"base-sized"` Wav2Vec2 model, *e.g.* [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base)
-on [librispeech_asr](https://huggingface.co/datasets/openslr/librispeech_asr), the following command can be run:
-
-```bash
-accelerate launch run_wav2vec2_pretraining_no_trainer.py \
- --dataset_name=openslr/librispeech_asr \
- --dataset_config_names clean clean other \
- --dataset_split_names train.100 train.360 train.500 \
- --model_name_or_path="patrickvonplaten/wav2vec2-base-v2" \
- --output_dir="./wav2vec2-pretrained-demo" \
- --max_train_steps="200000" \
- --num_warmup_steps="32000" \
- --gradient_accumulation_steps="4" \
- --learning_rate="0.001" \
- --weight_decay="0.01" \
- --max_duration_in_seconds="20.0" \
- --min_duration_in_seconds="2.0" \
- --logging_steps="1" \
- --saving_steps="10000" \
- --per_device_train_batch_size="8" \
- --per_device_eval_batch_size="8" \
- --adam_beta1="0.9" \
- --adam_beta2="0.98" \
- --adam_epsilon="1e-06" \
- --gradient_checkpointing \
- --mask_time_prob="0.65" \
- --mask_time_length="10"
-```
-
-The experiment was run on 8 GPU V100 (16 GB RAM each) for 4 days.
-In case you have more than 8 GPUs available for a higher effective `batch_size`,
-it is recommended to increase the `learning_rate` to `0.005` for faster convergence.
-
-The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/test/reports/Wav2Vec2-Base--VmlldzoxMTUyODQ0?accessToken=rg6e8u9yizx964k8q47zctq1m4afpvtn1i3qi9exgdmzip6xwkfzvagfajpzj55n) and the checkpoint pretrained for 85,000 steps can be accessed [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-repro-960h-libri-85k-steps)
-
-
-### Large
-
-To pre-train `"large-sized"` Wav2Vec2 model, *e.g.* [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60),
-on [librispeech_asr](https://huggingface.co/datasets/openslr/librispeech_asr), the following command can be run:
-
-```bash
-accelerate launch run_wav2vec2_pretraining_no_trainer.py \
- --dataset_name=openslr/librispeech_asr \
- --dataset_config_names clean clean other \
- --dataset_split_names train.100 train.360 train.500 \
- --output_dir=./test \
- --max_train_steps=200000 \
- --num_warmup_steps=32000 \
- --gradient_accumulation_steps=8 \
- --learning_rate=0.001 \
- --weight_decay=0.01 \
- --max_duration_in_seconds=20.0 \
- --min_duration_in_seconds=2.0 \
- --model_name_or_path=./ \
- --logging_steps=1 \
- --saving_steps=10000 \
- --per_device_train_batch_size=2 \
- --per_device_eval_batch_size=4 \
- --adam_beta1=0.9 \
- --adam_beta2=0.98 \
- --adam_epsilon=1e-06 \
- --gradient_checkpointing \
- --mask_time_prob=0.65 \
- --mask_time_length=10
-```
-
-The experiment was run on 8 GPU V100 (16 GB RAM each) for 7 days.
-In case you have more than 8 GPUs available for a higher effective `batch_size`,
-it is recommended to increase the `learning_rate` to `0.005` for faster convergence.
-
-The results of this run can be seen [here](https://wandb.ai/patrickvonplaten/pretraining-wav2vec2/reports/Wav2Vec2-Large--VmlldzoxMTAwODM4?accessToken=wm3qzcnldrwsa31tkvf2pdmilw3f63d4twtffs86ou016xjbyilh55uoi3mo1qzc) and the checkpoint pretrained for 120,000 steps can be accessed [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-repro-960h-libri-120k-steps)
diff --git a/examples/pytorch/speech-pretraining/requirements.txt b/examples/pytorch/speech-pretraining/requirements.txt
deleted file mode 100644
index 57851d2a09d1..000000000000
--- a/examples/pytorch/speech-pretraining/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-datasets[audio] >= 1.12.0
-torch >= 1.5
-torchaudio
-accelerate >= 0.12.0
-librosa
\ No newline at end of file
diff --git a/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py b/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py
deleted file mode 100755
index 10d367918126..000000000000
--- a/examples/pytorch/speech-pretraining/run_wav2vec2_pretraining_no_trainer.py
+++ /dev/null
@@ -1,807 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets[audio] >= 1.12.0",
-# "torch >= 1.5",
-# "torchaudio",
-# "accelerate >= 0.12.0",
-# "librosa",
-# ]
-# ///
-
-"""Pre-Training a 🤗 Wav2Vec2 model on unlabeled audio data"""
-
-import argparse
-import math
-import os
-from dataclasses import dataclass
-from pathlib import Path
-
-import aiohttp
-import datasets
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from datasets import DatasetDict, concatenate_datasets, load_dataset
-from huggingface_hub import HfApi
-from torch.utils.data.dataloader import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- SchedulerType,
- Wav2Vec2Config,
- Wav2Vec2FeatureExtractor,
- Wav2Vec2ForPreTraining,
- get_scheduler,
- is_wandb_available,
- set_seed,
-)
-from transformers.models.wav2vec2.modeling_wav2vec2 import _compute_mask_indices, _sample_negative_indices
-
-
-logger = get_logger(__name__)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_names",
- nargs="+",
- type=str,
- required=True,
- help="The configuration names of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_split_names",
- nargs="+",
- type=str,
- required=True,
- help="The names of the training data set splits to use (via the datasets library).",
- )
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--preprocessing_only",
- action="store_true",
- help="Only run the preprocessing script to be cached for future use",
- )
- parser.add_argument(
- "--cache_dir",
- type=str,
- default=None,
- help="Where do you want to store the pretrained models downloaded from huggingface.co",
- )
- parser.add_argument(
- "--validation_split_percentage",
- type=int,
- default=1,
- help="Percentage of training data that should be used for validation if no validation is present in dataset.",
- )
- parser.add_argument(
- "--logging_steps",
- type=int,
- default=500,
- help="Number of steps between each logging",
- )
- parser.add_argument(
- "--saving_steps",
- type=int,
- default=500,
- help="Number of steps between each logging",
- )
- parser.add_argument(
- "--audio_column_name",
- type=str,
- default="audio",
- help="Column in the dataset that contains speech file path. Defaults to 'audio'",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=True,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--train_cache_file_name",
- type=str,
- default=None,
- help="Path to the train cached file name",
- )
- parser.add_argument(
- "--validation_cache_file_name",
- type=str,
- default=None,
- help="Path to the validation cached file name",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--gradient_checkpointing",
- action="store_true",
- help="If True, use gradient checkpointing to save memory at the expense of slower backward pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=0, help="A seed for reproducible training.")
- parser.add_argument(
- "--max_gumbel_temperature",
- type=float,
- default=2.0,
- help="Maximum temperature for gumbel softmax.",
- )
- parser.add_argument(
- "--min_gumbel_temperature",
- type=float,
- default=0.5,
- help="Minimum temperature for gumbel softmax.",
- )
- parser.add_argument(
- "--gumbel_temperature_decay", type=float, default=0.999995, help="Decay of gumbel temperature during training."
- )
- parser.add_argument(
- "--max_duration_in_seconds",
- type=float,
- default=5.0,
- help="Filter out audio files that are longer than `max_duration_in_seconds` seconds",
- )
- parser.add_argument(
- "--min_duration_in_seconds",
- type=float,
- default=3.0,
- help="Filter out audio files that are shorter than `min_duration_in_seconds` seconds",
- )
- parser.add_argument(
- "--pad_to_multiple_of",
- type=int,
- default=None,
- help=(
- "If set will pad the sequence to a multiple of the provided value. This is especially useful to enable the"
- " use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta)."
- ),
- )
- parser.add_argument(
- "--adam_beta1",
- type=float,
- default=0.9,
- help="Beta1 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_beta2",
- type=float,
- default=0.999,
- help="Beta2 for AdamW optimizer",
- )
- parser.add_argument(
- "--adam_epsilon",
- type=float,
- default=1e-8,
- help="Epsilon for AdamW optimizer",
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--mask_time_prob",
- type=float,
- default=None,
- help=(
- "Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked in the"
- " contrastive task. If omitted, will pull value from model config."
- ),
- )
- parser.add_argument(
- "--mask_time_length",
- type=int,
- default=None,
- help=(
- "Length of each vector mask span to mask along the time axis in the contrastive task."
- " If omitted, will pull value from model config."
- ),
- )
- args = parser.parse_args()
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- if args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
-
- return args
-
-
-@dataclass
-class DataCollatorForWav2Vec2Pretraining:
- """
- Data collator that will dynamically pad the inputs received and prepare masked indices
- for self-supervised pretraining.
-
- Args:
- model (:class:`~transformers.Wav2Vec2ForPreTraining`):
- The Wav2Vec2 model used for pretraining. The data collator needs to have access
- to config and ``_get_feat_extract_output_lengths`` function for correct padding.
- feature_extractor (:class:`~transformers.Wav2Vec2FeatureExtractor`):
- The processor used for processing the data.
- padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
- Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
- among:
- * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
- sequence if provided).
- * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
- maximum acceptable input length for the model if that argument is not provided.
- * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
- different lengths).
- max_length (:obj:`int`, `optional`):
- Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
- pad_to_multiple_of (:obj:`int`, `optional`):
- If set will pad the sequence to a multiple of the provided value.
- This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
- 7.5 (Volta).
- mask_time_prob (:obj:`float`, `optional`, defaults to :obj:`0.65`):
- Percentage (between 0 and 1) of all feature vectors along the time axis which will be masked for the contrastive task.
- Note that overlap between masked sequences may decrease the actual percentage of masked vectors.
- The default value is taken from the original wav2vec 2.0 article (https://huggingface.co/papers/2006.11477),
- and results in about 49 percent of each sequence being masked on average.
- mask_time_length (:obj:`int`, `optional`, defaults to :obj:`10`):
- Length of each vector mask span to mask along the time axis in the contrastive task. The default value
- originates from the original wav2vec 2.0 article and corresponds to the ``M`` variable mentioned there.
- """
-
- model: Wav2Vec2ForPreTraining
- feature_extractor: Wav2Vec2FeatureExtractor
- padding: bool | str = "longest"
- pad_to_multiple_of: int | None = None
- mask_time_prob: float | None = 0.65
- mask_time_length: int | None = 10
-
- def __call__(self, features: list[dict[str, list[int] | torch.Tensor]]) -> dict[str, torch.Tensor]:
- # reformat list to dict and set to pytorch format
- batch = self.feature_extractor.pad(
- features,
- padding=self.padding,
- pad_to_multiple_of=self.pad_to_multiple_of,
- return_tensors="pt",
- )
-
- device = batch["input_values"].device
- batch_size = batch["input_values"].shape[0]
-
- mask_indices_seq_length = self.model._get_feat_extract_output_lengths(batch["input_values"].shape[-1])
- # make sure masked sequence length is a Python scalar
- mask_indices_seq_length = int(mask_indices_seq_length)
-
- # make sure that no loss is computed on padded inputs
- if batch.get("attention_mask") is not None:
- # compute real output lengths according to convolution formula
- batch["sub_attention_mask"] = self.model._get_feature_vector_attention_mask(
- mask_indices_seq_length, batch["attention_mask"]
- )
-
- features_shape = (batch_size, mask_indices_seq_length)
-
- # sample randomly masked indices
- mask_time_indices = _compute_mask_indices(
- features_shape,
- self.mask_time_prob,
- self.mask_time_length,
- attention_mask=batch.get("sub_attention_mask"),
- )
-
- # sample negative indices
- sampled_negative_indices = _sample_negative_indices(
- features_shape,
- self.model.config.num_negatives,
- mask_time_indices=mask_time_indices,
- )
- batch["mask_time_indices"] = torch.tensor(mask_time_indices, dtype=torch.long, device=device)
- batch["sampled_negative_indices"] = torch.tensor(sampled_negative_indices, dtype=torch.long, device=device)
-
- return batch
-
-
-def multiply_grads(params, c):
- """Multiplies grads by a constant *c*."""
- for p in params:
- if p.grad is not None:
- if torch.is_tensor(c):
- c = c.to(p.grad.device)
- p.grad.data.mul_(c)
-
-
-def get_grad_norm(params, scale=1):
- """Compute grad norm given a gradient scale."""
- total_norm = 0.0
- for p in params:
- if p.grad is not None:
- param_norm = (p.grad.detach().data / scale).norm(2)
- total_norm += param_norm.item() ** 2
- total_norm = total_norm**0.5
- return total_norm
-
-
-def main():
- # See all possible arguments in src/transformers/args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- accelerator = Accelerator()
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
-
- # set up weights and biases if available
- if is_wandb_available():
- import wandb
-
- wandb.init(project=args.output_dir.split("/")[-1])
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub and not args.preprocessing_only:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # 1. Download and create train, validation dataset
- # We load all dataset configuration and dataset split pairs passed in
- # ``args.dataset_config_names`` and ``args.dataset_split_names``
- datasets_splits = []
- for dataset_config_name, train_split_name in zip(args.dataset_config_names, args.dataset_split_names):
- # load dataset
- dataset_split = load_dataset(
- args.dataset_name,
- dataset_config_name,
- split=train_split_name,
- cache_dir=args.cache_dir,
- trust_remote_code=args.trust_remote_code,
- storage_options={"client_kwargs": {"timeout": aiohttp.ClientTimeout(total=60 * 60)}},
- )
- datasets_splits.append(dataset_split)
-
- # Next, we concatenate all configurations and splits into a single training dataset
- raw_datasets = DatasetDict()
- if len(datasets_splits) > 1:
- raw_datasets["train"] = concatenate_datasets(datasets_splits).shuffle(seed=args.seed)
- else:
- raw_datasets["train"] = datasets_splits[0]
-
- # Take ``args.validation_split_percentage`` from the training dataset for the validation_split_percentage
- num_validation_samples = raw_datasets["train"].num_rows * args.validation_split_percentage // 100
-
- if num_validation_samples == 0:
- raise ValueError(
- "`args.validation_split_percentage` is less than a single sample "
- f"for {len(raw_datasets['train'])} training samples. Increase "
- "`args.num_validation_split_percentage`. "
- )
-
- raw_datasets["validation"] = raw_datasets["train"].select(range(num_validation_samples))
- raw_datasets["train"] = raw_datasets["train"].select(range(num_validation_samples, raw_datasets["train"].num_rows))
-
- # 2. Now we preprocess the datasets including loading the audio, resampling and normalization
- # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
- # so that we just need to set the correct target sampling rate and normalize the input
- # via the `feature_extractor`
- feature_extractor = Wav2Vec2FeatureExtractor.from_pretrained(args.model_name_or_path)
-
- # make sure that dataset decodes audio with correct sampling rate
- raw_datasets = raw_datasets.cast_column(
- args.audio_column_name, datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate)
- )
-
- # only normalized-inputs-training is supported
- if not feature_extractor.do_normalize:
- raise ValueError(
- "Training is only supported for normalized inputs. Make sure ``feature_extractor.do_normalize == True``"
- )
-
- # set max & min audio length in number of samples
- max_length = int(args.max_duration_in_seconds * feature_extractor.sampling_rate)
- min_length = int(args.min_duration_in_seconds * feature_extractor.sampling_rate)
-
- def prepare_dataset(batch):
- sample = batch[args.audio_column_name]
-
- inputs = feature_extractor(
- sample["array"], sampling_rate=sample["sampling_rate"], max_length=max_length, truncation=True
- )
- batch["input_values"] = inputs.input_values[0]
- batch["input_length"] = len(inputs.input_values[0])
-
- return batch
-
- # load via mapped files via path
- cache_file_names = None
- if args.train_cache_file_name is not None:
- cache_file_names = {"train": args.train_cache_file_name, "validation": args.validation_cache_file_name}
-
- # load audio files into numpy arrays
- with accelerator.main_process_first():
- vectorized_datasets = raw_datasets.map(
- prepare_dataset,
- num_proc=args.preprocessing_num_workers,
- remove_columns=raw_datasets["train"].column_names,
- cache_file_names=cache_file_names,
- )
-
- if min_length > 0.0:
- vectorized_datasets = vectorized_datasets.filter(
- lambda x: x > min_length,
- num_proc=args.preprocessing_num_workers,
- input_columns=["input_length"],
- )
-
- vectorized_datasets = vectorized_datasets.remove_columns("input_length")
-
- # for large datasets it is advised to run the preprocessing on a
- # single machine first with ``args.preprocessing_only`` since there will mostly likely
- # be a timeout when running the script in distributed mode.
- # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
- # cached dataset
- if args.preprocessing_only:
- return
-
- # 3. Load model
- config = Wav2Vec2Config.from_pretrained(args.model_name_or_path)
-
- # pretraining is only supported for "newer" stable layer norm architecture
- # apply_spec_augment has to be True, mask_feature_prob has to be 0.0
- if not config.do_stable_layer_norm or config.feat_extract_norm != "layer":
- raise ValueError(
- "PreTraining is only supported for ``config.do_stable_layer_norm=True`` and"
- " ``config.feat_extract_norm='layer'"
- )
-
- # initialize random model
- model = Wav2Vec2ForPreTraining(config)
-
- # Activate gradient checkpointing if needed
- if args.gradient_checkpointing:
- model.gradient_checkpointing_enable()
-
- # 4. Define data collator, optimizer and scheduler
-
- mask_time_prob = config.mask_time_prob if args.mask_time_prob is None else args.mask_time_prob
- mask_time_length = config.mask_time_length if args.mask_time_length is None else args.mask_time_length
-
- data_collator = DataCollatorForWav2Vec2Pretraining(
- model=model,
- feature_extractor=feature_extractor,
- pad_to_multiple_of=args.pad_to_multiple_of,
- mask_time_prob=mask_time_prob,
- mask_time_length=mask_time_length,
- )
- train_dataloader = DataLoader(
- vectorized_datasets["train"],
- shuffle=True,
- collate_fn=data_collator,
- batch_size=args.per_device_train_batch_size,
- )
- eval_dataloader = DataLoader(
- vectorized_datasets["validation"], collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
-
- # Optimizer
- optimizer = torch.optim.AdamW(
- list(model.parameters()),
- lr=args.learning_rate,
- betas=[args.adam_beta1, args.adam_beta2],
- eps=args.adam_epsilon,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader
- )
-
- # Scheduler and math around the number of training steps.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
-
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps,
- num_training_steps=args.max_train_steps,
- )
-
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # 5. Train
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(vectorized_datasets['train'])}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- completed_steps = 0
- starting_epoch = 0
-
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- for step, batch in enumerate(train_dataloader):
- # compute num of losses
- num_losses = batch["mask_time_indices"].sum()
- sub_attention_mask = batch.pop("sub_attention_mask", None)
- sub_attention_mask = (
- sub_attention_mask if sub_attention_mask is not None else torch.ones_like(batch["mask_time_indices"])
- )
- percent_masked = num_losses / sub_attention_mask.sum()
-
- # forward
- outputs = model(**batch)
-
- # divide loss by gradient accumulation steps since gradients
- # are accumulated for multiple backward passes in PyTorch
- loss = outputs.loss / args.gradient_accumulation_steps
- accelerator.backward(loss)
-
- # make sure that `num_losses` is summed for distributed training
- # and average gradients over losses of all devices
- if accelerator.state.num_processes > 1:
- num_losses = accelerator.gather_for_metrics(num_losses).sum()
- gradient_multiplier = accelerator.state.num_processes / num_losses
- multiply_grads(model.module.parameters(), gradient_multiplier)
- else:
- multiply_grads(model.parameters(), 1 / num_losses)
-
- # update step
- if (step + 1) % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
- # compute grad norm for monitoring
- scale = (
- accelerator.scaler._scale.item()
- if hasattr(accelerator, "scaler") and accelerator.scaler is not None
- else 1
- )
- if accelerator.state.num_processes > 1:
- grad_norm = get_grad_norm(model.module.parameters(), scale)
- else:
- grad_norm = get_grad_norm(model.parameters(), scale)
-
- # update parameters
- optimizer.step()
- optimizer.zero_grad()
-
- if not accelerator.optimizer_step_was_skipped:
- lr_scheduler.step()
- elif accelerator.is_local_main_process:
- progress_bar.write(
- f"Gradients have overflown - skipping update step... Updating gradient scale to {scale}..."
- )
-
- # update gumbel temperature
- gumbel_temperature = max(
- args.max_gumbel_temperature * args.gumbel_temperature_decay**completed_steps,
- args.min_gumbel_temperature,
- )
- if hasattr(model, "module"):
- model.module.set_gumbel_temperature(gumbel_temperature)
- else:
- model.set_gumbel_temperature(gumbel_temperature)
-
- progress_bar.update(1)
- completed_steps += 1
-
- # 6. Log all results
- if (step + 1) % (args.gradient_accumulation_steps * args.logging_steps) == 0:
- loss.detach()
- outputs.contrastive_loss.detach()
- outputs.diversity_loss.detach()
-
- if accelerator.state.num_processes > 1:
- loss = accelerator.gather_for_metrics(loss).sum()
- outputs.contrastive_loss = accelerator.gather_for_metrics(outputs.contrastive_loss).sum()
- outputs.diversity_loss = accelerator.gather_for_metrics(outputs.diversity_loss).sum()
- percent_masked = accelerator.gather_for_metrics(percent_masked).sum()
-
- train_logs = {
- "loss": (loss * args.gradient_accumulation_steps) / num_losses,
- "constrast_loss": outputs.contrastive_loss / num_losses,
- "div_loss": outputs.diversity_loss / num_losses,
- "%_mask_idx": percent_masked / accelerator.num_processes,
- "ppl": outputs.codevector_perplexity,
- "lr": torch.tensor(optimizer.param_groups[0]["lr"]),
- "temp": torch.tensor(gumbel_temperature),
- "grad_norm": torch.tensor(grad_norm),
- }
- log_str = ""
- for k, v in train_logs.items():
- log_str += f"| {k}: {v.item():.3e}"
-
- if accelerator.is_local_main_process:
- progress_bar.write(log_str)
- if is_wandb_available():
- wandb.log(train_logs)
-
- # save model every `args.saving_steps` steps
- if (step + 1) % (args.gradient_accumulation_steps * args.saving_steps) == 0:
- if (args.push_to_hub and epoch < args.num_train_epochs - 1) or args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
-
- if (args.push_to_hub and epoch < args.num_train_epochs - 1) and accelerator.is_main_process:
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- # if completed steps > `args.max_train_steps` stop
- if completed_steps >= args.max_train_steps:
- break
-
- # 7. Validate!
- model.eval()
-
- # init logs
- val_logs = {
- "val_loss": 0,
- "val_contrastive_loss": 0,
- "val_diversity_loss": 0,
- "val_num_losses": 0,
- }
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- batch.pop("sub_attention_mask", None)
- outputs = model(**batch)
-
- val_logs["val_loss"] += outputs.loss
- val_logs["val_contrastive_loss"] += outputs.contrastive_loss
- val_logs["val_diversity_loss"] += outputs.diversity_loss
- val_logs["val_num_losses"] += batch["mask_time_indices"].sum()
-
- # sum over devices in multi-processing
- if accelerator.num_processes > 1:
- val_logs = {k: accelerator.gather_for_metrics(v).sum() for k, v in val_logs.items()}
-
- val_logs = {k: v / val_logs["val_num_losses"] for k, v in val_logs.items()}
-
- log_str = ""
- for k, v in val_logs.items():
- log_str += f"| {k}: {v.item():.3e}"
-
- if accelerator.is_local_main_process:
- progress_bar.write(log_str)
- if is_wandb_available():
- wandb.log(val_logs)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/speech-recognition/README.md b/examples/pytorch/speech-recognition/README.md
deleted file mode 100644
index 704b725076f0..000000000000
--- a/examples/pytorch/speech-recognition/README.md
+++ /dev/null
@@ -1,608 +0,0 @@
-
-
-# Automatic Speech Recognition Examples
-
-## Table of Contents
-
-- [Automatic Speech Recognition with CTC](#connectionist-temporal-classification)
- - [Single GPU example](#single-gpu-ctc)
- - [Multi GPU example](#multi-gpu-ctc)
- - [Examples](#examples-ctc)
- - [TIMIT](#timit-ctc)
- - [Librispeech](#librispeech-ctc)
- - [Common Voice](#common-voice-ctc)
- - [Multilingual Librispeech](#multilingual-librispeech-ctc)
-- [Automatic Speech Recognition with CTC and Adapter Layers](#connectionist-temporal-classification-with-adapters)
- - [Massive Multilingual Speech (MMS)](#mms-model)
- - [Examples](#examples-ctc-adapter)
- - [Common Voice](#common-voice-ctc-adapter)
-- [Automatic Speech Recognition with Sequence-to-Sequence](#sequence-to-sequence)
- - [Whisper Model](#whisper-model)
- - [Speech-Encoder-Decoder Model](#warm-started-speech-encoder-decoder-model)
- - [Examples](#examples-seq2seq)
- - [Librispeech](#librispeech-seq2seq)
-
-## Connectionist Temporal Classification
-
-The script [`run_speech_recognition_ctc.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py) can be used to fine-tune any pretrained [Connectionist Temporal Classification Model](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoModelForCTC) for automatic speech
-recognition on one of the [official speech recognition datasets](https://huggingface.co/datasets?task_ids=task_ids:automatic-speech-recognition) or a custom dataset.
-
-Speech recognition models that have been pretrained in unsupervised fashion on audio data alone, *e.g.* [Wav2Vec2](https://huggingface.co/transformers/main/model_doc/wav2vec2.html), [HuBERT](https://huggingface.co/transformers/main/model_doc/hubert.html), [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html), have shown to require only
-very little annotated data to yield good performance on automatic speech recognition datasets.
-
-In the script [`run_speech_recognition_ctc`], we first create a vocabulary from all unique characters of both the training data and evaluation data. Then, we preprocesses the speech recognition dataset, which includes correct resampling, normalization and padding. Finally, the pretrained speech recognition model is fine-tuned on the annotated speech recognition datasets using CTC loss.
-
----
-**NOTE**
-
-If you encounter problems with data preprocessing by setting `--preprocessing_num_workers` > 1,
-you might want to set the environment variable `OMP_NUM_THREADS` to 1 as follows:
-
-```bash
-OMP_NUM_THREADS=1 python run_speech_recognition_ctc ...
-```
-
-If the environment variable is not set, the training script might freeze, *i.e.* see: https://github.com/pytorch/audio/issues/1021#issuecomment-726915239
-
----
-
-### Single GPU CTC
-
-The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) using a single GPU in half-precision.
-
-```bash
-python run_speech_recognition_ctc.py \
- --dataset_name="mozilla-foundation/common_voice_17_0" \
- --model_name_or_path="facebook/wav2vec2-large-xlsr-53" \
- --dataset_config_name="tr" \
- --output_dir="./wav2vec2-common_voice-tr-demo" \
- --num_train_epochs="15" \
- --per_device_train_batch_size="16" \
- --gradient_accumulation_steps="2" \
- --learning_rate="3e-4" \
- --warmup_steps="500" \
- --eval_strategy="steps" \
- --text_column_name="sentence" \
- --length_column_name="input_length" \
- --save_steps="400" \
- --eval_steps="100" \
- --layerdrop="0.0" \
- --save_total_limit="3" \
- --freeze_feature_encoder \
- --gradient_checkpointing \
- --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
- --fp16 \
- --train_sampling_strategy group_by_length \
- --push_to_hub \
- --do_train --do_eval
-```
-
-On a single V100 GPU, this script should run in *ca.* 1 hour 20 minutes and yield a CTC loss of **0.39** and word error rate
-of **0.35**.
-
-### Multi GPU CTC
-
-The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) using 8 GPUs in half-precision.
-
-```bash
-torchrun \
- --nproc_per_node 8 run_speech_recognition_ctc.py \
- --dataset_name="mozilla-foundation/common_voice_17_0" \
- --model_name_or_path="facebook/wav2vec2-large-xlsr-53" \
- --dataset_config_name="tr" \
- --output_dir="./wav2vec2-common_voice-tr-demo-dist" \
- --num_train_epochs="15" \
- --per_device_train_batch_size="4" \
- --learning_rate="3e-4" \
- --warmup_steps="500" \
- --eval_strategy="steps" \
- --text_column_name="sentence" \
- --length_column_name="input_length" \
- --save_steps="400" \
- --eval_steps="100" \
- --logging_steps="1" \
- --layerdrop="0.0" \
- --save_total_limit="3" \
- --freeze_feature_encoder \
- --gradient_checkpointing \
- --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
- --fp16 \
- --train_sampling_strategy group_by_length \
- --push_to_hub \
- --do_train --do_eval
-```
-
-On 8 V100 GPUs, this script should run in *ca.* 18 minutes and yield a CTC loss of **0.39** and word error rate
-of **0.36**.
-
-
-### Multi GPU CTC with Dataset Streaming
-
-The following command shows how to use [Dataset Streaming mode](https://huggingface.co/docs/datasets/dataset_streaming)
-to fine-tune [XLS-R](https://huggingface.co/transformers/main/model_doc/xls_r.html)
-on [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) using 4 GPUs in half-precision.
-
-Streaming mode imposes several constraints on training:
-1. We need to construct a tokenizer beforehand and define it via `--tokenizer_name_or_path`.
-2. `--num_train_epochs` has to be replaced by `--max_steps`. Similarly, all other epoch-based arguments have to be
-replaced by step-based ones.
-3. Full dataset shuffling on each epoch is not possible, since we don't have the whole dataset available at once.
-However, the `--shuffle_buffer_size` argument controls how many examples we can pre-download before shuffling them.
-
-
-```bash
-**torchrun \
- --nproc_per_node 4 run_speech_recognition_ctc_streaming.py \
- --dataset_name="mozilla-foundation/common_voice_17_0" \
- --model_name_or_path="facebook/wav2vec2-xls-r-300m" \
- --tokenizer_name_or_path="anton-l/wav2vec2-tokenizer-turkish" \
- --dataset_config_name="tr" \
- --train_split_name="train+validation" \
- --eval_split_name="test" \
- --output_dir="wav2vec2-xls-r-common_voice-tr-ft" \
- --max_steps="5000" \
- --per_device_train_batch_size="8" \
- --gradient_accumulation_steps="2" \
- --learning_rate="5e-4" \
- --warmup_steps="500" \
- --eval_strategy="steps" \
- --text_column_name="sentence" \
- --save_steps="500" \
- --eval_steps="500" \
- --logging_steps="1" \
- --layerdrop="0.0" \
- --eval_metrics wer cer \
- --save_total_limit="1" \
- --mask_time_prob="0.3" \
- --mask_time_length="10" \
- --mask_feature_prob="0.1" \
- --mask_feature_length="64" \
- --freeze_feature_encoder \
- --chars_to_ignore , ? . ! - \; \: \" “ % ‘ ” � \
- --max_duration_in_seconds="20" \
- --shuffle_buffer_size="500" \
- --fp16 \
- --push_to_hub \
- --do_train --do_eval \
- --gradient_checkpointing**
-```
-
-On 4 V100 GPUs, this script should run in *ca.* 3h 31min and yield a CTC loss of **0.35** and word error rate
-of **0.29**.
-
-### Examples CTC
-
-The following tables present a couple of example runs on the most popular speech-recognition datasets.
-The presented performances are by no means optimal as no hyper-parameter tuning was done. Nevertheless,
-they can serve as a baseline to improve upon.
-
-
-#### TIMIT CTC
-
-- [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)
-
-| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
-|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
-| [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)| - | [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 0.21 | - | 1 GPU TITAN RTX | 32min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned/blob/main/run.sh) |
-| [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)| - | [wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) | 0.21 | - | 1 GPU TITAN RTX | 32min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-base-timit-fine-tuned/blob/main/run.sh) |
-| [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)| - | [unispeech-large-1500h-cv](https://huggingface.co/microsoft/unispeech-large-1500h-cv) | 0.22 | - | 1 GPU TITAN RTX | 35min | [here](https://huggingface.co/patrickvonplaten/unispeech-large-1500h-cv-timit) | [run.sh](https://huggingface.co/patrickvonplaten/unispeech-large-1500h-cv-timit/blob/main/run.sh) |
-| [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)| - | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 0.30 | - | 1 GPU TITAN RTX | 28min | [here](https://huggingface.co/patrickvonplaten/sew-small-100k-timit) | [run.sh](https://huggingface.co/patrickvonplaten/sew-small-100k-timit/blob/main/run.sh) |
-| [TIMIT](https://huggingface.co/datasets/timit-asr/timit_asr)| - | [ntu-spml/distilhubert](https://huggingface.co/ntu-spml/distilhubert) | 0.68 | - | 1 GPU TITAN RTX | 26min | [here](https://huggingface.co/patrickvonplaten/distilhubert-timit) | [run.sh](https://huggingface.co/patrickvonplaten/distilhubert-timit/blob/main/run.sh) |
-
-
-#### Librispeech CTC
-
-- [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)
-
-| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
-|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [microsoft/wavlm-large](https://huggingface.co/microsoft/wavlm-large) | 0.049 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-large) | [run.sh](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-large/blob/main/run.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [microsoft/wavlm-base-plus](https://huggingface.co/microsoft/wavlm-base-plus) | 0.068 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-base-plus) | [run.sh](https://huggingface.co/patrickvonplaten/wavlm-libri-clean-100h-base-plus/blob/main/run.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) | 0.042 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) | 0.042 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [facebook/hubert-large-ll60k](https://huggingface.co/facebook/hubert-large-ll60k) | 0.088 | - | 8 GPU V100 | 1h30min | [here](https://huggingface.co/patrickvonplaten/hubert-librispeech-clean-100h-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/hubert-librispeech-clean-100h-demo-dist/blob/main/run.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)| `"clean"` - `"train.100"` | [asapp/sew-mid-100k](https://huggingface.co/asapp/sew-mid-100k) | 0.167 | | 8 GPU V100 | 54min | [here](https://huggingface.co/patrickvonplaten/sew-mid-100k-librispeech-clean-100h-ft) | [run.sh](https://huggingface.co/patrickvonplaten/sew-mid-100k-librispeech-clean-100h-ft/blob/main/run.sh) |
-
-
-#### Common Voice CTC
-
-- [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)
-
-| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
-|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
-| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"tr"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.099 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-tr-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-tr-phoneme/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"it"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.077 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-it-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-it-phoneme/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/mozilla-foundation/common_voice_3_0)| `"sv-SE"` | [facebook/wav2vec2-large-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | - | 0.099 | 8 GPU V100 | 23min | [here](https://huggingface.co/patrickvonplaten/xls-r-300m-sv-phoneme) | [run.sh](https://huggingface.co/patrickvonplaten/xls-r-300m-sv-phoneme/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.36 | - | 8 GPU V100 | 18min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo-dist) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo-dist/blob/main/run_dist.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.31 | - | 8 GPU V100 | 1h05 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-xlsr-53-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xlsr-53-common_voice-tr-ft/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.35 | - | 1 GPU V100 | 1h20min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-common_voice-tr-demo/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.31 | - | 8 GPU V100 | 1h05 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-300m-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-300m-common_voice-tr-ft/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` | [facebook/wav2vec2-xls-r-1b](https://huggingface.co/facebook/wav2vec2-xls-r-1b) | 0.21 | - | 2 GPU Titan 24 GB RAM | 15h10 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-xls-r-1b-common_voice-tr-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-large-xls-r-1b-common_voice-tr-ft/blob/main/run.sh) |
-| [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice)| `"tr"` in streaming mode | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.29 | - | 4 GPU V100 | 3h31 | [here](https://huggingface.co/anton-l/wav2vec2-xls-r-common_voice-tr-ft-stream) | [run.sh](https://huggingface.co/anton-l/wav2vec2-xls-r-common_voice-tr-ft-stream/blob/main/run.sh) |
-
-
-#### Multilingual Librispeech CTC
-
-- [Multilingual Librispeech](https://huggingface.co/datasets/facebook/multilingual_librispeech)
-
-| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
-|-------|------------------------------|-------------|---------------|---------------|----------------------|-------------| -------------| ------- |
-| [Multilingual Librispeech](https://huggingface.co/datasets/facebook/multilingual_librispeech)| `"german"` | [facebook/wav2vec2-large-xlsr-53](https://huggingface.co/facebook/wav2vec2-large-xlsr-53) | 0.13 | - | 1 GPU Titan 24 GB RAM | 15h04 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-xlsr-53-300m-mls-german-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-xlsr-53-300m-mls-german-ft/blob/main/run.sh) |
-| [Multilingual Librispeech](https://huggingface.co/datasets/facebook/multilingual_librispeech)| `"german"` | [facebook/wav2vec2-xls-r-300m](https://huggingface.co/facebook/wav2vec2-xls-r-300m) | 0.15 | - | 1 GPU Titan 24 GB RAM | 15h04 | [here](https://huggingface.co/patrickvonplaten/wav2vec2-300m-mls-german-ft) | [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-300m-mls-german-ft/blob/main/run.sh) |
-
-## Connectionist Temporal Classification With Adapters
-
-The script [`run_speech_recognition_ctc_adapter.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py) can be used to fine-tune adapter layers for [Wav2Vec2-like models like MMS](https://huggingface.co/docs/transformers/main/en/model_doc/mms) for automatic speech recognition.
-
-### MMS Model
-
-The [Massive Multilingual Speech (MMS) model](https://huggingface.co/facebook/mms-1b-all) has been pre-trained and fine-tuned
-on 1000+ languages. The model makes use of adapter attention layers to fine-tune only a small part
-of the model on a specific language. The model already comes with fine-tuned adapter layers for 1000+ languages and
-can be used for inference for 1000+ languages out of the box.
-
-However, for improved performance or more specific use cases one can re-initialize the adapter weights, freeze all
-other weights and fine-tune them on a specific dataset as shown in the [example below](#examples-ctc-adapter).
-
-Note that the adapter weights include low dimensional linear layers for every attention block as well as the final language
-model head layers.
-
-### Examples CTC Adapter
-
-In the following we will look at how one can fine-tune adapter weights for any of the
-[MMS CTC checkpoints](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&other=mms&sort=downloads) in less than 1 hour.
-
-#### Common Voice CTC Adapter
-
-As in the examples [above](#examples-ctc), we fine-tune on Common Voice's 6 dataset in Turkish as an example.
-Contrary to [`run_speech_recognition_ctc.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py) before there is a `--target_language` which has to be defined to state for which
-language or concept the adapter layers shall be trained. The adapter weights will then
-accordingly be called `adapter.{/wav2vec2-2-bart-base
-cd wav2vec2-2-bart-base
-```
-
-Next, run the following script **inside** the just cloned repo:
-
-```python
-from transformers import SpeechEncoderDecoderModel, AutoFeatureExtractor, AutoTokenizer, Wav2Vec2Processor
-
-# checkpoints to leverage
-encoder_id = "facebook/wav2vec2-base"
-decoder_id = "facebook/bart-base"
-
-# load and save speech-encoder-decoder model
-# set some hyper-parameters for training and evaluation
-model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(encoder_id, decoder_id, encoder_add_adapter=True, encoder_feat_proj_dropout=0.0, encoder_layerdrop=0.0, max_length=200, num_beams=5)
-model.config.decoder_start_token_id = model.decoder.config.bos_token_id
-model.config.pad_token_id = model.decoder.config.pad_token_id
-model.config.eos_token_id = model.decoder.config.eos_token_id
-model.save_pretrained("./")
-
-# load and save processor
-feature_extractor = AutoFeatureExtractor.from_pretrained(encoder_id)
-tokenizer = AutoTokenizer.from_pretrained(decoder_id)
-processor = Wav2Vec2Processor(feature_extractor, tokenizer)
-processor.save_pretrained("./")
-```
-
-Finally, we can upload all files:
-```bash
-git lfs install
-git add . && git commit -m "upload model files" && git push
-```
-
-and link the official `run_speech_recognition_seq2seq.py` script to the folder:
-
-```bash
-ln -s $(realpath /examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py) ./
-```
-
-Note that we have added a randomly initialized _adapter layer_ to `wav2vec2-base` with the argument
-`encoder_add_adapter=True`. This adapter sub-samples the output sequence of
-`wav2vec2-base` along the time dimension. By default, a single
-output vector of `wav2vec2-base` has a receptive field of *ca.* 25ms (*cf.*
-Section *4.2* of the [official Wav2Vec2 paper](https://huggingface.co/papers/2006.11477)), which represents a little less a single character. On the other hand, BART
-makes use of a sentence-piece tokenizer as an input processor, so that a single
-hidden vector of `bart-base` represents *ca.* 4 characters. To better align the
-receptive field of the *Wav2Vec2* output vectors with *BART*'s hidden-states in the cross-attention
-mechanism, we further subsample *Wav2Vec2*'s output by a factor of 8 by
-adding a convolution-based adapter.
-
-Having warm-started the speech-encoder-decoder model under `/wav2vec2-2-bart`, we can now fine-tune it on the task of speech recognition.
-
-In the script [`run_speech_recognition_seq2seq`], we load the warm-started model,
-feature extractor, and tokenizer, process a speech recognition dataset,
-and subsequently make use of the [`Seq2SeqTrainer`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.Seq2SeqTrainer) to train our system.
-Note that it is important to align the target transcriptions with the decoder's vocabulary. For example, the [`Librispeech`](https://huggingface.co/datasets/openslr/librispeech_asr) dataset only contains capitalized letters in the transcriptions,
-whereas BART was pretrained mostly on normalized text. Thus, it is recommended to add the argument
-`--do_lower_case` to the fine-tuning script when using a warm-started `SpeechEncoderDecoderModel`.
-The model is fine-tuned on the standard cross-entropy language modeling
-loss for sequence-to-sequence (just like *T5* or *BART* in natural language processing).
-
----
-**NOTE**
-
-If you encounter problems with data preprocessing by setting `--preprocessing_num_workers` > 1,
-you might want to set the environment variable `OMP_NUM_THREADS` to 1 as follows:
-
-```bash
-OMP_NUM_THREADS=1 python run_speech_recognition_ctc ...
-```
-
-If the environment variable is not set, the training script might freeze, *i.e.* see: https://github.com/pytorch/audio/issues/1021#issuecomment-726915239.
-
----
-
-#### Single GPU Seq2Seq
-
-The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) using a single GPU in half-precision.
-
-```bash
-python run_speech_recognition_seq2seq.py \
- --dataset_name="openslr/librispeech_asr" \
- --model_name_or_path="./" \
- --dataset_config_name="clean" \
- --train_split_name="train.100" \
- --eval_split_name="validation" \
- --output_dir="./" \
- --preprocessing_num_workers="16" \
- --length_column_name="input_length" \
- --num_train_epochs="5" \
- --per_device_train_batch_size="8" \
- --per_device_eval_batch_size="8" \
- --gradient_accumulation_steps="8" \
- --learning_rate="3e-4" \
- --warmup_steps="400" \
- --eval_strategy="steps" \
- --text_column_name="text" \
- --save_steps="400" \
- --eval_steps="400" \
- --logging_steps="10" \
- --save_total_limit="1" \
- --freeze_feature_encoder \
- --gradient_checkpointing \
- --fp16 \
- --train_sampling_strategy group_by_length \
- --predict_with_generate \
- --generation_max_length="40" \
- --generation_num_beams="1" \
- --do_train --do_eval \
- --do_lower_case
-```
-
-On a single V100 GPU, this script should run in *ca.* 5 hours and yield a
-cross-entropy loss of **0.405** and word error rate of **0.0728**.
-
-#### Multi GPU Seq2Seq
-
-The following command shows how to fine-tune [XLSR-Wav2Vec2](https://huggingface.co/transformers/main/model_doc/xlsr_wav2vec2.html) on [Common Voice](https://huggingface.co/datasets/legacy-datasets/common_voice) using 8 GPUs in half-precision.
-
-```bash
-torchrun \
- --nproc_per_node 8 run_speech_recognition_seq2seq.py \
- --dataset_name="openslr/librispeech_asr" \
- --model_name_or_path="./" \
- --dataset_config_name="clean" \
- --train_split_name="train.100" \
- --eval_split_name="validation" \
- --output_dir="./" \
- --preprocessing_num_workers="16" \
- --length_column_name="input_length" \
- --num_train_epochs="5" \
- --per_device_train_batch_size="8" \
- --per_device_eval_batch_size="8" \
- --gradient_accumulation_steps="1" \
- --learning_rate="3e-4" \
- --warmup_steps="400" \
- --eval_strategy="steps" \
- --text_column_name="text" \
- --save_steps="400" \
- --eval_steps="400" \
- --logging_steps="10" \
- --save_total_limit="1" \
- --freeze_feature_encoder \
- --gradient_checkpointing \
- --fp16 \
- --train_sampling_strategy group_by_length \
- --predict_with_generate \
- --do_train --do_eval \
- --do_lower_case
-```
-
-On 8 V100 GPUs, this script should run in *ca.* 45 minutes and yield a cross-entropy loss of **0.405** and word error rate of **0.0728**
-
-### Examples Seq2Seq
-
-#### Librispeech Seq2Seq
-
-- [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr)
-
-| Dataset | Dataset Config | Pretrained Model | Word error rate on eval | Phoneme error rate on eval | GPU setup | Training time | Fine-tuned Model & Logs | Command to reproduce |
-|----------------------------------------------------------------|---------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------|-------------------------|----------------------------|------------|---------------|-----------------------------------------------------------------------|-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr) | `"clean"` - `"train.100"` | [facebook/wav2vec2-base](https://huggingface.co/facebook/wav2vec2-base) and [facebook/bart-base](https://huggingface.co/facebook/bart-base) | 0.0728 | - | 8 GPU V100 | 45min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base) | [create_model.py](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base/blob/main/create_model.py) & [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-base/blob/main/run_librispeech.sh) |
-| [Librispeech](https://huggingface.co/datasets/openslr/librispeech_asr) | `"clean"` - `"train.100"` | [facebook/wav2vec2-large-lv60](https://huggingface.co/facebook/wav2vec2-large-lv60) and [facebook/bart-large](https://huggingface.co/facebook/bart-large) | 0.0486 | - | 8 GPU V100 | 1h20min | [here](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large) | [create_model.py](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large/blob/main/create_model.py) & [run.sh](https://huggingface.co/patrickvonplaten/wav2vec2-2-bart-large/blob/main/run_librispeech.sh) |
diff --git a/examples/pytorch/speech-recognition/requirements.txt b/examples/pytorch/speech-recognition/requirements.txt
deleted file mode 100644
index 4137ea02ad76..000000000000
--- a/examples/pytorch/speech-recognition/requirements.txt
+++ /dev/null
@@ -1,6 +0,0 @@
-datasets[audio] >= 1.18.0
-torch >= 1.5
-torchaudio
-librosa
-jiwer
-evaluate
diff --git a/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py b/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py
deleted file mode 100755
index aa63dcbe11fe..000000000000
--- a/examples/pytorch/speech-recognition/run_speech_recognition_ctc.py
+++ /dev/null
@@ -1,813 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets[audio] >= 1.18.0",
-# "torch >= 1.5",
-# "torchaudio",
-# "librosa",
-# "jiwer",
-# "evaluate",
-# ]
-# ///
-
-"""Fine-tuning a 🤗 Transformers CTC model for automatic speech recognition"""
-
-import functools
-import json
-import logging
-import os
-import re
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import torch
-from datasets import DatasetDict, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoFeatureExtractor,
- AutoModelForCTC,
- AutoProcessor,
- AutoTokenizer,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.trainer_utils import is_main_process
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version(
- "datasets>=1.18.0",
- "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt",
-)
-
-
-logger = logging.getLogger(__name__)
-
-
-def list_field(default=None, metadata=None):
- return field(default_factory=lambda: default, metadata=metadata)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- tokenizer_name_or_path: str | None = field(
- default=None,
- metadata={"help": "Path to pretrained tokenizer or tokenizer identifier from huggingface.co/models"},
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- freeze_feature_encoder: bool = field(
- default=True,
- metadata={"help": "Whether to freeze the feature encoder layers of the model."},
- )
- attention_dropout: float = field(
- default=0.0,
- metadata={"help": "The dropout ratio for the attention probabilities."},
- )
- activation_dropout: float = field(
- default=0.0,
- metadata={"help": "The dropout ratio for activations inside the fully connected layer."},
- )
- feat_proj_dropout: float = field(default=0.0, metadata={"help": "The dropout ratio for the projected features."})
- hidden_dropout: float = field(
- default=0.0,
- metadata={
- "help": "The dropout probability for all fully connected layers in the embeddings, encoder, and pooler."
- },
- )
- final_dropout: float = field(
- default=0.0,
- metadata={"help": "The dropout probability for the final projection layer."},
- )
- mask_time_prob: float = field(
- default=0.05,
- metadata={
- "help": (
- "Probability of each feature vector along the time axis to be chosen as the start of the vector "
- "span to be masked. Approximately ``mask_time_prob * sequence_length // mask_time_length`` feature "
- "vectors will be masked along the time axis."
- )
- },
- )
- mask_time_length: int = field(
- default=10,
- metadata={"help": "Length of vector span to mask along the time axis."},
- )
- mask_feature_prob: float = field(
- default=0.0,
- metadata={
- "help": (
- "Probability of each feature vector along the feature axis to be chosen as the start of the vectorspan"
- " to be masked. Approximately ``mask_feature_prob * sequence_length // mask_feature_length`` feature"
- " bins will be masked along the time axis."
- )
- },
- )
- mask_feature_length: int = field(
- default=10,
- metadata={"help": "Length of vector span to mask along the feature axis."},
- )
- layerdrop: float = field(default=0.0, metadata={"help": "The LayerDrop probability."})
- ctc_loss_reduction: str | None = field(
- default="mean",
- metadata={"help": "The way the ctc loss should be reduced. Should be one of 'mean' or 'sum'."},
- )
- ctc_zero_infinity: bool | None = field(
- default=False,
- metadata={
- "help": "Whether to zero infinite losses and the associated gradients of `torch.nn.CTCLoss`. Infinite losses mainly"
- " occur when the inputs are too short to be aligned to the targets."
- },
- )
- add_adapter: bool | None = field(
- default=False,
- metadata={
- "help": "Whether a convolutional attention network should be stacked on top of the Wav2Vec2Bert Encoder. Can be very"
- "useful to downsample the output length."
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
-
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- dataset_name: str = field(
- metadata={"help": "Path or name of the dataset (cf `load_dataset` method of the Datasets library)."}
- )
- dataset_config_name: str = field(
- default=None,
- metadata={
- "help": "The configuration name of the dataset to use (cf `load_dataset` method of the Datasets library)."
- },
- )
- train_split_name: str = field(
- default="train+validation",
- metadata={
- "help": (
- "The name of the training data set split to use (via the datasets library). Defaults to "
- "'train+validation'"
- )
- },
- )
- eval_split_name: str = field(
- default="test",
- metadata={
- "help": "The name of the evaluation data set split to use (via the datasets library). Defaults to 'test'"
- },
- )
- audio_column_name: str = field(
- default="audio",
- metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
- )
- text_column_name: str = field(
- default="text",
- metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
- )
- overwrite_cache: bool = field(
- default=False,
- metadata={"help": "Overwrite the cached preprocessed datasets or not."},
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of validation examples to this "
- "value if set."
- )
- },
- )
- chars_to_ignore: list[str] | None = list_field(
- default=None,
- metadata={"help": "A list of characters to remove from the transcripts."},
- )
- eval_metrics: list[str] = list_field(
- default=["wer"],
- metadata={"help": "A list of metrics the model should be evaluated on. E.g. `'wer cer'`"},
- )
- max_duration_in_seconds: float = field(
- default=20.0,
- metadata={
- "help": (
- "Filter audio files that are longer than `max_duration_in_seconds` seconds to"
- " 'max_duration_in_seconds`"
- )
- },
- )
- min_duration_in_seconds: float = field(
- default=0.0,
- metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"},
- )
- preprocessing_only: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to only do data preprocessing and skip training. This is especially useful when data"
- " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
- " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
- " can consequently be loaded in distributed training"
- )
- },
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- unk_token: str = field(
- default="[UNK]",
- metadata={"help": "The unk token for the tokenizer"},
- )
- pad_token: str = field(
- default="[PAD]",
- metadata={"help": "The padding token for the tokenizer"},
- )
- word_delimiter_token: str = field(
- default="|",
- metadata={"help": "The word delimiter token for the tokenizer"},
- )
- phoneme_language: str | None = field(
- default=None,
- metadata={
- "help": (
- "The target language that should be used be"
- " passed to the tokenizer for tokenization. Note that"
- " this is only relevant if the model classifies the"
- " input audio to a sequence of phoneme sequences."
- )
- },
- )
-
-
-@dataclass
-class DataCollatorCTCWithPadding:
- """
- Data collator that will dynamically pad the inputs received.
- Args:
- processor (:class:`~transformers.AutoProcessor`)
- The processor used for processing the data.
- padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
- Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
- among:
- * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
- sequence if provided).
- * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
- maximum acceptable input length for the model if that argument is not provided.
- * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
- different lengths).
- max_length (:obj:`int`, `optional`):
- Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
- max_length_labels (:obj:`int`, `optional`):
- Maximum length of the ``labels`` returned list and optionally padding length (see above).
- pad_to_multiple_of (:obj:`int`, `optional`):
- If set will pad the sequence to a multiple of the provided value.
- This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
- 7.5 (Volta).
- """
-
- processor: AutoProcessor
- padding: bool | str = "longest"
- pad_to_multiple_of: int | None = None
- pad_to_multiple_of_labels: int | None = None
- feature_extractor_input_name: str | None = "input_values"
-
- def __call__(self, features: list[dict[str, list[int] | torch.Tensor]]) -> dict[str, torch.Tensor]:
- # split inputs and labels since they have to be of different lengths and need
- # different padding methods
- input_features = [
- {self.feature_extractor_input_name: feature[self.feature_extractor_input_name]} for feature in features
- ]
- label_features = [{"input_ids": feature["labels"]} for feature in features]
-
- batch = self.processor.pad(
- input_features,
- padding=self.padding,
- pad_to_multiple_of=self.pad_to_multiple_of,
- return_tensors="pt",
- )
-
- labels_batch = self.processor.pad(
- labels=label_features,
- padding=self.padding,
- pad_to_multiple_of=self.pad_to_multiple_of_labels,
- return_tensors="pt",
- )
-
- # replace padding with -100 to ignore loss correctly
- labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
-
- batch["labels"] = labels
- if "attention_mask" in batch:
- batch["attention_mask"] = batch["attention_mask"].to(torch.long)
-
- return batch
-
-
-def create_vocabulary_from_data(
- datasets: DatasetDict,
- word_delimiter_token: str | None = None,
- unk_token: str | None = None,
- pad_token: str | None = None,
-):
- # Given training and test labels create vocabulary
- def extract_all_chars(batch):
- all_text = " ".join(batch["target_text"])
- vocab = list(set(all_text))
- return {"vocab": [vocab], "all_text": [all_text]}
-
- vocabs = datasets.map(
- extract_all_chars,
- batched=True,
- batch_size=-1,
- keep_in_memory=True,
- remove_columns=datasets["train"].column_names,
- )
-
- # take union of all unique characters in each dataset
- vocab_set = functools.reduce(
- lambda vocab_1, vocab_2: set(vocab_1["vocab"][0]) | set(vocab_2["vocab"][0]),
- vocabs.values(),
- )
-
- vocab_dict = {v: k for k, v in enumerate(sorted(vocab_set))}
-
- # replace white space with delimiter token
- if word_delimiter_token is not None:
- vocab_dict[word_delimiter_token] = vocab_dict[" "]
- del vocab_dict[" "]
-
- # add unk and pad token
- if unk_token is not None:
- vocab_dict[unk_token] = len(vocab_dict)
-
- if pad_token is not None:
- vocab_dict[pad_token] = len(vocab_dict)
-
- return vocab_dict
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
- logger.setLevel(logging.INFO if is_main_process(training_args.local_process_index) else logging.WARN)
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- # Set the verbosity to info of the Transformers logger (on main process only):
- if is_main_process(training_args.local_process_index):
- transformers.utils.logging.set_verbosity_info()
- logger.info("Training/evaluation parameters %s", training_args)
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # 1. First, let's load the dataset
- raw_datasets = DatasetDict()
-
- if training_args.do_train:
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.train_split_name,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- if data_args.audio_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'."
- " Make sure to set `--audio_column_name` to the correct audio column - one of"
- f" {', '.join(raw_datasets['train'].column_names)}."
- )
-
- if data_args.text_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--text_column_name` to the correct text column - one of "
- f"{', '.join(raw_datasets['train'].column_names)}."
- )
-
- if data_args.max_train_samples is not None:
- raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
-
- if training_args.do_eval:
- raw_datasets["eval"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.eval_split_name,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- if data_args.max_eval_samples is not None:
- raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
-
- # 2. We remove some special characters from the datasets
- # that make training complicated and do not help in transcribing the speech
- # E.g. characters, such as `,` and `.` do not really have an acoustic characteristic
- # that could be easily picked up by the model
- chars_to_ignore_regex = (
- f"[{''.join(data_args.chars_to_ignore)}]" if data_args.chars_to_ignore is not None else None
- )
- text_column_name = data_args.text_column_name
-
- def remove_special_characters(batch):
- if chars_to_ignore_regex is not None:
- batch["target_text"] = re.sub(chars_to_ignore_regex, "", batch[text_column_name]).lower() + " "
- else:
- batch["target_text"] = batch[text_column_name].lower() + " "
- return batch
-
- with training_args.main_process_first(desc="dataset map special characters removal"):
- raw_datasets = raw_datasets.map(
- remove_special_characters,
- remove_columns=[text_column_name],
- desc="remove special characters from datasets",
- )
-
- # save special tokens for tokenizer
- word_delimiter_token = data_args.word_delimiter_token
- unk_token = data_args.unk_token
- pad_token = data_args.pad_token
-
- # 3. Next, let's load the config as we might need it to create
- # the tokenizer
- # load config
- config = AutoConfig.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # 4. Next, if no tokenizer file is defined,
- # we create the vocabulary of the model by extracting all unique characters from
- # the training and evaluation datasets
- # We need to make sure that only first rank saves vocabulary
- # make sure all processes wait until vocab is created
- tokenizer_name_or_path = model_args.tokenizer_name_or_path
- tokenizer_kwargs = {}
- if tokenizer_name_or_path is None:
- # save vocab in training output dir
- tokenizer_name_or_path = training_args.output_dir
-
- vocab_file = os.path.join(tokenizer_name_or_path, "vocab.json")
-
- with training_args.main_process_first():
- if os.path.isfile(vocab_file):
- try:
- os.remove(vocab_file)
- except OSError:
- # in shared file-systems it might be the case that
- # two processes try to delete the vocab file at the some time
- pass
-
- with training_args.main_process_first(desc="dataset map vocabulary creation"):
- if not os.path.isfile(vocab_file):
- os.makedirs(tokenizer_name_or_path, exist_ok=True)
- vocab_dict = create_vocabulary_from_data(
- raw_datasets,
- word_delimiter_token=word_delimiter_token,
- unk_token=unk_token,
- pad_token=pad_token,
- )
-
- # save vocab dict to be loaded into tokenizer
- with open(vocab_file, "w", encoding="utf-8") as file:
- json.dump(vocab_dict, file)
-
- tokenizer_kwargs = {
- "config": config,
- "tokenizer_type": config.model_type,
- "unk_token": unk_token,
- "pad_token": pad_token,
- "word_delimiter_token": word_delimiter_token,
- }
-
- # 5. Now we can instantiate the feature extractor, tokenizer and model
- # Note for distributed training, the .from_pretrained methods guarantee that only
- # one local process can concurrently download model & vocab.
-
- # load feature_extractor and tokenizer
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- **tokenizer_kwargs,
- )
- feature_extractor = AutoFeatureExtractor.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # adapt config
- config.update(
- {
- "feat_proj_dropout": model_args.feat_proj_dropout,
- "attention_dropout": model_args.attention_dropout,
- "hidden_dropout": model_args.hidden_dropout,
- "final_dropout": model_args.final_dropout,
- "mask_time_prob": model_args.mask_time_prob,
- "mask_time_length": model_args.mask_time_length,
- "mask_feature_prob": model_args.mask_feature_prob,
- "mask_feature_length": model_args.mask_feature_length,
- "gradient_checkpointing": training_args.gradient_checkpointing,
- "layerdrop": model_args.layerdrop,
- "ctc_loss_reduction": model_args.ctc_loss_reduction,
- "ctc_zero_infinity": model_args.ctc_zero_infinity,
- "pad_token_id": tokenizer.pad_token_id,
- "vocab_size": len(tokenizer),
- "activation_dropout": model_args.activation_dropout,
- "add_adapter": model_args.add_adapter,
- }
- )
-
- # create model
- model = AutoModelForCTC.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- config=config,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # freeze encoder
- if model_args.freeze_feature_encoder:
- model.freeze_feature_encoder()
-
- # 6. Now we preprocess the datasets including loading the audio, resampling and normalization
- # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
- # so that we just need to set the correct target sampling rate and normalize the input
- # via the `feature_extractor`
-
- # make sure that dataset decodes audio with correct sampling rate
- dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
- if dataset_sampling_rate != feature_extractor.sampling_rate:
- raw_datasets = raw_datasets.cast_column(
- data_args.audio_column_name,
- datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate),
- )
-
- # derive max & min input length for sample rate & max duration
- max_input_length = data_args.max_duration_in_seconds * feature_extractor.sampling_rate
- min_input_length = data_args.min_duration_in_seconds * feature_extractor.sampling_rate
- audio_column_name = data_args.audio_column_name
- num_workers = data_args.preprocessing_num_workers
- feature_extractor_input_name = feature_extractor.model_input_names[0]
-
- # `phoneme_language` is only relevant if the model is fine-tuned on phoneme classification
- phoneme_language = data_args.phoneme_language
-
- # Preprocessing the datasets.
- # We need to read the audio files as arrays and tokenize the targets.
- def prepare_dataset(batch):
- # load audio
- sample = batch[audio_column_name]
-
- inputs = feature_extractor(sample["array"], sampling_rate=sample["sampling_rate"])
- batch[feature_extractor_input_name] = getattr(inputs, feature_extractor_input_name)[0]
- # take length of raw audio waveform
- batch["input_length"] = len(sample["array"].squeeze())
-
- # encode targets
- additional_kwargs = {}
- if phoneme_language is not None:
- additional_kwargs["phonemizer_lang"] = phoneme_language
-
- batch["labels"] = tokenizer(batch["target_text"], **additional_kwargs).input_ids
- return batch
-
- with training_args.main_process_first(desc="dataset map preprocessing"):
- vectorized_datasets = raw_datasets.map(
- prepare_dataset,
- remove_columns=next(iter(raw_datasets.values())).column_names,
- num_proc=num_workers,
- desc="preprocess datasets",
- )
-
- def is_audio_in_length_range(length):
- return length > min_input_length and length < max_input_length
-
- # filter data that is shorter than min_input_length
- vectorized_datasets = vectorized_datasets.filter(
- is_audio_in_length_range,
- num_proc=num_workers,
- input_columns=["input_length"],
- )
-
- # 7. Next, we can prepare the training.
- # Let's use word error rate (WER) as our evaluation metric,
- # instantiate a data collator and the trainer
-
- # Define evaluation metrics during training, *i.e.* word error rate, character error rate
- eval_metrics = {metric: evaluate.load(metric, cache_dir=model_args.cache_dir) for metric in data_args.eval_metrics}
-
- # for large datasets it is advised to run the preprocessing on a
- # single machine first with ``args.preprocessing_only`` since there will mostly likely
- # be a timeout when running the script in distributed mode.
- # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
- # cached dataset
- if data_args.preprocessing_only:
- logger.info(f"Data preprocessing finished. Files cached at {vectorized_datasets.cache_files}")
- return
-
- # For languages like Chinese with large vocabulary size, we need to discard logits
- # and only keep the argmax, otherwise we run out of memory during evaluation.
- def preprocess_logits_for_metrics(logits, labels):
- pred_ids = torch.argmax(logits, dim=-1)
- return pred_ids, labels
-
- def compute_metrics(pred):
- pred_ids = pred.predictions[0]
- pred.label_ids[pred.label_ids == -100] = tokenizer.pad_token_id
-
- pred_str = tokenizer.batch_decode(pred_ids)
- # we do not want to group tokens when computing the metrics
- label_str = tokenizer.batch_decode(pred.label_ids, group_tokens=False)
-
- metrics = {k: v.compute(predictions=pred_str, references=label_str) for k, v in eval_metrics.items()}
-
- return metrics
-
- # Now save everything to be able to create a single processor later
- # make sure all processes wait until data is saved
- with training_args.main_process_first():
- # only the main process saves them
- if is_main_process(training_args.local_process_index):
- # save feature extractor, tokenizer and config
- feature_extractor.save_pretrained(training_args.output_dir)
- tokenizer.save_pretrained(training_args.output_dir)
- config.save_pretrained(training_args.output_dir)
-
- processor = AutoProcessor.from_pretrained(training_args.output_dir)
-
- # Instantiate custom data collator
- data_collator = DataCollatorCTCWithPadding(
- processor=processor, feature_extractor_input_name=feature_extractor_input_name
- )
-
- # Initialize Trainer
- trainer = Trainer(
- model=model,
- data_collator=data_collator,
- args=training_args,
- compute_metrics=compute_metrics,
- train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
- eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
- processing_class=processor,
- preprocess_logits_for_metrics=preprocess_logits_for_metrics,
- )
-
- # 8. Finally, we can start training
-
- # Training
- if training_args.do_train:
- # use last checkpoint if exist
- if os.path.isdir(model_args.model_name_or_path):
- checkpoint = model_args.model_name_or_path
- else:
- checkpoint = None
-
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples
- if data_args.max_train_samples is not None
- else len(vectorized_datasets["train"])
- )
- metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- results = {}
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate()
- max_eval_samples = (
- data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
- )
- metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- config_name = data_args.dataset_config_name if data_args.dataset_config_name is not None else "na"
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "automatic-speech-recognition",
- "tags": ["automatic-speech-recognition", data_args.dataset_name],
- "dataset_args": (
- f"Config: {config_name}, Training split: {data_args.train_split_name}, Eval split:"
- f" {data_args.eval_split_name}"
- ),
- "dataset": f"{data_args.dataset_name.upper()} - {config_name.upper()}",
- }
- if "common_voice" in data_args.dataset_name:
- kwargs["language"] = config_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
- return results
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py b/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py
deleted file mode 100755
index 561c2413a017..000000000000
--- a/examples/pytorch/speech-recognition/run_speech_recognition_ctc_adapter.py
+++ /dev/null
@@ -1,811 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2023 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets[audio] >= 1.18.0",
-# "torch >= 1.5",
-# "torchaudio",
-# "librosa",
-# "jiwer",
-# "evaluate",
-# ]
-# ///
-
-"""Fine-tuning a 🤗 Transformers CTC adapter model for automatic speech recognition"""
-
-import functools
-import json
-import logging
-import os
-import re
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from datasets import DatasetDict, load_dataset
-from safetensors.torch import save_file as safe_save_file
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoFeatureExtractor,
- AutoModelForCTC,
- AutoProcessor,
- AutoTokenizer,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.models.wav2vec2.modeling_wav2vec2 import WAV2VEC2_ADAPTER_SAFE_FILE
-from transformers.trainer_utils import is_main_process
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version(
- "datasets>=1.18.0",
- "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt",
-)
-
-
-logger = logging.getLogger(__name__)
-
-
-def list_field(default=None, metadata=None):
- return field(default_factory=lambda: default, metadata=metadata)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- tokenizer_name_or_path: str | None = field(
- default=None,
- metadata={"help": "Path to pretrained tokenizer or tokenizer identifier from huggingface.co/models"},
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- final_dropout: float = field(
- default=0.0,
- metadata={"help": "The dropout probability for the final projection layer."},
- )
- mask_time_prob: float = field(
- default=0.05,
- metadata={
- "help": (
- "Probability of each feature vector along the time axis to be chosen as the start of the vector "
- "span to be masked. Approximately ``mask_time_prob * sequence_length // mask_time_length`` feature "
- "vectors will be masked along the time axis."
- )
- },
- )
- mask_time_length: int = field(
- default=10,
- metadata={"help": "Length of vector span to mask along the time axis."},
- )
- mask_feature_prob: float = field(
- default=0.0,
- metadata={
- "help": (
- "Probability of each feature vector along the feature axis to be chosen as the start of the vectorspan"
- " to be masked. Approximately ``mask_feature_prob * sequence_length // mask_feature_length`` feature"
- " bins will be masked along the time axis."
- )
- },
- )
- mask_feature_length: int = field(
- default=10,
- metadata={"help": "Length of vector span to mask along the feature axis."},
- )
- layerdrop: float = field(default=0.0, metadata={"help": "The LayerDrop probability."})
- ctc_loss_reduction: str | None = field(
- default="mean",
- metadata={"help": "The way the ctc loss should be reduced. Should be one of 'mean' or 'sum'."},
- )
- adapter_attn_dim: int = field(
- default=16,
- metadata={
- "help": "The hidden dimension of the adapter layers that will be randomly initialized and trained. The higher the dimension, the more capacity is given to the adapter weights. Note that only the adapter weights are fine-tuned."
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
-
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- dataset_name: str = field(
- metadata={"help": "Path or name of the dataset (cf `load_dataset` method of the Datasets library)."}
- )
- target_language: str = field(
- metadata={
- "help": (
- "The target language on which the adapter attention layers"
- " should be trained on in ISO 693-3 code, e.g. `tur` for Turkish"
- " Wav2Vec2's MMS ISO codes can be looked up here: https://dl.fbaipublicfiles.com/mms/misc/language_coverage_mms.html"
- " If you are not training the adapter layers on a language, simply choose"
- " another acronym that fits your data."
- )
- },
- )
- dataset_config_name: str = field(
- default=None,
- metadata={
- "help": "The configuration name of the dataset to use (cf `load_dataset` method of the Datasets library)."
- },
- )
- train_split_name: str = field(
- default="train+validation",
- metadata={
- "help": (
- "The name of the training data set split to use (via the datasets library). Defaults to "
- "'train+validation'"
- )
- },
- )
- eval_split_name: str = field(
- default="test",
- metadata={
- "help": "The name of the evaluation data set split to use (via the datasets library). Defaults to 'test'"
- },
- )
- audio_column_name: str = field(
- default="audio",
- metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
- )
- text_column_name: str = field(
- default="text",
- metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
- )
- overwrite_cache: bool = field(
- default=False,
- metadata={"help": "Overwrite the cached preprocessed datasets or not."},
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of validation examples to this "
- "value if set."
- )
- },
- )
- chars_to_ignore: list[str] | None = list_field(
- default=None,
- metadata={"help": "A list of characters to remove from the transcripts."},
- )
- eval_metrics: list[str] = list_field(
- default=["wer"],
- metadata={"help": "A list of metrics the model should be evaluated on. E.g. `'wer cer'`"},
- )
- max_duration_in_seconds: float = field(
- default=20.0,
- metadata={
- "help": (
- "Filter audio files that are longer than `max_duration_in_seconds` seconds to"
- " 'max_duration_in_seconds`"
- )
- },
- )
- min_duration_in_seconds: float = field(
- default=0.0,
- metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"},
- )
- preprocessing_only: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to only do data preprocessing and skip training. This is especially useful when data"
- " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
- " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
- " can consequently be loaded in distributed training"
- )
- },
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- unk_token: str = field(
- default="[UNK]",
- metadata={"help": "The unk token for the tokenizer"},
- )
- pad_token: str = field(
- default="[PAD]",
- metadata={"help": "The padding token for the tokenizer"},
- )
- word_delimiter_token: str = field(
- default="|",
- metadata={"help": "The word delimiter token for the tokenizer"},
- )
- overwrite_lang_vocab: bool = field(
- default=False,
- metadata={"help": ("If :obj:`True`, will overwrite existing `target_language` vocabulary of tokenizer.")},
- )
-
-
-@dataclass
-class DataCollatorCTCWithPadding:
- """
- Data collator that will dynamically pad the inputs received.
- Args:
- processor (:class:`~transformers.AutoProcessor`)
- The processor used for processing the data.
- padding (:obj:`bool`, :obj:`str` or :class:`~transformers.tokenization_utils_base.PaddingStrategy`, `optional`, defaults to :obj:`True`):
- Select a strategy to pad the returned sequences (according to the model's padding side and padding index)
- among:
- * :obj:`True` or :obj:`'longest'`: Pad to the longest sequence in the batch (or no padding if only a single
- sequence if provided).
- * :obj:`'max_length'`: Pad to a maximum length specified with the argument :obj:`max_length` or to the
- maximum acceptable input length for the model if that argument is not provided.
- * :obj:`False` or :obj:`'do_not_pad'` (default): No padding (i.e., can output a batch with sequences of
- different lengths).
- max_length (:obj:`int`, `optional`):
- Maximum length of the ``input_values`` of the returned list and optionally padding length (see above).
- max_length_labels (:obj:`int`, `optional`):
- Maximum length of the ``labels`` returned list and optionally padding length (see above).
- pad_to_multiple_of (:obj:`int`, `optional`):
- If set will pad the sequence to a multiple of the provided value.
- This is especially useful to enable the use of Tensor Cores on NVIDIA hardware with compute capability >=
- 7.5 (Volta).
- """
-
- processor: AutoProcessor
- padding: bool | str = "longest"
- pad_to_multiple_of: int | None = None
- pad_to_multiple_of_labels: int | None = None
-
- def __call__(self, features: list[dict[str, list[int] | torch.Tensor]]) -> dict[str, torch.Tensor]:
- # split inputs and labels since they have to be of different lengths and need
- # different padding methods
- input_features = [{"input_values": feature["input_values"]} for feature in features]
- label_features = [{"input_ids": feature["labels"]} for feature in features]
-
- batch = self.processor.pad(
- input_features,
- padding=self.padding,
- pad_to_multiple_of=self.pad_to_multiple_of,
- return_tensors="pt",
- )
-
- labels_batch = self.processor.pad(
- labels=label_features,
- padding=self.padding,
- pad_to_multiple_of=self.pad_to_multiple_of_labels,
- return_tensors="pt",
- )
-
- # replace padding with -100 to ignore loss correctly
- labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
-
- batch["labels"] = labels
- if "attention_mask" in batch:
- batch["attention_mask"] = batch["attention_mask"].to(torch.long)
-
- return batch
-
-
-def create_vocabulary_from_data(
- datasets: DatasetDict,
- word_delimiter_token: str | None = None,
- unk_token: str | None = None,
- pad_token: str | None = None,
-):
- # Given training and test labels create vocabulary
- def extract_all_chars(batch):
- all_text = " ".join(batch["target_text"])
- vocab = list(set(all_text))
- return {"vocab": [vocab], "all_text": [all_text]}
-
- vocabs = datasets.map(
- extract_all_chars,
- batched=True,
- batch_size=-1,
- keep_in_memory=True,
- remove_columns=datasets["train"].column_names,
- )
-
- # take union of all unique characters in each dataset
- vocab_set = functools.reduce(
- lambda vocab_1, vocab_2: set(vocab_1["vocab"][0]) | set(vocab_2["vocab"][0]),
- vocabs.values(),
- )
-
- vocab_dict = {v: k for k, v in enumerate(sorted(vocab_set))}
-
- # replace white space with delimiter token
- if word_delimiter_token is not None:
- vocab_dict[word_delimiter_token] = vocab_dict[" "]
- del vocab_dict[" "]
-
- # add unk and pad token
- if unk_token is not None:
- vocab_dict[unk_token] = len(vocab_dict)
-
- if pad_token is not None:
- vocab_dict[pad_token] = len(vocab_dict)
-
- return vocab_dict
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
- logger.setLevel(logging.INFO if is_main_process(training_args.local_process_index) else logging.WARN)
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- # Set the verbosity to info of the Transformers logger (on main process only):
- if is_main_process(training_args.local_process_index):
- transformers.utils.logging.set_verbosity_info()
- logger.info("Training/evaluation parameters %s", training_args)
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # 1. First, let's load the dataset
- raw_datasets = DatasetDict()
-
- if training_args.do_train:
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.train_split_name,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- if data_args.audio_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'."
- " Make sure to set `--audio_column_name` to the correct audio column - one of"
- f" {', '.join(raw_datasets['train'].column_names)}."
- )
-
- if data_args.text_column_name not in raw_datasets["train"].column_names:
- raise ValueError(
- f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--text_column_name` to the correct text column - one of "
- f"{', '.join(raw_datasets['train'].column_names)}."
- )
-
- if data_args.max_train_samples is not None:
- raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
-
- if training_args.do_eval:
- raw_datasets["eval"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.eval_split_name,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- if data_args.max_eval_samples is not None:
- raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
-
- # 2. We remove some special characters from the datasets
- # that make training complicated and do not help in transcribing the speech
- # E.g. characters, such as `,` and `.` do not really have an acoustic characteristic
- # that could be easily picked up by the model
- chars_to_ignore_regex = (
- f"[{''.join(data_args.chars_to_ignore)}]" if data_args.chars_to_ignore is not None else None
- )
- text_column_name = data_args.text_column_name
-
- def remove_special_characters(batch):
- if chars_to_ignore_regex is not None:
- batch["target_text"] = re.sub(chars_to_ignore_regex, "", batch[text_column_name]).lower() + " "
- else:
- batch["target_text"] = batch[text_column_name].lower() + " "
- return batch
-
- with training_args.main_process_first(desc="dataset map special characters removal"):
- raw_datasets = raw_datasets.map(
- remove_special_characters,
- remove_columns=[text_column_name],
- desc="remove special characters from datasets",
- )
-
- # save special tokens for tokenizer
- word_delimiter_token = data_args.word_delimiter_token
- unk_token = data_args.unk_token
- pad_token = data_args.pad_token
-
- # 3. Next, let's load the config as we might need it to create
- # the tokenizer
- # load config
- config = AutoConfig.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # 4. Next, if no tokenizer file is defined,
- # we create the vocabulary of the model by extracting all unique characters from
- # the training and evaluation datasets
- # We need to make sure that only first rank saves vocabulary
- # make sure all processes wait until vocab is created
- tokenizer_name_or_path = model_args.tokenizer_name_or_path
- tokenizer_kwargs = {}
-
- vocab_dict = {}
- if tokenizer_name_or_path is not None:
- # load vocabulary of other adapter languages so that new language can be appended
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
- vocab_dict = tokenizer.vocab.copy()
- if tokenizer.target_lang is None:
- raise ValueError("Make sure to load a multi-lingual tokenizer with a set target language.")
-
- if data_args.target_language in tokenizer.vocab and not data_args.overwrite_lang_vocab:
- logger.info(
- "Adapter language already exists."
- " Skipping vocabulary creating. If you want to create a new vocabulary"
- f" for {data_args.target_language} make sure to add '--overwrite_lang_vocab'"
- )
- else:
- tokenizer_name_or_path = None
-
- if tokenizer_name_or_path is None:
- # save vocab in training output dir
- tokenizer_name_or_path = training_args.output_dir
-
- vocab_file = os.path.join(tokenizer_name_or_path, "vocab.json")
-
- with training_args.main_process_first():
- if os.path.isfile(vocab_file):
- try:
- os.remove(vocab_file)
- except OSError:
- # in shared file-systems it might be the case that
- # two processes try to delete the vocab file at the some time
- pass
-
- with training_args.main_process_first(desc="dataset map vocabulary creation"):
- if not os.path.isfile(vocab_file):
- os.makedirs(tokenizer_name_or_path, exist_ok=True)
- lang_dict = create_vocabulary_from_data(
- raw_datasets,
- word_delimiter_token=word_delimiter_token,
- unk_token=unk_token,
- pad_token=pad_token,
- )
-
- # if we doing adapter language training, save
- # vocab with adapter language
- if data_args.target_language is not None:
- vocab_dict[data_args.target_language] = lang_dict
-
- # save vocab dict to be loaded into tokenizer
- with open(vocab_file, "w", encoding="utf-8") as file:
- json.dump(vocab_dict, file)
-
- tokenizer_kwargs = {
- "config": config,
- "tokenizer_type": config.model_type,
- "unk_token": unk_token,
- "pad_token": pad_token,
- "word_delimiter_token": word_delimiter_token,
- "target_lang": data_args.target_language,
- }
-
- # 5. Now we can instantiate the feature extractor, tokenizer and model
- # Note for distributed training, the .from_pretrained methods guarantee that only
- # one local process can concurrently download model & vocab.
-
- # load feature_extractor and tokenizer
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- **tokenizer_kwargs,
- )
- feature_extractor = AutoFeatureExtractor.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- )
-
- # adapt config
- config.update(
- {
- "final_dropout": model_args.final_dropout,
- "mask_time_prob": model_args.mask_time_prob,
- "mask_time_length": model_args.mask_time_length,
- "mask_feature_prob": model_args.mask_feature_prob,
- "mask_feature_length": model_args.mask_feature_length,
- "gradient_checkpointing": training_args.gradient_checkpointing,
- "layerdrop": model_args.layerdrop,
- "ctc_loss_reduction": model_args.ctc_loss_reduction,
- "pad_token_id": tokenizer.pad_token_id,
- "vocab_size": len(tokenizer),
- "adapter_attn_dim": model_args.adapter_attn_dim,
- }
- )
-
- # create model
- model = AutoModelForCTC.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- config=config,
- token=data_args.token,
- trust_remote_code=data_args.trust_remote_code,
- ignore_mismatched_sizes=True,
- )
-
- # if attn adapter is defined, freeze all non-adapter weights
- if model.config.adapter_attn_dim is not None:
- model.init_adapter_layers()
- # first we freeze the whole base model
- model.freeze_base_model()
-
- # next we unfreeze all adapter layers
- adapter_weights = model._get_adapters()
- for param in adapter_weights.values():
- param.requires_grad = True
-
- # 6. Now we preprocess the datasets including loading the audio, resampling and normalization
- # Thankfully, `datasets` takes care of automatically loading and resampling the audio,
- # so that we just need to set the correct target sampling rate and normalize the input
- # via the `feature_extractor`
-
- # make sure that dataset decodes audio with correct sampling rate
- dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
- if dataset_sampling_rate != feature_extractor.sampling_rate:
- raw_datasets = raw_datasets.cast_column(
- data_args.audio_column_name,
- datasets.features.Audio(sampling_rate=feature_extractor.sampling_rate),
- )
-
- # derive max & min input length for sample rate & max duration
- max_input_length = data_args.max_duration_in_seconds * feature_extractor.sampling_rate
- min_input_length = data_args.min_duration_in_seconds * feature_extractor.sampling_rate
- audio_column_name = data_args.audio_column_name
- num_workers = data_args.preprocessing_num_workers
-
- # Preprocessing the datasets.
- # We need to read the audio files as arrays and tokenize the targets.
- def prepare_dataset(batch):
- # load audio
- sample = batch[audio_column_name]
-
- inputs = feature_extractor(sample["array"], sampling_rate=sample["sampling_rate"])
- batch["input_values"] = inputs.input_values[0]
- batch["input_length"] = len(batch["input_values"])
-
- # encode targets
- batch["labels"] = tokenizer(batch["target_text"]).input_ids
- return batch
-
- with training_args.main_process_first(desc="dataset map preprocessing"):
- vectorized_datasets = raw_datasets.map(
- prepare_dataset,
- remove_columns=next(iter(raw_datasets.values())).column_names,
- num_proc=num_workers,
- desc="preprocess datasets",
- )
-
- def is_audio_in_length_range(length):
- return length > min_input_length and length < max_input_length
-
- # filter data that is shorter than min_input_length
- vectorized_datasets = vectorized_datasets.filter(
- is_audio_in_length_range,
- num_proc=num_workers,
- input_columns=["input_length"],
- )
-
- # 7. Next, we can prepare the training.
- # Let's use word error rate (WER) as our evaluation metric,
- # instantiate a data collator and the trainer
-
- # Define evaluation metrics during training, *i.e.* word error rate, character error rate
- eval_metrics = {metric: evaluate.load(metric, cache_dir=model_args.cache_dir) for metric in data_args.eval_metrics}
-
- # for large datasets it is advised to run the preprocessing on a
- # single machine first with ``args.preprocessing_only`` since there will mostly likely
- # be a timeout when running the script in distributed mode.
- # In a second step ``args.preprocessing_only`` can then be set to `False` to load the
- # cached dataset
- if data_args.preprocessing_only:
- logger.info(f"Data preprocessing finished. Files cached at {vectorized_datasets.cache_files}")
- return
-
- def compute_metrics(pred):
- pred_logits = pred.predictions
- pred_ids = np.argmax(pred_logits, axis=-1)
-
- pred.label_ids[pred.label_ids == -100] = tokenizer.pad_token_id
-
- pred_str = tokenizer.batch_decode(pred_ids)
- # we do not want to group tokens when computing the metrics
- label_str = tokenizer.batch_decode(pred.label_ids, group_tokens=False)
-
- metrics = {k: v.compute(predictions=pred_str, references=label_str) for k, v in eval_metrics.items()}
-
- return metrics
-
- # Now save everything to be able to create a single processor later
- # make sure all processes wait until data is saved
- with training_args.main_process_first():
- # only the main process saves them
- if is_main_process(training_args.local_process_index):
- # save feature extractor, tokenizer and config
- feature_extractor.save_pretrained(training_args.output_dir)
- tokenizer.save_pretrained(training_args.output_dir)
- config.save_pretrained(training_args.output_dir)
-
- processor = AutoProcessor.from_pretrained(training_args.output_dir)
-
- # Instantiate custom data collator
- data_collator = DataCollatorCTCWithPadding(processor=processor)
-
- # Initialize Trainer
- trainer = Trainer(
- model=model,
- data_collator=data_collator,
- args=training_args,
- compute_metrics=compute_metrics,
- train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
- eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
- processing_class=processor,
- )
-
- # 8. Finally, we can start training
-
- # Training
- if training_args.do_train:
- # use last checkpoint if exist
- if os.path.isdir(model_args.model_name_or_path):
- checkpoint = model_args.model_name_or_path
- else:
- checkpoint = None
-
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model()
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples
- if data_args.max_train_samples is not None
- else len(vectorized_datasets["train"])
- )
- metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- results = {}
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate()
- max_eval_samples = (
- data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
- )
- metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Write model card and (optionally) push to hub
- config_name = data_args.dataset_config_name if data_args.dataset_config_name is not None else "na"
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "automatic-speech-recognition",
- "tags": ["automatic-speech-recognition", data_args.dataset_name, "mms"],
- "dataset_args": (
- f"Config: {config_name}, Training split: {data_args.train_split_name}, Eval split:"
- f" {data_args.eval_split_name}"
- ),
- "dataset": f"{data_args.dataset_name.upper()} - {config_name.upper()}",
- }
- if "common_voice" in data_args.dataset_name:
- kwargs["language"] = config_name
-
- # make sure that adapter weights are saved separately
- adapter_file = WAV2VEC2_ADAPTER_SAFE_FILE.format(data_args.target_language)
- adapter_file = os.path.join(training_args.output_dir, adapter_file)
- logger.info(f"Saving adapter weights under {adapter_file}...")
- safe_save_file(model._get_adapters(), adapter_file, metadata={"format": "pt"})
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
- return results
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py b/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py
deleted file mode 100755
index 346851d71b75..000000000000
--- a/examples/pytorch/speech-recognition/run_speech_recognition_seq2seq.py
+++ /dev/null
@@ -1,603 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "datasets[audio] >= 1.18.0",
-# "torch >= 1.5",
-# "torchaudio",
-# "librosa",
-# "jiwer",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for sequence to sequence speech recognition.
-"""
-# You can also adapt this script on your own sequence to sequence speech
-# recognition task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-from typing import Any
-
-import datasets
-import evaluate
-import torch
-from datasets import DatasetDict, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSpeechSeq2Seq,
- AutoProcessor,
- HfArgumentParser,
- Seq2SeqTrainer,
- Seq2SeqTrainingArguments,
- set_seed,
-)
-from transformers.trainer_utils import is_main_process
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version(
- "datasets>=1.18.0",
- "To fix: pip install -r examples/pytorch/speech-recognition/requirements.txt",
-)
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None,
- metadata={"help": "Pretrained config name or path if not the same as model_name"},
- )
- tokenizer_name: str | None = field(
- default=None,
- metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"},
- )
- feature_extractor_name: str | None = field(
- default=None,
- metadata={"help": "feature extractor name or path if not the same as model_name"},
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- freeze_feature_encoder: bool = field(
- default=True,
- metadata={"help": "Whether to freeze the feature encoder layers of the model."},
- )
- freeze_encoder: bool = field(
- default=False,
- metadata={"help": "Whether to freeze the entire encoder of the seq2seq model."},
- )
- apply_spec_augment: bool = field(
- default=False,
- metadata={
- "help": "Whether to apply *SpecAugment* data augmentation to the input features. This is currently only relevant for Wav2Vec2, HuBERT, WavLM and Whisper models."
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- dataset_name: str = field(
- metadata={"help": "Path or name of the dataset (cf `load_dataset` method of the Datasets library)."}
- )
- dataset_config_name: str = field(
- default=None,
- metadata={
- "help": "The configuration name of the dataset to use (cf `load_dataset` method of the Datasets library)."
- },
- )
- overwrite_cache: bool = field(
- default=False,
- metadata={"help": "Overwrite the cached training and evaluation sets"},
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- audio_column_name: str = field(
- default="audio",
- metadata={"help": "The name of the dataset column containing the audio data. Defaults to 'audio'"},
- )
- text_column_name: str = field(
- default="text",
- metadata={"help": "The name of the dataset column containing the text data. Defaults to 'text'"},
- )
- max_duration_in_seconds: float = field(
- default=20.0,
- metadata={
- "help": (
- "Truncate audio files that are longer than `max_duration_in_seconds` seconds to"
- " 'max_duration_in_seconds`"
- )
- },
- )
- min_duration_in_seconds: float = field(
- default=0.0,
- metadata={"help": "Filter audio files that are shorter than `min_duration_in_seconds` seconds"},
- )
- preprocessing_only: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to only do data preprocessing and skip training. This is especially useful when data"
- " preprocessing errors out in distributed training due to timeout. In this case, one should run the"
- " preprocessing in a non-distributed setup with `preprocessing_only=True` so that the cached datasets"
- " can consequently be loaded in distributed training"
- )
- },
- )
- train_split_name: str = field(
- default="train",
- metadata={
- "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
- },
- )
- eval_split_name: str = field(
- default="test",
- metadata={
- "help": "The name of the training data set split to use (via the datasets library). Defaults to 'train'"
- },
- )
- do_lower_case: bool = field(
- default=True,
- metadata={"help": "Whether the target text should be lower cased."},
- )
- language: str = field(
- default=None,
- metadata={
- "help": (
- "Language for multilingual fine-tuning. This argument should be set for multilingual fine-tuning "
- "only. For English speech recognition, it should be set to `None`."
- )
- },
- )
- task: str = field(
- default="transcribe",
- metadata={"help": "Task, either `transcribe` for speech recognition or `translate` for speech translation."},
- )
-
-
-@dataclass
-class DataCollatorSpeechSeq2SeqWithPadding:
- """
- Data collator that will dynamically pad the inputs received.
- Args:
- processor ([`WhisperProcessor`])
- The processor used for processing the data.
- decoder_start_token_id (`int`)
- The begin-of-sentence of the decoder.
- forward_attention_mask (`bool`)
- Whether to return attention_mask.
- """
-
- processor: Any
- decoder_start_token_id: int
- forward_attention_mask: bool
-
- def __call__(self, features: list[dict[str, list[int] | torch.Tensor]]) -> dict[str, torch.Tensor]:
- # split inputs and labels since they have to be of different lengths and need
- # different padding methods
- model_input_name = self.processor.model_input_names[0]
- input_features = [{model_input_name: feature[model_input_name]} for feature in features]
- label_features = [{"input_ids": feature["labels"]} for feature in features]
-
- batch = self.processor.feature_extractor.pad(input_features, return_tensors="pt")
-
- if self.forward_attention_mask:
- batch["attention_mask"] = torch.LongTensor([feature["attention_mask"] for feature in features])
-
- labels_batch = self.processor.tokenizer.pad(label_features, return_tensors="pt")
-
- # replace padding with -100 to ignore loss correctly
- labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
-
- # if bos token is appended in previous tokenization step,
- # cut bos token here as it's append later anyways
- if (labels[:, 0] == self.decoder_start_token_id).all().cpu().item():
- labels = labels[:, 1:]
-
- batch["labels"] = labels
-
- return batch
-
-
-def main():
- # 1. Parse input arguments
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
-
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # 2. Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- logger.setLevel(logging.INFO if is_main_process(training_args.local_process_index) else logging.WARN)
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set the verbosity to info of the Transformers logger (on main process only):
- if is_main_process(training_args.local_process_index):
- transformers.utils.logging.set_verbosity_info()
- logger.info("Training/evaluation parameters %s", training_args)
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # 4. Load dataset
- raw_datasets = DatasetDict()
-
- if training_args.do_train:
- raw_datasets["train"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.train_split_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- if training_args.do_eval:
- raw_datasets["eval"] = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- split=data_args.eval_split_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- if data_args.audio_column_name not in next(iter(raw_datasets.values())).column_names:
- raise ValueError(
- f"--audio_column_name '{data_args.audio_column_name}' not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--audio_column_name` to the correct audio column - one of "
- f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
- )
-
- if data_args.text_column_name not in next(iter(raw_datasets.values())).column_names:
- raise ValueError(
- f"--text_column_name {data_args.text_column_name} not found in dataset '{data_args.dataset_name}'. "
- "Make sure to set `--text_column_name` to the correct text column - one of "
- f"{', '.join(next(iter(raw_datasets.values())).column_names)}."
- )
-
- # 5. Load pretrained model, tokenizer, and feature extractor
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- config = AutoConfig.from_pretrained(
- (model_args.config_name if model_args.config_name else model_args.model_name_or_path),
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # SpecAugment for whisper models
- if getattr(config, "model_type", None) == "whisper":
- config.update({"apply_spec_augment": model_args.apply_spec_augment})
-
- processor = AutoProcessor.from_pretrained(
- model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSpeechSeq2Seq.from_pretrained(
- model_args.model_name_or_path,
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- if model_args.freeze_feature_encoder:
- model.freeze_feature_encoder()
-
- if model_args.freeze_encoder:
- model.freeze_encoder()
- model.model.encoder.gradient_checkpointing = False
-
- if hasattr(model.generation_config, "is_multilingual") and model.generation_config.is_multilingual:
- # We only need to set the language and task ids in a multilingual setting
- processor.tokenizer.set_prefix_tokens(language=data_args.language, task=data_args.task)
- model.generation_config.language = data_args.language
- model.generation_config.task = data_args.task
- elif data_args.language is not None:
- raise ValueError(
- "Setting language token for an English-only checkpoint is not permitted. The language argument should "
- "only be set for multilingual checkpoints."
- )
-
- model.generation_config.forced_decoder_ids = None
- model.config.forced_decoder_ids = None
-
- # 6. Resample speech dataset if necessary
- dataset_sampling_rate = next(iter(raw_datasets.values())).features[data_args.audio_column_name].sampling_rate
- if dataset_sampling_rate != processor.feature_extractor.sampling_rate:
- raw_datasets = raw_datasets.cast_column(
- data_args.audio_column_name,
- datasets.features.Audio(sampling_rate=processor.feature_extractor.sampling_rate),
- )
-
- # 7. Preprocessing the datasets.
- # We need to read the audio files as arrays and tokenize the targets.
- max_input_length = data_args.max_duration_in_seconds * processor.feature_extractor.sampling_rate
- min_input_length = data_args.min_duration_in_seconds * processor.feature_extractor.sampling_rate
- audio_column_name = data_args.audio_column_name
- num_workers = data_args.preprocessing_num_workers
- text_column_name = data_args.text_column_name
- model_input_name = processor.feature_extractor.model_input_names[0]
- do_lower_case = data_args.do_lower_case
- # if SpecAugment is used for whisper models, return attention_mask to guide the mask along time axis
- forward_attention_mask = (
- getattr(config, "model_type", None) == "whisper"
- and getattr(config, "apply_spec_augment", False)
- and getattr(config, "mask_time_prob", 0) > 0
- )
-
- if data_args.max_train_samples is not None:
- raw_datasets["train"] = raw_datasets["train"].select(range(data_args.max_train_samples))
-
- if data_args.max_eval_samples is not None:
- raw_datasets["eval"] = raw_datasets["eval"].select(range(data_args.max_eval_samples))
-
- def prepare_dataset(batch):
- # process audio
- sample = batch[audio_column_name]
- inputs = processor.feature_extractor(
- sample["array"],
- sampling_rate=sample["sampling_rate"],
- return_attention_mask=forward_attention_mask,
- )
- # process audio length
- batch[model_input_name] = inputs.get(model_input_name)[0]
- batch["input_length"] = len(sample["array"])
- if forward_attention_mask:
- batch["attention_mask"] = inputs.get("attention_mask")[0]
-
- # process targets
- input_str = batch[text_column_name].lower() if do_lower_case else batch[text_column_name]
- batch["labels"] = processor.tokenizer(input_str).input_ids
- return batch
-
- with training_args.main_process_first(desc="dataset map pre-processing"):
- vectorized_datasets = raw_datasets.map(
- prepare_dataset,
- remove_columns=next(iter(raw_datasets.values())).column_names,
- num_proc=data_args.preprocessing_num_workers,
- desc="preprocess train dataset",
- )
-
- # filter data that is shorter than min_input_length or longer than
- # max_input_length
- def is_audio_in_length_range(length):
- return length > min_input_length and length < max_input_length
-
- vectorized_datasets = vectorized_datasets.filter(
- is_audio_in_length_range,
- num_proc=num_workers,
- input_columns=["input_length"],
- )
-
- # for large datasets it is advised to run the preprocessing on a
- # single machine first with `args.preprocessing_only` since there will mostly likely
- # be a timeout when running the script in distributed mode.
- # In a second step `args.preprocessing_only` can then be set to `False` to load the
- # cached dataset
- if data_args.preprocessing_only:
- cache = {k: v.cache_files for k, v in vectorized_datasets.items()}
- logger.info(f"Data preprocessing finished. Files cached at {cache}.")
- return
-
- # 8. Load Metric
- metric = evaluate.load("wer", cache_dir=model_args.cache_dir)
-
- def compute_metrics(pred):
- pred_ids = pred.predictions
-
- pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
-
- pred_str = processor.tokenizer.batch_decode(pred_ids, skip_special_tokens=True)
- # we do not want to group tokens when computing the metrics
- label_str = processor.tokenizer.batch_decode(pred.label_ids, skip_special_tokens=True)
-
- wer = metric.compute(predictions=pred_str, references=label_str)
-
- return {"wer": wer}
-
- # 9. Create a single speech processor
- # make sure all processes wait until data is saved
- with training_args.main_process_first():
- # only the main process saves them
- if is_main_process(training_args.local_process_index):
- config.save_pretrained(training_args.output_dir)
-
- # 10. Define data collator
- data_collator = DataCollatorSpeechSeq2SeqWithPadding(
- processor=processor,
- decoder_start_token_id=model.config.decoder_start_token_id,
- forward_attention_mask=forward_attention_mask,
- )
-
- # 11. Initialize Trainer
- trainer = Seq2SeqTrainer(
- model=model,
- args=training_args,
- train_dataset=vectorized_datasets["train"] if training_args.do_train else None,
- eval_dataset=vectorized_datasets["eval"] if training_args.do_eval else None,
- processing_class=processor.feature_extractor,
- data_collator=data_collator,
- compute_metrics=(compute_metrics if training_args.predict_with_generate else None),
- )
-
- # 12. Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the feature extractor too for easy upload
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples
- if data_args.max_train_samples is not None
- else len(vectorized_datasets["train"])
- )
- metrics["train_samples"] = min(max_train_samples, len(vectorized_datasets["train"]))
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # 13. Evaluation
- results = {}
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate(
- metric_key_prefix="eval",
- max_length=training_args.generation_max_length,
- num_beams=training_args.generation_num_beams,
- )
- max_eval_samples = (
- data_args.max_eval_samples if data_args.max_eval_samples is not None else len(vectorized_datasets["eval"])
- )
- metrics["eval_samples"] = min(max_eval_samples, len(vectorized_datasets["eval"]))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # 14. Write Training Stats
- kwargs = {
- "finetuned_from": model_args.model_name_or_path,
- "tasks": "automatic-speech-recognition",
- }
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
- return results
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/summarization/README.md b/examples/pytorch/summarization/README.md
deleted file mode 100644
index d82809ffe99b..000000000000
--- a/examples/pytorch/summarization/README.md
+++ /dev/null
@@ -1,194 +0,0 @@
-
-
-## Summarization
-
-This directory contains examples for finetuning and evaluating transformers on summarization tasks.
-Please tag @patil-suraj with any issues/unexpected behaviors, or send a PR!
-For deprecated `bertabs` instructions, see https://github.com/huggingface/transformers-research-projects/blob/main/bertabs/README.md.
-For the old `finetune_trainer.py` and related utils, see [`examples/legacy/seq2seq`](https://github.com/huggingface/transformers/blob/main/examples/legacy/seq2seq).
-
-### Supported Architectures
-
-- `BartForConditionalGeneration`
-- `FSMTForConditionalGeneration` (translation only)
-- `MBartForConditionalGeneration`
-- `MarianMTModel`
-- `PegasusForConditionalGeneration`
-- `T5ForConditionalGeneration`
-- `MT5ForConditionalGeneration`
-
-`run_summarization.py` is a lightweight example of how to download and preprocess a dataset from the [🤗 Datasets](https://github.com/huggingface/datasets) library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
-
-For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files
-and you also will find examples of these below.
-
-## With Trainer
-
-Here is an example on a summarization task:
-```bash
-python run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --dataset_name abisee/cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-Only T5 models `google-t5/t5-small`, `google-t5/t5-base`, `google-t5/t5-large`, `google-t5/t5-3b` and `google-t5/t5-11b` must use an additional argument: `--source_prefix "summarize: "`.
-
-We used CNN/DailyMail dataset in this example as `google-t5/t5-small` was trained on it and one can get good scores even when pre-training with a very small sample.
-
-Extreme Summarization (XSum) Dataset is another commonly used dataset for the task of summarization. To use it replace `--dataset_name abisee/cnn_dailymail --dataset_config "3.0.0"` with `--dataset_name EdinburghNLP/xsum`.
-
-And here is how you would use it on your own files, after adjusting the values for the arguments
-`--train_file`, `--validation_file`, `--text_column` and `--summary_column` to match your setup:
-
-```bash
-python run_summarization.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --train_file path_to_csv_or_jsonlines_file \
- --validation_file path_to_csv_or_jsonlines_file \
- --source_prefix "summarize: " \
- --output_dir /tmp/tst-summarization \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-The task of summarization supports custom CSV and JSONLINES formats.
-
-#### Custom CSV Files
-
-If it's a csv file the training and validation files should have a column for the inputs texts and a column for the summaries.
-
-If the csv file has just two columns as in the following example:
-
-```csv
-text,summary
-"I'm sitting here in a boring room. It's just another rainy Sunday afternoon. I'm wasting my time I got nothing to do. I'm hanging around I'm waiting for you. But nothing ever happens. And I wonder","I'm sitting in a room where I'm waiting for something to happen"
-"I see trees so green, red roses too. I see them bloom for me and you. And I think to myself what a wonderful world. I see skies so blue and clouds so white. The bright blessed day, the dark sacred night. And I think to myself what a wonderful world.","I'm a gardener and I'm a big fan of flowers."
-"Christmas time is here. Happiness and cheer. Fun for all that children call. Their favorite time of the year. Snowflakes in the air. Carols everywhere. Olden times and ancient rhymes. Of love and dreams to share","It's that time of year again."
-```
-
-The first column is assumed to be for `text` and the second is for summary.
-
-If the csv file has multiple columns, you can then specify the names of the columns to use:
-
-```bash
- --text_column text_column_name \
- --summary_column summary_column_name \
-```
-
-For example if the columns were:
-
-```csv
-id,date,text,summary
-```
-
-and you wanted to select only `text` and `summary`, then you'd pass these additional arguments:
-
-```bash
- --text_column text \
- --summary_column summary \
-```
-
-#### Custom JSONLINES Files
-
-The second supported format is jsonlines. Here is an example of a jsonlines custom data file.
-
-
-```json
-{"text": "I'm sitting here in a boring room. It's just another rainy Sunday afternoon. I'm wasting my time I got nothing to do. I'm hanging around I'm waiting for you. But nothing ever happens. And I wonder", "summary": "I'm sitting in a room where I'm waiting for something to happen"}
-{"text": "I see trees so green, red roses too. I see them bloom for me and you. And I think to myself what a wonderful world. I see skies so blue and clouds so white. The bright blessed day, the dark sacred night. And I think to myself what a wonderful world.", "summary": "I'm a gardener and I'm a big fan of flowers."}
-{"text": "Christmas time is here. Happiness and cheer. Fun for all that children call. Their favorite time of the year. Snowflakes in the air. Carols everywhere. Olden times and ancient rhymes. Of love and dreams to share", "summary": "It's that time of year again."}
-```
-
-Same as with the CSV files, by default the first value will be used as the text record and the second as the summary record. Therefore you can use any key names for the entries, in this example `text` and `summary` were used.
-
-And as with the CSV files, you can specify which values to select from the file, by explicitly specifying the corresponding key names. In our example this again would be:
-
-```bash
- --text_column text \
- --summary_column summary \
-```
-
-## With Accelerate
-
-Based on the script [`run_summarization_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/summarization/run_summarization_no_trainer.py).
-
-Like `run_summarization.py`, this script allows you to fine-tune any of the models supported on a
-summarization task, the main difference is that this
-script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
-the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-python run_summarization_no_trainer.py \
- --model_name_or_path google-t5/t5-small \
- --dataset_name abisee/cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir ~/tmp/tst-summarization
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_summarization_no_trainer.py \
- --model_name_or_path google-t5/t5-small \
- --dataset_name abisee/cnn_dailymail \
- --dataset_config "3.0.0" \
- --source_prefix "summarize: " \
- --output_dir ~/tmp/tst-summarization
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/examples/pytorch/summarization/requirements.txt b/examples/pytorch/summarization/requirements.txt
deleted file mode 100644
index 8db3440bebad..000000000000
--- a/examples/pytorch/summarization/requirements.txt
+++ /dev/null
@@ -1,9 +0,0 @@
-accelerate >= 0.12.0
-datasets >= 1.8.0
-sentencepiece != 0.1.92
-protobuf
-rouge-score
-nltk >= 3.9
-py7zr
-torch >= 1.3
-evaluate
diff --git a/examples/pytorch/summarization/run_summarization.py b/examples/pytorch/summarization/run_summarization.py
deleted file mode 100755
index 4400e6ac4e9f..000000000000
--- a/examples/pytorch/summarization/run_summarization.py
+++ /dev/null
@@ -1,769 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "rouge-score",
-# "nltk >= 3.9",
-# "py7zr",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for sequence to sequence.
-"""
-# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import nltk # Here to have a nice missing dependency error message early on
-import numpy as np
-from datasets import load_dataset
-from filelock import FileLock
-from huggingface_hub import is_offline_mode
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSeq2SeqLM,
- AutoTokenizer,
- DataCollatorForSeq2Seq,
- HfArgumentParser,
- MBart50Tokenizer,
- MBart50TokenizerFast,
- MBartTokenizer,
- MBartTokenizerFast,
- Seq2SeqTrainer,
- Seq2SeqTrainingArguments,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/summarization/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-# NLTK 3.9 replaced the pickled punkt data with punkt_tab, which is what sent_tokenize loads
-try:
- nltk.data.find("tokenizers/punkt_tab")
-except (LookupError, OSError):
- if is_offline_mode():
- raise LookupError(
- "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
- )
- with FileLock(".lock") as lock:
- nltk.download("punkt_tab", quiet=True)
-
-# A list of all multilingual tokenizer which require lang attribute.
-MULTILINGUAL_TOKENIZERS = [MBartTokenizer, MBartTokenizerFast, MBart50Tokenizer, MBart50TokenizerFast]
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- resize_position_embeddings: bool | None = field(
- default=None,
- metadata={
- "help": (
- "Whether to automatically resize the position embeddings if `max_source_length` exceeds "
- "the model's position embeddings."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- lang: str | None = field(default=None, metadata={"help": "Language id for summarization."})
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- text_column: str | None = field(
- default=None,
- metadata={"help": "The name of the column in the datasets containing the full texts (for summarization)."},
- )
- summary_column: str | None = field(
- default=None,
- metadata={"help": "The name of the column in the datasets containing the summaries (for summarization)."},
- )
- train_file: str | None = field(
- default=None, metadata={"help": "The input training data file (a jsonlines or csv file)."}
- )
- validation_file: str | None = field(
- default=None,
- metadata={
- "help": (
- "An optional input evaluation data file to evaluate the metrics (rouge) on (a jsonlines or csv file)."
- )
- },
- )
- test_file: str | None = field(
- default=None,
- metadata={
- "help": "An optional input test data file to evaluate the metrics (rouge) on (a jsonlines or csv file)."
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_source_length: int | None = field(
- default=1024,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- max_target_length: int | None = field(
- default=128,
- metadata={
- "help": (
- "The maximum total sequence length for target text after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- val_max_target_length: int | None = field(
- default=None,
- metadata={
- "help": (
- "The maximum total sequence length for validation target text after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
- "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
- "during ``evaluate`` and ``predict``."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to model maximum sentence length. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
- "efficient on GPU but very bad for TPU."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- num_beams: int | None = field(
- default=1,
- metadata={
- "help": (
- "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
- "which is used during ``evaluate`` and ``predict``."
- )
- },
- )
- ignore_pad_token_for_loss: bool = field(
- default=True,
- metadata={
- "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
- },
- )
- source_prefix: str | None = field(
- default=None, metadata={"help": "A prefix to add before every source text (useful for T5 models)."}
- )
-
- forced_bos_token: str | None = field(
- default=None,
- metadata={
- "help": (
- "The token to force as the first generated token after the decoder_start_token_id. "
- "Useful for multilingual models like mBART where the first generated token"
- "needs to be the target language token (Usually it is the target language token)"
- )
- },
- )
-
- def __post_init__(self):
- if (
- self.dataset_name is None
- and self.train_file is None
- and self.validation_file is None
- and self.test_file is None
- ):
- raise ValueError("Need either a dataset name or a training, validation, or test file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- if self.test_file is not None:
- extension = self.test_file.split(".")[-1]
- assert extension in ["csv", "json"], "`test_file` should be a csv or a json file."
- if self.val_max_target_length is None:
- self.val_max_target_length = self.max_target_length
-
-
-summarization_name_mapping = {
- "amazon_reviews_multi": ("review_body", "review_title"),
- "big_patent": ("description", "abstract"),
- "cnn_dailymail": ("article", "highlights"),
- "orange_sum": ("text", "summary"),
- "pn_summary": ("article", "summary"),
- "psc": ("extract_text", "summary_text"),
- "samsum": ("dialogue", "summary"),
- "thaisum": ("body", "summary"),
- "xglue": ("news_body", "news_title"),
- "xsum": ("document", "summary"),
- "wiki_summary": ("article", "highlights"),
- "multi_news": ("document", "summary"),
-}
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- if data_args.source_prefix is None and model_args.model_name_or_path in [
- "google-t5/t5-small",
- "google-t5/t5-base",
- "google-t5/t5-large",
- "google-t5/t5-3b",
- "google-t5/t5-11b",
- ]:
- logger.warning(
- "You're running a t5 model but didn't provide a source prefix, which is the expected, e.g. with "
- "`--source_prefix 'summarize: ' `"
- )
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files this script will use the first column for the full texts and the second column for the
- # summaries (unless you specify column names for this with the `text_column` and `summary_column` arguments).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- raw_datasets = load_dataset(
- extension,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSeq2SeqLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
- if isinstance(tokenizer, MBartTokenizer):
- model.config.decoder_start_token_id = tokenizer.lang_code_to_id[data_args.lang]
- else:
- model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(data_args.lang)
-
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- if (
- hasattr(model.config, "max_position_embeddings")
- and model.config.max_position_embeddings < data_args.max_source_length
- ):
- if model_args.resize_position_embeddings is None:
- logger.warning(
- "Increasing the model's number of position embedding vectors from"
- f" {model.config.max_position_embeddings} to {data_args.max_source_length}."
- )
- model.resize_position_embeddings(data_args.max_source_length)
- elif model_args.resize_position_embeddings:
- model.resize_position_embeddings(data_args.max_source_length)
- else:
- raise ValueError(
- f"`--max_source_length` is set to {data_args.max_source_length}, but the model only has"
- f" {model.config.max_position_embeddings} position encodings. Consider either reducing"
- f" `--max_source_length` to {model.config.max_position_embeddings} or to automatically resize the"
- " model's position encodings by passing `--resize_position_embeddings`."
- )
-
- prefix = data_args.source_prefix if data_args.source_prefix is not None else ""
-
- # Preprocessing the datasets.
- # We need to tokenize inputs and targets.
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- column_names = raw_datasets["train"].column_names
- elif training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- column_names = raw_datasets["validation"].column_names
- elif training_args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- column_names = raw_datasets["test"].column_names
- else:
- logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
- return
-
- if isinstance(tokenizer, tuple(MULTILINGUAL_TOKENIZERS)):
- assert data_args.lang is not None, (
- f"{tokenizer.__class__.__name__} is a multilingual tokenizer which requires --lang argument"
- )
-
- tokenizer.src_lang = data_args.lang
- tokenizer.tgt_lang = data_args.lang
-
- # For multilingual translation models like mBART-50 and M2M100 we need to force the target language token
- # as the first generated token. We ask the user to explicitly provide this as --forced_bos_token argument.
- forced_bos_token_id = (
- tokenizer.lang_code_to_id[data_args.forced_bos_token] if data_args.forced_bos_token is not None else None
- )
- model.config.forced_bos_token_id = forced_bos_token_id
-
- # Get the column names for input/target.
- dataset_columns = summarization_name_mapping.get(data_args.dataset_name)
- if data_args.text_column is None:
- text_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
- else:
- text_column = data_args.text_column
- if text_column not in column_names:
- raise ValueError(
- f"--text_column' value '{data_args.text_column}' needs to be one of: {', '.join(column_names)}"
- )
- if data_args.summary_column is None:
- summary_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
- else:
- summary_column = data_args.summary_column
- if summary_column not in column_names:
- raise ValueError(
- f"--summary_column' value '{data_args.summary_column}' needs to be one of: {', '.join(column_names)}"
- )
-
- # Temporarily set max_target_length for training.
- max_target_length = data_args.max_target_length
- padding = "max_length" if data_args.pad_to_max_length else False
-
- if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
- logger.warning(
- "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
- f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
- )
-
- def preprocess_function(examples):
- # remove pairs where at least one record is None
-
- inputs, targets = [], []
- for i in range(len(examples[text_column])):
- if examples[text_column][i] and examples[summary_column][i]:
- inputs.append(examples[text_column][i])
- targets.append(examples[summary_column][i])
-
- inputs = [prefix + inp for inp in inputs]
- model_inputs = tokenizer(inputs, max_length=data_args.max_source_length, padding=padding, truncation=True)
-
- # Tokenize targets with the `text_target` keyword argument
- labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and data_args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- model_inputs["labels"] = labels["input_ids"]
- return model_inputs
-
- if training_args.do_train:
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
-
- if training_args.do_eval:
- max_target_length = data_args.val_max_target_length
- eval_dataset = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if training_args.do_predict:
- max_target_length = data_args.val_max_target_length
- predict_dataset = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
-
- # Data collator
- label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
- data_collator = DataCollatorForSeq2Seq(
- tokenizer,
- model=model,
- label_pad_token_id=label_pad_token_id,
- pad_to_multiple_of=8 if training_args.fp16 else None,
- )
-
- # Metric
- metric = evaluate.load("rouge", cache_dir=model_args.cache_dir)
-
- def postprocess_text(preds, labels):
- preds = [pred.strip() for pred in preds]
- labels = [label.strip() for label in labels]
-
- # rougeLSum expects newline after each sentence
- preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
- labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
-
- return preds, labels
-
- def compute_metrics(eval_preds):
- preds, labels = eval_preds
- if isinstance(preds, tuple):
- preds = preds[0]
- # Replace -100s used for padding as we can't decode them
- preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
- decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
- labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
- decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
-
- # Some simple post-processing
- decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
-
- result = metric.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
- result = {k: round(v * 100, 4) for k, v in result.items()}
- prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
- result["gen_len"] = np.mean(prediction_lens)
- return result
-
- # Override the decoding parameters of Seq2SeqTrainer
- training_args.generation_max_length = (
- training_args.generation_max_length
- if training_args.generation_max_length is not None
- else data_args.val_max_target_length
- )
- training_args.generation_num_beams = (
- data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
- )
-
- # Initialize our Trainer
- trainer = Seq2SeqTrainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics if training_args.predict_with_generate else None,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- results = {}
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- if isinstance(eval_dataset, dict):
- metrics = {}
- for eval_ds_name, eval_ds in eval_dataset.items():
- dataset_metrics = trainer.evaluate(eval_dataset=eval_ds, metric_key_prefix=f"eval_{eval_ds_name}")
- metrics.update(dataset_metrics)
- else:
- metrics = trainer.evaluate(metric_key_prefix="eval")
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- if training_args.do_predict:
- logger.info("*** Predict ***")
-
- predict_results = trainer.predict(predict_dataset, metric_key_prefix="predict")
- metrics = predict_results.metrics
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- if trainer.is_world_process_zero():
- if training_args.predict_with_generate:
- predictions = predict_results.predictions
- predictions = np.where(predictions != -100, predictions, tokenizer.pad_token_id)
- predictions = tokenizer.batch_decode(
- predictions, skip_special_tokens=True, clean_up_tokenization_spaces=True
- )
- predictions = [pred.strip() for pred in predictions]
- output_prediction_file = os.path.join(training_args.output_dir, "generated_predictions.txt")
- with open(output_prediction_file, "w", encoding="utf-8") as writer:
- writer.write("\n".join(predictions))
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "summarization"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if data_args.lang is not None:
- kwargs["language"] = data_args.lang
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
- return results
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/summarization/run_summarization_no_trainer.py b/examples/pytorch/summarization/run_summarization_no_trainer.py
deleted file mode 100644
index 662b67aa3b32..000000000000
--- a/examples/pytorch/summarization/run_summarization_no_trainer.py
+++ /dev/null
@@ -1,814 +0,0 @@
-#!/usr/bin/env python
-# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "rouge-score",
-# "nltk >= 3.9",
-# "py7zr",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning a 🤗 Transformers model on summarization.
-"""
-# You can also adapt this script on your own summarization task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import nltk
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from filelock import FileLock
-from huggingface_hub import HfApi, is_offline_mode
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForSeq2SeqLM,
- AutoTokenizer,
- DataCollatorForSeq2Seq,
- SchedulerType,
- get_scheduler,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/summarization/requirements.txt")
-
-# You should update this to your particular problem to have better documentation of `model_type`
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-# NLTK 3.9 replaced the pickled punkt data with punkt_tab, which is what sent_tokenize loads
-try:
- nltk.data.find("tokenizers/punkt_tab")
-except (LookupError, OSError):
- if is_offline_mode():
- raise LookupError(
- "Offline mode: run this script without TRANSFORMERS_OFFLINE first to download nltk data files"
- )
- with FileLock(".lock") as lock:
- nltk.download("punkt_tab", quiet=True)
-
-summarization_name_mapping = {
- "amazon_reviews_multi": ("review_body", "review_title"),
- "big_patent": ("description", "abstract"),
- "cnn_dailymail": ("article", "highlights"),
- "orange_sum": ("text", "summary"),
- "pn_summary": ("article", "summary"),
- "psc": ("extract_text", "summary_text"),
- "samsum": ("dialogue", "summary"),
- "thaisum": ("body", "summary"),
- "xglue": ("news_body", "news_title"),
- "xsum": ("document", "summary"),
- "wiki_summary": ("article", "highlights"),
-}
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a summarization task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--ignore_pad_token_for_loss",
- type=bool,
- default=True,
- help="Whether to ignore the tokens corresponding to padded labels in the loss computation or not.",
- )
- parser.add_argument(
- "--max_source_length",
- type=int,
- default=1024,
- help=(
- "The maximum total input sequence length after "
- "tokenization.Sequences longer than this will be truncated, sequences shorter will be padded."
- ),
- )
- parser.add_argument(
- "--source_prefix",
- type=str,
- default=None,
- help="A prefix to add before every source text (useful for T5 models).",
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--max_target_length",
- type=int,
- default=128,
- help=(
- "The maximum total sequence length for target text after "
- "tokenization. Sequences longer than this will be truncated, sequences shorter will be padded. "
- "during ``evaluate`` and ``predict``."
- ),
- )
- parser.add_argument(
- "--val_max_target_length",
- type=int,
- default=None,
- help=(
- "The maximum total sequence length for validation "
- "target text after tokenization.Sequences longer than this will be truncated, sequences shorter will be "
- "padded. Will default to `max_target_length`.This argument is also used to override the ``max_length`` "
- "param of ``model.generate``, which is used during ``evaluate`` and ``predict``."
- ),
- )
- parser.add_argument(
- "--num_beams",
- type=int,
- default=None,
- help=(
- "Number of beams to use for evaluation. This argument will be "
- "passed to ``model.generate``, which is used during ``evaluate`` and ``predict``."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--text_column",
- type=str,
- default=None,
- help="The name of the column in the datasets containing the full texts (for summarization).",
- )
- parser.add_argument(
- "--summary_column",
- type=str,
- default=None,
- help="The name of the column in the datasets containing the summaries (for summarization).",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.dataset_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator_log_kwargs = {}
-
- if args.with_tracking:
- accelerator_log_kwargs["log_with"] = args.report_to
- accelerator_log_kwargs["project_dir"] = args.output_dir
-
- accelerator = Accelerator(gradient_accumulation_steps=args.gradient_accumulation_steps, **accelerator_log_kwargs)
- if args.source_prefix is None and args.model_name_or_path in [
- "google-t5/t5-small",
- "google-t5/t5-base",
- "google-t5/t5-large",
- "google-t5/t5-3b",
- "google-t5/t5-11b",
- ]:
- logger.warning(
- "You're running a t5 model but didn't provide a source prefix, which is the expected, e.g. with "
- "`--source_prefix 'summarize: ' `"
- )
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files)
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForSeq2SeqLM.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForSeq2SeqLM.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- prefix = args.source_prefix if args.source_prefix is not None else ""
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- column_names = raw_datasets["train"].column_names
-
- # Get the column names for input/target.
- dataset_columns = summarization_name_mapping.get(args.dataset_name)
- if args.text_column is None:
- text_column = dataset_columns[0] if dataset_columns is not None else column_names[0]
- else:
- text_column = args.text_column
- if text_column not in column_names:
- raise ValueError(
- f"--text_column' value '{args.text_column}' needs to be one of: {', '.join(column_names)}"
- )
- if args.summary_column is None:
- summary_column = dataset_columns[1] if dataset_columns is not None else column_names[1]
- else:
- summary_column = args.summary_column
- if summary_column not in column_names:
- raise ValueError(
- f"--summary_column' value '{args.summary_column}' needs to be one of: {', '.join(column_names)}"
- )
-
- if args.val_max_target_length is None:
- args.val_max_target_length = args.max_target_length
-
- # Temporarily set max_target_length for training.
- max_target_length = args.max_target_length
- padding = "max_length" if args.pad_to_max_length else False
-
- def preprocess_function(examples):
- inputs = examples[text_column]
- targets = examples[summary_column]
- inputs = [prefix + inp for inp in inputs]
- model_inputs = tokenizer(inputs, max_length=args.max_source_length, padding=padding, truncation=True)
-
- # Tokenize targets with the `text_target` keyword argument
- labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- model_inputs["labels"] = labels["input_ids"]
- return model_inputs
-
- with accelerator.main_process_first():
- train_dataset = raw_datasets["train"].map(
- preprocess_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- # Temporarily set max_target_length for validation.
- max_target_length = args.val_max_target_length
- eval_dataset = raw_datasets["validation"].map(
- preprocess_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 1):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- label_pad_token_id = -100 if args.ignore_pad_token_for_loss else tokenizer.pad_token_id
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorForSeq2Seq(
- tokenizer,
- model=model,
- label_pad_token_id=label_pad_token_id,
- pad_to_multiple_of=pad_to_multiple_of,
- )
-
- def postprocess_text(preds, labels):
- preds = [pred.strip() for pred in preds]
- labels = [label.strip() for label in labels]
-
- # rougeLSum expects newline after each sentence
- preds = ["\n".join(nltk.sent_tokenize(pred)) for pred in preds]
- labels = ["\n".join(nltk.sent_tokenize(label)) for label in labels]
-
- return preds, labels
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- no_decay = ["bias", "LayerNorm.weight", "layer_norm.weight"]
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps * accelerator.num_processes,
- num_training_steps=args.max_train_steps
- if overrode_max_train_steps
- else args.max_train_steps * accelerator.num_processes,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("summarization_no_trainer", experiment_config)
-
- # Metric
- metric = evaluate.load("rouge")
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- with accelerator.accumulate(model):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- accelerator.backward(loss)
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
-
- # Checks if the accelerator has performed an optimization step behind the scenes
- if accelerator.sync_gradients:
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
-
- gen_kwargs = {
- "max_length": args.val_max_target_length,
- "num_beams": args.num_beams,
- }
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- generated_tokens = accelerator.unwrap_model(model).generate(
- batch["input_ids"],
- attention_mask=batch["attention_mask"],
- **gen_kwargs,
- )
-
- generated_tokens = accelerator.pad_across_processes(
- generated_tokens, dim=1, pad_index=tokenizer.pad_token_id
- )
- labels = batch["labels"]
- if not args.pad_to_max_length:
- # If we did not pad to max length, we need to pad the labels too
- labels = accelerator.pad_across_processes(batch["labels"], dim=1, pad_index=tokenizer.pad_token_id)
-
- generated_tokens, labels = accelerator.gather_for_metrics((generated_tokens, labels))
- generated_tokens = generated_tokens.cpu().numpy()
- labels = labels.cpu().numpy()
-
- if args.ignore_pad_token_for_loss:
- # Replace -100 in the labels as we can't decode them.
- labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
- if isinstance(generated_tokens, tuple):
- generated_tokens = generated_tokens[0]
- decoded_preds = tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
- decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
-
- decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
- metric.add_batch(
- predictions=decoded_preds,
- references=decoded_labels,
- )
- result = metric.compute(use_stemmer=True)
- result = {k: round(v * 100, 4) for k, v in result.items()}
-
- logger.info(result)
-
- if args.with_tracking:
- result["train_loss"] = total_loss.item() / len(train_dataloader)
- result["epoch"] = epoch
- result["step"] = completed_steps
- accelerator.log(result, step=completed_steps)
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- all_results = {f"eval_{k}": v for k, v in result.items()}
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(all_results, f)
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/test_accelerate_examples.py b/examples/pytorch/test_accelerate_examples.py
deleted file mode 100644
index be974576d234..000000000000
--- a/examples/pytorch/test_accelerate_examples.py
+++ /dev/null
@@ -1,386 +0,0 @@
-# Copyright 2018 HuggingFace Inc..
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-
-import argparse
-import json
-import logging
-import os
-import shutil
-import sys
-import tempfile
-import unittest
-from unittest import mock
-
-from accelerate.utils import write_basic_config
-
-from transformers.testing_utils import (
- TestCasePlus,
- backend_device_count,
- run_command,
- slow,
- torch_device,
-)
-
-
-logging.basicConfig(level=logging.DEBUG)
-
-logger = logging.getLogger()
-
-
-def get_setup_file():
- parser = argparse.ArgumentParser()
- parser.add_argument("-f")
- args = parser.parse_args()
- return args.f
-
-
-def get_results(output_dir):
- results = {}
- path = os.path.join(output_dir, "all_results.json")
- if os.path.exists(path):
- with open(path, encoding="utf-8") as f:
- results = json.load(f)
- else:
- raise ValueError(f"can't find {path}")
- return results
-
-
-stream_handler = logging.StreamHandler(sys.stdout)
-logger.addHandler(stream_handler)
-
-
-class ExamplesTestsNoTrainer(TestCasePlus):
- @classmethod
- def setUpClass(cls):
- # Write Accelerate config, will pick up on CPU, GPU, and multi-GPU
- cls.tmpdir = tempfile.mkdtemp()
- cls.configPath = os.path.join(cls.tmpdir, "default_config.yml")
- write_basic_config(save_location=cls.configPath)
- cls._launch_args = ["accelerate", "launch", "--config_file", cls.configPath]
-
- @classmethod
- def tearDownClass(cls):
- shutil.rmtree(cls.tmpdir)
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_glue_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/text-classification/run_glue_no_trainer.py
- --model_name_or_path distilbert/distilbert-base-uncased
- --output_dir {tmp_dir}
- --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
- --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --learning_rate=1e-4
- --seed=42
- --num_warmup_steps=2
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.75)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "glue_no_trainer")))
-
- @unittest.skip("Zach is working on this.")
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_clm_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/language-modeling/run_clm_no_trainer.py
- --model_name_or_path distilbert/distilgpt2
- --train_file ./tests/fixtures/sample_text.txt
- --validation_file ./tests/fixtures/sample_text.txt
- --block_size 128
- --per_device_train_batch_size 5
- --per_device_eval_batch_size 5
- --num_train_epochs 2
- --output_dir {tmp_dir}
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- if backend_device_count(torch_device) > 1:
- # Skipping because there are not enough batches to train the model + would need a drop_last to work.
- return
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertLess(result["perplexity"], 100)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "clm_no_trainer")))
-
- @unittest.skip("Zach is working on this.")
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_mlm_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/language-modeling/run_mlm_no_trainer.py
- --model_name_or_path distilbert/distilroberta-base
- --train_file ./tests/fixtures/sample_text.txt
- --validation_file ./tests/fixtures/sample_text.txt
- --output_dir {tmp_dir}
- --num_train_epochs=1
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertLess(result["perplexity"], 42)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "mlm_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_ner_no_trainer(self):
- # with so little data distributed training needs more epochs to get the score on par with 0/1 gpu
- epochs = 7 if backend_device_count(torch_device) > 1 else 2
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/token-classification/run_ner_no_trainer.py
- --model_name_or_path google-bert/bert-base-uncased
- --train_file tests/fixtures/tests_samples/conll/sample.json
- --validation_file tests/fixtures/tests_samples/conll/sample.json
- --output_dir {tmp_dir}
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=2
- --num_train_epochs={epochs}
- --seed 7
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.75)
- self.assertLess(result["train_loss"], 0.6)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "ner_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_squad_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/question-answering/run_qa_no_trainer.py
- --model_name_or_path google-bert/bert-base-uncased
- --version_2_with_negative
- --train_file tests/fixtures/tests_samples/SQUAD/sample.json
- --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
- --output_dir {tmp_dir}
- --seed=42
- --max_train_steps=10
- --num_warmup_steps=2
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- # Because we use --version_2_with_negative the testing script uses SQuAD v2 metrics.
- self.assertGreaterEqual(result["eval_f1"], 28)
- self.assertGreaterEqual(result["eval_exact"], 28)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "qa_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_swag_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/multiple-choice/run_swag_no_trainer.py
- --model_name_or_path google-bert/bert-base-uncased
- --train_file tests/fixtures/tests_samples/swag/sample.json
- --validation_file tests/fixtures/tests_samples/swag/sample.json
- --output_dir {tmp_dir}
- --max_train_steps=20
- --num_warmup_steps=2
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.8)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "swag_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_summarization_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/summarization/run_summarization_no_trainer.py
- --model_name_or_path google-t5/t5-small
- --train_file tests/fixtures/tests_samples/xsum/sample.json
- --validation_file tests/fixtures/tests_samples/xsum/sample.json
- --output_dir {tmp_dir}
- --max_train_steps=50
- --num_warmup_steps=8
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_rouge1"], 10)
- self.assertGreaterEqual(result["eval_rouge2"], 2)
- self.assertGreaterEqual(result["eval_rougeL"], 7)
- self.assertGreaterEqual(result["eval_rougeLsum"], 7)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "summarization_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_translation_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/translation/run_translation_no_trainer.py
- --model_name_or_path sshleifer/student_marian_en_ro_6_1
- --source_lang en
- --target_lang ro
- --train_file tests/fixtures/tests_samples/wmt16/sample.json
- --validation_file tests/fixtures/tests_samples/wmt16/sample.json
- --output_dir {tmp_dir}
- --max_train_steps=50
- --num_warmup_steps=8
- --num_beams=6
- --learning_rate=3e-3
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --source_lang en_XX
- --target_lang ro_RO
- --checkpointing_steps epoch
- --with_tracking
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_bleu"], 30)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "epoch_0")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "translation_no_trainer")))
-
- @slow
- def test_run_semantic_segmentation_no_trainer(self):
- stream_handler = logging.StreamHandler(sys.stdout)
- logger.addHandler(stream_handler)
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/semantic-segmentation/run_semantic_segmentation_no_trainer.py
- --dataset_name huggingface/semantic-segmentation-test-sample
- --output_dir {tmp_dir}
- --max_train_steps=10
- --num_warmup_steps=2
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --checkpointing_steps epoch
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_overall_accuracy"], 0.10)
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_image_classification_no_trainer(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/image-classification/run_image_classification_no_trainer.py
- --model_name_or_path google/vit-base-patch16-224-in21k
- --dataset_name hf-internal-testing/cats_vs_dogs_sample
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --max_train_steps 2
- --train_val_split 0.1
- --seed 42
- --output_dir {tmp_dir}
- --with_tracking
- --checkpointing_steps 1
- --label_column_name labels
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- # The base model scores a 25%
- self.assertGreaterEqual(result["eval_accuracy"], 0.4)
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "step_1")))
- self.assertTrue(os.path.exists(os.path.join(tmp_dir, "image_classification_no_trainer")))
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_object_detection_no_trainer(self):
- stream_handler = logging.StreamHandler(sys.stdout)
- logger.addHandler(stream_handler)
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/object-detection/run_object_detection_no_trainer.py
- --model_name_or_path qubvel-hf/detr-resnet-50-finetuned-10k-cppe5
- --dataset_name qubvel-hf/cppe-5-sample
- --output_dir {tmp_dir}
- --max_train_steps=10
- --num_warmup_steps=2
- --learning_rate=1e-6
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --checkpointing_steps epoch
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["test_map"], 0.10)
-
- @slow
- @mock.patch.dict(os.environ, {"WANDB_MODE": "offline", "DVCLIVE_TEST": "true"})
- def test_run_instance_segmentation_no_trainer(self):
- stream_handler = logging.StreamHandler(sys.stdout)
- logger.addHandler(stream_handler)
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- {self.examples_dir}/pytorch/instance-segmentation/run_instance_segmentation_no_trainer.py
- --model_name_or_path qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former
- --output_dir {tmp_dir}
- --dataset_name qubvel-hf/ade20k-nano
- --do_reduce_labels
- --image_height 256
- --image_width 256
- --num_train_epochs 1
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --seed 1234
- """.split()
-
- run_command(self._launch_args + testargs)
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["test_map"], 0.1)
diff --git a/examples/pytorch/test_pytorch_examples.py b/examples/pytorch/test_pytorch_examples.py
deleted file mode 100644
index f21d5f60c51a..000000000000
--- a/examples/pytorch/test_pytorch_examples.py
+++ /dev/null
@@ -1,714 +0,0 @@
-# Copyright 2018 HuggingFace Inc..
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-
-import json
-import logging
-import os
-import sys
-import tempfile
-from unittest.mock import patch
-
-import torch
-from test_memory_cleanup_mixin import MemoryCleanupMixin
-
-from transformers import (
- AutoTokenizer,
- BertConfig,
- BertForMultipleChoice,
- GPT2Config,
- GPT2LMHeadModel,
- ViTMAEForPreTraining,
- Wav2Vec2ForPreTraining,
-)
-from transformers.testing_utils import (
- CaptureLogger,
- TestCasePlus,
- backend_device_count,
- is_torch_fp16_available_on_device,
- slow,
- torch_device,
-)
-
-
-SRC_DIRS = [
- os.path.join(os.path.dirname(__file__), dirname)
- for dirname in [
- "text-generation",
- "text-classification",
- "token-classification",
- "language-modeling",
- "multiple-choice",
- "question-answering",
- "summarization",
- "translation",
- "image-classification",
- "speech-recognition",
- "audio-classification",
- "speech-pretraining",
- "image-pretraining",
- "semantic-segmentation",
- "object-detection",
- "instance-segmentation",
- ]
-]
-sys.path.extend(SRC_DIRS)
-
-
-if SRC_DIRS is not None:
- import run_audio_classification
- import run_clm
- import run_generation
- import run_glue
- import run_image_classification
- import run_instance_segmentation
- import run_mae
- import run_mlm
- import run_ner
- import run_object_detection
- import run_qa as run_squad
- import run_semantic_segmentation
- import run_seq2seq_qa as run_squad_seq2seq
- import run_speech_recognition_ctc
- import run_speech_recognition_ctc_adapter
- import run_speech_recognition_seq2seq
- import run_summarization
- import run_swag
- import run_translation
- import run_wav2vec2_pretraining_no_trainer
-
-
-logging.basicConfig(level=logging.DEBUG)
-
-logger = logging.getLogger()
-
-
-def get_results(output_dir):
- results = {}
- path = os.path.join(output_dir, "all_results.json")
- if os.path.exists(path):
- with open(path, encoding="utf-8") as f:
- results = json.load(f)
- else:
- raise ValueError(f"can't find {path}")
- return results
-
-
-stream_handler = logging.StreamHandler(sys.stdout)
-logger.addHandler(stream_handler)
-
-
-class ExamplesTests(MemoryCleanupMixin, TestCasePlus):
- # Tests do training — gradients are required.
- run_under_no_grad = False
-
- def test_run_glue(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_glue.py
- --model_name_or_path hf-internal-testing/tiny-random-bert
- --output_dir {tmp_dir}
- --train_file ./tests/fixtures/tests_samples/MRPC/train.csv
- --validation_file ./tests/fixtures/tests_samples/MRPC/dev.csv
- --do_train
- --do_eval
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --learning_rate=5e-3
- --max_steps=30
- --warmup_steps=2
- --seed=42
- --max_seq_length=128
- --dataloader_num_workers=0
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_glue.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.75)
-
- def test_run_clm(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
-
- if backend_device_count(torch_device) > 1:
- # Skipping because there are not enough batches to train the model + would need a drop_last to work.
- return
-
- # Create a tiny GPT-2 from config to avoid downloading distilgpt2 (82M params).
- # Fixed seed gives reproducible init; 25 epochs + lr=1e-2 lets it memorize the tiny
- # sample_text.txt fixture (33 lines) to achieve perplexity < 100.
- with tempfile.TemporaryDirectory() as model_dir:
- torch.manual_seed(42)
- GPT2LMHeadModel(
- GPT2Config(vocab_size=50257, n_embd=32, n_layer=2, n_head=2, n_positions=512)
- ).save_pretrained(model_dir)
- AutoTokenizer.from_pretrained("sshleifer/tiny-gpt2").save_pretrained(model_dir)
-
- testargs = f"""
- run_clm.py
- --model_name_or_path {model_dir}
- --train_file ./tests/fixtures/sample_text.txt
- --validation_file ./tests/fixtures/sample_text.txt
- --do_train
- --do_eval
- --block_size 128
- --per_device_train_batch_size 5
- --per_device_eval_batch_size 5
- --num_train_epochs 25
- --learning_rate 1e-2
- --output_dir {tmp_dir}
- """.split()
-
- if torch_device == "cpu":
- testargs.append("--use_cpu")
-
- with patch.object(sys, "argv", testargs):
- run_clm.main()
- result = get_results(tmp_dir)
- self.assertLess(result["perplexity"], 100)
-
- def test_run_clm_config_overrides(self):
- # test that config_overrides works, despite the misleading dumps of default un-updated
- # config via tokenizer
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_clm.py
- --model_type gpt2
- --tokenizer_name openai-community/gpt2
- --train_file ./tests/fixtures/sample_text.txt
- --output_dir {tmp_dir}
- --config_overrides n_embd=10,n_head=2
- """.split()
-
- if torch_device == "cpu":
- testargs.append("--use_cpu")
-
- logger = run_clm.logger
- with patch.object(sys, "argv", testargs):
- with CaptureLogger(logger) as cl:
- run_clm.main()
-
- self.assertIn('"n_embd": 10', cl.out)
- self.assertIn('"n_head": 2', cl.out)
-
- def test_run_mlm(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_mlm.py
- --model_name_or_path hf-internal-testing/tiny-random-bert
- --train_file ./tests/fixtures/sample_text.txt
- --validation_file ./tests/fixtures/sample_text.txt
- --output_dir {tmp_dir}
- --do_train
- --do_eval
- --prediction_loss_only
- --num_train_epochs=20
- --learning_rate=5e-3
- --dataloader_num_workers=0
- --seed=42
- """.split()
-
- if torch_device == "cpu":
- testargs.append("--use_cpu")
-
- with patch.object(sys, "argv", testargs):
- run_mlm.main()
- result = get_results(tmp_dir)
- self.assertLess(result["perplexity"], 100)
-
- def test_run_ner(self):
- # with so little data distributed training needs more epochs to get the score on par with 0/1 gpu
- epochs = 14 if backend_device_count(torch_device) > 1 else 10
-
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_ner.py
- --model_name_or_path hf-internal-testing/tiny-random-bert
- --train_file tests/fixtures/tests_samples/conll/sample.json
- --validation_file tests/fixtures/tests_samples/conll/sample.json
- --output_dir {tmp_dir}
- --do_train
- --do_eval
- --warmup_steps=2
- --learning_rate=5e-3
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=2
- --num_train_epochs={epochs}
- --seed 7
- --ignore_mismatched_sizes True
- """.split()
-
- if torch_device == "cpu":
- testargs.append("--use_cpu")
-
- with patch.object(sys, "argv", testargs):
- run_ner.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.75)
- self.assertLess(result["eval_loss"], 1.0)
-
- def test_run_squad(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_qa.py
- --model_name_or_path hf-internal-testing/tiny-random-bert
- --version_2_with_negative
- --train_file tests/fixtures/tests_samples/SQUAD/sample.json
- --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
- --output_dir {tmp_dir}
- --max_steps=30
- --warmup_steps=2
- --do_train
- --do_eval
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_squad.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_f1"], 30)
- self.assertGreaterEqual(result["eval_exact"], 30)
-
- def test_run_squad_seq2seq(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_seq2seq_qa.py
- --model_name_or_path sshleifer/t5-tinier-random
- --context_column context
- --question_column question
- --answer_column answers
- --version_2_with_negative
- --train_file tests/fixtures/tests_samples/SQUAD/sample.json
- --validation_file tests/fixtures/tests_samples/SQUAD/sample.json
- --output_dir {tmp_dir}
- --max_steps=30
- --warmup_steps=2
- --do_train
- --do_eval
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --predict_with_generate
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_squad_seq2seq.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_f1"], 30)
- self.assertGreaterEqual(result["eval_exact"], 30)
-
- def test_run_swag(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- # Create a tiny BertForMultipleChoice from config to avoid downloading a large model
- # and to ensure the classifier head has the correct shape ([1, hidden_size]).
- # Fixed seed guarantees reproducible weight init so accuracy is deterministic.
- with tempfile.TemporaryDirectory() as model_dir:
- torch.manual_seed(42)
- config = BertConfig(
- vocab_size=1000,
- hidden_size=32,
- num_hidden_layers=5,
- num_attention_heads=4,
- intermediate_size=37,
- )
- BertForMultipleChoice(config).save_pretrained(model_dir)
- AutoTokenizer.from_pretrained("hf-internal-testing/tiny-random-bert").save_pretrained(model_dir)
-
- testargs = f"""
- run_swag.py
- --model_name_or_path {model_dir}
- --train_file tests/fixtures/tests_samples/swag/sample.json
- --validation_file tests/fixtures/tests_samples/swag/sample.json
- --output_dir {tmp_dir}
- --max_steps=30
- --warmup_steps=2
- --do_train
- --do_eval
- --learning_rate=5e-3
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_swag.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.8)
-
- def test_generation(self):
- testargs = ["run_generation.py", "--prompt=Hello", "--length=10", "--seed=42"]
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- model_type, model_name = (
- "--model_type=gpt2",
- "--model_name_or_path=sshleifer/tiny-gpt2",
- )
- with patch.object(sys, "argv", testargs + [model_type, model_name]):
- result = run_generation.main()
- self.assertGreaterEqual(len(result[0]), 10)
-
- @slow
- def test_run_summarization(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_summarization.py
- --model_name_or_path google-t5/t5-small
- --train_file tests/fixtures/tests_samples/xsum/sample.json
- --validation_file tests/fixtures/tests_samples/xsum/sample.json
- --output_dir {tmp_dir}
- --max_steps=50
- --warmup_steps=8
- --do_train
- --do_eval
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --predict_with_generate
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_summarization.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_rouge1"], 10)
- self.assertGreaterEqual(result["eval_rouge2"], 2)
- self.assertGreaterEqual(result["eval_rougeL"], 7)
- self.assertGreaterEqual(result["eval_rougeLsum"], 7)
-
- @slow
- def test_run_translation(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_translation.py
- --model_name_or_path sshleifer/student_marian_en_ro_6_1
- --source_lang en
- --target_lang ro
- --train_file tests/fixtures/tests_samples/wmt16/sample.json
- --validation_file tests/fixtures/tests_samples/wmt16/sample.json
- --output_dir {tmp_dir}
- --max_steps=50
- --warmup_steps=8
- --do_train
- --do_eval
- --learning_rate=3e-3
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --predict_with_generate
- --source_lang en_XX
- --target_lang ro_RO
- --max_source_length 512
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_translation.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_bleu"], 30)
-
- @slow
- def test_run_image_classification(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_image_classification.py
- --output_dir {tmp_dir}
- --model_name_or_path google/vit-base-patch16-224-in21k
- --dataset_name hf-internal-testing/cats_vs_dogs_sample
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --remove_unused_columns False
- --dataloader_num_workers 0
- --metric_for_best_model accuracy
- --max_steps 10
- --train_val_split 0.1
- --seed 42
- --label_column_name labels
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_image_classification.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_accuracy"], 0.8)
-
- @slow
- def test_run_speech_recognition_ctc(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_speech_recognition_ctc.py
- --output_dir {tmp_dir}
- --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
- --dataset_name hf-internal-testing/librispeech_asr_dummy
- --dataset_config_name clean
- --train_split_name validation
- --eval_split_name validation
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --remove_unused_columns False
- --preprocessing_num_workers 0
- --max_steps 10
- --seed 42
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_speech_recognition_ctc.main()
- result = get_results(tmp_dir)
- self.assertLess(result["eval_loss"], result["train_loss"])
-
- def test_run_speech_recognition_ctc_adapter(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_speech_recognition_ctc_adapter.py
- --output_dir {tmp_dir}
- --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
- --dataset_name hf-internal-testing/librispeech_asr_dummy
- --dataset_config_name clean
- --train_split_name validation
- --eval_split_name validation
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --remove_unused_columns False
- --preprocessing_num_workers 0
- --max_steps 10
- --max_duration_in_seconds 3.0
- --min_duration_in_seconds 0.0
- --target_language tur
- --seed 42
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_speech_recognition_ctc_adapter.main()
- result = get_results(tmp_dir)
- self.assertTrue(os.path.isfile(os.path.join(tmp_dir, "./adapter.tur.safetensors")))
- self.assertLess(result["eval_loss"], result["train_loss"])
-
- def test_run_speech_recognition_seq2seq(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_speech_recognition_seq2seq.py
- --output_dir {tmp_dir}
- --model_name_or_path hf-internal-testing/tiny-random-speech-encoder-decoder
- --dataset_name hf-internal-testing/librispeech_asr_dummy
- --dataset_config_name clean
- --train_split_name validation
- --eval_split_name validation
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 4
- --remove_unused_columns False
- --preprocessing_num_workers 0
- --max_steps 10
- --max_duration_in_seconds 3.0
- --min_duration_in_seconds 0.0
- --seed 42
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_speech_recognition_seq2seq.main()
- result = get_results(tmp_dir)
- self.assertLess(result["eval_loss"], result["train_loss"])
-
- def test_run_audio_classification(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_audio_classification.py
- --output_dir {tmp_dir}
- --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
- --dataset_name anton-l/superb_demo
- --dataset_config_name ks
- --train_split_name test
- --eval_split_name test
- --audio_column_name audio
- --label_column_name label
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --remove_unused_columns False
- --num_train_epochs 10
- --max_steps 50
- --seed 42
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_audio_classification.main()
- result = get_results(tmp_dir)
- self.assertLess(result["eval_loss"], result["train_loss"])
-
- def test_run_wav2vec2_pretraining(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_wav2vec2_pretraining_no_trainer.py
- --output_dir {tmp_dir}
- --model_name_or_path hf-internal-testing/tiny-random-wav2vec2
- --dataset_name hf-internal-testing/librispeech_asr_dummy
- --dataset_config_names clean
- --dataset_split_names validation
- --learning_rate 1e-4
- --per_device_train_batch_size 4
- --per_device_eval_batch_size 4
- --preprocessing_num_workers 0
- --max_train_steps 2
- --validation_split_percentage 5
- --seed 42
- --max_duration_in_seconds 1.0
- --min_duration_in_seconds 0.5
- """.split()
-
- with patch.object(sys, "argv", testargs):
- run_wav2vec2_pretraining_no_trainer.main()
- model = Wav2Vec2ForPreTraining.from_pretrained(tmp_dir)
- self.assertIsNotNone(model)
-
- def test_run_vit_mae_pretraining(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_mae.py
- --output_dir {tmp_dir}
- --dataset_name hf-internal-testing/cats_vs_dogs_sample
- --do_train
- --do_eval
- --learning_rate 1e-4
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --remove_unused_columns False
- --dataloader_num_workers 0
- --metric_for_best_model accuracy
- --max_steps 10
- --train_val_split 0.1
- --seed 42
- --config_overrides hidden_size=32,intermediate_size=64,num_hidden_layers=2,num_attention_heads=2,decoder_hidden_size=32,decoder_intermediate_size=64,decoder_num_hidden_layers=2,decoder_num_attention_heads=2
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_mae.main()
- model = ViTMAEForPreTraining.from_pretrained(tmp_dir)
- self.assertIsNotNone(model)
-
- @slow
- def test_run_semantic_segmentation(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_semantic_segmentation.py
- --output_dir {tmp_dir}
- --dataset_name huggingface/semantic-segmentation-test-sample
- --do_train
- --do_eval
- --remove_unused_columns False
- --max_steps 10
- --learning_rate=2e-4
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --seed 32
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_semantic_segmentation.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["eval_overall_accuracy"], 0.1)
-
- @slow
- @patch.dict(os.environ, {"WANDB_DISABLED": "true"})
- def test_run_object_detection(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_object_detection.py
- --model_name_or_path qubvel-hf/detr-resnet-50-finetuned-10k-cppe5
- --output_dir {tmp_dir}
- --dataset_name qubvel-hf/cppe-5-sample
- --do_train
- --do_eval
- --remove_unused_columns False
- --eval_do_concat_batches False
- --max_steps 10
- --learning_rate=1e-6
- --per_device_train_batch_size=2
- --per_device_eval_batch_size=1
- --seed 32
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_object_detection.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["test_map"], 0.1)
-
- @slow
- @patch.dict(os.environ, {"WANDB_DISABLED": "true"})
- def test_run_instance_segmentation(self):
- tmp_dir = self.get_auto_remove_tmp_dir()
- testargs = f"""
- run_instance_segmentation.py
- --model_name_or_path qubvel-hf/finetune-instance-segmentation-ade20k-mini-mask2former
- --output_dir {tmp_dir}
- --dataset_name qubvel-hf/ade20k-nano
- --do_reduce_labels
- --image_height 256
- --image_width 256
- --do_train
- --num_train_epochs 1
- --learning_rate 1e-5
- --lr_scheduler_type constant
- --per_device_train_batch_size 2
- --per_device_eval_batch_size 1
- --do_eval
- --eval_strategy epoch
- --seed 32
- """.split()
-
- if is_torch_fp16_available_on_device(torch_device):
- testargs.append("--fp16")
-
- with patch.object(sys, "argv", testargs):
- run_instance_segmentation.main()
- result = get_results(tmp_dir)
- self.assertGreaterEqual(result["test_map"], 0.1)
diff --git a/examples/pytorch/text-classification/README.md b/examples/pytorch/text-classification/README.md
deleted file mode 100644
index fe029a542e1f..000000000000
--- a/examples/pytorch/text-classification/README.md
+++ /dev/null
@@ -1,251 +0,0 @@
-
-
-# Text classification examples
-
-## GLUE tasks
-
-Based on the script [`run_glue.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py).
-
-Fine-tuning the library models for sequence classification on the GLUE benchmark: [General Language Understanding
-Evaluation](https://gluebenchmark.com/). This script can fine-tune any of the models on the [hub](https://huggingface.co/models)
-and can also be used for a dataset hosted on our [hub](https://huggingface.co/datasets) or your own data in a csv or a JSON file
-(the script might need some tweaks in that case, refer to the comments inside for help).
-
-GLUE is made up of a total of 9 different tasks. Here is how to run the script on one of them:
-
-```bash
-export TASK_NAME=mrpc
-
-python run_glue.py \
- --model_name_or_path google-bert/bert-base-cased \
- --task_name $TASK_NAME \
- --do_train \
- --do_eval \
- --max_seq_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/
-```
-
-where task name can be one of cola, sst2, mrpc, stsb, qqp, mnli, qnli, rte, wnli.
-
-We get the following results on the dev set of the benchmark with the previous commands (with an exception for MRPC and
-WNLI which are tiny and where we used 5 epochs instead of 3). Trainings are seeded so you should obtain the same
-results with PyTorch 1.6.0 (and close results with different versions), training times are given for information (a
-single Titan RTX was used):
-
-| Task | Metric | Result | Training time |
-|-------|------------------------------|-------------|---------------|
-| CoLA | Matthews corr | 56.53 | 3:17 |
-| SST-2 | Accuracy | 92.32 | 26:06 |
-| MRPC | F1/Accuracy | 88.85/84.07 | 2:21 |
-| STS-B | Pearson/Spearman corr. | 88.64/88.48 | 2:13 |
-| QQP | Accuracy/F1 | 90.71/87.49 | 2:22:26 |
-| MNLI | Matched acc./Mismatched acc. | 83.91/84.10 | 2:35:23 |
-| QNLI | Accuracy | 90.66 | 40:57 |
-| RTE | Accuracy | 65.70 | 57 |
-| WNLI | Accuracy | 56.34 | 24 |
-
-Some of these results are significantly different from the ones reported on the test set of GLUE benchmark on the
-website. For QQP and WNLI, please refer to [FAQ #12](https://gluebenchmark.com/faq) on the website.
-
-The following example fine-tunes BERT on the `imdb` dataset hosted on our [hub](https://huggingface.co/datasets):
-
-```bash
-python run_glue.py \
- --model_name_or_path google-bert/bert-base-cased \
- --dataset_name stanfordnlp/imdb \
- --do_train \
- --do_predict \
- --max_seq_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/imdb/
-```
-
-> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
-
-## Text classification
-As an alternative, we can use the script [`run_classification.py`](./run_classification.py) to fine-tune models on a single/multi-label classification task.
-
-The following example fine-tunes BERT on the [`dbpedia_14`](https://huggingface.co/datasets/fancyzhx/dbpedia_14) dataset.
-We can specify the metric, the label column and also choose which text columns to use jointly for classification.
-```bash
-dataset="fancyzhx/dbpedia_14"
-python run_classification.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name ${dataset} \
- --shuffle_train_dataset \
- --metric_name accuracy \
- --text_column_name "title,content" \
- --text_column_delimiter "\n" \
- --label_column_name label \
- --do_train \
- --do_eval \
- --max_seq_length 512 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 1 \
- --max_train_samples 20000 \
- --max_eval_samples 5000 \
- --output_dir /tmp/dbpedia_14/
-```
-Training on 20,000 samples for 1 epoch results in an accuracy of around 0.97. Remove `--max_train_samples` and `--max_eval_samples` to train and evaluate on the full dataset.
-
-The following is a multi-label classification example. It fine-tunes BERT on the `reuters21578` dataset hosted on our [hub](https://huggingface.co/datasets/ucirvine/reuters21578):
-```bash
-dataset="ucirvine/reuters21578"
-subset="ModApte"
-python run_classification.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name ${dataset} \
- --dataset_config_name ${subset} \
- --shuffle_train_dataset \
- --remove_splits "unused" \
- --metric_name f1 \
- --text_column_name text \
- --label_column_name topics \
- --do_train \
- --do_eval \
- --max_seq_length 512 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 15 \
- --output_dir /tmp/${dataset}_${subset}/
-```
- It results in a Micro F1 score of around 0.82 without any text and label filtering. Note that you have to explicitly remove the "unused" split from the dataset, since it is not used for classification.
-
-### Mixed precision training
-
-If you have a GPU with mixed precision capabilities (architecture Pascal or more recent), you can use mixed precision
-training with PyTorch 1.6.0 or latest. Just add the flag `--fp16` to your command launching one of the scripts mentioned above!
-
-Using mixed precision training usually results in 2x-speedup for training with the same final results:
-
-| Task | Metric | Result | Training time | Result (FP16) | Training time (FP16) |
-|-------|------------------------------|-------------|---------------|---------------|----------------------|
-| CoLA | Matthews corr | 56.53 | 3:17 | 56.78 | 1:41 |
-| SST-2 | Accuracy | 92.32 | 26:06 | 91.74 | 13:11 |
-| MRPC | F1/Accuracy | 88.85/84.07 | 2:21 | 88.12/83.58 | 1:10 |
-| STS-B | Pearson/Spearman corr. | 88.64/88.48 | 2:13 | 88.71/88.55 | 1:08 |
-| QQP | Accuracy/F1 | 90.71/87.49 | 2:22:26 | 90.67/87.43 | 1:11:54 |
-| MNLI | Matched acc./Mismatched acc. | 83.91/84.10 | 2:35:23 | 84.04/84.06 | 1:17:06 |
-| QNLI | Accuracy | 90.66 | 40:57 | 90.96 | 20:16 |
-| RTE | Accuracy | 65.70 | 57 | 65.34 | 29 |
-| WNLI | Accuracy | 56.34 | 24 | 56.34 | 12 |
-
-
-## PyTorch version, no Trainer
-
-Based on the script [`run_glue_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue_no_trainer.py).
-
-Like `run_glue.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on a
-text classification task, either a GLUE task or your own data in a csv or a JSON file. The main difference is that this
-script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
-the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-export TASK_NAME=mrpc
-
-python run_glue_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --task_name $TASK_NAME \
- --max_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-export TASK_NAME=mrpc
-
-accelerate launch run_glue_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --task_name $TASK_NAME \
- --max_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
-
-## XNLI
-
-Based on the script [`run_xnli.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_xnli.py).
-
-[XNLI](https://cims.nyu.edu/~sbowman/xnli/) is a crowd-sourced dataset based on [MultiNLI](https://cims.nyu.edu/~sbowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
-
-#### Fine-tuning on XNLI
-
-This example code fine-tunes mBERT (multi-lingual BERT) on the XNLI dataset. It runs in 106 mins on a single tesla V100 16GB.
-
-```bash
-python run_xnli.py \
- --model_name_or_path google-bert/bert-base-multilingual-cased \
- --language de \
- --train_language en \
- --do_train \
- --do_eval \
- --per_device_train_batch_size 32 \
- --learning_rate 5e-5 \
- --num_train_epochs 2.0 \
- --max_seq_length 128 \
- --output_dir /tmp/debug_xnli/ \
- --save_steps -1
-```
-
-Training with the previously defined hyper-parameters yields the following results on the **test** set:
-
-```bash
-acc = 0.7093812375249501
-```
diff --git a/examples/pytorch/text-classification/requirements.txt b/examples/pytorch/text-classification/requirements.txt
deleted file mode 100644
index 19090ab12477..000000000000
--- a/examples/pytorch/text-classification/requirements.txt
+++ /dev/null
@@ -1,8 +0,0 @@
-accelerate >= 0.12.0
-datasets >= 1.8.0
-sentencepiece != 0.1.92
-scipy
-scikit-learn
-protobuf
-torch >= 1.3
-evaluate
\ No newline at end of file
diff --git a/examples/pytorch/text-classification/run_classification.py b/examples/pytorch/text-classification/run_classification.py
deleted file mode 100755
index 28c5fea9ac02..000000000000
--- a/examples/pytorch/text-classification/run_classification.py
+++ /dev/null
@@ -1,746 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "scipy",
-# "scikit-learn",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""Finetuning the library models for text classification."""
-# You can also adapt this script on your own text classification task. Pointers for this are left as comments.
-
-import logging
-import os
-import random
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import Value, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSequenceClassification,
- AutoTokenizer,
- DataCollatorWithPadding,
- EvalPrediction,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
-
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
-
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- do_regression: bool = field(
- default=None,
- metadata={
- "help": "Whether to do regression instead of classification. If None, will be inferred from the dataset."
- },
- )
- text_column_names: str | None = field(
- default=None,
- metadata={
- "help": (
- "The name of the text column in the input dataset or a CSV/JSON file. "
- 'If not specified, will use the "sentence" column for single/multi-label classification task.'
- )
- },
- )
- text_column_delimiter: str | None = field(
- default=" ", metadata={"help": "The delimiter to use to join text columns into a single sentence."}
- )
- train_split_name: str | None = field(
- default=None,
- metadata={
- "help": 'The name of the train split in the input dataset. If not specified, will use the "train" split when do_train is enabled'
- },
- )
- validation_split_name: str | None = field(
- default=None,
- metadata={
- "help": 'The name of the validation split in the input dataset. If not specified, will use the "validation" split when do_eval is enabled'
- },
- )
- test_split_name: str | None = field(
- default=None,
- metadata={
- "help": 'The name of the test split in the input dataset. If not specified, will use the "test" split when do_predict is enabled'
- },
- )
- remove_splits: str | None = field(
- default=None,
- metadata={"help": "The splits to remove from the dataset. Multiple splits should be separated by commas."},
- )
- remove_columns: str | None = field(
- default=None,
- metadata={"help": "The columns to remove from the dataset. Multiple columns should be separated by commas."},
- )
- label_column_name: str | None = field(
- default=None,
- metadata={
- "help": (
- "The name of the label column in the input dataset or a CSV/JSON file. "
- 'If not specified, will use the "label" column for single/multi-label classification task'
- )
- },
- )
- max_seq_length: int = field(
- default=128,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch."
- )
- },
- )
- shuffle_train_dataset: bool = field(
- default=False, metadata={"help": "Whether to shuffle the train dataset or not."}
- )
- shuffle_seed: int = field(
- default=42, metadata={"help": "Random seed that will be used to shuffle the train dataset."}
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- metric_name: str | None = field(default=None, metadata={"help": "The metric to use for evaluation."})
- train_file: str | None = field(
- default=None, metadata={"help": "A csv or a json file containing the training data."}
- )
- validation_file: str | None = field(
- default=None, metadata={"help": "A csv or a json file containing the validation data."}
- )
- test_file: str | None = field(default=None, metadata={"help": "A csv or a json file containing the test data."})
-
- def __post_init__(self):
- if self.dataset_name is None:
- if self.train_file is None or self.validation_file is None:
- raise ValueError(" training/validation file or a dataset name.")
-
- train_extension = self.train_file.split(".")[-1]
- assert train_extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- validation_extension = self.validation_file.split(".")[-1]
- assert validation_extension == train_extension, (
- "`validation_file` should have the same extension (csv or json) as `train_file`."
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-def get_label_list(raw_dataset, split="train") -> list[str]:
- """Get the list of labels from a multi-label dataset"""
-
- if isinstance(raw_dataset[split]["label"][0], list):
- label_list = [label for sample in raw_dataset[split]["label"] for label in sample]
- label_list = list(set(label_list))
- else:
- label_list = raw_dataset[split].unique("label")
- # we will treat the label list as a list of string instead of int, consistent with model.config.label2id
- label_list = [str(label) for label in label_list]
- return label_list
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON training and evaluation files, or specify a dataset name
- # to load from huggingface/datasets. In ether case, you can specify a the key of the column(s) containing the text and
- # the key of the column containing the label. If multiple columns are specified for the text, they will be joined together
- # for the actual text value.
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- # Try print some info about the dataset
- logger.info(f"Dataset loaded: {raw_datasets}")
- logger.info(raw_datasets)
- else:
- # Loading a dataset from your local files.
- # CSV/JSON training and evaluation files are needed.
- data_files = {"train": data_args.train_file, "validation": data_args.validation_file}
-
- # Get the test dataset: you can provide your own CSV/JSON test file
- if training_args.do_predict:
- if data_args.test_file is not None:
- train_extension = data_args.train_file.split(".")[-1]
- test_extension = data_args.test_file.split(".")[-1]
- assert test_extension == train_extension, (
- "`test_file` should have the same extension (csv or json) as `train_file`."
- )
- data_files["test"] = data_args.test_file
- else:
- raise ValueError("Need either a dataset name or a test file for `do_predict`.")
-
- for key in data_files:
- logger.info(f"load a local file for {key}: {data_files[key]}")
-
- if data_args.train_file.endswith(".csv"):
- # Loading a dataset from local csv files
- raw_datasets = load_dataset(
- "csv",
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- else:
- # Loading a dataset from local json files
- raw_datasets = load_dataset(
- "json",
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
-
- # See more about loading any type of standard or custom dataset at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- if data_args.remove_splits is not None:
- for split in data_args.remove_splits.split(","):
- logger.info(f"removing split {split}")
- raw_datasets.pop(split)
-
- if data_args.train_split_name is not None:
- logger.info(f"using {data_args.train_split_name} as train set")
- raw_datasets["train"] = raw_datasets[data_args.train_split_name]
- raw_datasets.pop(data_args.train_split_name)
-
- if data_args.validation_split_name is not None:
- logger.info(f"using {data_args.validation_split_name} as validation set")
- raw_datasets["validation"] = raw_datasets[data_args.validation_split_name]
- raw_datasets.pop(data_args.validation_split_name)
-
- if data_args.test_split_name is not None:
- logger.info(f"using {data_args.test_split_name} as test set")
- raw_datasets["test"] = raw_datasets[data_args.test_split_name]
- raw_datasets.pop(data_args.test_split_name)
-
- if data_args.remove_columns is not None:
- for split in raw_datasets:
- for column in data_args.remove_columns.split(","):
- logger.info(f"removing column {column} from split {split}")
- raw_datasets[split] = raw_datasets[split].remove_columns(column)
-
- if data_args.label_column_name is not None and data_args.label_column_name != "label":
- for key in raw_datasets:
- raw_datasets[key] = raw_datasets[key].rename_column(data_args.label_column_name, "label")
-
- # Trying to have good defaults here, don't hesitate to tweak to your needs.
-
- is_regression = (
- raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
- if data_args.do_regression is None
- else data_args.do_regression
- )
-
- is_multi_label = False
- if is_regression:
- label_list = None
- num_labels = 1
- # regression requires float as label type, let's cast it if needed
- for split in raw_datasets:
- if raw_datasets[split].features["label"].dtype not in ["float32", "float64"]:
- logger.warning(
- f"Label type for {split} set to float32, was {raw_datasets[split].features['label'].dtype}"
- )
- features = raw_datasets[split].features
- features.update({"label": Value("float32")})
- try:
- raw_datasets[split] = raw_datasets[split].cast(features)
- except TypeError as error:
- logger.error(
- f"Unable to cast {split} set to float32, please check the labels are correct, or maybe try with --do_regression=False"
- )
- raise error
-
- else: # classification
- if raw_datasets["train"].features["label"].dtype == "list": # multi-label classification
- is_multi_label = True
- logger.info("Label type is list, doing multi-label classification")
- # Trying to find the number of labels in a multi-label classification task
- # We have to deal with common cases that labels appear in the training set but not in the validation/test set.
- # So we build the label list from the union of labels in train/val/test.
- label_list = get_label_list(raw_datasets, split="train")
- for split in ["validation", "test"]:
- if split in raw_datasets:
- val_or_test_labels = get_label_list(raw_datasets, split=split)
- diff = set(val_or_test_labels).difference(set(label_list))
- if len(diff) > 0:
- # add the labels that appear in val/test but not in train, throw a warning
- logger.warning(
- f"Labels {diff} in {split} set but not in training set, adding them to the label list"
- )
- label_list += list(diff)
- # if label is -1, we throw a warning and remove it from the label list
- for label in label_list:
- if label == -1:
- logger.warning("Label -1 found in label list, removing it.")
- label_list.remove(label)
-
- label_list.sort()
- num_labels = len(label_list)
- if num_labels <= 1:
- raise ValueError("You need more than one label to do classification.")
-
- # Load pretrained model and tokenizer
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- num_labels=num_labels,
- finetuning_task="text-classification",
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- if is_regression:
- config.problem_type = "regression"
- logger.info("setting problem type to regression")
- elif is_multi_label:
- config.problem_type = "multi_label_classification"
- logger.info("setting problem type to multi label classification")
- else:
- config.problem_type = "single_label_classification"
- logger.info("setting problem type to single label classification")
-
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSequenceClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
-
- # Padding strategy
- if data_args.pad_to_max_length:
- padding = "max_length"
- else:
- # We will pad later, dynamically at batch creation, to the max sequence length in each batch
- padding = False
-
- # for training ,we will update the config with label infos,
- # if do_train is not set, we will use the label infos in the config
- if training_args.do_train and not is_regression: # classification, training
- label_to_id = {v: i for i, v in enumerate(label_list)}
- # update config with label infos
- if model.config.label2id != label_to_id:
- logger.warning(
- "The label2id key in the model config.json is not equal to the label2id key of this "
- "run. You can ignore this if you are doing finetuning."
- )
- model.config.label2id = label_to_id
- model.config.id2label = {id: label for label, id in label_to_id.items()}
- elif not is_regression: # classification, but not training
- logger.info("using label infos in the model config")
- logger.info(f"label2id: {model.config.label2id}")
- label_to_id = model.config.label2id
- else: # regression
- label_to_id = None
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- def multi_labels_to_ids(labels: list[str]) -> list[float]:
- ids = [0.0] * len(label_to_id) # BCELoss requires float as target type
- for label in labels:
- ids[label_to_id[label]] = 1.0
- return ids
-
- def preprocess_function(examples):
- if data_args.text_column_names is not None:
- text_column_names = data_args.text_column_names.split(",")
- # join together text columns into "sentence" column
- examples["sentence"] = examples[text_column_names[0]]
- for column in text_column_names[1:]:
- for i in range(len(examples[column])):
- examples["sentence"][i] += data_args.text_column_delimiter + examples[column][i]
- # Tokenize the texts
- result = tokenizer(examples["sentence"], padding=padding, max_length=max_seq_length, truncation=True)
- if label_to_id is not None and "label" in examples:
- if is_multi_label:
- result["label"] = [multi_labels_to_ids(l) for l in examples["label"]]
- else:
- result["label"] = [(label_to_id[str(l)] if l != -1 else -1) for l in examples["label"]]
- return result
-
- # Running the preprocessing pipeline on all the datasets
- with training_args.main_process_first(desc="dataset map pre-processing"):
- raw_datasets = raw_datasets.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset.")
- train_dataset = raw_datasets["train"]
- if data_args.shuffle_train_dataset:
- logger.info("Shuffling the training dataset")
- train_dataset = train_dataset.shuffle(seed=data_args.shuffle_seed)
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
-
- if training_args.do_eval:
- if "validation" not in raw_datasets and "validation_matched" not in raw_datasets:
- if "test" not in raw_datasets and "test_matched" not in raw_datasets:
- raise ValueError("--do_eval requires a validation or test dataset if validation is not defined.")
- else:
- logger.warning("Validation dataset not found. Falling back to test dataset for validation.")
- eval_dataset = raw_datasets["test"]
- else:
- eval_dataset = raw_datasets["validation"]
-
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
-
- if training_args.do_predict or data_args.test_file is not None:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_dataset = raw_datasets["test"]
- # remove label column if it exists
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
-
- # Log a few random samples from the training set:
- if training_args.do_train:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- if data_args.metric_name is not None:
- metric = (
- evaluate.load(data_args.metric_name, config_name="multilabel", cache_dir=model_args.cache_dir)
- if is_multi_label
- else evaluate.load(data_args.metric_name, cache_dir=model_args.cache_dir)
- )
- logger.info(f"Using metric {data_args.metric_name} for evaluation.")
- else:
- if is_regression:
- metric = evaluate.load("mse", cache_dir=model_args.cache_dir)
- logger.info("Using mean squared error (mse) as regression score, you can use --metric_name to overwrite.")
- else:
- if is_multi_label:
- metric = evaluate.load("f1", config_name="multilabel", cache_dir=model_args.cache_dir)
- logger.info(
- "Using multilabel F1 for multi-label classification task, you can use --metric_name to overwrite."
- )
- else:
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
- logger.info("Using accuracy as classification score, you can use --metric_name to overwrite.")
-
- def compute_metrics(p: EvalPrediction):
- preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
- if is_regression:
- preds = np.squeeze(preds)
- result = metric.compute(predictions=preds, references=p.label_ids)
- elif is_multi_label:
- preds = np.array([np.where(p > 0, 1, 0) for p in preds]) # convert logits to multi-hot encoding
- # Micro F1 is commonly used in multi-label classification
- result = metric.compute(predictions=preds, references=p.label_ids, average="micro")
- else:
- preds = np.argmax(preds, axis=1)
- result = metric.compute(predictions=preds, references=p.label_ids)
- if len(result) > 1:
- result["combined_score"] = np.mean(list(result.values())).item()
- return result
-
- # Data collator will default to DataCollatorWithPadding when the tokenizer is passed to Trainer, so we change it if
- # we already did the padding.
- if data_args.pad_to_max_length:
- data_collator = default_data_collator
- elif training_args.fp16:
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
- else:
- data_collator = None
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=tokenizer,
- data_collator=data_collator,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
- trainer.save_model() # Saves the tokenizer too for easy upload
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate(eval_dataset=eval_dataset)
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- if training_args.do_predict:
- logger.info("*** Predict ***")
- # Removing the `label` columns if exists because it might contains -1 and Trainer won't like that.
- if "label" in predict_dataset.features:
- predict_dataset = predict_dataset.remove_columns("label")
- predictions = trainer.predict(predict_dataset, metric_key_prefix="predict").predictions
- if is_regression:
- predictions = np.squeeze(predictions)
- elif is_multi_label:
- # Convert logits to multi-hot encoding. We compare the logits to 0 instead of 0.5, because the sigmoid is not applied.
- # You can also pass `preprocess_logits_for_metrics=lambda logits, labels: nn.functional.sigmoid(logits)` to the Trainer
- # and set p > 0.5 below (less efficient in this case)
- predictions = np.array([np.where(p > 0, 1, 0) for p in predictions])
- else:
- predictions = np.argmax(predictions, axis=1)
- output_predict_file = os.path.join(training_args.output_dir, "predict_results.txt")
- if trainer.is_world_process_zero():
- with open(output_predict_file, "w", encoding="utf-8") as writer:
- logger.info("***** Predict results *****")
- writer.write("index\tprediction\n")
- for index, item in enumerate(predictions):
- if is_regression:
- writer.write(f"{index}\t{item:3.3f}\n")
- elif is_multi_label:
- # recover from multi-hot encoding
- item = [label_list[i] for i in range(len(item)) if item[i] == 1]
- writer.write(f"{index}\t{item}\n")
- else:
- item = label_list[item]
- writer.write(f"{index}\t{item}\n")
- logger.info(f"Predict results saved at {output_predict_file}")
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-classification"}
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/text-classification/run_glue.py b/examples/pytorch/text-classification/run_glue.py
deleted file mode 100755
index 4713961076b3..000000000000
--- a/examples/pytorch/text-classification/run_glue.py
+++ /dev/null
@@ -1,652 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "scipy",
-# "scikit-learn",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""Finetuning the library models for sequence classification on GLUE."""
-# You can also adapt this script on your own text classification task. Pointers for this are left as comments.
-
-import logging
-import os
-import random
-import sys
-from collections import Counter
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import Value, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSequenceClassification,
- AutoTokenizer,
- DataCollatorWithPadding,
- EvalPrediction,
- HfArgumentParser,
- PreTrainedConfig,
- Trainer,
- TrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
-
-task_to_keys = {
- "cola": ("sentence", None),
- "mnli": ("premise", "hypothesis"),
- "mrpc": ("sentence1", "sentence2"),
- "qnli": ("question", "sentence"),
- "qqp": ("question1", "question2"),
- "rte": ("sentence1", "sentence2"),
- "sst2": ("sentence", None),
- "stsb": ("sentence1", "sentence2"),
- "wnli": ("sentence1", "sentence2"),
-}
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
-
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- task_name: str | None = field(
- default=None,
- metadata={"help": "The name of the task to train on: " + ", ".join(task_to_keys.keys())},
- )
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- max_seq_length: int = field(
- default=128,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- train_file: str | None = field(
- default=None, metadata={"help": "A csv or a json file containing the training data."}
- )
- validation_file: str | None = field(
- default=None, metadata={"help": "A csv or a json file containing the validation data."}
- )
- test_file: str | None = field(default=None, metadata={"help": "A csv or a json file containing the test data."})
-
- def __post_init__(self):
- if self.task_name is not None:
- self.task_name = self.task_name.lower()
- if self.task_name not in task_to_keys:
- raise ValueError("Unknown task, you should pick one in " + ",".join(task_to_keys.keys()))
- elif self.dataset_name is not None:
- pass
- elif self.train_file is None or self.validation_file is None:
- raise ValueError("Need either a GLUE task, a training/validation file or a dataset name.")
- else:
- train_extension = self.train_file.split(".")[-1]
- assert train_extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- validation_extension = self.validation_file.split(".")[-1]
- assert validation_extension == train_extension, (
- "`validation_file` should have the same extension (csv or json) as `train_file`."
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
- # or specify a GLUE benchmark task (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use as labels the column called 'label' and as pair of sentences the
- # sentences in columns called 'sentence1' and 'sentence2' if such column exists or the first two columns not named
- # label if at least two columns are provided.
- #
- # If the CSVs/JSONs contain only one non-label column, the script does single sentence classification on this
- # single column. You can easily tweak this behavior (see below)
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.task_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- "nyu-mll/glue",
- data_args.task_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- elif data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- # Loading a dataset from your local files.
- # CSV/JSON training and evaluation files are needed.
- data_files = {"train": data_args.train_file, "validation": data_args.validation_file}
-
- # Get the test dataset: you can provide your own CSV/JSON test file (see below)
- # when you use `do_predict` without specifying a GLUE benchmark task.
- if training_args.do_predict:
- if data_args.test_file is not None:
- train_extension = data_args.train_file.split(".")[-1]
- test_extension = data_args.test_file.split(".")[-1]
- assert test_extension == train_extension, (
- "`test_file` should have the same extension (csv or json) as `train_file`."
- )
- data_files["test"] = data_args.test_file
- else:
- raise ValueError("Need either a GLUE task or a test file for `do_predict`.")
-
- for key in data_files:
- logger.info(f"load a local file for {key}: {data_files[key]}")
-
- if data_args.train_file.endswith(".csv"):
- # Loading a dataset from local csv files
- raw_datasets = load_dataset(
- "csv",
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- else:
- # Loading a dataset from local json files
- raw_datasets = load_dataset(
- "json",
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # With pandas>=3, text columns of CSV files are loaded as `large_string`, and `datasets.map` then casts the label
- # ids computed below back to that type, so they end up as strings. Using `string` lets them be inferred as ints.
- for split in raw_datasets:
- if raw_datasets[split].features.get("label") == Value("large_string"):
- raw_datasets[split] = raw_datasets[split].cast_column("label", Value("string"))
-
- # Labels
- if data_args.task_name is not None:
- is_regression = data_args.task_name == "stsb"
- if not is_regression:
- label_list = raw_datasets["train"].features["label"].names
- num_labels = len(label_list)
- else:
- num_labels = 1
- else:
- # Trying to have good defaults here, don't hesitate to tweak to your needs.
- is_regression = raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
- if is_regression:
- num_labels = 1
- else:
- # A useful fast method:
- # https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.unique
- label_list = raw_datasets["train"].unique("label")
- label_list.sort() # Let's sort it for determinism
- num_labels = len(label_list)
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- num_labels=num_labels,
- finetuning_task=data_args.task_name,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSequenceClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
-
- # Preprocessing the raw_datasets
- if data_args.task_name is not None:
- sentence1_key, sentence2_key = task_to_keys[data_args.task_name]
- else:
- # Again, we try to have some nice defaults but don't hesitate to tweak to your use case.
- non_label_column_names = [name for name in raw_datasets["train"].column_names if name != "label"]
- if "sentence1" in non_label_column_names and "sentence2" in non_label_column_names:
- sentence1_key, sentence2_key = "sentence1", "sentence2"
- else:
- if len(non_label_column_names) >= 2:
- sentence1_key, sentence2_key = non_label_column_names[:2]
- else:
- sentence1_key, sentence2_key = non_label_column_names[0], None
-
- # Padding strategy
- if data_args.pad_to_max_length:
- padding = "max_length"
- else:
- # We will pad later, dynamically at batch creation, to the max sequence length in each batch
- padding = False
-
- # Some models have set the order of the labels to use, so let's make sure we do use it.
- label_to_id = None
- if (
- model.config.label2id != PreTrainedConfig(num_labels=num_labels).label2id
- and data_args.task_name is not None
- and not is_regression
- ):
- # Some have all caps in their config, some don't.
- label_name_to_id = {k.lower(): v for k, v in model.config.label2id.items()}
- if sorted(label_name_to_id.keys()) == sorted(label_list):
- label_to_id = {i: int(label_name_to_id[label_list[i]]) for i in range(num_labels)}
- else:
- logger.warning(
- "Your model seems to have been trained with labels, but they don't match the dataset: "
- f"model labels: {sorted(label_name_to_id.keys())}, dataset labels: {sorted(label_list)}."
- "\nIgnoring the model labels as a result.",
- )
- elif data_args.task_name is None and not is_regression:
- label_to_id = {v: i for i, v in enumerate(label_list)}
-
- if label_to_id is not None:
- model.config.label2id = label_to_id
- model.config.id2label = {id: label for label, id in config.label2id.items()}
- elif data_args.task_name is not None and not is_regression:
- model.config.label2id = {l: i for i, l in enumerate(label_list)}
- model.config.id2label = {id: label for label, id in config.label2id.items()}
-
- if data_args.max_seq_length > tokenizer.model_max_length:
- logger.warning(
- f"The max_seq_length passed ({data_args.max_seq_length}) is larger than the maximum length for the "
- f"model ({tokenizer.model_max_length}). Using max_seq_length={tokenizer.model_max_length}."
- )
- max_seq_length = min(data_args.max_seq_length, tokenizer.model_max_length)
-
- def preprocess_function(examples):
- # Tokenize the texts
- args = (
- (examples[sentence1_key],) if sentence2_key is None else (examples[sentence1_key], examples[sentence2_key])
- )
- result = tokenizer(*args, padding=padding, max_length=max_seq_length, truncation=True)
-
- # Map labels to IDs (not necessary for GLUE tasks)
- if label_to_id is not None and "label" in examples:
- result["label"] = [(label_to_id[l] if l != -1 else -1) for l in examples["label"]]
- return result
-
- with training_args.main_process_first(desc="dataset map pre-processing"):
- raw_datasets = raw_datasets.map(
- preprocess_function,
- batched=True,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- def print_class_distribution(dataset, split_name):
- label_counts = Counter(dataset["label"])
- total = sum(label_counts.values())
- logger.info(f"Class distribution in {split_name} set:")
- for label, count in label_counts.items():
- logger.info(f" Label {label}: {count} ({count / total:.2%})")
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- print_class_distribution(train_dataset, "train")
-
- if training_args.do_eval:
- if "validation" not in raw_datasets and "validation_matched" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = raw_datasets["validation_matched" if data_args.task_name == "mnli" else "validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- print_class_distribution(eval_dataset, "validation")
-
- if training_args.do_predict or data_args.task_name is not None or data_args.test_file is not None:
- if "test" not in raw_datasets and "test_matched" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_dataset = raw_datasets["test_matched" if data_args.task_name == "mnli" else "test"]
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
- print_class_distribution(predict_dataset, "test")
-
- # Log a few random samples from the training set:
- if training_args.do_train:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # Get the metric function
- if data_args.task_name is not None:
- metric = evaluate.load("glue", data_args.task_name, cache_dir=model_args.cache_dir)
- elif is_regression:
- metric = evaluate.load("mse", cache_dir=model_args.cache_dir)
- else:
- metric = evaluate.load("accuracy", cache_dir=model_args.cache_dir)
-
- # You can define your custom compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
- # predictions and label_ids field) and has to return a dictionary string to float.
- def compute_metrics(p: EvalPrediction):
- preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
- labels = p.label_ids
- if not training_args.eval_do_concat_batches:
- preds = np.concatenate(preds, axis=0)
- labels = np.concatenate(p.label_ids, axis=0)
- preds = np.squeeze(preds) if is_regression else np.argmax(preds, axis=1)
- result = metric.compute(predictions=preds, references=labels)
- if len(result) > 1:
- result["combined_score"] = np.mean(list(result.values())).item()
- return result
-
- # Data collator will default to DataCollatorWithPadding when the tokenizer is passed to Trainer, so we change it if
- # we already did the padding.
- if data_args.pad_to_max_length:
- data_collator = default_data_collator
- elif training_args.fp16:
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
- else:
- data_collator = None
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=tokenizer,
- data_collator=data_collator,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- # Loop to handle MNLI double evaluation (matched, mis-matched)
- tasks = [data_args.task_name]
- eval_datasets = [eval_dataset]
- if data_args.task_name == "mnli":
- tasks.append("mnli-mm")
- valid_mm_dataset = raw_datasets["validation_mismatched"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(valid_mm_dataset), data_args.max_eval_samples)
- valid_mm_dataset = valid_mm_dataset.select(range(max_eval_samples))
- eval_datasets.append(valid_mm_dataset)
- combined = {}
-
- for eval_dataset, task in zip(eval_datasets, tasks):
- metrics = trainer.evaluate(eval_dataset=eval_dataset)
-
- max_eval_samples = (
- data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- )
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- if task == "mnli-mm":
- metrics = {k + "_mm": v for k, v in metrics.items()}
- if task is not None and "mnli" in task:
- combined.update(metrics)
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", combined if task is not None and "mnli" in task else metrics)
-
- if training_args.do_predict:
- logger.info("*** Predict ***")
-
- # Loop to handle MNLI double evaluation (matched, mis-matched)
- tasks = [data_args.task_name]
- predict_datasets = [predict_dataset]
- if data_args.task_name == "mnli":
- tasks.append("mnli-mm")
- predict_datasets.append(raw_datasets["test_mismatched"])
-
- for predict_dataset, task in zip(predict_datasets, tasks):
- # Removing the `label` columns because it contains -1 and Trainer won't like that.
- predict_dataset = predict_dataset.remove_columns("label")
- predictions = trainer.predict(predict_dataset, metric_key_prefix="predict").predictions
- predictions = np.squeeze(predictions) if is_regression else np.argmax(predictions, axis=1)
-
- output_predict_file = os.path.join(training_args.output_dir, f"predict_results_{task}.txt")
- if trainer.is_world_process_zero():
- with open(output_predict_file, "w", encoding="utf-8") as writer:
- logger.info(f"***** Predict results {task} *****")
- writer.write("index\tprediction\n")
- for index, item in enumerate(predictions):
- if is_regression:
- writer.write(f"{index}\t{item:3.3f}\n")
- else:
- item = label_list[item]
- writer.write(f"{index}\t{item}\n")
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "text-classification"}
- if data_args.task_name is not None:
- kwargs["language"] = "en"
- kwargs["dataset_tags"] = "glue"
- kwargs["dataset_args"] = data_args.task_name
- kwargs["dataset"] = f"GLUE {data_args.task_name.upper()}"
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/text-classification/run_glue_no_trainer.py b/examples/pytorch/text-classification/run_glue_no_trainer.py
deleted file mode 100644
index a97930340911..000000000000
--- a/examples/pytorch/text-classification/run_glue_no_trainer.py
+++ /dev/null
@@ -1,699 +0,0 @@
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "scipy",
-# "scikit-learn",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""Finetuning a 🤗 Transformers model for sequence classification on GLUE."""
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSequenceClassification,
- AutoTokenizer,
- DataCollatorWithPadding,
- PreTrainedConfig,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
-
-task_to_keys = {
- "cola": ("sentence", None),
- "mnli": ("premise", "hypothesis"),
- "mrpc": ("sentence1", "sentence2"),
- "qnli": ("question", "sentence"),
- "qqp": ("question1", "question2"),
- "rte": ("sentence1", "sentence2"),
- "sst2": ("sentence", None),
- "stsb": ("sentence1", "sentence2"),
- "wnli": ("sentence1", "sentence2"),
-}
-
-
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
- parser.add_argument(
- "--task_name",
- type=str,
- default=None,
- help="The name of the glue task to train on.",
- choices=list(task_to_keys.keys()),
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--max_length",
- type=int,
- default=128,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=True,
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- type=bool,
- default=False,
- help=(
- "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
- "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
- "execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- parser.add_argument(
- "--ignore_mismatched_sizes",
- action="store_true",
- help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.task_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a task name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator = (
- Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
- )
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON training and evaluation files (see below)
- # or specify a GLUE benchmark task (the dataset will be downloaded automatically from the datasets Hub).
-
- # For CSV/JSON files, this script will use as labels the column called 'label' and as pair of sentences the
- # sentences in columns called 'sentence1' and 'sentence2' if such column exists or the first two columns not named
- # label if at least two columns are provided.
-
- # If the CSVs/JSONs contain only one non-label column, the script does single sentence classification on this
- # single column. You can easily tweak this behavior (see below)
-
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.task_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset("nyu-mll/glue", args.task_name)
- else:
- # Loading the dataset from local csv or json file.
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = (args.train_file if args.train_file is not None else args.validation_file).split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files)
- # See more about loading any type of standard or custom dataset at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Labels
- if args.task_name is not None:
- is_regression = args.task_name == "stsb"
- if not is_regression:
- label_list = raw_datasets["train"].features["label"].names
- num_labels = len(label_list)
- else:
- num_labels = 1
- else:
- # Trying to have good defaults here, don't hesitate to tweak to your needs.
- is_regression = raw_datasets["train"].features["label"].dtype in ["float32", "float64"]
- if is_regression:
- num_labels = 1
- else:
- # A useful fast method:
- # https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.unique
- label_list = raw_datasets["train"].unique("label")
- label_list.sort() # Let's sort it for determinism
- num_labels = len(label_list)
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- args.model_name_or_path,
- num_labels=num_labels,
- finetuning_task=args.task_name,
- trust_remote_code=args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- if tokenizer.pad_token is None:
- tokenizer.pad_token = tokenizer.eos_token
- config.pad_token_id = tokenizer.pad_token_id
- model = AutoModelForSequenceClassification.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- ignore_mismatched_sizes=args.ignore_mismatched_sizes,
- trust_remote_code=args.trust_remote_code,
- )
-
- # Preprocessing the datasets
- if args.task_name is not None:
- sentence1_key, sentence2_key = task_to_keys[args.task_name]
- else:
- # Again, we try to have some nice defaults but don't hesitate to tweak to your use case.
- non_label_column_names = [name for name in raw_datasets["train"].column_names if name != "label"]
- if "sentence1" in non_label_column_names and "sentence2" in non_label_column_names:
- sentence1_key, sentence2_key = "sentence1", "sentence2"
- else:
- if len(non_label_column_names) >= 2:
- sentence1_key, sentence2_key = non_label_column_names[:2]
- else:
- sentence1_key, sentence2_key = non_label_column_names[0], None
-
- # Some models have set the order of the labels to use, so let's make sure we do use it.
- label_to_id = None
- if (
- model.config.label2id != PreTrainedConfig(num_labels=num_labels).label2id
- and args.task_name is not None
- and not is_regression
- ):
- # Some have all caps in their config, some don't.
- label_name_to_id = {k.lower(): v for k, v in model.config.label2id.items()}
- if sorted(label_name_to_id.keys()) == sorted(label_list):
- logger.info(
- f"The configuration of the model provided the following label correspondence: {label_name_to_id}. "
- "Using it!"
- )
- label_to_id = {i: label_name_to_id[label_list[i]] for i in range(num_labels)}
- else:
- logger.warning(
- "Your model seems to have been trained with labels, but they don't match the dataset: "
- f"model labels: {sorted(label_name_to_id.keys())}, dataset labels: {sorted(label_list)}."
- "\nIgnoring the model labels as a result.",
- )
- elif args.task_name is None and not is_regression:
- label_to_id = {v: i for i, v in enumerate(label_list)}
-
- if label_to_id is not None:
- model.config.label2id = label_to_id
- model.config.id2label = {id: label for label, id in config.label2id.items()}
- elif args.task_name is not None and not is_regression:
- model.config.label2id = {l: i for i, l in enumerate(label_list)}
- model.config.id2label = {id: label for label, id in config.label2id.items()}
-
- padding = "max_length" if args.pad_to_max_length else False
-
- def preprocess_function(examples):
- # Tokenize the texts
- texts = (
- (examples[sentence1_key],) if sentence2_key is None else (examples[sentence1_key], examples[sentence2_key])
- )
- result = tokenizer(*texts, padding=padding, max_length=args.max_length, truncation=True)
-
- if "label" in examples:
- if label_to_id is not None:
- # Map labels to IDs (not necessary for GLUE tasks)
- result["labels"] = [label_to_id[l] for l in examples["label"]]
- else:
- # In all cases, rename the column to labels because the model will expect that.
- result["labels"] = examples["label"]
- return result
-
- with accelerator.main_process_first():
- processed_datasets = raw_datasets.map(
- preprocess_function,
- batched=True,
- remove_columns=raw_datasets["train"].column_names,
- desc="Running tokenizer on dataset",
- )
-
- train_dataset = processed_datasets["train"]
- eval_dataset = processed_datasets["validation_matched" if args.task_name == "mnli" else "validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps,
- num_training_steps=args.max_train_steps,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("glue_no_trainer", experiment_config)
-
- # Get the metric function
- if args.task_name is not None:
- metric = evaluate.load("glue", args.task_name)
- else:
- metric = evaluate.load("accuracy")
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- loss = loss / args.gradient_accumulation_steps
- accelerator.backward(loss)
- if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- samples_seen = 0
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- predictions = outputs.logits.argmax(dim=-1) if not is_regression else outputs.logits.squeeze()
- predictions, references = accelerator.gather((predictions, batch["labels"]))
- # If we are in a multiprocess environment, the last batch has duplicates
- if accelerator.num_processes > 1:
- if step == len(eval_dataloader) - 1:
- predictions = predictions[: len(eval_dataloader.dataset) - samples_seen]
- references = references[: len(eval_dataloader.dataset) - samples_seen]
- else:
- samples_seen += references.shape[0]
- metric.add_batch(
- predictions=predictions,
- references=references,
- )
-
- eval_metric = metric.compute()
- logger.info(f"epoch {epoch}: {eval_metric}")
-
- if args.with_tracking:
- accelerator.log(
- {
- "accuracy" if args.task_name is not None else "glue": eval_metric,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.task_name == "mnli":
- # Final evaluation on mismatched validation set
- eval_dataset = processed_datasets["validation_mismatched"]
- eval_dataloader = DataLoader(
- eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size
- )
- eval_dataloader = accelerator.prepare(eval_dataloader)
-
- model.eval()
- for step, batch in enumerate(eval_dataloader):
- outputs = model(**batch)
- predictions = outputs.logits.argmax(dim=-1)
- metric.add_batch(
- predictions=accelerator.gather(predictions),
- references=accelerator.gather(batch["labels"]),
- )
-
- eval_metric = metric.compute()
- logger.info(f"mnli-mm: {eval_metric}")
-
- if args.output_dir is not None:
- all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump(all_results, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/text-classification/run_xnli.py b/examples/pytorch/text-classification/run_xnli.py
deleted file mode 100755
index af6e47a5b457..000000000000
--- a/examples/pytorch/text-classification/run_xnli.py
+++ /dev/null
@@ -1,448 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
-# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "scipy",
-# "scikit-learn",
-# "protobuf",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""Finetuning multi-lingual models on XNLI (e.g. Bert, DistilBERT, XLM).
-Adapted from `examples/text-classification/run_glue.py`"""
-
-import logging
-import os
-import random
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSequenceClassification,
- AutoTokenizer,
- DataCollatorWithPadding,
- EvalPrediction,
- HfArgumentParser,
- Trainer,
- TrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/text-classification/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
-
- Using `HfArgumentParser` we can turn this class
- into argparse arguments to be able to specify them on
- the command line.
- """
-
- max_seq_length: int | None = field(
- default=128,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached preprocessed datasets or not."}
- )
- pad_to_max_length: bool = field(
- default=True,
- metadata={
- "help": (
- "Whether to pad all samples to `max_seq_length`. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- default=None, metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- language: str = field(
- default=None, metadata={"help": "Evaluation language. Also train language if `train_language` is set to None."}
- )
- train_language: str | None = field(
- default=None, metadata={"help": "Train language if it is different from the evaluation language."}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- do_lower_case: bool | None = field(
- default=False,
- metadata={"help": "arg to indicate if tokenizer should do lower case in AutoTokenizer.from_pretrained()"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether or not to allow for custom models defined on the Hub in their own modeling files. This option "
- "should only be set to `True` for repositories you trust and in which you have read the code, as it will "
- "execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # In distributed training, the load_dataset function guarantees that only one local process can concurrently
- # download the dataset.
- # Downloading and loading xnli dataset from the hub.
- if training_args.do_train:
- if model_args.train_language is None:
- train_dataset = load_dataset(
- "facebook/xnli",
- model_args.language,
- split="train",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- else:
- train_dataset = load_dataset(
- "facebook/xnli",
- model_args.train_language,
- split="train",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- label_list = train_dataset.features["label"].names
-
- if training_args.do_eval:
- eval_dataset = load_dataset(
- "facebook/xnli",
- model_args.language,
- split="validation",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- label_list = eval_dataset.features["label"].names
-
- if training_args.do_predict:
- predict_dataset = load_dataset(
- "facebook/xnli",
- model_args.language,
- split="test",
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- label_list = predict_dataset.features["label"].names
-
- # Labels
- num_labels = len(label_list)
-
- # Load pretrained model and tokenizer
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- num_labels=num_labels,
- id2label={str(i): label for i, label in enumerate(label_list)},
- label2id={label: i for i, label in enumerate(label_list)},
- finetuning_task="xnli",
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- do_lower_case=model_args.do_lower_case,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSequenceClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
-
- # Preprocessing the datasets
- # Padding strategy
- if data_args.pad_to_max_length:
- padding = "max_length"
- else:
- # We will pad later, dynamically at batch creation, to the max sequence length in each batch
- padding = False
-
- def preprocess_function(examples):
- # Tokenize the texts
- return tokenizer(
- examples["premise"],
- examples["hypothesis"],
- padding=padding,
- max_length=data_args.max_seq_length,
- truncation=True,
- )
-
- if training_args.do_train:
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- preprocess_function,
- batched=True,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- if training_args.do_eval:
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_dataset.map(
- preprocess_function,
- batched=True,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if training_args.do_predict:
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_dataset.map(
- preprocess_function,
- batched=True,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
-
- # Get the metric function
- metric = evaluate.load("xnli", cache_dir=model_args.cache_dir)
-
- # You can define your custom compute_metrics function. It takes an `EvalPrediction` object (a namedtuple with a
- # predictions and label_ids field) and has to return a dictionary string to float.
- def compute_metrics(p: EvalPrediction):
- preds = p.predictions[0] if isinstance(p.predictions, tuple) else p.predictions
- preds = np.argmax(preds, axis=1)
- return metric.compute(predictions=preds, references=p.label_ids)
-
- # Data collator will default to DataCollatorWithPadding, so we change it if we already did the padding.
- if data_args.pad_to_max_length:
- data_collator = default_data_collator
- elif training_args.fp16:
- data_collator = DataCollatorWithPadding(tokenizer, pad_to_multiple_of=8)
- else:
- data_collator = None
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- compute_metrics=compute_metrics,
- processing_class=tokenizer,
- data_collator=data_collator,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
- metrics = trainer.evaluate(eval_dataset=eval_dataset)
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Prediction
- if training_args.do_predict:
- logger.info("*** Predict ***")
- predictions, labels, metrics = trainer.predict(predict_dataset, metric_key_prefix="predict")
-
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- predictions = np.argmax(predictions, axis=1)
- output_predict_file = os.path.join(training_args.output_dir, "predictions.txt")
- if trainer.is_world_process_zero():
- with open(output_predict_file, "w", encoding="utf-8") as writer:
- writer.write("index\tprediction\n")
- for index, item in enumerate(predictions):
- item = label_list[item]
- writer.write(f"{index}\t{item}\n")
-
- trainer.end()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/text-generation/README.md b/examples/pytorch/text-generation/README.md
deleted file mode 100644
index b96bcd92241c..000000000000
--- a/examples/pytorch/text-generation/README.md
+++ /dev/null
@@ -1,31 +0,0 @@
-
-
-## Language generation
-
-Based on the script [`run_generation.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-generation/run_generation.py).
-
-Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, GPT-J, Transformer-XL, XLNet, CTRL, BLOOM, LLAMA, OPT.
-A similar script is used for our official demo [Write With Transformer](https://transformer.huggingface.co), where you
-can try out the different models available in the library.
-
-Example usage:
-
-```bash
-python run_generation.py \
- --model_type=gpt2 \
- --model_name_or_path=openai-community/gpt2
-```
diff --git a/examples/pytorch/text-generation/requirements.txt b/examples/pytorch/text-generation/requirements.txt
deleted file mode 100644
index 324a8cfb1c29..000000000000
--- a/examples/pytorch/text-generation/requirements.txt
+++ /dev/null
@@ -1,4 +0,0 @@
-accelerate >= 0.21.0
-sentencepiece != 0.1.92
-protobuf
-torch >= 1.3
diff --git a/examples/pytorch/text-generation/run_generation.py b/examples/pytorch/text-generation/run_generation.py
deleted file mode 100755
index 9d9477f8f099..000000000000
--- a/examples/pytorch/text-generation/run_generation.py
+++ /dev/null
@@ -1,448 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2018 Google AI, Google Brain and Carnegie Mellon University Authors and the HuggingFace Inc. team.
-# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.21.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "torch >= 1.3",
-# ]
-# ///
-
-"""Conditional text generation with the auto-regressive models of the library (GPT/GPT-2/CTRL/Transformer-XL/XLNet)"""
-
-import argparse
-import inspect
-import logging
-
-import torch
-from accelerate import PartialState
-from accelerate.utils import set_seed
-
-from transformers import (
- AutoTokenizer,
- BloomForCausalLM,
- CTRLLMHeadModel,
- CTRLTokenizer,
- GenerationMixin,
- GPT2LMHeadModel,
- GPT2Tokenizer,
- GPTJForCausalLM,
- LlamaForCausalLM,
- OpenAIGPTLMHeadModel,
- OpenAIGPTTokenizer,
- OPTForCausalLM,
- XLMTokenizer,
- XLMWithLMHeadModel,
- XLNetLMHeadModel,
- XLNetTokenizer,
-)
-from transformers.modeling_outputs import CausalLMOutputWithPast
-
-
-logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
-)
-logger = logging.getLogger(__name__)
-
-MAX_LENGTH = 10000 # Hardcoded max length to avoid infinite loop
-
-MODEL_CLASSES = {
- "gpt2": (GPT2LMHeadModel, GPT2Tokenizer),
- "ctrl": (CTRLLMHeadModel, CTRLTokenizer),
- "openai-gpt": (OpenAIGPTLMHeadModel, OpenAIGPTTokenizer),
- "xlnet": (XLNetLMHeadModel, XLNetTokenizer),
- "xlm": (XLMWithLMHeadModel, XLMTokenizer),
- "gptj": (GPTJForCausalLM, AutoTokenizer),
- "bloom": (BloomForCausalLM, AutoTokenizer),
- "llama": (LlamaForCausalLM, AutoTokenizer),
- "opt": (OPTForCausalLM, GPT2Tokenizer),
-}
-
-# Padding text to help Transformer-XL and XLNet with short prompts as proposed by Aman Rusia
-# in https://github.com/rusiaaman/XLNet-gen#methodology
-# and https://medium.com/@amanrusia/xlnet-speaks-comparison-to-gpt-2-ea1a4e9ba39e
-PREFIX = """In 1991, the remains of Russian Tsar Nicholas II and his family
-(except for Alexei and Maria) are discovered.
-The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
-remainder of the story. 1883 Western Siberia,
-a young Grigori Rasputin is asked by his father and a group of men to perform magic.
-Rasputin has a vision and denounces one of the men as a horse thief. Although his
-father initially slaps him for making such an accusation, Rasputin watches as the
-man is chased outside and beaten. Twenty years later, Rasputin sees a vision of
-the Virgin Mary, prompting him to become a priest. Rasputin quickly becomes famous,
-with people, even a bishop, begging for his blessing. """
-
-
-#
-# Functions to prepare models' input
-#
-
-
-def prepare_ctrl_input(args, _, tokenizer, prompt_text):
- if args.temperature > 0.7:
- logger.info("CTRL typically works better with lower temperatures (and lower top_k).")
-
- encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False)
- if not any(encoded_prompt[0] == x for x in tokenizer.control_codes.values()):
- logger.info("WARNING! You are not starting your generation from a control code so you won't get good results")
- return prompt_text
-
-
-def prepare_xlm_input(args, model, tokenizer, prompt_text):
- # kwargs = {"language": None, "mask_token_id": None}
-
- # Set the language
- use_lang_emb = hasattr(model.config, "use_lang_emb") and model.config.use_lang_emb
- if hasattr(model.config, "lang2id") and use_lang_emb:
- available_languages = model.config.lang2id.keys()
- if args.xlm_language in available_languages:
- language = args.xlm_language
- else:
- language = None
- while language not in available_languages:
- language = input("Using XLM. Select language in " + str(list(available_languages)) + " >>> ")
-
- model.config.lang_id = model.config.lang2id[language]
- # kwargs["language"] = tokenizer.lang2id[language]
-
- # TODO fix mask_token_id setup when configurations will be synchronized between models and tokenizers
- # XLM masked-language modeling (MLM) models need masked token
- # is_xlm_mlm = "mlm" in args.model_name_or_path
- # if is_xlm_mlm:
- # kwargs["mask_token_id"] = tokenizer.mask_token_id
-
- return prompt_text
-
-
-def prepare_xlnet_input(args, _, tokenizer, prompt_text):
- prefix = args.prefix if args.prefix else args.padding_text if args.padding_text else PREFIX
- prompt_text = prefix + prompt_text
- return prompt_text
-
-
-def prepare_transfoxl_input(args, _, tokenizer, prompt_text):
- prefix = args.prefix if args.prefix else args.padding_text if args.padding_text else PREFIX
- prompt_text = prefix + prompt_text
- return prompt_text
-
-
-PREPROCESSING_FUNCTIONS = {
- "ctrl": prepare_ctrl_input,
- "xlm": prepare_xlm_input,
- "xlnet": prepare_xlnet_input,
- "transfo-xl": prepare_transfoxl_input,
-}
-
-
-def adjust_length_to_model(length, max_sequence_length):
- if length < 0 and max_sequence_length > 0:
- length = max_sequence_length
- elif 0 < max_sequence_length < length:
- length = max_sequence_length # No generation bigger than model size
- elif length < 0:
- length = MAX_LENGTH # avoid infinite loop
- return length
-
-
-def sparse_model_config(model_config):
- embedding_size = None
- if hasattr(model_config, "hidden_size"):
- embedding_size = model_config.hidden_size
- elif hasattr(model_config, "n_embed"):
- embedding_size = model_config.n_embed
- elif hasattr(model_config, "n_embd"):
- embedding_size = model_config.n_embd
-
- num_head = None
- if hasattr(model_config, "num_attention_heads"):
- num_head = model_config.num_attention_heads
- elif hasattr(model_config, "n_head"):
- num_head = model_config.n_head
-
- if embedding_size is None or num_head is None or num_head == 0:
- raise ValueError("Check the model config")
-
- num_embedding_size_per_head = int(embedding_size / num_head)
- if hasattr(model_config, "n_layer"):
- num_layer = model_config.n_layer
- elif hasattr(model_config, "num_hidden_layers"):
- num_layer = model_config.num_hidden_layers
- else:
- raise ValueError("Number of hidden layers couldn't be determined from the model config")
-
- return num_layer, num_head, num_embedding_size_per_head
-
-
-def generate_past_key_values(model, batch_size, seq_len):
- num_block_layers, num_attention_heads, num_embedding_size_per_head = sparse_model_config(model.config)
- if model.config.model_type == "bloom":
- past_key_values = tuple(
- (
- torch.empty(int(num_attention_heads * batch_size), num_embedding_size_per_head, seq_len)
- .to(model.dtype)
- .to(model.device),
- torch.empty(int(num_attention_heads * batch_size), seq_len, num_embedding_size_per_head)
- .to(model.dtype)
- .to(model.device),
- )
- for _ in range(num_block_layers)
- )
- else:
- past_key_values = tuple(
- (
- torch.empty(batch_size, num_attention_heads, seq_len, num_embedding_size_per_head)
- .to(model.dtype)
- .to(model.device),
- torch.empty(batch_size, num_attention_heads, seq_len, num_embedding_size_per_head)
- .to(model.dtype)
- .to(model.device),
- )
- for _ in range(num_block_layers)
- )
- return past_key_values
-
-
-def prepare_jit_inputs(inputs, model, tokenizer):
- batch_size = len(inputs)
- dummy_input = tokenizer.batch_encode_plus(inputs, return_tensors="pt")
- dummy_input = dummy_input.to(model.device)
- if model.config.use_cache:
- dummy_input["past_key_values"] = generate_past_key_values(model, batch_size, 1)
- dummy_input["attention_mask"] = torch.cat(
- [
- torch.zeros(dummy_input["attention_mask"].shape[0], 1)
- .to(dummy_input["attention_mask"].dtype)
- .to(model.device),
- dummy_input["attention_mask"],
- ],
- -1,
- )
- return dummy_input
-
-
-class _ModelFallbackWrapper(GenerationMixin):
- __slots__ = ("_optimized", "_default")
-
- def __init__(self, optimized, default):
- self._optimized = optimized
- self._default = default
-
- def __call__(self, *args, **kwargs):
- if kwargs["past_key_values"] is None and self._default.config.use_cache:
- kwargs["past_key_values"] = generate_past_key_values(self._default, kwargs["input_ids"].shape[0], 0)
- kwargs.pop("position_ids", None)
- for k in list(kwargs.keys()):
- if kwargs[k] is None or isinstance(kwargs[k], bool):
- kwargs.pop(k)
- outputs = self._optimized(**kwargs)
- lm_logits = outputs[0]
- past_key_values = outputs[1]
- fixed_output = CausalLMOutputWithPast(
- loss=None,
- logits=lm_logits,
- past_key_values=past_key_values,
- hidden_states=None,
- attentions=None,
- )
- return fixed_output
-
- def __getattr__(self, item):
- return getattr(self._default, item)
-
- def prepare_inputs_for_generation(
- self, input_ids, past_key_values=None, inputs_embeds=None, use_cache=None, **kwargs
- ):
- return self._default.prepare_inputs_for_generation(
- input_ids, past_key_values=past_key_values, inputs_embeds=inputs_embeds, use_cache=use_cache, **kwargs
- )
-
- def _reorder_cache(
- self, past_key_values: tuple[tuple[torch.Tensor]], beam_idx: torch.Tensor
- ) -> tuple[tuple[torch.Tensor]]:
- """
- This function is used to re-order the `past_key_values` cache if [`~PretrainedModel.beam_search`] or
- [`~PretrainedModel.beam_sample`] is called. This is required to match `past_key_values` with the correct
- beam_idx at every generation step.
- """
- return self._default._reorder_cache(past_key_values, beam_idx)
-
-
-def main():
- parser = argparse.ArgumentParser()
- parser.add_argument(
- "--model_type",
- default=None,
- type=str,
- required=True,
- help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
- )
- parser.add_argument(
- "--model_name_or_path",
- default=None,
- type=str,
- required=True,
- help="Path to pre-trained model or shortcut name selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
- )
-
- parser.add_argument("--prompt", type=str, default="")
- parser.add_argument("--length", type=int, default=20)
- parser.add_argument("--stop_token", type=str, default=None, help="Token at which text generation is stopped")
-
- parser.add_argument(
- "--temperature",
- type=float,
- default=1.0,
- help="temperature of 1.0 has no effect, lower tend toward greedy sampling",
- )
- parser.add_argument(
- "--repetition_penalty", type=float, default=1.0, help="primarily useful for CTRL model; in that case, use 1.2"
- )
- parser.add_argument("--k", type=int, default=0)
- parser.add_argument("--p", type=float, default=0.9)
-
- parser.add_argument("--prefix", type=str, default="", help="Text added prior to input.")
- parser.add_argument("--padding_text", type=str, default="", help="Deprecated, the use of `--prefix` is preferred.")
- parser.add_argument("--xlm_language", type=str, default="", help="Optional language when used with the XLM model.")
-
- parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
- parser.add_argument(
- "--use_cpu",
- action="store_true",
- help="Whether or not to use cpu. If set to False, we will use gpu/npu or mps device if available",
- )
- parser.add_argument("--num_return_sequences", type=int, default=1, help="The number of samples to generate.")
- parser.add_argument(
- "--fp16",
- action="store_true",
- help="Whether to use 16-bit (mixed) precision instead of 32-bit",
- )
- parser.add_argument("--jit", action="store_true", help="Whether or not to use jit trace to accelerate inference")
- args = parser.parse_args()
-
- # Initialize the distributed state.
- distributed_state = PartialState(cpu=args.use_cpu)
-
- logger.warning(f"device: {distributed_state.device}, 16-bits inference: {args.fp16}")
-
- if args.seed is not None:
- set_seed(args.seed)
-
- # Initialize the model and tokenizer
- try:
- args.model_type = args.model_type.lower()
- model_class, tokenizer_class = MODEL_CLASSES[args.model_type]
- except KeyError:
- raise KeyError("the model {} you specified is not supported. You are welcome to add it and open a PR :)")
-
- tokenizer = tokenizer_class.from_pretrained(args.model_name_or_path)
- if tokenizer.pad_token is None:
- tokenizer.pad_token = tokenizer.eos_token
- model = model_class.from_pretrained(args.model_name_or_path)
-
- # Set the model to the right device
- model.to(distributed_state.device)
-
- if args.fp16:
- model.half()
- max_seq_length = getattr(model.config, "max_position_embeddings", 0)
- args.length = adjust_length_to_model(args.length, max_sequence_length=max_seq_length)
- logger.info(args)
-
- prompt_text = args.prompt if args.prompt else input("Model prompt >>> ")
-
- # Different models need different input formatting and/or extra arguments
- requires_preprocessing = args.model_type in PREPROCESSING_FUNCTIONS
- if requires_preprocessing:
- prepare_input = PREPROCESSING_FUNCTIONS.get(args.model_type)
- preprocessed_prompt_text = prepare_input(args, model, tokenizer, prompt_text)
-
- tokenizer_kwargs = {}
-
- encoded_prompt = tokenizer.encode(
- preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt", **tokenizer_kwargs
- )
- else:
- prefix = args.prefix if args.prefix else args.padding_text
- encoded_prompt = tokenizer.encode(prefix + prompt_text, add_special_tokens=False, return_tensors="pt")
- encoded_prompt = encoded_prompt.to(distributed_state.device)
-
- if encoded_prompt.size()[-1] == 0:
- input_ids = None
- else:
- input_ids = encoded_prompt
-
- if args.jit:
- jit_input_texts = ["enable jit"]
- jit_inputs = prepare_jit_inputs(jit_input_texts, model, tokenizer)
- torch._C._jit_set_texpr_fuser_enabled(False)
- model.config.return_dict = False
- if hasattr(model, "forward"):
- sig = inspect.signature(model.forward)
- else:
- sig = inspect.signature(model.__call__)
- jit_inputs = tuple(jit_inputs[key] for key in sig.parameters if jit_inputs.get(key, None) is not None)
- traced_model = torch.jit.trace(model, jit_inputs, strict=False)
- traced_model = torch.jit.freeze(traced_model.eval())
- traced_model(*jit_inputs)
- traced_model(*jit_inputs)
-
- model = _ModelFallbackWrapper(traced_model, model)
-
- output_sequences = model.generate(
- input_ids=input_ids,
- max_length=args.length + len(encoded_prompt[0]),
- temperature=args.temperature,
- top_k=args.k,
- top_p=args.p,
- repetition_penalty=args.repetition_penalty,
- do_sample=True,
- num_return_sequences=args.num_return_sequences,
- )
-
- # Remove the batch dimension when returning multiple sequences
- if len(output_sequences.shape) > 2:
- output_sequences.squeeze_()
-
- generated_sequences = []
-
- for generated_sequence_idx, generated_sequence in enumerate(output_sequences):
- print(f"=== GENERATED SEQUENCE {generated_sequence_idx + 1} ===")
- generated_sequence = generated_sequence.tolist()
-
- # Decode text
- text = tokenizer.decode(generated_sequence, clean_up_tokenization_spaces=True)
-
- # Remove all text after the stop token
- text = text[: text.find(args.stop_token) if args.stop_token else None]
-
- # Add the prompt at the beginning of the sequence. Remove the excess text that was used for pre-processing
- total_sequence = (
- prompt_text + text[len(tokenizer.decode(encoded_prompt[0], clean_up_tokenization_spaces=True)) :]
- )
-
- generated_sequences.append(total_sequence)
- print(total_sequence)
-
- return generated_sequences
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/token-classification/README.md b/examples/pytorch/token-classification/README.md
deleted file mode 100644
index b4db0ba8dfad..000000000000
--- a/examples/pytorch/token-classification/README.md
+++ /dev/null
@@ -1,146 +0,0 @@
-
-
-# Token classification
-
-## PyTorch version
-
-Fine-tuning the library models for token classification task such as Named Entity Recognition (NER), Parts-of-speech
-tagging (POS) or phrase extraction (CHUNKS). The main script `run_ner.py` leverages the 🤗 Datasets library and the Trainer API. You can easily
-customize it to your needs if you need extra processing on your datasets.
-
-It will either run on a datasets hosted on our [hub](https://huggingface.co/datasets) or with your own text files for
-training and validation, you might just need to add some tweaks in the data preprocessing.
-
-### Using your own data
-
-If you use your own data, the script expects the following format of the data -
-
-```bash
-{
- "chunk_tags": [11, 12, 12, 21, 13, 11, 11, 21, 13, 11, 12, 13, 11, 21, 22, 11, 12, 17, 11, 21, 17, 11, 12, 12, 21, 22, 22, 13, 11, 0],
- "id": "0",
- "ner_tags": [0, 3, 4, 0, 0, 0, 0, 0, 0, 7, 0, 0, 0, 0, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
- "pos_tags": [12, 22, 22, 38, 15, 22, 28, 38, 15, 16, 21, 35, 24, 35, 37, 16, 21, 15, 24, 41, 15, 16, 21, 21, 20, 37, 40, 35, 21, 7],
- "tokens": ["The", "European", "Commission", "said", "on", "Thursday", "it", "disagreed", "with", "German", "advice", "to", "consumers", "to", "shun", "British", "lamb", "until", "scientists", "determine", "whether", "mad", "cow", "disease", "can", "be", "transmitted", "to", "sheep", "."]
-}
-```
-
-The following example fine-tunes BERT on CoNLL-2003:
-
-```bash
-python run_ner.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --dataset_name tomaarsen/conll2003 \
- --output_dir /tmp/test-ner \
- --do_train \
- --do_eval
-```
-
-or just can just run the bash script `run.sh`.
-
-To run on your own training and validation files, use the following command:
-
-```bash
-python run_ner.py \
- --model_name_or_path google-bert/bert-base-uncased \
- --train_file path_to_train_file \
- --validation_file path_to_validation_file \
- --output_dir /tmp/test-ner \
- --do_train \
- --do_eval
-```
-
-**Note:** This script only works with models that have a fast tokenizer (backed by the 🤗 Tokenizers library) as it
-uses special features of those tokenizers. You can check if your favorite model has a fast tokenizer in
-[this table](https://huggingface.co/transformers/index.html#supported-frameworks), if it doesn't you can still use the old version
-of the script.
-
-> If your model classification head dimensions do not fit the number of labels in the dataset, you can specify `--ignore_mismatched_sizes` to adapt it.
-
-## Old version of the script
-
-You can find the old version of the PyTorch script [here](https://github.com/huggingface/transformers/blob/main/examples/legacy/token-classification/run_ner.py).
-
-## Pytorch version, no Trainer
-
-Based on the script [run_ner_no_trainer.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/token-classification/run_ner_no_trainer.py).
-
-Like `run_ner.py`, this script allows you to fine-tune any of the models on the [hub](https://huggingface.co/models) on a
-token classification task, either NER, POS or CHUNKS tasks or your own data in a csv or a JSON file. The main difference is that this
-script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
-the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-export TASK_NAME=ner
-
-python run_ner_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --dataset_name tomaarsen/conll2003 \
- --task_name $TASK_NAME \
- --max_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-export TASK_NAME=ner
-
-accelerate launch run_ner_no_trainer.py \
- --model_name_or_path google-bert/bert-base-cased \
- --dataset_name tomaarsen/conll2003 \
- --task_name $TASK_NAME \
- --max_length 128 \
- --per_device_train_batch_size 32 \
- --learning_rate 2e-5 \
- --num_train_epochs 3 \
- --output_dir /tmp/$TASK_NAME/
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/examples/pytorch/token-classification/requirements.txt b/examples/pytorch/token-classification/requirements.txt
deleted file mode 100644
index 53740bf4e81a..000000000000
--- a/examples/pytorch/token-classification/requirements.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-accelerate >= 0.12.0
-seqeval
-datasets >= 1.8.0
-torch >= 1.3
-evaluate
\ No newline at end of file
diff --git a/examples/pytorch/token-classification/run.sh b/examples/pytorch/token-classification/run.sh
deleted file mode 100755
index 81e2557bf11e..000000000000
--- a/examples/pytorch/token-classification/run.sh
+++ /dev/null
@@ -1,20 +0,0 @@
-# Copyright 2020 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-python3 run_ner.py \
- --model_name_or_path bert-base-uncased \
- --dataset_name tomaarsen/conll2003 \
- --output_dir /tmp/test-ner \
- --do_train \
- --do_eval
diff --git a/examples/pytorch/token-classification/run_ner.py b/examples/pytorch/token-classification/run_ner.py
deleted file mode 100755
index 0138d5b6fed1..000000000000
--- a/examples/pytorch/token-classification/run_ner.py
+++ /dev/null
@@ -1,643 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2020 The HuggingFace Team All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "seqeval",
-# "datasets >= 1.8.0",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for token classification.
-"""
-# You can also adapt this script on your own token classification task and datasets. Pointers for this are left as
-# comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import ClassLabel, load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForTokenClassification,
- AutoTokenizer,
- DataCollatorForTokenClassification,
- HfArgumentParser,
- PreTrainedConfig,
- Trainer,
- TrainingArguments,
- set_seed,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/token-classification/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where do you want to store the pretrained models downloaded from huggingface.co"},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
- ignore_mismatched_sizes: bool = field(
- default=False,
- metadata={"help": "Will enable to load a pretrained model whose head dimensions are different."},
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- task_name: str | None = field(default="ner", metadata={"help": "The name of the task (ner, pos...)."})
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(
- default=None, metadata={"help": "The input training data file (a csv or JSON file)."}
- )
- validation_file: str | None = field(
- default=None,
- metadata={"help": "An optional input evaluation data file to evaluate on (a csv or JSON file)."},
- )
- test_file: str | None = field(
- default=None,
- metadata={"help": "An optional input test data file to predict on (a csv or JSON file)."},
- )
- text_column_name: str | None = field(
- default=None, metadata={"help": "The column name of text to input in the file (a csv or JSON file)."}
- )
- label_column_name: str | None = field(
- default=None, metadata={"help": "The column name of label to input in the file (a csv or JSON file)."}
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_seq_length: int = field(
- default=None,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. If set, sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to model maximum sentence length. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
- "efficient on GPU but very bad for TPU."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- label_all_tokens: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to put the label for one word on all tokens of generated by that word or just on the "
- "one (in which case the other tokens will have a padding index)."
- )
- },
- )
- return_entity_level_metrics: bool = field(
- default=False,
- metadata={"help": "Whether to return all the entity levels during evaluation or just the overall ones."},
- )
-
- def __post_init__(self):
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- else:
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
- self.task_name = self.task_name.lower()
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files, cache_dir=model_args.cache_dir)
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- features = raw_datasets["train"].features
- else:
- column_names = raw_datasets["validation"].column_names
- features = raw_datasets["validation"].features
-
- if data_args.text_column_name is not None:
- text_column_name = data_args.text_column_name
- elif "tokens" in column_names:
- text_column_name = "tokens"
- else:
- text_column_name = column_names[0]
-
- if data_args.label_column_name is not None:
- label_column_name = data_args.label_column_name
- elif f"{data_args.task_name}_tags" in column_names:
- label_column_name = f"{data_args.task_name}_tags"
- else:
- label_column_name = column_names[1]
-
- # In the event the labels are not a `Sequence[ClassLabel]`, we will need to go through the dataset to get the
- # unique labels.
- def get_label_list(labels):
- unique_labels = set()
- for label in labels:
- unique_labels = unique_labels | set(label)
- label_list = list(unique_labels)
- label_list.sort()
- return label_list
-
- # If the labels are of type ClassLabel, they are already integers and we have the map stored somewhere.
- # Otherwise, we have to get the list of labels manually.
- labels_are_int = isinstance(features[label_column_name].feature, ClassLabel)
- if labels_are_int:
- label_list = features[label_column_name].feature.names
- label_to_id = {i: i for i in range(len(label_list))}
- else:
- label_list = get_label_list(raw_datasets["train"][label_column_name])
- label_to_id = {l: i for i, l in enumerate(label_list)}
-
- num_labels = len(label_list)
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- num_labels=num_labels,
- finetuning_task=data_args.task_name,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- tokenizer_name_or_path = model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path
- if config.model_type in {"bloom", "gpt2", "roberta", "deberta"}:
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=True,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- add_prefix_space=True,
- )
- else:
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=True,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- model = AutoModelForTokenClassification.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- ignore_mismatched_sizes=model_args.ignore_mismatched_sizes,
- )
-
- # Tokenizer check: this script requires a fast tokenizer.
- # Check if tokenizer has _tokenizer attribute (from tokenizers library) or is_fast property
- if not (hasattr(tokenizer, "_tokenizer") or getattr(tokenizer, "is_fast", False)):
- raise TypeError(
- "This example script only works for models that have a fast tokenizer. Check out the big table of models at"
- " https://huggingface.co/transformers/index.html#supported-frameworks to find the model types that meet"
- " this requirement"
- )
-
- # Model has labels -> use them.
- if model.config.label2id != PreTrainedConfig(num_labels=num_labels).label2id:
- if sorted(model.config.label2id.keys()) == sorted(label_list):
- # Reorganize `label_list` to match the ordering of the model.
- if labels_are_int:
- label_to_id = {i: int(model.config.label2id[l]) for i, l in enumerate(label_list)}
- label_list = [model.config.id2label[i] for i in range(num_labels)]
- else:
- label_list = [model.config.id2label[i] for i in range(num_labels)]
- label_to_id = {l: i for i, l in enumerate(label_list)}
- else:
- logger.warning(
- "Your model seems to have been trained with labels, but they don't match the dataset: "
- f"model labels: {sorted(model.config.label2id.keys())}, dataset labels:"
- f" {sorted(label_list)}.\nIgnoring the model labels as a result.",
- )
-
- # Set the correspondences label/ID inside the model config
- model.config.label2id = {l: i for i, l in enumerate(label_list)}
- model.config.id2label = dict(enumerate(label_list))
-
- # Map that sends B-Xxx label to its I-Xxx counterpart
- b_to_i_label = []
- for idx, label in enumerate(label_list):
- if label.startswith("B-") and label.replace("B-", "I-") in label_list:
- b_to_i_label.append(label_list.index(label.replace("B-", "I-")))
- else:
- b_to_i_label.append(idx)
-
- # Preprocessing the dataset
- # Padding strategy
- padding = "max_length" if data_args.pad_to_max_length else False
-
- # Tokenize all texts and align the labels with them.
- def tokenize_and_align_labels(examples):
- tokenized_inputs = tokenizer(
- examples[text_column_name],
- padding=padding,
- truncation=True,
- max_length=data_args.max_seq_length,
- # We use this argument because the texts in our dataset are lists of words (with a label for each word).
- is_split_into_words=True,
- )
- labels = []
- for i, label in enumerate(examples[label_column_name]):
- word_ids = tokenized_inputs.word_ids(batch_index=i)
- previous_word_idx = None
- label_ids = []
- for word_idx in word_ids:
- # Special tokens have a word id that is None. We set the label to -100 so they are automatically
- # ignored in the loss function.
- if word_idx is None:
- label_ids.append(-100)
- # We set the label for the first token of each word.
- elif word_idx != previous_word_idx:
- label_ids.append(label_to_id[label[word_idx]])
- # For the other tokens in a word, we set the label to either the current label or -100, depending on
- # the label_all_tokens flag.
- else:
- if data_args.label_all_tokens:
- label_ids.append(b_to_i_label[label_to_id[label[word_idx]]])
- else:
- label_ids.append(-100)
- previous_word_idx = word_idx
-
- labels.append(label_ids)
- tokenized_inputs["labels"] = labels
- return tokenized_inputs
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- tokenize_and_align_labels,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
-
- if training_args.do_eval:
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_dataset.map(
- tokenize_and_align_labels,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if training_args.do_predict:
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_dataset = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_dataset.map(
- tokenize_and_align_labels,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
-
- # Data collator
- data_collator = DataCollatorForTokenClassification(tokenizer, pad_to_multiple_of=8 if training_args.fp16 else None)
-
- # Metrics
- metric = evaluate.load("seqeval", cache_dir=model_args.cache_dir)
-
- def compute_metrics(p):
- predictions, labels = p
- if not training_args.eval_do_concat_batches:
- predictions = np.hstack(predictions)
- labels = np.hstack(labels)
- predictions = np.argmax(predictions, axis=2)
-
- # Remove ignored index (special tokens)
- true_predictions = [
- [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
- for prediction, label in zip(predictions, labels)
- ]
- true_labels = [
- [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
- for prediction, label in zip(predictions, labels)
- ]
-
- results = metric.compute(predictions=true_predictions, references=true_labels)
- if data_args.return_entity_level_metrics:
- # Unpack nested dictionaries
- final_results = {}
- for key, value in results.items():
- if isinstance(value, dict):
- for n, v in value.items():
- final_results[f"{key}_{n}"] = v
- else:
- final_results[key] = value
- return final_results
- else:
- return {
- "precision": results["overall_precision"],
- "recall": results["overall_recall"],
- "f1": results["overall_f1"],
- "accuracy": results["overall_accuracy"],
- }
-
- # Initialize our Trainer
- trainer = Trainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- metrics = train_result.metrics
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate()
-
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- # Predict
- if training_args.do_predict:
- logger.info("*** Predict ***")
-
- predictions, labels, metrics = trainer.predict(predict_dataset, metric_key_prefix="predict")
- predictions = np.argmax(predictions, axis=2)
-
- # Remove ignored index (special tokens)
- true_predictions = [
- [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
- for prediction, label in zip(predictions, labels)
- ]
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- # Save predictions
- output_predictions_file = os.path.join(training_args.output_dir, "predictions.txt")
- if trainer.is_world_process_zero():
- with open(output_predictions_file, "w", encoding="utf-8") as writer:
- writer.writelines(" ".join(prediction) + "\n" for prediction in true_predictions)
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "token-classification"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/token-classification/run_ner_no_trainer.py b/examples/pytorch/token-classification/run_ner_no_trainer.py
deleted file mode 100755
index da9d7978a6f3..000000000000
--- a/examples/pytorch/token-classification/run_ner_no_trainer.py
+++ /dev/null
@@ -1,842 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "seqeval",
-# "datasets >= 1.8.0",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning a 🤗 Transformers model on token classification tasks (NER, POS, CHUNKS) relying on the accelerate library
-without using a Trainer.
-"""
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import ClassLabel, load_dataset
-from huggingface_hub import HfApi
-from torch import nn
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForTokenClassification,
- AutoTokenizer,
- DataCollatorForTokenClassification,
- PreTrainedConfig,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.trainer_pt_utils import get_parameter_names
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/token-classification/requirements.txt")
-
-# You should update this to your particular problem to have better documentation of `model_type`
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-def parse_args():
- parser = argparse.ArgumentParser(
- description="Finetune a transformers model on a text classification task (NER) with accelerate library"
- )
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--text_column_name",
- type=str,
- default=None,
- help="The column name of text to input in the file (a csv or JSON file).",
- )
- parser.add_argument(
- "--label_column_name",
- type=str,
- default=None,
- help="The column name of label to input in the file (a csv or JSON file).",
- )
- parser.add_argument(
- "--max_length",
- type=int,
- default=128,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- action="store_true",
- help="If passed, pad all samples to `max_length`. Otherwise, dynamic padding is used.",
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument(
- "--label_all_tokens",
- action="store_true",
- help="Setting labels of all special tokens to -100 and thus PyTorch will ignore them.",
- )
- parser.add_argument(
- "--return_entity_level_metrics",
- action="store_true",
- help="Indication whether entity level metrics are to be returner.",
- )
- parser.add_argument(
- "--task_name",
- type=str,
- default="ner",
- choices=["ner", "pos", "chunk"],
- help="The name of the task.",
- )
- parser.add_argument(
- "--debug",
- action="store_true",
- help="Activate debug mode and run training only with a subset of data.",
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- parser.add_argument(
- "--ignore_mismatched_sizes",
- action="store_true",
- help="Whether or not to enable to load a pretrained model whose head dimensions are different.",
- )
- args = parser.parse_args()
-
- # Sanity checks
- if args.task_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a task name or a training/validation file.")
- else:
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator = (
- Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
- )
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets for token classification task available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'tokens' or the first column if no column called
- # 'tokens' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files)
- # Trim a number of training examples
- if args.debug:
- for split in raw_datasets:
- raw_datasets[split] = raw_datasets[split].select(range(100))
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- if raw_datasets["train"] is not None:
- column_names = raw_datasets["train"].column_names
- features = raw_datasets["train"].features
- else:
- column_names = raw_datasets["validation"].column_names
- features = raw_datasets["validation"].features
-
- if args.text_column_name is not None:
- text_column_name = args.text_column_name
- elif "tokens" in column_names:
- text_column_name = "tokens"
- else:
- text_column_name = column_names[0]
-
- if args.label_column_name is not None:
- label_column_name = args.label_column_name
- elif f"{args.task_name}_tags" in column_names:
- label_column_name = f"{args.task_name}_tags"
- else:
- label_column_name = column_names[1]
-
- # In the event the labels are not a `Sequence[ClassLabel]`, we will need to go through the dataset to get the
- # unique labels.
- def get_label_list(labels):
- unique_labels = set()
- for label in labels:
- unique_labels = unique_labels | set(label)
- label_list = list(unique_labels)
- label_list.sort()
- return label_list
-
- # If the labels are of type ClassLabel, they are already integers and we have the map stored somewhere.
- # Otherwise, we have to get the list of labels manually.
- labels_are_int = isinstance(features[label_column_name].feature, ClassLabel)
- if labels_are_int:
- label_list = features[label_column_name].feature.names
- label_to_id = {i: i for i in range(len(label_list))}
- else:
- label_list = get_label_list(raw_datasets["train"][label_column_name])
- label_to_id = {l: i for i, l in enumerate(label_list)}
-
- num_labels = len(label_list)
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(
- args.config_name, num_labels=num_labels, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(
- args.model_name_or_path, num_labels=num_labels, trust_remote_code=args.trust_remote_code
- )
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- tokenizer_name_or_path = args.tokenizer_name if args.tokenizer_name else args.model_name_or_path
- if not tokenizer_name_or_path:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if config.model_type in {"bloom", "gpt2", "roberta"}:
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path, use_fast=True, add_prefix_space=True, trust_remote_code=args.trust_remote_code
- )
- else:
- tokenizer = AutoTokenizer.from_pretrained(
- tokenizer_name_or_path, use_fast=True, trust_remote_code=args.trust_remote_code
- )
-
- if args.model_name_or_path:
- model = AutoModelForTokenClassification.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- ignore_mismatched_sizes=args.ignore_mismatched_sizes,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForTokenClassification.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Model has labels -> use them.
- if model.config.label2id != PreTrainedConfig(num_labels=num_labels).label2id:
- if sorted(model.config.label2id.keys()) == sorted(label_list):
- # Reorganize `label_list` to match the ordering of the model.
- if labels_are_int:
- label_to_id = {i: int(model.config.label2id[l]) for i, l in enumerate(label_list)}
- label_list = [model.config.id2label[i] for i in range(num_labels)]
- else:
- label_list = [model.config.id2label[i] for i in range(num_labels)]
- label_to_id = {l: i for i, l in enumerate(label_list)}
- else:
- logger.warning(
- "Your model seems to have been trained with labels, but they don't match the dataset: "
- f"model labels: {sorted(model.config.label2id.keys())}, dataset labels:"
- f" {sorted(label_list)}.\nIgnoring the model labels as a result.",
- )
-
- # Set the correspondences label/ID inside the model config
- model.config.label2id = {l: i for i, l in enumerate(label_list)}
- model.config.id2label = dict(enumerate(label_list))
-
- # Map that sends B-Xxx label to its I-Xxx counterpart
- b_to_i_label = []
- for idx, label in enumerate(label_list):
- if label.startswith("B-") and label.replace("B-", "I-") in label_list:
- b_to_i_label.append(label_list.index(label.replace("B-", "I-")))
- else:
- b_to_i_label.append(idx)
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- padding = "max_length" if args.pad_to_max_length else False
-
- # Tokenize all texts and align the labels with them.
-
- def tokenize_and_align_labels(examples):
- tokenized_inputs = tokenizer(
- examples[text_column_name],
- max_length=args.max_length,
- padding=padding,
- truncation=True,
- # We use this argument because the texts in our dataset are lists of words (with a label for each word).
- is_split_into_words=True,
- )
-
- labels = []
- for i, label in enumerate(examples[label_column_name]):
- word_ids = tokenized_inputs.word_ids(batch_index=i)
- previous_word_idx = None
- label_ids = []
- for word_idx in word_ids:
- # Special tokens have a word id that is None. We set the label to -100 so they are automatically
- # ignored in the loss function.
- if word_idx is None:
- label_ids.append(-100)
- # We set the label for the first token of each word.
- elif word_idx != previous_word_idx:
- label_ids.append(label_to_id[label[word_idx]])
- # For the other tokens in a word, we set the label to either the current label or -100, depending on
- # the label_all_tokens flag.
- else:
- if args.label_all_tokens:
- label_ids.append(b_to_i_label[label_to_id[label[word_idx]]])
- else:
- label_ids.append(-100)
- previous_word_idx = word_idx
-
- labels.append(label_ids)
- tokenized_inputs["labels"] = labels
- return tokenized_inputs
-
- with accelerator.main_process_first():
- processed_raw_datasets = raw_datasets.map(
- tokenize_and_align_labels,
- batched=True,
- remove_columns=raw_datasets["train"].column_names,
- desc="Running tokenizer on dataset",
- )
-
- train_dataset = processed_raw_datasets["train"]
- eval_dataset = processed_raw_datasets["validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorForTokenClassification` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorForTokenClassification(tokenizer, pad_to_multiple_of=pad_to_multiple_of)
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- forbidden_name_patterns = [r"bias", r"layernorm", r"rmsnorm", r"(?:^|\.)norm(?:$|\.)", r"_norm(?:$|\.)"]
- decay_parameters = get_parameter_names(model, [nn.LayerNorm], forbidden_layer_names=forbidden_name_patterns)
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if n in decay_parameters and p.requires_grad],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if n not in decay_parameters and p.requires_grad],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Use the device given by the `accelerator` object.
- device = accelerator.device
- model.to(device)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps,
- num_training_steps=args.max_train_steps,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
-
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # The trackers initializes automatically on the main process.
- if args.with_tracking:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("ner_no_trainer", experiment_config)
-
- # Metrics
- metric = evaluate.load("seqeval")
-
- def get_labels(predictions, references):
- # Transform predictions and references tensos to numpy arrays
- if device.type == "cpu":
- y_pred = predictions.detach().clone().numpy()
- y_true = references.detach().clone().numpy()
- else:
- y_pred = predictions.detach().cpu().clone().numpy()
- y_true = references.detach().cpu().clone().numpy()
-
- # Remove ignored index (special tokens)
- true_predictions = [
- [label_list[p] for (p, l) in zip(pred, gold_label) if l != -100]
- for pred, gold_label in zip(y_pred, y_true)
- ]
- true_labels = [
- [label_list[l] for (p, l) in zip(pred, gold_label) if l != -100]
- for pred, gold_label in zip(y_pred, y_true)
- ]
- return true_predictions, true_labels
-
- def compute_metrics():
- results = metric.compute()
- if args.return_entity_level_metrics:
- # Unpack nested dictionaries
- final_results = {}
- for key, value in results.items():
- if isinstance(value, dict):
- for n, v in value.items():
- final_results[f"{key}_{n}"] = v
- else:
- final_results[key] = value
- return final_results
- else:
- return {
- "precision": results["overall_precision"],
- "recall": results["overall_recall"],
- "f1": results["overall_f1"],
- "accuracy": results["overall_accuracy"],
- }
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- loss = loss / args.gradient_accumulation_steps
- accelerator.backward(loss)
- if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
- samples_seen = 0
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- outputs = model(**batch)
- predictions = outputs.logits.argmax(dim=-1)
- labels = batch["labels"]
- if not args.pad_to_max_length: # necessary to pad predictions and labels for being gathered
- predictions = accelerator.pad_across_processes(predictions, dim=1, pad_index=-100)
- labels = accelerator.pad_across_processes(labels, dim=1, pad_index=-100)
- predictions_gathered, labels_gathered = accelerator.gather((predictions, labels))
- # If we are in a multiprocess environment, the last batch has duplicates
- if accelerator.num_processes > 1:
- if step == len(eval_dataloader) - 1:
- predictions_gathered = predictions_gathered[: len(eval_dataloader.dataset) - samples_seen]
- labels_gathered = labels_gathered[: len(eval_dataloader.dataset) - samples_seen]
- else:
- samples_seen += labels_gathered.shape[0]
- preds, refs = get_labels(predictions_gathered, labels_gathered)
- metric.add_batch(
- predictions=preds,
- references=refs,
- ) # predictions and preferences are expected to be a nested list of labels, not label_ids
-
- eval_metric = compute_metrics()
- accelerator.print(f"epoch {epoch}:", eval_metric)
- if args.with_tracking:
- accelerator.log(
- {
- "seqeval": eval_metric,
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- all_results = {f"eval_{k}": v for k, v in eval_metric.items()}
- if args.with_tracking:
- all_results.update({"train_loss": total_loss.item() / len(train_dataloader)})
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- # Convert all float64 & int64 type numbers to float & int for json serialization
- for key, value in all_results.items():
- if isinstance(value, np.float64):
- all_results[key] = float(value)
- elif isinstance(value, np.int64):
- all_results[key] = int(value)
- json.dump(all_results, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/token-classification/run_no_trainer.sh b/examples/pytorch/token-classification/run_no_trainer.sh
deleted file mode 100755
index 8987e92cffbf..000000000000
--- a/examples/pytorch/token-classification/run_no_trainer.sh
+++ /dev/null
@@ -1,21 +0,0 @@
-# Copyright 2020 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-accelerate launch run_ner_no_trainer.py \
- --model_name_or_path bert-base-uncased \
- --dataset_name tomaarsen/conll2003 \
- --output_dir /tmp/test-ner \
- --pad_to_max_length \
- --task_name ner \
- --return_entity_level_metrics
diff --git a/examples/pytorch/translation/README.md b/examples/pytorch/translation/README.md
deleted file mode 100644
index 2cb7c5eb86e0..000000000000
--- a/examples/pytorch/translation/README.md
+++ /dev/null
@@ -1,206 +0,0 @@
-
-
-## Translation
-
-This directory contains examples for finetuning and evaluating transformers on translation tasks.
-Please tag @patil-suraj with any issues/unexpected behaviors, or send a PR!
-For deprecated `bertabs` instructions, see https://github.com/huggingface/transformers-research-projects/blob/main/bertabs/README.md.
-For the old `finetune_trainer.py` and related utils, see [`examples/legacy/seq2seq`](https://github.com/huggingface/transformers/blob/main/examples/legacy/seq2seq).
-
-### Supported Architectures
-
-- `BartForConditionalGeneration`
-- `FSMTForConditionalGeneration` (translation only)
-- `MBartForConditionalGeneration`
-- `MarianMTModel`
-- `PegasusForConditionalGeneration`
-- `T5ForConditionalGeneration`
-- `MT5ForConditionalGeneration`
-
-`run_translation.py` is a lightweight examples of how to download and preprocess a dataset from the [🤗 Datasets](https://github.com/huggingface/datasets) library or use your own files (jsonlines or csv), then fine-tune one of the architectures above on it.
-
-For custom datasets in `jsonlines` format please see: https://huggingface.co/docs/datasets/loading_datasets#json-files
-and you also will find examples of these below.
-
-
-## With Trainer
-
-Here is an example of a translation fine-tuning with a MarianMT model:
-
-```bash
-python run_translation.py \
- --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
- --do_train \
- --do_eval \
- --source_lang en \
- --target_lang ro \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --output_dir /tmp/tst-translation \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-MBart and some T5 models require special handling.
-
-T5 models `google-t5/t5-small`, `google-t5/t5-base`, `google-t5/t5-large`, `google-t5/t5-3b` and `google-t5/t5-11b` must use an additional argument: `--source_prefix "translate {source_lang} to {target_lang}"`. For example:
-
-```bash
-python run_translation.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --source_lang en \
- --target_lang ro \
- --source_prefix "translate English to Romanian: " \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --output_dir /tmp/tst-translation \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-If you get a terrible BLEU score, make sure that you didn't forget to use the `--source_prefix` argument.
-
-For the aforementioned group of T5 models it's important to remember that if you switch to a different language pair, make sure to adjust the source and target values in all 3 language-specific command line argument: `--source_lang`, `--target_lang` and `--source_prefix`.
-
-MBart models require a different format for `--source_lang` and `--target_lang` values, e.g. instead of `en` it expects `en_XX`, for `ro` it expects `ro_RO`. The full MBart specification for language codes can be found [here](https://huggingface.co/facebook/mbart-large-cc25). For example:
-
-```bash
-python run_translation.py \
- --model_name_or_path facebook/mbart-large-en-ro \
- --do_train \
- --do_eval \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --source_lang en_XX \
- --target_lang ro_RO \
- --output_dir /tmp/tst-translation \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
- ```
-
-And here is how you would use the translation finetuning on your own files, after adjusting the
-values for the arguments `--train_file`, `--validation_file` to match your setup:
-
-```bash
-python run_translation.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --source_lang en \
- --target_lang ro \
- --source_prefix "translate English to Romanian: " \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --train_file path_to_jsonlines_file \
- --validation_file path_to_jsonlines_file \
- --output_dir /tmp/tst-translation \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
-```
-
-The task of translation supports only custom JSONLINES files, with each line being a dictionary with a key `"translation"` and its value another dictionary whose keys is the language pair. For example:
-
-```json
-{ "translation": { "en": "Others have dismissed him as a joke.", "ro": "Alții l-au numit o glumă." } }
-{ "translation": { "en": "And some are holding out for an implosion.", "ro": "Iar alții așteaptă implozia." } }
-```
-Here the languages are Romanian (`ro`) and English (`en`).
-
-If you want to use a pre-processed dataset that leads to high BLEU scores, but for the `en-de` language pair, you can use `--dataset_name stas/wmt14-en-de-pre-processed`, as following:
-
-```bash
-python run_translation.py \
- --model_name_or_path google-t5/t5-small \
- --do_train \
- --do_eval \
- --source_lang en \
- --target_lang de \
- --source_prefix "translate English to German: " \
- --dataset_name stas/wmt14-en-de-pre-processed \
- --output_dir /tmp/tst-translation \
- --per_device_train_batch_size=4 \
- --per_device_eval_batch_size=4 \
- --predict_with_generate
- ```
-
-## With Accelerate
-
-Based on the script [`run_translation_no_trainer.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/translation/run_translation_no_trainer.py).
-
-Like `run_translation.py`, this script allows you to fine-tune any of the models supported on a
-translation task, the main difference is that this
-script exposes the bare training loop, to allow you to quickly experiment and add any customization you would like.
-
-It offers less options than the script with `Trainer` (for instance you can easily change the options for the optimizer
-or the dataloaders directly in the script) but still run in a distributed setup, on TPU and supports mixed precision by
-the mean of the [🤗 `Accelerate`](https://github.com/huggingface/accelerate) library. You can use the script normally
-after installing it:
-
-```bash
-pip install git+https://github.com/huggingface/accelerate
-```
-
-then
-
-```bash
-python run_translation_no_trainer.py \
- --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
- --source_lang en \
- --target_lang ro \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --output_dir ~/tmp/tst-translation
-```
-
-You can then use your usual launchers to run in it in a distributed environment, but the easiest way is to run
-
-```bash
-accelerate config
-```
-
-and reply to the questions asked. Then
-
-```bash
-accelerate test
-```
-
-that will check everything is ready for training. Finally, you can launch training with
-
-```bash
-accelerate launch run_translation_no_trainer.py \
- --model_name_or_path Helsinki-NLP/opus-mt-en-ro \
- --source_lang en \
- --target_lang ro \
- --dataset_name wmt/wmt16 \
- --dataset_config_name ro-en \
- --output_dir ~/tmp/tst-translation
-```
-
-This command is the same and will work for:
-
-- a CPU-only setup
-- a setup with one GPU
-- a distributed training with several GPUs (single or multi node)
-- a training on TPUs
-
-Note that this library is in alpha release so your feedback is more than welcome if you encounter any problem using it.
diff --git a/examples/pytorch/translation/requirements.txt b/examples/pytorch/translation/requirements.txt
deleted file mode 100644
index 9c9257430c06..000000000000
--- a/examples/pytorch/translation/requirements.txt
+++ /dev/null
@@ -1,8 +0,0 @@
-accelerate >= 0.12.0
-datasets >= 1.8.0
-sentencepiece != 0.1.92
-protobuf
-sacrebleu >= 1.4.12
-py7zr
-torch >= 1.3
-evaluate
\ No newline at end of file
diff --git a/examples/pytorch/translation/run_translation.py b/examples/pytorch/translation/run_translation.py
deleted file mode 100755
index 2c0574e48af0..000000000000
--- a/examples/pytorch/translation/run_translation.py
+++ /dev/null
@@ -1,693 +0,0 @@
-#!/usr/bin/env python
-# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "sacrebleu >= 1.4.12",
-# "py7zr",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning the library models for sequence to sequence.
-"""
-# You can also adapt this script on your own sequence to sequence task. Pointers for this are left as comments.
-
-import logging
-import os
-import sys
-from dataclasses import dataclass, field
-
-import datasets
-import evaluate
-import numpy as np
-from datasets import load_dataset
-
-import transformers
-from transformers import (
- AutoConfig,
- AutoModelForSeq2SeqLM,
- AutoTokenizer,
- DataCollatorForSeq2Seq,
- HfArgumentParser,
- M2M100Tokenizer,
- MBart50Tokenizer,
- MBart50TokenizerFast,
- MBartTokenizer,
- MBartTokenizerFast,
- Seq2SeqTrainer,
- Seq2SeqTrainingArguments,
- default_data_collator,
- set_seed,
-)
-from transformers.tokenization_utils_sentencepiece import SentencePieceBackend
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/translation/requirements.txt")
-
-logger = logging.getLogger(__name__)
-
-# A list of all multilingual tokenizer which require src_lang and tgt_lang attributes.
-MULTILINGUAL_TOKENIZERS = [MBartTokenizer, MBartTokenizerFast, MBart50Tokenizer, MBart50TokenizerFast, M2M100Tokenizer]
-
-
-@dataclass
-class ModelArguments:
- """
- Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
- """
-
- model_name_or_path: str = field(
- metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
- )
- config_name: str | None = field(
- default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
- )
- tokenizer_name: str | None = field(
- default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
- )
- cache_dir: str | None = field(
- default=None,
- metadata={"help": "Where to store the pretrained models downloaded from huggingface.co"},
- )
- use_fast_tokenizer: bool = field(
- default=True,
- metadata={"help": "Whether to use one of the fast tokenizer (backed by the tokenizers library) or not."},
- )
- model_revision: str = field(
- default="main",
- metadata={"help": "The specific model version to use (can be a branch name, tag name or commit id)."},
- )
- token: str = field(
- default=None,
- metadata={
- "help": (
- "The token to use as HTTP bearer authorization for remote files. If not specified, will use the token "
- "generated when running `hf auth login` (stored in `~/.huggingface`)."
- )
- },
- )
- trust_remote_code: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- )
- },
- )
-
-
-@dataclass
-class DataTrainingArguments:
- """
- Arguments pertaining to what data we are going to input our model for training and eval.
- """
-
- source_lang: str = field(default=None, metadata={"help": "Source language id for translation."})
- target_lang: str = field(default=None, metadata={"help": "Target language id for translation."})
-
- dataset_name: str | None = field(
- default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
- )
- dataset_config_name: str | None = field(
- default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
- )
- train_file: str | None = field(default=None, metadata={"help": "The input training data file (a jsonlines)."})
- validation_file: str | None = field(
- default=None,
- metadata={
- "help": "An optional input evaluation data file to evaluate the metrics (sacrebleu) on a jsonlines file."
- },
- )
- test_file: str | None = field(
- default=None,
- metadata={"help": "An optional input test data file to evaluate the metrics (sacrebleu) on a jsonlines file."},
- )
- overwrite_cache: bool = field(
- default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
- )
- preprocessing_num_workers: int | None = field(
- default=None,
- metadata={"help": "The number of processes to use for the preprocessing."},
- )
- max_source_length: int | None = field(
- default=1024,
- metadata={
- "help": (
- "The maximum total input sequence length after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- max_target_length: int | None = field(
- default=128,
- metadata={
- "help": (
- "The maximum total sequence length for target text after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded."
- )
- },
- )
- val_max_target_length: int | None = field(
- default=None,
- metadata={
- "help": (
- "The maximum total sequence length for validation target text after tokenization. Sequences longer "
- "than this will be truncated, sequences shorter will be padded. Will default to `max_target_length`. "
- "This argument is also used to override the ``max_length`` param of ``model.generate``, which is used "
- "during ``evaluate`` and ``predict``."
- )
- },
- )
- pad_to_max_length: bool = field(
- default=False,
- metadata={
- "help": (
- "Whether to pad all samples to model maximum sentence length. "
- "If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
- "efficient on GPU but very bad for TPU."
- )
- },
- )
- max_train_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of training examples to this "
- "value if set."
- )
- },
- )
- max_eval_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of evaluation examples to this "
- "value if set."
- )
- },
- )
- max_predict_samples: int | None = field(
- default=None,
- metadata={
- "help": (
- "For debugging purposes or quicker training, truncate the number of prediction examples to this "
- "value if set."
- )
- },
- )
- num_beams: int | None = field(
- default=1,
- metadata={
- "help": (
- "Number of beams to use for evaluation. This argument will be passed to ``model.generate``, "
- "which is used during ``evaluate`` and ``predict``."
- )
- },
- )
- ignore_pad_token_for_loss: bool = field(
- default=True,
- metadata={
- "help": "Whether to ignore the tokens corresponding to padded labels in the loss computation or not."
- },
- )
- source_prefix: str | None = field(
- default=None, metadata={"help": "A prefix to add before every source text (useful for T5 models)."}
- )
- forced_bos_token: str | None = field(
- default=None,
- metadata={
- "help": (
- "The token to force as the first generated token after the :obj:`decoder_start_token_id`.Useful for"
- " multilingual models like :doc:`mBART <../model_doc/mbart>` where the first generated token needs to"
- " be the target language token.(Usually it is the target language token)"
- )
- },
- )
-
- def __post_init__(self):
- if self.dataset_name is None and self.train_file is None and self.validation_file is None:
- raise ValueError("Need either a dataset name or a training/validation file.")
- elif self.source_lang is None or self.target_lang is None:
- raise ValueError("Need to specify the source language and the target language.")
-
- # accepting both json and jsonl file extensions, as
- # many jsonlines files actually have a .json extension
- valid_extensions = ["json", "jsonl"]
-
- if self.train_file is not None:
- extension = self.train_file.split(".")[-1]
- assert extension in valid_extensions, "`train_file` should be a jsonlines file."
- if self.validation_file is not None:
- extension = self.validation_file.split(".")[-1]
- assert extension in valid_extensions, "`validation_file` should be a jsonlines file."
- if self.val_max_target_length is None:
- self.val_max_target_length = self.max_target_length
-
-
-def main():
- # See all possible arguments in src/transformers/training_args.py
- # or by passing the --help flag to this script.
- # We now keep distinct sets of args, for a cleaner separation of concerns.
-
- parser = HfArgumentParser((ModelArguments, DataTrainingArguments, Seq2SeqTrainingArguments))
- if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
- # If we pass only one argument to the script and it's the path to a json file,
- # let's parse it to get our arguments.
- model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
- else:
- model_args, data_args, training_args = parser.parse_args_into_dataclasses()
-
- # Setup logging
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- handlers=[logging.StreamHandler(sys.stdout)],
- )
-
- if training_args.should_log:
- # The default of training_args.log_level is passive, so we set log level at info here to have that default.
- transformers.utils.logging.set_verbosity_info()
-
- log_level = training_args.get_process_log_level()
- logger.setLevel(log_level)
- datasets.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.set_verbosity(log_level)
- transformers.utils.logging.enable_default_handler()
- transformers.utils.logging.enable_explicit_format()
-
- # Log on each process the small summary:
- logger.warning(
- f"Process rank: {training_args.local_process_index}, device: {training_args.device}, n_gpu: {training_args.n_gpu}, "
- + f"distributed training: {training_args.parallel_mode.value == 'distributed'}, 16-bits training: {training_args.fp16}"
- )
- logger.info(f"Training/evaluation parameters {training_args}")
-
- if data_args.source_prefix is None and model_args.model_name_or_path in [
- "google-t5/t5-small",
- "google-t5/t5-base",
- "google-t5/t5-large",
- "google-t5/t5-3b",
- "google-t5/t5-11b",
- ]:
- logger.warning(
- "You're running a t5 model but didn't provide a source prefix, which is expected, e.g. with "
- "`--source_prefix 'translate English to German: ' `"
- )
-
- # Set seed before initializing model.
- set_seed(training_args.seed)
-
- # Get the datasets: you can either provide your own JSON training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For translation, only JSON files are supported, with one field named "translation" containing two keys for the
- # source and target languages (unless you adapt what follows).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if data_args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- data_args.dataset_name,
- data_args.dataset_config_name,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- else:
- data_files = {}
- if data_args.train_file is not None:
- data_files["train"] = data_args.train_file
- extension = data_args.train_file.split(".")[-1]
- if data_args.validation_file is not None:
- data_files["validation"] = data_args.validation_file
- extension = data_args.validation_file.split(".")[-1]
- if data_args.test_file is not None:
- data_files["test"] = data_args.test_file
- extension = data_args.test_file.split(".")[-1]
- if extension == "jsonl":
- builder_name = "json" # the "json" builder reads both .json and .jsonl files
- else:
- builder_name = extension # e.g. "parquet"
- raw_datasets = load_dataset(
- builder_name,
- data_files=data_files,
- cache_dir=model_args.cache_dir,
- token=model_args.token,
- )
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading.
-
- # Load pretrained model and tokenizer
- #
- # Distributed training:
- # The .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- config = AutoConfig.from_pretrained(
- model_args.config_name if model_args.config_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- tokenizer = AutoTokenizer.from_pretrained(
- model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
- cache_dir=model_args.cache_dir,
- use_fast=model_args.use_fast_tokenizer,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
- model = AutoModelForSeq2SeqLM.from_pretrained(
- model_args.model_name_or_path,
- from_tf=bool(".ckpt" in model_args.model_name_or_path),
- config=config,
- cache_dir=model_args.cache_dir,
- revision=model_args.model_revision,
- token=model_args.token,
- trust_remote_code=model_args.trust_remote_code,
- )
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Set decoder_start_token_id
- if model.config.decoder_start_token_id is None and isinstance(
- tokenizer, (MBartTokenizer, MBartTokenizerFast, SentencePieceBackend)
- ):
- if isinstance(tokenizer, MBartTokenizer):
- model.config.decoder_start_token_id = tokenizer.lang_code_to_id[data_args.target_lang]
- else:
- model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(data_args.target_lang)
-
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- prefix = data_args.source_prefix if data_args.source_prefix is not None else ""
-
- # Preprocessing the datasets.
- # We need to tokenize inputs and targets.
- if training_args.do_train:
- column_names = raw_datasets["train"].column_names
- elif training_args.do_eval:
- column_names = raw_datasets["validation"].column_names
- elif training_args.do_predict:
- column_names = raw_datasets["test"].column_names
- else:
- logger.info("There is nothing to do. Please pass `do_train`, `do_eval` and/or `do_predict`.")
- return
-
- # For translation we set the codes of our source and target languages (only useful for mBART, the others will
- # ignore those attributes).
- if isinstance(tokenizer, tuple(MULTILINGUAL_TOKENIZERS)):
- assert data_args.target_lang is not None and data_args.source_lang is not None, (
- f"{tokenizer.__class__.__name__} is a multilingual tokenizer which requires --source_lang and "
- "--target_lang arguments."
- )
-
- tokenizer.src_lang = data_args.source_lang
- tokenizer.tgt_lang = data_args.target_lang
-
- # For multilingual translation models like mBART-50 and M2M100 we need to force the target language token
- # as the first generated token. We ask the user to explicitly provide this as --forced_bos_token argument.
- forced_bos_token_id = (
- tokenizer.lang_code_to_id[data_args.forced_bos_token] if data_args.forced_bos_token is not None else None
- )
- model.config.forced_bos_token_id = forced_bos_token_id
-
- # Get the language codes for input/target.
- source_lang = data_args.source_lang.split("_")[0]
- target_lang = data_args.target_lang.split("_")[0]
-
- # Check the whether the source target length fits in the model, if it has absolute positional embeddings
- if (
- hasattr(model.config, "max_position_embeddings")
- and not hasattr(model.config, "relative_attention_max_distance")
- and model.config.max_position_embeddings < data_args.max_source_length
- ):
- raise ValueError(
- f"`--max_source_length` is set to {data_args.max_source_length}, but the model only has"
- f" {model.config.max_position_embeddings} position encodings. Consider either reducing"
- f" `--max_source_length` to {model.config.max_position_embeddings} or using a model with larger position "
- "embeddings"
- )
-
- # Temporarily set max_target_length for training.
- max_target_length = data_args.max_target_length
- padding = "max_length" if data_args.pad_to_max_length else False
-
- if training_args.label_smoothing_factor > 0 and not hasattr(model, "prepare_decoder_input_ids_from_labels"):
- logger.warning(
- "label_smoothing is enabled but the `prepare_decoder_input_ids_from_labels` method is not defined for "
- f"`{model.__class__.__name__}`. This will lead to loss being calculated twice and will take up more memory"
- )
-
- def preprocess_function(examples):
- inputs = [ex[source_lang] for ex in examples["translation"]]
- targets = [ex[target_lang] for ex in examples["translation"]]
- inputs = [prefix + inp for inp in inputs]
- model_inputs = tokenizer(inputs, max_length=data_args.max_source_length, padding=padding, truncation=True)
-
- # Tokenize targets with the `text_target` keyword argument
- labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and data_args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- model_inputs["labels"] = labels["input_ids"]
- return model_inputs
-
- if training_args.do_train:
- if "train" not in raw_datasets:
- raise ValueError("--do_train requires a train dataset")
- train_dataset = raw_datasets["train"]
- if data_args.max_train_samples is not None:
- max_train_samples = min(len(train_dataset), data_args.max_train_samples)
- train_dataset = train_dataset.select(range(max_train_samples))
- with training_args.main_process_first(desc="train dataset map pre-processing"):
- train_dataset = train_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on train dataset",
- )
-
- if training_args.do_eval:
- max_target_length = data_args.val_max_target_length
- if "validation" not in raw_datasets:
- raise ValueError("--do_eval requires a validation dataset")
- eval_dataset = raw_datasets["validation"]
- if data_args.max_eval_samples is not None:
- max_eval_samples = min(len(eval_dataset), data_args.max_eval_samples)
- eval_dataset = eval_dataset.select(range(max_eval_samples))
- with training_args.main_process_first(desc="validation dataset map pre-processing"):
- eval_dataset = eval_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on validation dataset",
- )
-
- if training_args.do_predict:
- max_target_length = data_args.val_max_target_length
- if "test" not in raw_datasets:
- raise ValueError("--do_predict requires a test dataset")
- predict_dataset = raw_datasets["test"]
- if data_args.max_predict_samples is not None:
- max_predict_samples = min(len(predict_dataset), data_args.max_predict_samples)
- predict_dataset = predict_dataset.select(range(max_predict_samples))
- with training_args.main_process_first(desc="prediction dataset map pre-processing"):
- predict_dataset = predict_dataset.map(
- preprocess_function,
- batched=True,
- num_proc=data_args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not data_args.overwrite_cache,
- desc="Running tokenizer on prediction dataset",
- )
-
- # Data collator
- label_pad_token_id = -100 if data_args.ignore_pad_token_for_loss else tokenizer.pad_token_id
- if data_args.pad_to_max_length:
- data_collator = default_data_collator
- else:
- data_collator = DataCollatorForSeq2Seq(
- tokenizer,
- model=model,
- label_pad_token_id=label_pad_token_id,
- pad_to_multiple_of=8 if training_args.fp16 else None,
- )
-
- # Metric
- metric = evaluate.load("sacrebleu", cache_dir=model_args.cache_dir)
-
- def postprocess_text(preds, labels):
- preds = [pred.strip() for pred in preds]
- labels = [[label.strip()] for label in labels]
-
- return preds, labels
-
- def compute_metrics(eval_preds):
- preds, labels = eval_preds
- if isinstance(preds, tuple):
- preds = preds[0]
- # Replace -100s used for padding as we can't decode them
- preds = np.where(preds != -100, preds, tokenizer.pad_token_id)
- decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
- labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
- decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
-
- # Some simple post-processing
- decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
-
- result = metric.compute(predictions=decoded_preds, references=decoded_labels)
- result = {"bleu": result["score"]}
-
- prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
- result["gen_len"] = np.mean(prediction_lens)
- result = {k: round(v, 4) for k, v in result.items()}
- return result
-
- # Initialize our Trainer
- trainer = Seq2SeqTrainer(
- model=model,
- args=training_args,
- train_dataset=train_dataset if training_args.do_train else None,
- eval_dataset=eval_dataset if training_args.do_eval else None,
- processing_class=tokenizer,
- data_collator=data_collator,
- compute_metrics=compute_metrics if training_args.predict_with_generate else None,
- )
-
- # Training
- if training_args.do_train:
- checkpoint = None
- if training_args.resume_from_checkpoint is not None:
- checkpoint = training_args.resume_from_checkpoint
- train_result = trainer.train(resume_from_checkpoint=checkpoint)
- trainer.save_model() # Saves the tokenizer too for easy upload
-
- metrics = train_result.metrics
- max_train_samples = (
- data_args.max_train_samples if data_args.max_train_samples is not None else len(train_dataset)
- )
- metrics["train_samples"] = min(max_train_samples, len(train_dataset))
-
- trainer.log_metrics("train", metrics)
- trainer.save_metrics("train", metrics)
- trainer.save_state()
-
- # Evaluation
- results = {}
- max_length = (
- training_args.generation_max_length
- if training_args.generation_max_length is not None
- else data_args.val_max_target_length
- )
- num_beams = data_args.num_beams if data_args.num_beams is not None else training_args.generation_num_beams
- if training_args.do_eval:
- logger.info("*** Evaluate ***")
-
- metrics = trainer.evaluate(max_length=max_length, num_beams=num_beams, metric_key_prefix="eval")
- max_eval_samples = data_args.max_eval_samples if data_args.max_eval_samples is not None else len(eval_dataset)
- metrics["eval_samples"] = min(max_eval_samples, len(eval_dataset))
-
- trainer.log_metrics("eval", metrics)
- trainer.save_metrics("eval", metrics)
-
- if training_args.do_predict:
- logger.info("*** Predict ***")
-
- predict_results = trainer.predict(
- predict_dataset, metric_key_prefix="predict", max_length=max_length, num_beams=num_beams
- )
- metrics = predict_results.metrics
- max_predict_samples = (
- data_args.max_predict_samples if data_args.max_predict_samples is not None else len(predict_dataset)
- )
- metrics["predict_samples"] = min(max_predict_samples, len(predict_dataset))
-
- trainer.log_metrics("predict", metrics)
- trainer.save_metrics("predict", metrics)
-
- if trainer.is_world_process_zero():
- if training_args.predict_with_generate:
- predictions = predict_results.predictions
- predictions = np.where(predictions != -100, predictions, tokenizer.pad_token_id)
- predictions = tokenizer.batch_decode(
- predictions, skip_special_tokens=True, clean_up_tokenization_spaces=True
- )
- predictions = [pred.strip() for pred in predictions]
- output_prediction_file = os.path.join(training_args.output_dir, "generated_predictions.txt")
- with open(output_prediction_file, "w", encoding="utf-8") as writer:
- writer.write("\n".join(predictions))
-
- kwargs = {"finetuned_from": model_args.model_name_or_path, "tasks": "translation"}
- if data_args.dataset_name is not None:
- kwargs["dataset_tags"] = data_args.dataset_name
- if data_args.dataset_config_name is not None:
- kwargs["dataset_args"] = data_args.dataset_config_name
- kwargs["dataset"] = f"{data_args.dataset_name} {data_args.dataset_config_name}"
- else:
- kwargs["dataset"] = data_args.dataset_name
-
- languages = [l for l in [data_args.source_lang, data_args.target_lang] if l is not None]
- if len(languages) > 0:
- kwargs["language"] = languages
-
- if training_args.push_to_hub:
- trainer.push_to_hub(**kwargs)
- else:
- trainer.create_model_card(**kwargs)
-
- trainer.end()
-
- return results
-
-
-def _mp_fn(index):
- # For xla_spawn (TPUs)
- main()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/translation/run_translation_no_trainer.py b/examples/pytorch/translation/run_translation_no_trainer.py
deleted file mode 100644
index 701c5ccb2d2e..000000000000
--- a/examples/pytorch/translation/run_translation_no_trainer.py
+++ /dev/null
@@ -1,800 +0,0 @@
-#!/usr/bin/env python
-# Copyright The HuggingFace Team and The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-# /// script
-# dependencies = [
-# "transformers @ git+https://github.com/huggingface/transformers.git",
-# "accelerate >= 0.12.0",
-# "datasets >= 1.8.0",
-# "sentencepiece != 0.1.92",
-# "protobuf",
-# "sacrebleu >= 1.4.12",
-# "py7zr",
-# "torch >= 1.3",
-# "evaluate",
-# ]
-# ///
-
-"""
-Fine-tuning a 🤗 Transformers model on text translation.
-"""
-# You can also adapt this script on your own text translation task. Pointers for this are left as comments.
-
-import argparse
-import json
-import logging
-import math
-import os
-import random
-from pathlib import Path
-
-import datasets
-import evaluate
-import numpy as np
-import torch
-from accelerate import Accelerator
-from accelerate.logging import get_logger
-from accelerate.utils import set_seed
-from datasets import load_dataset
-from huggingface_hub import HfApi
-from torch.utils.data import DataLoader
-from tqdm.auto import tqdm
-
-import transformers
-from transformers import (
- CONFIG_MAPPING,
- MODEL_MAPPING,
- AutoConfig,
- AutoModelForSeq2SeqLM,
- AutoTokenizer,
- DataCollatorForSeq2Seq,
- MBartTokenizer,
- MBartTokenizerFast,
- SchedulerType,
- default_data_collator,
- get_scheduler,
-)
-from transformers.utils import check_min_version
-from transformers.utils.versions import require_version
-
-
-# Will error if the minimal version of Transformers is not installed. Remove at your own risks.
-check_min_version("4.57.0.dev0")
-
-logger = get_logger(__name__)
-require_version("datasets>=1.8.0", "To fix: pip install -r examples/pytorch/translation/requirements.txt")
-
-# You should update this to your particular problem to have better documentation of `model_type`
-MODEL_CONFIG_CLASSES = list(MODEL_MAPPING.keys())
-MODEL_TYPES = tuple(conf.model_type for conf in MODEL_CONFIG_CLASSES)
-
-
-# Parsing input arguments
-def parse_args():
- parser = argparse.ArgumentParser(description="Finetune a transformers model on a text classification task")
- parser.add_argument(
- "--dataset_name",
- type=str,
- default=None,
- help="The name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--predict_with_generate",
- type=bool,
- default=True,
- help="",
- )
- parser.add_argument(
- "--dataset_config_name",
- type=str,
- default=None,
- help="The configuration name of the dataset to use (via the datasets library).",
- )
- parser.add_argument(
- "--train_file", type=str, default=None, help="A csv or a json file containing the training data."
- )
-
- parser.add_argument(
- "--num_beams",
- type=int,
- default=None,
- help=(
- "Number of beams to use for evaluation. This argument will be "
- "passed to ``model.generate``, which is used during ``evaluate`` and ``predict``."
- ),
- )
-
- parser.add_argument(
- "--max_source_length",
- type=int,
- default=1024,
- help=(
- "The maximum total input sequence length after "
- "tokenization.Sequences longer than this will be truncated, sequences shorter will be padded."
- ),
- )
- parser.add_argument(
- "--max_target_length",
- type=int,
- default=128,
- help=(
- "The maximum total sequence length for target text after "
- "tokenization. Sequences longer than this will be truncated, sequences shorter will be padded "
- "during ``evaluate`` and ``predict``."
- ),
- )
- parser.add_argument(
- "--val_max_target_length",
- type=int,
- default=None,
- help=(
- "The maximum total sequence length for validation "
- "target text after tokenization.Sequences longer than this will be truncated, sequences shorter will be "
- "padded. Will default to `max_target_length`.This argument is also used to override the ``max_length`` "
- "param of ``model.generate``, which is used during ``evaluate`` and ``predict``."
- ),
- )
- parser.add_argument(
- "--pad_to_max_length",
- type=bool,
- default=False,
- help=(
- "Whether to pad all samples to model maximum sentence "
- "length. If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
- "efficient on GPU but very bad for TPU."
- ),
- )
- parser.add_argument(
- "--validation_file", type=str, default=None, help="A csv or a json file containing the validation data."
- )
- parser.add_argument(
- "--ignore_pad_token_for_loss",
- type=bool,
- default=True,
- help="Whether to ignore the tokens corresponding to padded labels in the loss computation or not.",
- )
- parser.add_argument("--source_lang", type=str, default=None, help="Source language id for translation.")
- parser.add_argument("--target_lang", type=str, default=None, help="Target language id for translation.")
- parser.add_argument(
- "--source_prefix",
- type=str,
- default=None,
- help="A prefix to add before every source text (useful for T5 models).",
- )
- parser.add_argument(
- "--preprocessing_num_workers",
- type=int,
- default=None,
- help="The number of processes to use for the preprocessing.",
- )
- parser.add_argument(
- "--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
- )
- parser.add_argument(
- "--max_length",
- type=int,
- default=128,
- help=(
- "The maximum total input sequence length after tokenization. Sequences longer than this will be truncated,"
- " sequences shorter will be padded if `--pad_to_max_length` is passed."
- ),
- )
- parser.add_argument(
- "--model_name_or_path",
- type=str,
- help="Path to pretrained model or model identifier from huggingface.co/models.",
- required=False,
- )
- parser.add_argument(
- "--config_name",
- type=str,
- default=None,
- help="Pretrained config name or path if not the same as model_name",
- )
- parser.add_argument(
- "--tokenizer_name",
- type=str,
- default=None,
- help="Pretrained tokenizer name or path if not the same as model_name",
- )
- parser.add_argument(
- "--use_slow_tokenizer",
- action="store_true",
- help="If passed, will use a slow tokenizer (not backed by the Hugging Face Tokenizers library).",
- )
- parser.add_argument(
- "--per_device_train_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the training dataloader.",
- )
- parser.add_argument(
- "--per_device_eval_batch_size",
- type=int,
- default=8,
- help="Batch size (per device) for the evaluation dataloader.",
- )
- parser.add_argument(
- "--learning_rate",
- type=float,
- default=5e-5,
- help="Initial learning rate (after the potential warmup period) to use.",
- )
- parser.add_argument("--weight_decay", type=float, default=0.0, help="Weight decay to use.")
- parser.add_argument("--num_train_epochs", type=int, default=3, help="Total number of training epochs to perform.")
- parser.add_argument(
- "--max_train_steps",
- type=int,
- default=None,
- help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
- )
- parser.add_argument(
- "--gradient_accumulation_steps",
- type=int,
- default=1,
- help="Number of updates steps to accumulate before performing a backward/update pass.",
- )
- parser.add_argument(
- "--lr_scheduler_type",
- type=SchedulerType,
- default="linear",
- help="The scheduler type to use.",
- choices=["linear", "cosine", "cosine_with_restarts", "polynomial", "constant", "constant_with_warmup"],
- )
- parser.add_argument(
- "--num_warmup_steps", type=int, default=0, help="Number of steps for the warmup in the lr scheduler."
- )
- parser.add_argument("--output_dir", type=str, default=None, help="Where to store the final model.")
- parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
- parser.add_argument(
- "--model_type",
- type=str,
- default=None,
- help="Model type to use if training from scratch.",
- choices=MODEL_TYPES,
- )
- parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
- parser.add_argument(
- "--hub_model_id", type=str, help="The name of the repository to keep in sync with the local `output_dir`."
- )
- parser.add_argument("--hub_token", type=str, help="The token to use to push to the Model Hub.")
- parser.add_argument(
- "--trust_remote_code",
- action="store_true",
- help=(
- "Whether to trust the execution of code from datasets/models defined on the Hub."
- " This option should only be set to `True` for repositories you trust and in which you have read the"
- " code, as it will execute code present on the Hub on your local machine."
- ),
- )
- parser.add_argument(
- "--checkpointing_steps",
- type=str,
- default=None,
- help="Whether the various states should be saved at the end of every n steps, or 'epoch' for each epoch.",
- )
- parser.add_argument(
- "--resume_from_checkpoint",
- type=str,
- default=None,
- help="If the training should continue from a checkpoint folder.",
- )
- parser.add_argument(
- "--with_tracking",
- action="store_true",
- help="Whether to enable experiment trackers for logging.",
- )
- parser.add_argument(
- "--report_to",
- type=str,
- default="all",
- help=(
- 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`,'
- ' `"wandb"`, `"comet_ml"` and `"clearml"`. Use `"all"` (default) to report to all integrations. '
- "Only applicable when `--with_tracking` is passed."
- ),
- )
- args = parser.parse_args()
-
- # Sanity checks
-
- if args.dataset_name is None and args.train_file is None and args.validation_file is None:
- raise ValueError("Need either a task name or a training/validation file.")
-
- if args.train_file is not None:
- extension = args.train_file.split(".")[-1]
- assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
- if args.validation_file is not None:
- extension = args.validation_file.split(".")[-1]
- assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
-
- if args.push_to_hub:
- assert args.output_dir is not None, "Need an `output_dir` to create a repo when `--push_to_hub` is passed."
-
- return args
-
-
-def main():
- # Parse the arguments
- args = parse_args()
-
- # Initialize the accelerator. We will let the accelerator handle device placement for us in this example.
- # If we're using tracking, we also need to initialize it here and it will by default pick up all supported trackers
- # in the environment
- accelerator = (
- Accelerator(log_with=args.report_to, project_dir=args.output_dir) if args.with_tracking else Accelerator()
- )
-
- # Make one log on every process with the configuration for debugging.
- logging.basicConfig(
- format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
- datefmt="%m/%d/%Y %H:%M:%S",
- level=logging.INFO,
- )
- logger.info(accelerator.state, main_process_only=False)
- if accelerator.is_local_main_process:
- datasets.utils.logging.set_verbosity_warning()
- transformers.utils.logging.set_verbosity_info()
- else:
- datasets.utils.logging.set_verbosity_error()
- transformers.utils.logging.set_verbosity_error()
-
- # If passed along, set the training seed now.
- if args.seed is not None:
- set_seed(args.seed)
-
- # Handle the repository creation
- if accelerator.is_main_process:
- if args.push_to_hub:
- # Retrieve of infer repo_name
- repo_name = args.hub_model_id
- if repo_name is None:
- repo_name = Path(args.output_dir).absolute().name
- # Create repo and retrieve repo_id
- api = HfApi()
- repo_id = api.create_repo(repo_name, exist_ok=True, token=args.hub_token).repo_id
-
- with open(os.path.join(args.output_dir, ".gitignore"), "w+", encoding="utf-8") as gitignore:
- if "step_*" not in gitignore:
- gitignore.write("step_*\n")
- if "epoch_*" not in gitignore:
- gitignore.write("epoch_*\n")
- elif args.output_dir is not None:
- os.makedirs(args.output_dir, exist_ok=True)
- accelerator.wait_for_everyone()
-
- # Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
- # or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
- # (the dataset will be downloaded automatically from the datasets Hub).
- #
- # For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
- # 'text' is found. You can easily tweak this behavior (see below).
- #
- # In distributed training, the load_dataset function guarantee that only one local process can concurrently
- # download the dataset.
- if args.dataset_name is not None:
- # Downloading and loading a dataset from the hub.
- raw_datasets = load_dataset(
- args.dataset_name, args.dataset_config_name, trust_remote_code=args.trust_remote_code
- )
- else:
- data_files = {}
- if args.train_file is not None:
- data_files["train"] = args.train_file
- extension = args.train_file.split(".")[-1]
- if args.validation_file is not None:
- data_files["validation"] = args.validation_file
- extension = args.validation_file.split(".")[-1]
- raw_datasets = load_dataset(extension, data_files=data_files)
- # See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
- # https://huggingface.co/docs/datasets/loading_datasets.
-
- # Load pretrained model and tokenizer
- #
- # In distributed training, the .from_pretrained methods guarantee that only one local process can concurrently
- # download model & vocab.
- if args.config_name:
- config = AutoConfig.from_pretrained(args.config_name, trust_remote_code=args.trust_remote_code)
- elif args.model_name_or_path:
- config = AutoConfig.from_pretrained(args.model_name_or_path, trust_remote_code=args.trust_remote_code)
- else:
- config = CONFIG_MAPPING[args.model_type]()
- logger.warning("You are instantiating a new config instance from scratch.")
-
- if args.tokenizer_name:
- tokenizer = AutoTokenizer.from_pretrained(
- args.tokenizer_name, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- elif args.model_name_or_path:
- tokenizer = AutoTokenizer.from_pretrained(
- args.model_name_or_path, use_fast=not args.use_slow_tokenizer, trust_remote_code=args.trust_remote_code
- )
- else:
- raise ValueError(
- "You are instantiating a new tokenizer from scratch. This is not supported by this script. "
- "You can do it from another script, save it, and load it from here, using --tokenizer_name."
- )
-
- if args.model_name_or_path:
- model = AutoModelForSeq2SeqLM.from_pretrained(
- args.model_name_or_path,
- from_tf=bool(".ckpt" in args.model_name_or_path),
- config=config,
- trust_remote_code=args.trust_remote_code,
- )
- else:
- logger.info("Training new model from scratch")
- model = AutoModelForSeq2SeqLM.from_config(config, trust_remote_code=args.trust_remote_code)
-
- # We resize the embeddings only when necessary to avoid index errors. If you are creating a model from scratch
- # on a small vocab and want a smaller embedding size, remove this test.
- embedding_size = model.get_input_embeddings().weight.shape[0]
- if len(tokenizer) > embedding_size:
- model.resize_token_embeddings(len(tokenizer))
-
- # Set decoder_start_token_id
- if model.config.decoder_start_token_id is None and isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
- assert args.target_lang is not None and args.source_lang is not None, (
- "mBart requires --target_lang and --source_lang"
- )
- if isinstance(tokenizer, MBartTokenizer):
- model.config.decoder_start_token_id = tokenizer.lang_code_to_id[args.target_lang]
- else:
- model.config.decoder_start_token_id = tokenizer.convert_tokens_to_ids(args.target_lang)
-
- if model.config.decoder_start_token_id is None:
- raise ValueError("Make sure that `config.decoder_start_token_id` is correctly defined")
-
- prefix = args.source_prefix if args.source_prefix is not None else ""
-
- # Preprocessing the datasets.
- # First we tokenize all the texts.
- column_names = raw_datasets["train"].column_names
-
- # For translation we set the codes of our source and target languages (only useful for mBART, the others will
- # ignore those attributes).
- if isinstance(tokenizer, (MBartTokenizer, MBartTokenizerFast)):
- if args.source_lang is not None:
- tokenizer.src_lang = args.source_lang
- if args.target_lang is not None:
- tokenizer.tgt_lang = args.target_lang
-
- # Get the language codes for input/target.
- source_lang = args.source_lang.split("_")[0]
- target_lang = args.target_lang.split("_")[0]
-
- padding = "max_length" if args.pad_to_max_length else False
-
- # Temporarily set max_target_length for training.
- max_target_length = args.max_target_length
- padding = "max_length" if args.pad_to_max_length else False
-
- def preprocess_function(examples):
- inputs = [ex[source_lang] for ex in examples["translation"]]
- targets = [ex[target_lang] for ex in examples["translation"]]
- inputs = [prefix + inp for inp in inputs]
- model_inputs = tokenizer(inputs, max_length=args.max_source_length, padding=padding, truncation=True)
-
- # Tokenize targets with the `text_target` keyword argument
- labels = tokenizer(text_target=targets, max_length=max_target_length, padding=padding, truncation=True)
-
- # If we are padding here, replace all tokenizer.pad_token_id in the labels by -100 when we want to ignore
- # padding in the loss.
- if padding == "max_length" and args.ignore_pad_token_for_loss:
- labels["input_ids"] = [
- [(l if l != tokenizer.pad_token_id else -100) for l in label] for label in labels["input_ids"]
- ]
-
- model_inputs["labels"] = labels["input_ids"]
- return model_inputs
-
- with accelerator.main_process_first():
- processed_datasets = raw_datasets.map(
- preprocess_function,
- batched=True,
- num_proc=args.preprocessing_num_workers,
- remove_columns=column_names,
- load_from_cache_file=not args.overwrite_cache,
- desc="Running tokenizer on dataset",
- )
-
- train_dataset = processed_datasets["train"]
- eval_dataset = processed_datasets["validation"]
-
- # Log a few random samples from the training set:
- for index in random.sample(range(len(train_dataset)), 3):
- logger.info(f"Sample {index} of the training set: {train_dataset[index]}.")
-
- # DataLoaders creation:
- label_pad_token_id = -100 if args.ignore_pad_token_for_loss else tokenizer.pad_token_id
- if args.pad_to_max_length:
- # If padding was already done ot max length, we use the default data collator that will just convert everything
- # to tensors.
- data_collator = default_data_collator
- else:
- # Otherwise, `DataCollatorWithPadding` will apply dynamic padding for us (by padding to the maximum length of
- # the samples passed). When using mixed precision, we add `pad_to_multiple_of=8` to pad all tensors to multiple
- # of 8s, which will enable the use of Tensor Cores on NVIDIA hardware with compute capability >= 7.5 (Volta).
- # For fp8, we pad to multiple of 16.
- if accelerator.mixed_precision == "fp8":
- pad_to_multiple_of = 16
- elif accelerator.mixed_precision != "no":
- pad_to_multiple_of = 8
- else:
- pad_to_multiple_of = None
- data_collator = DataCollatorForSeq2Seq(
- tokenizer,
- model=model,
- label_pad_token_id=label_pad_token_id,
- pad_to_multiple_of=pad_to_multiple_of,
- )
-
- train_dataloader = DataLoader(
- train_dataset, shuffle=True, collate_fn=data_collator, batch_size=args.per_device_train_batch_size
- )
- eval_dataloader = DataLoader(eval_dataset, collate_fn=data_collator, batch_size=args.per_device_eval_batch_size)
-
- # Optimizer
- # Split weights in two groups, one with weight decay and the other not.
- no_decay = ["bias", "LayerNorm.weight", "layer_norm.weight"]
- optimizer_grouped_parameters = [
- {
- "params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
- "weight_decay": args.weight_decay,
- },
- {
- "params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
- "weight_decay": 0.0,
- },
- ]
- optimizer = torch.optim.AdamW(optimizer_grouped_parameters, lr=args.learning_rate)
-
- # Scheduler and math around the number of training steps.
- overrode_max_train_steps = False
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if args.max_train_steps is None:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- overrode_max_train_steps = True
-
- lr_scheduler = get_scheduler(
- name=args.lr_scheduler_type,
- optimizer=optimizer,
- num_warmup_steps=args.num_warmup_steps,
- num_training_steps=args.max_train_steps,
- )
-
- # Prepare everything with our `accelerator`.
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler = accelerator.prepare(
- model, optimizer, train_dataloader, eval_dataloader, lr_scheduler
- )
-
- # We need to recalculate our total training steps as the size of the training dataloader may have changed.
- num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
- if overrode_max_train_steps:
- args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
- # Afterwards we recalculate our number of training epochs
- args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
- # Figure out how many steps we should save the Accelerator states
- checkpointing_steps = args.checkpointing_steps
- if checkpointing_steps is not None and checkpointing_steps.isdigit():
- checkpointing_steps = int(checkpointing_steps)
-
- # We need to initialize the trackers we use, and also store our configuration.
- # We initialize the trackers only on main process because `accelerator.log`
- # only logs on main process and we don't want empty logs/runs on other processes.
- if args.with_tracking:
- if accelerator.is_main_process:
- experiment_config = vars(args)
- # TensorBoard cannot log Enums, need the raw value
- experiment_config["lr_scheduler_type"] = experiment_config["lr_scheduler_type"].value
- accelerator.init_trackers("translation_no_trainer", experiment_config)
-
- metric = evaluate.load("sacrebleu")
-
- def postprocess_text(preds, labels):
- preds = [pred.strip() for pred in preds]
- labels = [[label.strip()] for label in labels]
-
- return preds, labels
-
- # Train!
- total_batch_size = args.per_device_train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
-
- logger.info("***** Running training *****")
- logger.info(f" Num examples = {len(train_dataset)}")
- logger.info(f" Num Epochs = {args.num_train_epochs}")
- logger.info(f" Instantaneous batch size per device = {args.per_device_train_batch_size}")
- logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
- logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
- logger.info(f" Total optimization steps = {args.max_train_steps}")
- # Only show the progress bar once on each machine.
- progress_bar = tqdm(range(args.max_train_steps), disable=not accelerator.is_local_main_process)
- completed_steps = 0
- starting_epoch = 0
-
- # Potentially load in the weights and states from a previous save
- if args.resume_from_checkpoint:
- if args.resume_from_checkpoint is not None or args.resume_from_checkpoint != "":
- checkpoint_path = args.resume_from_checkpoint
- path = os.path.basename(args.resume_from_checkpoint)
- else:
- # Get the most recent checkpoint
- dirs = [f.name for f in os.scandir(os.getcwd()) if f.is_dir()]
- dirs.sort(key=os.path.getctime)
- path = dirs[-1] # Sorts folders by date modified, most recent checkpoint is the last
- checkpoint_path = path
- path = os.path.basename(checkpoint_path)
-
- accelerator.print(f"Resumed from checkpoint: {checkpoint_path}")
- accelerator.load_state(checkpoint_path)
- # Extract `epoch_{i}` or `step_{i}`
- training_difference = os.path.splitext(path)[0]
-
- if "epoch" in training_difference:
- starting_epoch = int(training_difference.replace("epoch_", "")) + 1
- resume_step = None
- completed_steps = starting_epoch * num_update_steps_per_epoch
- else:
- # need to multiply `gradient_accumulation_steps` to reflect real steps
- resume_step = int(training_difference.replace("step_", "")) * args.gradient_accumulation_steps
- starting_epoch = resume_step // len(train_dataloader)
- completed_steps = resume_step // args.gradient_accumulation_steps
- resume_step -= starting_epoch * len(train_dataloader)
-
- # update the progress_bar if load from checkpoint
- progress_bar.update(completed_steps)
-
- for epoch in range(starting_epoch, args.num_train_epochs):
- model.train()
- if args.with_tracking:
- total_loss = 0
- if args.resume_from_checkpoint and epoch == starting_epoch and resume_step is not None:
- # We skip the first `n` batches in the dataloader when resuming from a checkpoint
- active_dataloader = accelerator.skip_first_batches(train_dataloader, resume_step)
- else:
- active_dataloader = train_dataloader
- for step, batch in enumerate(active_dataloader):
- outputs = model(**batch)
- loss = outputs.loss
- # We keep track of the loss at each epoch
- if args.with_tracking:
- total_loss += loss.detach().float()
- loss = loss / args.gradient_accumulation_steps
- accelerator.backward(loss)
- if step % args.gradient_accumulation_steps == 0 or step == len(train_dataloader) - 1:
- optimizer.step()
- lr_scheduler.step()
- optimizer.zero_grad()
- progress_bar.update(1)
- completed_steps += 1
-
- if isinstance(checkpointing_steps, int):
- if completed_steps % checkpointing_steps == 0 and accelerator.sync_gradients:
- output_dir = f"step_{completed_steps}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if completed_steps >= args.max_train_steps:
- break
-
- model.eval()
-
- if args.val_max_target_length is None:
- args.val_max_target_length = args.max_target_length
-
- gen_kwargs = {
- "max_length": args.val_max_target_length if args is not None else config.max_length,
- "num_beams": args.num_beams,
- }
- samples_seen = 0
- for step, batch in enumerate(eval_dataloader):
- with torch.no_grad():
- generated_tokens = accelerator.unwrap_model(model).generate(
- batch["input_ids"],
- attention_mask=batch["attention_mask"],
- **gen_kwargs,
- )
-
- generated_tokens = accelerator.pad_across_processes(
- generated_tokens, dim=1, pad_index=tokenizer.pad_token_id
- )
- labels = batch["labels"]
- if not args.pad_to_max_length:
- # If we did not pad to max length, we need to pad the labels too
- labels = accelerator.pad_across_processes(batch["labels"], dim=1, pad_index=tokenizer.pad_token_id)
-
- generated_tokens = accelerator.gather(generated_tokens).cpu().numpy()
- labels = accelerator.gather(labels).cpu().numpy()
-
- if args.ignore_pad_token_for_loss:
- # Replace -100 in the labels as we can't decode them.
- labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
-
- decoded_preds = tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
- decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
-
- decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
-
- # If we are in a multiprocess environment, the last batch has duplicates
- if accelerator.num_processes > 1:
- if step == len(eval_dataloader) - 1:
- decoded_preds = decoded_preds[: len(eval_dataloader.dataset) - samples_seen]
- decoded_labels = decoded_labels[: len(eval_dataloader.dataset) - samples_seen]
- else:
- samples_seen += len(decoded_labels)
-
- metric.add_batch(predictions=decoded_preds, references=decoded_labels)
- eval_metric = metric.compute()
- logger.info({"bleu": eval_metric["score"]})
-
- if args.with_tracking:
- accelerator.log(
- {
- "bleu": eval_metric["score"],
- "train_loss": total_loss.item() / len(train_dataloader),
- "epoch": epoch,
- "step": completed_steps,
- },
- step=completed_steps,
- )
-
- if args.push_to_hub and epoch < args.num_train_epochs - 1:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- api.upload_folder(
- commit_message=f"Training in progress epoch {epoch}",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
-
- if args.checkpointing_steps == "epoch":
- output_dir = f"epoch_{epoch}"
- if args.output_dir is not None:
- output_dir = os.path.join(args.output_dir, output_dir)
- accelerator.save_state(output_dir)
-
- if args.output_dir is not None:
- accelerator.wait_for_everyone()
- unwrapped_model = accelerator.unwrap_model(model)
- unwrapped_model.save_pretrained(
- args.output_dir, is_main_process=accelerator.is_main_process, save_function=accelerator.save
- )
- if accelerator.is_main_process:
- tokenizer.save_pretrained(args.output_dir)
- if args.push_to_hub:
- api.upload_folder(
- commit_message="End of training",
- folder_path=args.output_dir,
- repo_id=repo_id,
- repo_type="model",
- token=args.hub_token,
- )
- with open(os.path.join(args.output_dir, "all_results.json"), "w", encoding="utf-8") as f:
- json.dump({"eval_bleu": eval_metric["score"]}, f)
-
- accelerator.wait_for_everyone()
- accelerator.end_training()
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/pytorch/xla_spawn.py b/examples/pytorch/xla_spawn.py
deleted file mode 100644
index 70fad50df2df..000000000000
--- a/examples/pytorch/xla_spawn.py
+++ /dev/null
@@ -1,82 +0,0 @@
-# Copyright 2020 The HuggingFace Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-"""
-A simple launcher script for TPU training
-
-Inspired by https://github.com/pytorch/pytorch/blob/master/torch/distributed/launch.py
-
-::
- >>> python xla_spawn.py --num_cores=NUM_CORES_YOU_HAVE
- YOUR_TRAINING_SCRIPT.py (--arg1 --arg2 --arg3 and all other
- arguments of your training script)
-
-"""
-
-import importlib
-import sys
-from argparse import REMAINDER, ArgumentParser
-from pathlib import Path
-
-import torch_xla.distributed.xla_multiprocessing as xmp
-
-
-def parse_args():
- """
- Helper function parsing the command line options
- @retval ArgumentParser
- """
- parser = ArgumentParser(
- description=(
- "PyTorch TPU distributed training launch helper utility that will spawn up multiple distributed processes"
- )
- )
-
- # Optional arguments for the launch helper
- parser.add_argument("--num_cores", type=int, default=1, help="Number of TPU cores to use (1 or 8).")
-
- # positional
- parser.add_argument(
- "training_script",
- type=str,
- help=(
- "The full path to the single TPU training "
- "program/script to be launched in parallel, "
- "followed by all the arguments for the "
- "training script"
- ),
- )
-
- # rest from the training program
- parser.add_argument("training_script_args", nargs=REMAINDER)
-
- return parser.parse_args()
-
-
-def main():
- args = parse_args()
-
- # Import training_script as a module.
- script_fpath = Path(args.training_script)
- sys.path.append(str(script_fpath.parent.resolve()))
- mod_name = script_fpath.stem
- mod = importlib.import_module(mod_name)
-
- # Patch sys.argv
- sys.argv = [args.training_script] + args.training_script_args
-
- xmp.spawn(mod._mp_fn, args=(), nprocs=args.num_cores)
-
-
-if __name__ == "__main__":
- main()
diff --git a/examples/research_projects/README.md b/examples/research_projects/README.md
deleted file mode 100644
index e8a0ecd8c4e9..000000000000
--- a/examples/research_projects/README.md
+++ /dev/null
@@ -1,20 +0,0 @@
-
-
-# Research projects
-
-This directory previously contained various research projects using 🤗 Transformers. They have been moved
-to a separate repo, so you can now find them at https://github.com/huggingface/transformers-research-projects/
diff --git a/examples/run_on_remote.py b/examples/run_on_remote.py
deleted file mode 100644
index 2baf1d1a032a..000000000000
--- a/examples/run_on_remote.py
+++ /dev/null
@@ -1,70 +0,0 @@
-#!/usr/bin/env python
-# Copyright 2021 The HuggingFace Inc. team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-import argparse
-import shlex
-
-import runhouse as rh
-
-
-if __name__ == "__main__":
- # Refer to https://runhouse-docs.readthedocs-hosted.com/en/latest/api/python/cluster.html#hardware-setup for cloud access
- # setup instructions, if using on-demand hardware
-
- # If user passes --user --host --key_path , fill them in as BYO cluster
- # If user passes --instance --provider , fill them in as on-demand cluster
- # Throw an error if user passes both BYO and on-demand cluster args
- # Otherwise, use default values
- parser = argparse.ArgumentParser()
- parser.add_argument("--user", type=str, default="ubuntu")
- parser.add_argument("--host", type=str, default="localhost")
- parser.add_argument("--key_path", type=str, default=None)
- parser.add_argument("--instance", type=str, default="V100:1")
- parser.add_argument("--provider", type=str, default="cheapest")
- parser.add_argument("--use_spot", type=bool, default=False)
- parser.add_argument("--example", type=str, default="pytorch/text-generation/run_generation.py")
- args, unknown = parser.parse_known_args()
- if args.host != "localhost":
- if args.instance != "V100:1" or args.provider != "cheapest":
- raise ValueError("Cannot specify both BYO and on-demand cluster args")
- cluster = rh.cluster(
- name="rh-cluster", ips=[args.host], ssh_creds={"ssh_user": args.user, "ssh_private_key": args.key_path}
- )
- else:
- cluster = rh.cluster(
- name="rh-cluster", instance_type=args.instance, provider=args.provider, use_spot=args.use_spot
- )
- example_dir = args.example.rsplit("/", 1)[0]
-
- # Set up remote environment
- cluster.install_packages(["pip:./"]) # Installs transformers from local source
- # Note transformers is copied into the home directory on the remote machine, so we can install from there
- cluster.run([f"pip install -r transformers/examples/{example_dir}/requirements.txt"])
- cluster.run(["pip install torch --upgrade --extra-index-url https://download.pytorch.org/whl/cu117"])
-
- # Run example. You can bypass the CLI wrapper and paste your own code here.
- cluster.run([f"python transformers/examples/{args.example} {shlex.join(unknown)}"])
-
- # Alternatively, we can just import and run a training function (especially if there's no wrapper CLI):
- # from my_script... import train
- # reqs = ['pip:./', 'torch', 'datasets', 'accelerate', 'evaluate', 'tqdm', 'scipy', 'scikit-learn', 'tensorboard']
- # launch_train_gpu = rh.function(fn=train,
- # system=gpu,
- # reqs=reqs,
- # name='train_bert_glue')
- #
- # We can pass in arguments just like we would to a function:
- # launch_train_gpu(num_epochs = 3, lr = 2e-5, seed = 42, batch_size = 16
- # stream_logs=True)
diff --git a/examples/training/distributed_training.py b/examples/training/distributed_training.py
deleted file mode 100644
index af19106a8276..000000000000
--- a/examples/training/distributed_training.py
+++ /dev/null
@@ -1,113 +0,0 @@
-import argparse
-import os
-
-import torch
-import torch.distributed as dist
-
-
-# Environment variables set by torch.distributed.launch
-LOCAL_RANK = int(os.environ["LOCAL_RANK"])
-WORLD_SIZE = int(os.environ["WORLD_SIZE"])
-WORLD_RANK = int(os.environ["RANK"])
-
-LOCAL_RANK = int(os.environ["OMPI_COMM_WORLD_LOCAL_RANK"])
-WORLD_SIZE = int(os.environ["OMPI_COMM_WORLD_SIZE"])
-WORLD_RANK = int(os.environ["OMPI_COMM_WORLD_RANK"])
-
-
-def run(backend):
- tensor = torch.zeros(1)
- # Need to put tensor on a GPU device for nccl backend
- if backend == "nccl":
- device = torch.device(f"cuda:{LOCAL_RANK}")
- tensor = tensor.to(device)
-
- if WORLD_RANK == 0:
- for rank_recv in range(1, WORLD_SIZE):
- dist.send(tensor=tensor, dst=rank_recv)
- print(f"worker_{0} sent data to Rank {rank_recv}\n")
- else:
- dist.recv(tensor=tensor, src=0)
- print(f"worker_{WORLD_RANK} has received data from rank {0}\n")
-
-
-def init_processes(backend):
- dist.init_process_group(backend, rank=WORLD_RANK, world_size=WORLD_SIZE)
- run(backend)
-
-
-if __name__ == "__main__":
- parser = argparse.ArgumentParser()
- parser.add_argument(
- "--local_rank", type=int, help="Local rank. Necessary for using the torch.distributed.launch utility."
- )
- parser.add_argument("--backend", type=str, default="nccl", choices=["nccl", "gloo"])
- args = parser.parse_args()
-
- init_processes(backend=args.backend)
-
-""""
-python-m torch.distributed.launch \
---nproc_per_node=2 --nnodes=2 --node_rank=0 \
-test_compile.py
-
-python3 -m torch.distributed.launch \
---nproc_per_node=2 --nnodes=2 --node_rank=1 \
---master_addr=104.171.200.62 --master_port=1234 \
-main.py \
---backend=nccl --use_syn --batch_size=8192 --arch=resnet152
-
-
-
-mpirun -np 4 \
--H 104.171.200.62:2,104.171.200.182:2 \
--x MASTER_ADDR=104.171.200.62 \
--x MASTER_PORT=1234 \
--x PATH \
--bind-to none -map-by slot \
--mca pml ob1 -mca btl ^openib \
-python3 main.py
-"""
-
-
-""""
-You need a host file with the name of hosts.
-for example I have arthur@ip-26-0-162-46 and arthur@ip-26-0-162-239
-
-________
-hostfile
-ip-26-0-162-46 slots=8
-ip-26-0-162-239 slots=8
-________
-
-mpirun --hostfile hostfile -np 16 \
- --bind-to none --map-by slot \
- -x MASTER_ADDR= \
- -x MASTER_PORT=29500 \
- -x NCCL_DEBUG=INFO \
- -x NCCL_SOCKET_IFNAME=^lo,docker0 \
- -x CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
- python your_script.py --backend nccl
-
-
-to get the master IP you need to do a few things:
-hostname -I | awk '{print $1}'
-
-
-Use `ping ip-26-0-162-46` to check if connected
-
-26.0.162.46
-
-mpirun --hostfile hostfile -np 16 \
- --bind-to none --map-by slot \
- -x MASTER_ADDR=26.0.162.46 \
- -x MASTER_PORT=29500 \
- -x NCCL_DEBUG=INFO \
- -x NCCL_SOCKET_IFNAME=^lo,docker0 \
- -x CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
- python your_script.py --backend nccl
-
-
-mpirun --hostfile hostfile -np 2 -x NCCL_DEBUG=INFO python -c "import os;print(os.environ['OMPI_COMM_WORLD_LOCAL_RANK'])" -b 8 -e 128M -f 2 -g 1
-to test your setup
-"""
diff --git a/i18n/README_ar.md b/i18n/README_ar.md
index dfb757db9d13..dbf45cb2f001 100644
--- a/i18n/README_ar.md
+++ b/i18n/README_ar.md
@@ -244,7 +244,6 @@ limitations under the License.
- ليست هذه المكتبة عبارة عن مجموعة أدوات من الصناديق المكونة للشبكات العصبية. لم يتم إعادة صياغة التعليمات البرمجية في ملفات النموذج باستخدام تجريدات إضافية عن قصد، بحيث يمكن للباحثين إجراء حلقات تكرار سريعة على كل من النماذج دون الغوص في تجريدات/ملفات إضافية.
- لا يُقصد بواجهة برمجة التطبيقات (API) للتدريب العمل على أي نموذج ولكنه مُستَهدف للعمل مع النماذج التي توفرها المكتبة. للحلقات العامة للتعلم الآلي، يجب استخدام مكتبة أخرى (ربما، [تسريع](https://huggingface.co/docs/accelerate)).
-- في حين أننا نسعى جاهدين لتقديم أكبر عدد ممكن من حالات الاستخدام، فإن البرامج النصية الموجودة في مجلد [الأمثلة](https://github.com/huggingface/transformers/tree/main/examples) الخاص بنا هي مجرد أمثلة. من المتوقع ألا تعمل هذه البرامج النصية خارج الصندوق على مشكلتك المحددة وأنه سيُطلب منك تغيير بضع أسطر من التعليمات البرمجية لتكييفها مع احتياجاتك.
## التثبيت
@@ -291,7 +290,7 @@ conda install conda-forge::transformers
للتحقق مما إذا كان لكل نموذج تنفيذ في Flax أو PyTorch أو TensorFlow، أو كان لديه مُعلم مرفق مدعوم من مكتبة 🤗 Tokenizers، يرجى الرجوع إلى [هذا الجدول](https://huggingface.co/docs/transformers/index#supported-frameworks).
-تم اختبار هذه التطبيقات على العديد من مجموعات البيانات (راجع البرامج النصية المثالية) ويجب أن تتطابق مع أداء التنفيذ الأصلي. يمكنك العثور على مزيد من التفاصيل حول الأداء في قسم الأمثلة من [الوثائق](https://github.com/huggingface/transformers/tree/main/examples).
+تم اختبار هذه التطبيقات على العديد من مجموعات البيانات ويجب أن تتطابق مع أداء التنفيذ الأصلي.
## تعلم المزيد
@@ -302,7 +301,6 @@ conda install conda-forge::transformers
| [ملخص المهام](https://huggingface.co/docs/transformers/task_summary) | المهام التي يدعمها 🤗 Transformers |
| [برنامج تعليمي لمعالجة مسبقة](https://huggingface.co/docs/transformers/preprocessing) | استخدام فئة `Tokenizer` لإعداد البيانات للنماذج |
| [التدريب والضبط الدقيق](https://huggingface.co/docs/transformers/training) | استخدام النماذج التي يوفرها 🤗 Transformers في حلقة تدريب PyTorch/TensorFlow وواجهة برمجة تطبيقات `Trainer` |
-| [جولة سريعة: البرامج النصية للضبط الدقيق/الاستخدام](https://github.com/huggingface/transformers/tree/main/examples) | البرامج النصية المثالية للضبط الدقيق للنماذج على مجموعة واسعة من المهام |
| [مشاركة النماذج وتحميلها](https://huggingface.co/docs/transformers/model_sharing) | تحميل ومشاركة نماذجك المضبوطة بدقة مع المجتمع |
## الاستشهاد
diff --git a/i18n/README_bn.md b/i18n/README_bn.md
index 2bfb9b28d2dc..bcda25cd56b6 100644
--- a/i18n/README_bn.md
+++ b/i18n/README_bn.md
@@ -244,7 +244,6 @@ pipeline(
* এই লাইব্রেরি নিউরাল নেটওয়ার্কের জন্য ব্লক-মডিউল টুলবক্স নয়। মডেল ফাইলের কোডে অতিরিক্ত অ্যাবস্ট্র্যাকশন intentionally করা হয়নি, যাতে গবেষকরা দ্রুত প্রতিটি মডেলের উপর কাজ করতে পারে কোনো অতিরিক্ত ফাইল বা স্তরে না গিয়ে।
* ট্রেইনিং API মূলত Transformers-এর PyTorch মডেলের সাথে কাজ করার জন্য অপটিমাইজ করা হয়েছে। সাধারণ মেশিন লার্নিং লুপের জন্য, [Accelerate](https://huggingface.co/docs/accelerate) এর মতো অন্য লাইব্রেরি ব্যবহার করা উচিত।
-* [উদাহরণ স্ক্রিপ্টগুলো](https://github.com/huggingface/transformers/tree/main/examples) শুধু *উদাহরণ*। এগুলো সরাসরি আপনার ব্যবহারের ক্ষেত্রে কাজ নাও করতে পারে, তাই কোড সামঞ্জস্য করতে হতে পারে।
## Transformers দিয়ে ১০০টি প্রজেক্ট
diff --git a/i18n/README_de.md b/i18n/README_de.md
index 8017d491c7d3..533e3f2583a1 100644
--- a/i18n/README_de.md
+++ b/i18n/README_de.md
@@ -245,7 +245,6 @@ Das Modell selbst ist ein reguläres [PyTorch `nn.Module`](https://pytorch.org/d
- Diese Bibliothek ist kein modularer Werkzeugkasten mit Bausteinen für neuronale Netze. Der Code in den Modelldateien ist absichtlich nicht mit zusätzlichen Abstraktionen refaktorisiert, sodass Forscher schnell mit jedem der Modelle iterieren können, ohne sich in zusätzliche Abstraktionen/Dateien vertiefen zu müssen.
- Die Trainings-API ist nicht dafür gedacht, mit beliebigen Modellen zu funktionieren, sondern ist für die Verwendung mit den von der Bibliothek bereitgestellten Modellen optimiert. Für generische Trainingsschleifen von maschinellem Lernen sollten Sie eine andere Bibliothek verwenden (möglicherweise [Accelerate](https://huggingface.co/docs/accelerate)).
-- Auch wenn wir bestrebt sind, so viele Anwendungsfälle wie möglich zu veranschaulichen, sind die Beispielskripte in unserem [`examples`](./examples) Ordner genau das: Beispiele. Es ist davon auszugehen, dass sie nicht sofort auf Ihr spezielles Problem anwendbar sind und einige Codezeilen geändert werden müssen, um sie für Ihre Bedürfnisse anzupassen.
## Installation
@@ -291,7 +290,7 @@ Aktuelle Anzahl der Checkpoints: .
-Diese Implementierungen wurden mit mehreren Datensätzen getestet (siehe Beispielskripte) und sollten den Leistungen der ursprünglichen Implementierungen entsprechen. Weitere Details zur Leistung finden Sie im Abschnitt der Beispiele in der [Dokumentation](https://github.com/huggingface/transformers/tree/main/examples).
+Diese Implementierungen wurden mit mehreren Datensätzen getestet und sollten den Leistungen der ursprünglichen Implementierungen entsprechen.
## Mehr erfahren
@@ -301,7 +300,6 @@ Diese Implementierungen wurden mit mehreren Datensätzen getestet (siehe Beispie
| [Zusammenfassung der Aufgaben](https://huggingface.co/docs/transformers/task_summary) | Von 🤗 Transformers unterstützte Aufgaben |
| [Vorverarbeitungs-Tutorial](https://huggingface.co/docs/transformers/preprocessing) | Verwendung der `Tokenizer`-Klasse zur Vorverarbeitung der Daten für die Modelle |
| [Training und Feintuning](https://huggingface.co/docs/transformers/training) | Verwendung der von 🤗 Transformers bereitgestellten Modelle in einer PyTorch-/TensorFlow-Trainingsschleife und der `Trainer`-API |
-| [Schnelleinstieg: Feintuning/Anwendungsskripte](https://github.com/huggingface/transformers/tree/main/examples) | Beispielskripte für das Feintuning von Modellen für eine breite Palette von Aufgaben |
| [Modellfreigabe und -upload](https://huggingface.co/docs/transformers/model_sharing) | Laden Sie Ihre feingetunten Modelle hoch und teilen Sie sie mit der Community |
## Zitation
diff --git a/i18n/README_es.md b/i18n/README_es.md
index 4bd124a182be..253ecea2dff7 100644
--- a/i18n/README_es.md
+++ b/i18n/README_es.md
@@ -226,7 +226,6 @@ El modelo en si es un [Pytorch `nn.Module`](https://pytorch.org/docs/stable/nn.h
- Esta biblioteca no es una caja de herramientas modular de bloques de construcción para redes neuronales. El código en los archivos del modelo no se refactoriza con abstracciones adicionales a propósito, de modo que los investigadores puedan iterar rápidamente en cada uno de los modelos sin sumergirse en abstracciones/archivos adicionales.
- La API de entrenamiento no está diseñada para funcionar en ningún modelo, pero está optimizada para funcionar con los modelos proporcionados por la biblioteca. Para bucles genéricos de aprendizaje automático, debe usar otra biblioteca (posiblemente, [Accelerate](https://huggingface.co/docs/accelerate)).
-- Si bien nos esforzamos por presentar tantos casos de uso como sea posible, los scripts en nuestra [carpeta de ejemplos](https://github.com/huggingface/transformers/tree/main/examples) son solo eso: ejemplos. Se espera que no funcionen de forma inmediata en su problema específico y que deba cambiar algunas líneas de código para adaptarlas a sus necesidades.
## Instalación
@@ -273,7 +272,7 @@ Número actual de puntos de control: .
-Estas implementaciones se han probado en varios conjuntos de datos (consulte los scripts de ejemplo) y deberían coincidir con el rendimiento de las implementaciones originales. Puede encontrar más detalles sobre el rendimiento en la sección Examples de la [documentación](https://github.com/huggingface/transformers/tree/main/examples).
+Estas implementaciones se han probado en varios conjuntos de datos y deberían coincidir con el rendimiento de las implementaciones originales.
## Aprender más
@@ -284,7 +283,6 @@ Estas implementaciones se han probado en varios conjuntos de datos (consulte los
| [Resumen de tareas](https://huggingface.co/docs/transformers/task_summary) | Tareas soportadas 🤗 Transformers |
| [Tutorial de preprocesamiento](https://huggingface.co/docs/transformers/preprocessing) | Usando la clase `Tokenizer` para preparar datos para los modelos |
| [Entrenamiento y puesta a punto](https://huggingface.co/docs/transformers/training) | Usando los modelos aportados por 🤗 Transformers en un bucle de entreno de PyTorch/TensorFlow y la API de `Trainer` |
-| [Recorrido rápido: secuencias de comandos de ajuste/uso](https://github.com/huggingface/transformers/tree/main/examples) | Scripts de ejemplo para ajustar modelos en una amplia gama de tareas |
| [Compartir y subir modelos](https://huggingface.co/docs/transformers/model_sharing) | Carga y comparte tus modelos perfeccionados con la comunidad |
| [Migración](https://huggingface.co/docs/transformers/migration) | Migra a 🤗 Transformers desde `pytorch-transformers` o `pytorch-pretrained-bert` |
diff --git a/i18n/README_fa.md b/i18n/README_fa.md
index c3c17b52c48e..20bab3ec776f 100644
--- a/i18n/README_fa.md
+++ b/i18n/README_fa.md
@@ -236,7 +236,6 @@ pipeline(
- این کتابخانه یک جعبهابزار ماژولار برای شبکههای عصبی عمومی نیست؛ کدهای مدلها عمداً برای محققان کمتر انتزاعی شدهاند.
- رابط آموزش (Training API) بهینهسازی شده برای مدلهای Transformers است. برای حلقههای عمومی یادگیری ماشین، بهتر است از کتابخانههایی مانند [Accelerate](https://huggingface.co/docs/accelerate) استفاده کنید.
-- [اسکریپتهای نمونه](https://github.com/huggingface/transformers/tree/main/examples) ممکن است برای موارد استفاده خاص شما نیاز به تغییر و سازگاری داشته باشند.
## ۱۰۰ پروژه با استفاده از Transformers
diff --git a/i18n/README_fr.md b/i18n/README_fr.md
index 3e511f142b8d..eebf3bbe4c33 100644
--- a/i18n/README_fr.md
+++ b/i18n/README_fr.md
@@ -242,7 +242,6 @@ Le modèle lui-même est un module [`nn.Module` PyTorch](https://pytorch.org/doc
- Cette bibliothèque n'est pas une boîte à outils modulaire de blocs de construction pour les réseaux neuronaux. Le code dans les fichiers de modèle n'est pas refactorisé avec des abstractions supplémentaires à dessein, afin que les chercheurs puissent itérer rapidement sur chacun des modèles sans plonger dans des abstractions/fichiers supplémentaires.
- L'API d'entraînement n'est pas destinée à fonctionner avec n'importe quel modèle, mais elle est optimisée pour fonctionner avec les modèles fournis par la bibliothèque. Pour des boucles génériques d'apprentissage automatique, vous devriez utiliser une autre bibliothèque (éventuellement, [Accelerate](https://huggingface.co/docs/accelerate)).
-- Bien que nous nous efforcions de présenter autant de cas d'utilisation que possible, les scripts de notre [dossier d'exemples](https://github.com/huggingface/transformers/tree/main/examples) ne sont que cela : des exemples. Il est prévu qu'ils ne fonctionnent pas immédiatement sur votre problème spécifique et que vous devrez probablement modifier quelques lignes de code pour les adapter à vos besoins.
## Installation
@@ -289,7 +288,7 @@ Nombre actuel de points de contrôle : .
-Ces implémentations ont été testées sur plusieurs ensembles de données (voir les scripts d'exemple) et devraient correspondre aux performances des implémentations originales. Vous pouvez trouver plus de détails sur les performances dans la section Exemples de la [documentation](https://github.com/huggingface/transformers/tree/main/examples).
+Ces implémentations ont été testées sur plusieurs ensembles de données et devraient correspondre aux performances des implémentations originales.
## En savoir plus
@@ -299,7 +298,6 @@ Ces implémentations ont été testées sur plusieurs ensembles de données (voi
| [Résumé des tâches](https://huggingface.co/docs/transformers/task_summary) | Tâches prises en charge par les 🤗 Transformers |
| [Tutoriel de prétraitement](https://huggingface.co/docs/transformers/preprocessing) | Utilisation de la classe `Tokenizer` pour préparer les données pour les modèles |
| [Entraînement et ajustement fin](https://huggingface.co/docs/transformers/training) | Utilisation des modèles fournis par les 🤗 Transformers dans une boucle d'entraînement PyTorch/TensorFlow et de l'API `Trainer` |
-| [Tour rapide : Scripts d'ajustement fin/d'utilisation](https://github.com/huggingface/transformers/tree/main/examples) | Scripts d'exemple pour ajuster finement les modèles sur une large gamme de tâches |
| [Partage et téléversement de modèles](https://huggingface.co/docs/transformers/model_sharing) | Téléchargez et partagez vos modèles ajustés avec la communauté |
## Citation
diff --git a/i18n/README_hd.md b/i18n/README_hd.md
index 4d16912fb2f8..ff3b999c4581 100644
--- a/i18n/README_hd.md
+++ b/i18n/README_hd.md
@@ -202,7 +202,6 @@ checkpoint: जाँच बिंदु
- यह लाइब्रेरी मॉड्यूलर न्यूरल नेटवर्क टूलबॉक्स नहीं है। मॉडल फ़ाइल में कोड जानबूझकर अल्पविकसित है, बिना अतिरिक्त सार इनकैप्सुलेशन के, ताकि शोधकर्ता अमूर्तता और फ़ाइल जंपिंग में शामिल हुए जल्दी से पुनरावृति कर सकें।
- `ट्रेनर` एपीआई किसी भी मॉडल के साथ संगत नहीं है, यह केवल इस पुस्तकालय के मॉडल के लिए अनुकूलित है। यदि आप सामान्य मशीन लर्निंग के लिए उपयुक्त प्रशिक्षण लूप कार्यान्वयन की तलाश में हैं, तो कहीं और देखें।
-- हमारे सर्वोत्तम प्रयासों के बावजूद, [उदाहरण निर्देशिका](https://github.com/huggingface/transformers/tree/main/examples) में स्क्रिप्ट केवल उपयोग के मामले हैं। आपकी विशिष्ट समस्या के लिए, वे जरूरी नहीं कि बॉक्स से बाहर काम करें, और आपको कोड की कुछ पंक्तियों को सूट करने की आवश्यकता हो सकती है।
## स्थापित करना
@@ -247,7 +246,7 @@ conda install conda-forge::transformers
यह जांचने के लिए कि क्या किसी मॉडल में पहले से ही Flax, PyTorch या TensorFlow का कार्यान्वयन है, या यदि उसके पास Tokenizers लाइब्रेरी में संबंधित टोकन है, तो [यह तालिका](https://huggingface.co/docs/transformers/index#supported) देखें। -फ्रेमवर्क)।
-इन कार्यान्वयनों का परीक्षण कई डेटासेट पर किया गया है (देखें केस स्क्रिप्ट का उपयोग करें) और वैनिला कार्यान्वयन के लिए तुलनात्मक रूप से प्रदर्शन करना चाहिए। आप उपयोग के मामले के दस्तावेज़ [इस अनुभाग](https://huggingface.co/docs/transformers/examples) में व्यवहार का विवरण पढ़ सकते हैं।
+इन कार्यान्वयनों का परीक्षण कई डेटासेट पर किया गया है और वैनिला कार्यान्वयन के लिए तुलनात्मक रूप से प्रदर्शन करना चाहिए।
## अधिक समझें
@@ -258,7 +257,6 @@ conda install conda-forge::transformers
| [कार्य सारांश](https://huggingface.co/docs/transformers/task_summary) | ट्रांसफॉर्मर समर्थित कार्य |
| [प्रीप्रोसेसिंग ट्यूटोरियल](https://huggingface.co/docs/transformers/preprocessing) | मॉडल के लिए डेटा तैयार करने के लिए `टोकनाइज़र` का उपयोग करना |
| [प्रशिक्षण और फाइन-ट्यूनिंग](https://huggingface.co/docs/transformers/training) | PyTorch/TensorFlow के ट्रेनिंग लूप या `ट्रेनर` API में ट्रांसफॉर्मर द्वारा दिए गए मॉडल का उपयोग करें |
-| [क्विक स्टार्ट: ट्वीकिंग एंड यूज़ केस स्क्रिप्ट्स](https://github.com/huggingface/transformers/tree/main/examples) | विभिन्न कार्यों के लिए केस स्क्रिप्ट का उपयोग करें |
| [मॉडल साझा करना और अपलोड करना](https://huggingface.co/docs/transformers/model_sharing) | समुदाय के साथ अपने फाइन टूनड मॉडल अपलोड और साझा करें |
| [माइग्रेशन](https://huggingface.co/docs/transformers/migration) | `पाइटोरच-ट्रांसफॉर्मर्स` या `पाइटोरच-प्रीट्रेनड-बर्ट` से ट्रांसफॉर्मर में माइग्रेट करना |
diff --git a/i18n/README_it.md b/i18n/README_it.md
index f0dd78cb64c7..04e6bb786a24 100644
--- a/i18n/README_it.md
+++ b/i18n/README_it.md
@@ -246,7 +246,6 @@ pipeline(
- Questa libreria non è un toolbox modulare di blocchi costitutivi per reti neurali. Il codice nei file dei modelli non è stato rifattorizzato con ulteriori astrazioni di proposito, in modo che i ricercatori possano iterare rapidamente su ciascuno dei modelli senza dover approfondire ulteriori astrazioni/file.
- L'API di addestramento è ottimizzata per funzionare con i modelli PyTorch forniti da Transformers. Per i loop generici di machine learning, è necessario utilizzare un'altra libreria come [Accelerate](https://huggingface.co/docs/accelerate).
-- Gli [script di esempio](https://github.com/huggingface/transformers/tree/main/examples) sono solo *esempi*. Potrebbero non funzionare immediatamente nel vostro caso specifico e potrebbe essere necessario adattare il codice affinché funzioni.
## 100 progetti che usano Transformers
diff --git a/i18n/README_ja.md b/i18n/README_ja.md
index b611f0e846b9..ad4dd8583652 100644
--- a/i18n/README_ja.md
+++ b/i18n/README_ja.md
@@ -275,7 +275,6 @@ pipeline(
- このライブラリは、ニューラルネットのためのビルディングブロックのモジュール式ツールボックスではありません。モデルファイルのコードは、研究者が追加の抽象化/ファイルに飛び込むことなく、各モデルを素早く反復できるように、意図的に追加の抽象化でリファクタリングされていません。
- 学習APIはTransformersが提供するPyTorchモデルで動作するように最適化されています。一般的な機械学習のループには、[Accelerate](https://huggingface.co/docs/accelerate)のような別のライブラリを使用する必要があります。
-- [example scripts](https://github.com/huggingface/transformers/tree/main/examples)にあるスクリプトはあくまで*例*です。あなたの特定の問題に対してすぐに動作するわけではなく、あなたのニーズに合わせるためにコードを適応させる必要があるでしょう。
## Transformersを使用している100のプロジェクト
diff --git a/i18n/README_ko.md b/i18n/README_ko.md
index 54d93b03a53f..937bdcc1dae0 100644
--- a/i18n/README_ko.md
+++ b/i18n/README_ko.md
@@ -241,7 +241,6 @@ Transformers에 달린 100,000개의 별을 축하하기 위해, 우리는 커
- 이 라이브러리는 신경망 블록을 만들기 위한 모듈이 아닙니다. 연구자들이 여러 파일을 살펴보지 않고 바로 각 모델을 사용할 수 있도록, 모델 파일 코드의 추상화 수준을 적정하게 유지했습니다.
- 학습 API는 모든 모델에 적용할 수 있도록 만들어지진 않았지만, 라이브러리가 제공하는 모델들에 적용할 수 있도록 최적화되었습니다. 일반적인 머신 러닝을 위해선, 다른 라이브러리를 사용하세요(예를 들면, [Accelerate](https://huggingface.co/docs/accelerate/index)).
-- 가능한 많은 사용 예시를 보여드리고 싶어서, [예시 폴더](https://github.com/huggingface/transformers/tree/main/examples)의 스크립트를 준비했습니다. 이 스크립트들을 수정 없이 특정한 문제에 바로 적용하지 못할 수 있습니다. 필요에 맞게 일부 코드를 수정해야 할 수 있습니다.
## 설치
@@ -288,7 +287,7 @@ Flax, PyTorch, TensorFlow 설치 페이지에서 이들을 conda로 설치하는
각 모델이 Flax, PyTorch, TensorFlow으로 구현되었는지 또는 🤗 Tokenizers 라이브러리가 지원하는 토크나이저를 사용하는지 확인하려면, [이 표](https://huggingface.co/docs/transformers/ko/index#supported-framework)를 확인하세요.
-이 구현은 여러 데이터로 검증되었고 (예시 스크립트를 참고하세요) 오리지널 구현의 성능과 같아야 합니다. [도큐먼트](https://github.com/huggingface/transformers/tree/main/examples)의 Examples 섹션에서 성능에 대한 자세한 설명을 확인할 수 있습니다.
+이 구현은 여러 데이터로 검증되었고 오리지널 구현의 성능과 같아야 합니다.
## 더 알아보기
@@ -298,7 +297,6 @@ Flax, PyTorch, TensorFlow 설치 페이지에서 이들을 conda로 설치하는
| [과제 요약](https://huggingface.co/docs/transformers/ko/task_summary) | 🤗 Transformers가 지원하는 과제들 |
| [전처리 튜토리얼](https://huggingface.co/docs/transformers/ko/preprocessing) | `Tokenizer` 클래스를 이용해 모델을 위한 데이터 준비하기 |
| [학습과 파인 튜닝](https://huggingface.co/docs/transformers/ko/training) | 🤗 Transformers가 제공하는 모델 PyTorch/TensorFlow 학습 과정과 `Trainer` API에서 사용하기 |
-| [퀵 투어: 파인 튜닝/사용 스크립트](https://github.com/huggingface/transformers/tree/main/examples) | 다양한 과제에서 모델을 파인 튜닝하는 예시 스크립트 |
| [모델 공유 및 업로드](https://huggingface.co/docs/transformers/ko/model_sharing) | 커뮤니티에 파인 튜닝된 모델을 업로드 및 공유하기 |
## 인용
diff --git a/i18n/README_pt-br.md b/i18n/README_pt-br.md
index e3e59f31373d..377c05ebe6a5 100644
--- a/i18n/README_pt-br.md
+++ b/i18n/README_pt-br.md
@@ -252,7 +252,6 @@ O modelo em si é um [Pytorch `nn.Module`](https://pytorch.org/docs/stable/nn.ht
- Esta biblioteca não é uma caixa de ferramentas modular para construir redes neurais. O código nos arquivos do modelo não é refatorado com abstrações adicionais de propósito, para que os pesquisadores possam iterar rapidamente em cada um dos modelos sem se aprofundar em abstrações/arquivos adicionais.
- A API de treinamento não é projetada para funcionar com qualquer modelo, mas é otimizada para funcionar com os modelos fornecidos pela biblioteca. Para loops de aprendizado de máquina genéricos, você deve usar outra biblioteca (possivelmente, [Accelerate](https://huggingface.co/docs/accelerate)).
-- Embora nos esforcemos para apresentar o maior número possível de casos de uso, os scripts em nossa [pasta de exemplos](https://github.com/huggingface/transformers/tree/main/examples) são apenas isso: exemplos. É esperado que eles não funcionem prontos para uso em seu problema específico e que seja necessário modificar algumas linhas de código para adaptá-los às suas necessidades.
@@ -300,7 +299,7 @@ Número atual de pontos de verificação: .
-Essas implementações foram testadas em vários conjuntos de dados (veja os scripts de exemplo) e devem corresponder ao desempenho das implementações originais. Você pode encontrar mais detalhes sobre o desempenho na seção de Exemplos da [documentação](https://github.com/huggingface/transformers/tree/main/examples).
+Essas implementações foram testadas em vários conjuntos de dados e devem corresponder ao desempenho das implementações originais.
## Saiba mais
@@ -311,7 +310,6 @@ Essas implementações foram testadas em vários conjuntos de dados (veja os scr
| [Resumo de Tarefas](https://huggingface.co/docs/transformers/task_summary) | Tarefas suportadas pelo 🤗 Transformers |
| [Tutorial de Pré-processamento](https://huggingface.co/docs/transformers/preprocessing) | Usando a classe `Tokenizer` para preparar dados para os modelos |
| [Treinamento e Ajuste Fino](https://huggingface.co/docs/transformers/training) | Usando os modelos fornecidos pelo 🤗 Transformers em um loop de treinamento PyTorch/TensorFlow e a API `Trainer` |
-| [Tour Rápido: Scripts de Ajuste Fino/Utilização](https://github.com/huggingface/transformers/tree/main/examples) | Scripts de exemplo para ajuste fino de modelos em uma ampla gama de tarefas |
| [Compartilhamento e Envio de Modelos](https://huggingface.co/docs/transformers/model_sharing) | Envie e compartilhe seus modelos ajustados com a comunidade |
## Citação
diff --git a/i18n/README_ro.md b/i18n/README_ro.md
index f6a40aaad410..2c8d93a95707 100644
--- a/i18n/README_ro.md
+++ b/i18n/README_ro.md
@@ -241,7 +241,6 @@ pipeline(
- Această bibliotecă nu este un toolbox de block-uri pentru construirea rețelelor neuronale. Codul din fișierele modelelor nu este refactorizat cu mai multă abstractizare pentru ca cercetătorii să poată utiliza rapid fiecare dintre modele fără să aibă de-a face cu fișiere/abstractizări adiționale.
- API-ul de antrenare este optimizat pentru utilizarea cu modele PyTorch oferite de Transformers. Pentru loop-uri generice de machine learning, utilizează o bibliotecă precum [Accelerate](https://huggingface.co/docs/accelerate).
-- [Script-urile de exemplu](https://github.com/huggingface/transformers/tree/main/examples) sunt doar *exemple*. S-ar putea ca acestea să nu funcționeze în toate cazurile și va trebui să adaptezi codul pentru ca acestea să funcționeze.
## 100 de proiecte folosind Transformers
diff --git a/i18n/README_ru.md b/i18n/README_ru.md
index f0196add47e8..f2a8e847f315 100644
--- a/i18n/README_ru.md
+++ b/i18n/README_ru.md
@@ -243,7 +243,6 @@ Hugging Face Hub. Мы хотим, чтобы Transformers позволил ра
- Данная библиотека не является модульным набором строительных блоков для нейронных сетей. Код в файлах моделей специально не рефакторится дополнительными абстракциями, чтобы исследователи могли быстро итеративно работать с каждой из моделей, не погружаясь в дополнительные абстракции/файлы.
- API обучения не предназначен для работы с любой моделью, а оптимизирован для работы с моделями, предоставляемыми библиотекой. Для работы с общими циклами машинного обучения следует использовать другую библиотеку (возможно, [Accelerate](https://huggingface.co/docs/accelerate)).
-- Несмотря на то, что мы стремимся представить как можно больше примеров использования, скрипты в нашей папке [примеров](https://github.com/huggingface/transformers/tree/main/examples) являются именно примерами. Предполагается, что они не будут работать "из коробки" для решения вашей конкретной задачи, и вам придется изменить несколько строк кода, чтобы адаптировать их под свои нужды.
## Установка
@@ -290,7 +289,7 @@ conda install conda-forge::transformers
Чтобы проверить, есть ли у каждой модели реализация на Flax, PyTorch или TensorFlow, или связанный с ней токенизатор, поддерживаемый библиотекой 🤗 Tokenizers, обратитесь к [этой таблице](https://huggingface.co/docs/transformers/index#supported-frameworks).
-Эти реализации были протестированы на нескольких наборах данных (см. примеры скриптов) и должны соответствовать производительности оригинальных реализаций. Более подробную информацию о производительности можно найти в разделе "Примеры" [документации](https://github.com/huggingface/transformers/tree/main/examples).
+Эти реализации были протестированы на нескольких наборах данных и должны соответствовать производительности оригинальных реализаций.
## Изучи больше
@@ -301,7 +300,6 @@ conda install conda-forge::transformers
| [Краткие описания задач](https://huggingface.co/docs/transformers/task_summary) | Задачи поддерживаются 🤗 Transformers |
| [Пособие по предварительной обработке](https://huggingface.co/docs/transformers/preprocessing) | Использование класса `Tokenizer` для подготовки данных для моделей |
| [Обучение и доработка](https://huggingface.co/docs/transformers/training) | Использование моделей, предоставляемых 🤗 Transformers, в цикле обучения PyTorch/TensorFlow и API `Trainer`. |
-| [Быстрый тур: Тонкая настройка/скрипты использования](https://github.com/huggingface/transformers/tree/main/examples) | Примеры скриптов для тонкой настройки моделей на широком спектре задач |
| [Совместное использование и загрузка моделей](https://huggingface.co/docs/transformers/model_sharing) | Загружайте и делитесь с сообществом своими доработанными моделями |
## Цитирование
diff --git a/i18n/README_te.md b/i18n/README_te.md
index 70bc241962c9..d819cfe84c3d 100644
--- a/i18n/README_te.md
+++ b/i18n/README_te.md
@@ -245,7 +245,6 @@ limitations under the License.
- ఈ లైబ్రరీ న్యూరల్ నెట్ల కోసం బిల్డింగ్ బ్లాక్ల మాడ్యులర్ టూల్బాక్స్ కాదు. మోడల్ ఫైల్లలోని కోడ్ ఉద్దేశపూర్వకంగా అదనపు సంగ్రహణలతో రీఫ్యాక్టరింగ్ చేయబడదు, తద్వారా పరిశోధకులు అదనపు సంగ్రహణలు/ఫైళ్లలోకి ప్రవేశించకుండా ప్రతి మోడల్పై త్వరగా మళ్లించగలరు.
- శిక్షణ API ఏ మోడల్లో పని చేయడానికి ఉద్దేశించబడలేదు కానీ లైబ్రరీ అందించిన మోడల్లతో పని చేయడానికి ఆప్టిమైజ్ చేయబడింది. సాధారణ మెషిన్ లెర్నింగ్ లూప్ల కోసం, మీరు మరొక లైబ్రరీని ఉపయోగించాలి (బహుశా, [Accelerate](https://huggingface.co/docs/accelerate)).
-- మేము వీలైనన్ని ఎక్కువ వినియోగ సందర్భాలను ప్రదర్శించడానికి ప్రయత్నిస్తున్నప్పుడు, మా [ఉదాహరణల ఫోల్డర్](https://github.com/huggingface/transformers/tree/main/examples)లోని స్క్రిప్ట్లు కేవలం: ఉదాహరణలు. మీ నిర్దిష్ట సమస్యపై అవి పని చేయవు మరియు వాటిని మీ అవసరాలకు అనుగుణంగా మార్చుకోవడానికి మీరు కొన్ని కోడ్ లైన్లను మార్చవలసి ఉంటుంది.
## సంస్థాపన
@@ -290,7 +289,7 @@ Flax, PyTorch లేదా TensorFlow యొక్క ఇన్స్టా
🤗 ట్రాన్స్ఫార్మర్లు ప్రస్తుతం కింది ఆర్కిటెక్చర్లను అందజేస్తున్నాయి: వాటిలో ప్రతి ఒక్కటి ఉన్నత స్థాయి సారాంశం కోసం [ఇక్కడ](https://huggingface.co/docs/transformers/model_summary) చూడండి.
-ఈ అమలులు అనేక డేటాసెట్లలో పరీక్షించబడ్డాయి (ఉదాహరణ స్క్రిప్ట్లను చూడండి) మరియు అసలైన అమలుల పనితీరుతో సరిపోలాలి. మీరు [డాక్యుమెంటేషన్](https://github.com/huggingface/transformers/tree/main/examples) యొక్క ఉదాహరణల విభాగంలో పనితీరుపై మరిన్ని వివరాలను కనుగొనవచ్చు.
+ఈ అమలులు అనేక డేటాసెట్లలో పరీక్షించబడ్డాయి మరియు అసలైన అమలుల పనితీరుతో సరిపోలాలి.
## ఇంకా నేర్చుకో
@@ -300,7 +299,6 @@ Flax, PyTorch లేదా TensorFlow యొక్క ఇన్స్టా
| [టాస్క్ సారాంశం](https://huggingface.co/docs/transformers/task_summary) | 🤗 ట్రాన్స్ఫార్మర్ల ద్వారా సపోర్ట్ చేయబడిన విధులు |
| [ప్రీప్రాసెసింగ్ ట్యుటోరియల్](https://huggingface.co/docs/transformers/preprocessing) | మోడల్ల కోసం డేటాను సిద్ధం చేయడానికి `Tokenizer` క్లాస్ని ఉపయోగించడం |
| [ట్రైనింగ్ మరియు ఫైన్-ట్యూనింగ్](https://huggingface.co/docs/transformers/training) | PyTorch/TensorFlow ట్రైనింగ్ లూప్ మరియు `Trainer` APIలో 🤗 ట్రాన్స్ఫార్మర్లు అందించిన మోడల్లను ఉపయోగించడం |
-| [త్వరిత పర్యటన: ఫైన్-ట్యూనింగ్/యూసేజ్ స్క్రిప్ట్లు](https://github.com/huggingface/transformers/tree/main/examples) | విస్తృత శ్రేణి టాస్క్లపై ఫైన్-ట్యూనింగ్ మోడల్స్ కోసం ఉదాహరణ స్క్రిప్ట్లు |
| [మోడల్ భాగస్వామ్యం మరియు అప్లోడ్ చేయడం](https://huggingface.co/docs/transformers/model_sharing) | కమ్యూనిటీతో మీ ఫైన్-ట్యూన్డ్ మోడల్లను అప్లోడ్ చేయండి మరియు భాగస్వామ్యం చేయండి |
## అనులేఖనం
diff --git a/i18n/README_tr.md b/i18n/README_tr.md
index ab90083df76a..e61ad900fb6f 100644
--- a/i18n/README_tr.md
+++ b/i18n/README_tr.md
@@ -240,7 +240,6 @@ pipeline(
- Bu kütüphane, sinir ağları için yapı taşlarından oluşan modüler bir araç kutusu değildir. Model dosyalarındaki kod, araştırmacıların ek soyutlamalara/dosyalara dalmadan her bir model üzerinde hızlıca yineleme yapabilmesi için kasıtlı olarak ek soyutlamalarla yeniden düzenlenmemiştir.
- Eğitim API'si, Transformers tarafından sağlanan PyTorch modelleriyle çalışmak üzere optimize edilmiştir. Genel amaçlı makine öğrenimi döngüleri için [Accelerate](https://huggingface.co/docs/accelerate) gibi başka bir kütüphane kullanmalısınız.
-- [Örnek kodlar](https://github.com/huggingface/transformers/tree/main/examples) yalnızca *örnektir*. Sizin özel kullanım durumunuzda doğrudan çalışmayabilir ve çalışması için kodu uyarlamanız gerekebilir.
## Transformers kullanan 100 proje
diff --git a/i18n/README_ur.md b/i18n/README_ur.md
index 2e7e8919f61a..3c8aad97eb2a 100644
--- a/i18n/README_ur.md
+++ b/i18n/README_ur.md
@@ -258,7 +258,6 @@ limitations under the License.
- یہ لائبریری نیورل نیٹس کے لیے بلڈنگ بلاکس کا ماڈیولر ٹول باکس نہیں ہے۔ ماڈل فائلز میں موجود کوڈ جان بوجھ کر اضافی ایبسٹریکشنز کے ساتھ دوبارہ ترتیب نہیں دیا گیا ہے، تاکہ محققین بغیر اضافی ایبسٹریکشنز/فائلوں میں گئے ہوئے جلدی سے ہر ماڈل پر کام کر سکیں۔
- تربیتی API کا مقصد کسی بھی ماڈل پر کام کرنے کے لیے نہیں ہے بلکہ یہ لائبریری کے فراہم کردہ ماڈلز کے ساتھ کام کرنے کے لیے بہتر بنایا گیا ہے۔ عام مشین لرننگ لوپس کے لیے، آپ کو دوسری لائبریری (ممکنہ طور پر [Accelerate](https://huggingface.co/docs/accelerate)) استعمال کرنی چاہیے۔
-- حالانکہ ہم جتنا ممکن ہو زیادہ سے زیادہ استعمال کے کیسز پیش کرنے کی کوشش کرتے ہیں، ہمارے [مثالوں کے فولڈر](https://github.com/huggingface/transformers/tree/main/examples) میں موجود اسکرپٹس صرف یہی ہیں: مثالیں۔ یہ توقع کی جاتی ہے کہ یہ آپ کے مخصوص مسئلے پر فوراً کام نہیں کریں گی اور آپ کو اپنی ضروریات کے مطابق کوڈ کی کچھ لائنیں تبدیل کرنی پڑیں گی۔
### انسٹالیشن
@@ -305,7 +304,7 @@ Flax، PyTorch، یا TensorFlow کو conda کے ساتھ انسٹال کرنے
یہ چیک کرنے کے لیے کہ ہر ماڈل کی Flax، PyTorch یا TensorFlow میں کوئی عملداری ہے یا 🤗 Tokenizers لائبریری کے ذریعہ سپورٹ کردہ ٹوکنائزر کے ساتھ ہے، [اس جدول](https://huggingface.co/docs/transformers/index#supported-frameworks) کا حوالہ لیں۔
-یہ عملداری مختلف ڈیٹا سیٹس پر ٹیسٹ کی گئی ہیں (مثال کے اسکرپٹس دیکھیں) اور اصل عملداری کی کارکردگی کے ہم آہنگ ہونی چاہئیں۔ آپ کو کارکردگی کی مزید تفصیلات [دستاویزات](https://github.com/huggingface/transformers/tree/main/examples) کے مثالوں کے سیکشن میں مل سکتی ہیں۔
+یہ عملداری مختلف ڈیٹا سیٹس پر ٹیسٹ کی گئی ہیں اور اصل عملداری کی کارکردگی کے ہم آہنگ ہونی چاہئیں۔
## مزید معلومات حاصل کریں
@@ -316,7 +315,6 @@ Flax، PyTorch، یا TensorFlow کو conda کے ساتھ انسٹال کرنے
| [ٹاسک کا خلاصہ](https://huggingface.co/docs/transformers/task_summary) | 🤗 Transformers کے ذریعہ سپورٹ کردہ ٹاسک |
| [پری پروسیسنگ ٹیوٹوریل](https://huggingface.co/docs/transformers/preprocessing) | ماڈلز کے لیے ڈیٹا تیار کرنے کے لیے `Tokenizer` کلاس کا استعمال |
| [ٹریننگ اور فائن ٹیوننگ](https://huggingface.co/docs/transformers/training) | PyTorch/TensorFlow ٹریننگ لوپ میں 🤗 Transformers کی طرف سے فراہم کردہ ماڈلز کا استعمال اور `Trainer` API |
-| [تیز دورہ: فائن ٹیوننگ/استعمال کے اسکرپٹس](https://github.com/huggingface/transformers/tree/main/examples) | مختلف قسم کے ٹاسک پر ماڈلز کو فائن ٹیون کرنے کے لیے مثال کے اسکرپٹس |
| [ماڈل کا اشتراک اور اپ لوڈ کرنا](https://huggingface.co/docs/transformers/model_sharing) | اپنی فائن ٹیون کردہ ماڈلز کو کمیونٹی کے ساتھ اپ لوڈ اور شیئر کریں |
## استشہاد
diff --git a/i18n/README_vi.md b/i18n/README_vi.md
index 5922cd03a893..323a51cff3fa 100644
--- a/i18n/README_vi.md
+++ b/i18n/README_vi.md
@@ -244,7 +244,6 @@ Chính mô hình là một [Pytorch `nn.Module`](https://pytorch.org/docs/stable
- Thư viện này không phải là một bộ công cụ modul cho các khối xây dựng mạng neural. Mã trong các tệp mô hình không được tái cấu trúc với các trừu tượng bổ sung một cách cố ý, để các nhà nghiên cứu có thể lặp nhanh trên từng mô hình mà không cần đào sâu vào các trừu tượng/tệp bổ sung.
- API huấn luyện không được thiết kế để hoạt động trên bất kỳ mô hình nào, mà được tối ưu hóa để hoạt động với các mô hình được cung cấp bởi thư viện. Đối với vòng lặp học máy chung, bạn nên sử dụng một thư viện khác (có thể là [Accelerate](https://huggingface.co/docs/accelerate)).
-- Mặc dù chúng tôi cố gắng trình bày càng nhiều trường hợp sử dụng càng tốt, nhưng các tập lệnh trong thư mục [examples](https://github.com/huggingface/transformers/tree/main/examples) chỉ là ví dụ. Dự kiến rằng chúng sẽ không hoạt động ngay tức khắc trên vấn đề cụ thể của bạn và bạn sẽ phải thay đổi một số dòng mã để thích nghi với nhu cầu của bạn.
## Cài đặt
@@ -291,7 +290,7 @@ Số lượng điểm kiểm tra hiện tại: .
-Những phiên bản này đã được kiểm tra trên một số tập dữ liệu (xem các tập lệnh ví dụ) và nên tương đương với hiệu suất của các phiên bản gốc. Bạn có thể tìm thấy thêm thông tin về hiệu suất trong phần Ví dụ của [tài liệu](https://github.com/huggingface/transformers/tree/main/examples).
+Những phiên bản này đã được kiểm tra trên một số tập dữ liệu và nên tương đương với hiệu suất của các phiên bản gốc.
## Tìm hiểu thêm
@@ -302,7 +301,6 @@ Những phiên bản này đã được kiểm tra trên một số tập dữ l
| [Tóm tắt nhiệm vụ](https://huggingface.co/docs/transformers/task_summary) | Các nhiệm vụ được hỗ trợ bởi 🤗 Transformers |
| [Hướng dẫn tiền xử lý](https://huggingface.co/docs/transformers/preprocessing) | Sử dụng lớp `Tokenizer` để chuẩn bị dữ liệu cho các mô hình |
| [Huấn luyện và điều chỉnh](https://huggingface.co/docs/transformers/training) | Sử dụng các mô hình được cung cấp bởi 🤗 Transformers trong vòng lặp huấn luyện PyTorch/TensorFlow và API `Trainer` |
-| [Hướng dẫn nhanh: Điều chỉnh/sử dụng các kịch bản](https://github.com/huggingface/transformers/tree/main/examples) | Các kịch bản ví dụ để điều chỉnh mô hình trên nhiều nhiệm vụ khác nhau |
| [Chia sẻ và tải lên mô hình](https://huggingface.co/docs/transformers/model_sharing) | Tải lên và chia sẻ các mô hình đã điều chỉnh của bạn với cộng đồng |
## Trích dẫn
diff --git a/i18n/README_zh-hans.md b/i18n/README_zh-hans.md
index 23ec83969f9a..eefdd7f2cb71 100644
--- a/i18n/README_zh-hans.md
+++ b/i18n/README_zh-hans.md
@@ -265,7 +265,6 @@ pipeline(
- 该库不是一个可自由拼搭的神经网络模块化工具箱。模型文件中的代码刻意减少额外抽象,以便研究者能快速在各个模型上迭代,而无需深入更多抽象或文件跳转。
- 训练 API 优化用于 Transformers 提供的 PyTorch 模型。若需要通用的机器学习训练循环,请使用其它库,如 [Accelerate](https://huggingface.co/docs/accelerate)。
-- [示例脚本](https://github.com/huggingface/transformers/tree/main/examples)只是「示例」。它们不一定能直接适配你的具体用例,需要你进行必要的改动。
## 100 个使用 Transformers 的项目
diff --git a/i18n/README_zh-hant.md b/i18n/README_zh-hant.md
index b49617baf457..b13ee2a6c784 100644
--- a/i18n/README_zh-hant.md
+++ b/i18n/README_zh-hant.md
@@ -240,7 +240,6 @@ pipeline(
- 本函式庫並非一個用於建構神經網路的模組化工具箱。模型檔案中的程式碼為了讓研究人員能快速在模型上迭代,而沒有進行過度的抽象重構,避免了深入額外的抽象層/檔案。
- 訓練 API 針對 Transformers 提供的 PyTorch 模型進行了最佳化。對於通用的機器學習迴圈,您應該使用像 [Accelerate](https://huggingface.co/docs/accelerate) 這樣的其他函式庫。
-- [範例指令稿](https://github.com/huggingface/transformers/tree/main/examples)僅僅是*範例*。它們不一定能在您的特定用例上開箱即用,您可能需要修改程式碼才能使其正常運作。
## 100個使用 Transformers 的專案
diff --git a/setup.py b/setup.py
index fc56c13653af..d5d80e920519 100644
--- a/setup.py
+++ b/setup.py
@@ -79,8 +79,6 @@
"datasets>=2.15.0", # We need either this pin or pyarrow<21.0.0
"deepspeed>=0.9.3",
"diffusers==0.35.2", # Needed for VibeVoice TTS integration tests
- "dill<0.3.5",
- "evaluate>=0.4.6",
"faiss-cpu",
"fastapi",
"filelock",
@@ -121,16 +119,11 @@
"regex>=2025.10.22",
"rhoknp>=1.1.0,<1.3.1",
"rjieba",
- "rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1",
"ruff==0.14.10",
# When bumping `transformers-mlinter`, sync repo-local rule overrides from
# `utils/rules.toml` back into the released package.
"transformers-mlinter==0.1.5",
"ty==0.0.20",
- # `sacrebleu` not used in `transformers`. However, it is needed in several tests, when a test calls
- # `evaluate.load("sacrebleu")`. This metric is used in the examples that we use to test the `Trainer` with, in the
- # `Trainer` tests (see references to `run_translation.py`).
- "sacrebleu>=1.4.12,<2.0.0",
"sacremoses",
"safetensors>=0.8.0",
"sagemaker>=2.31.0",
@@ -222,16 +215,12 @@ def deps_list(*pkgs):
"timeout-decorator",
"parameterized",
"psutil",
- "dill",
"diffusers", # Needed for VibeVoice TTS integration tests
- "evaluate",
- "rouge-score",
"nltk",
"sacremoses",
"rjieba",
"beautifulsoup4",
"tensorboard",
- "sacrebleu", # needed in trainer tests, see references to `run_translation.py`
"filelock", # filesystem locks, e.g., to prevent parallel downloads
)
+ extras["docs"]
diff --git a/src/transformers/dependency_versions_table.py b/src/transformers/dependency_versions_table.py
index 91429504eac2..0ed9d02e2fcc 100644
--- a/src/transformers/dependency_versions_table.py
+++ b/src/transformers/dependency_versions_table.py
@@ -11,8 +11,6 @@
"datasets": "datasets>=2.15.0",
"deepspeed": "deepspeed>=0.9.3",
"diffusers": "diffusers==0.35.2",
- "dill": "dill<0.3.5",
- "evaluate": "evaluate>=0.4.6",
"faiss-cpu": "faiss-cpu",
"fastapi": "fastapi",
"filelock": "filelock",
@@ -53,11 +51,9 @@
"regex": "regex>=2025.10.22",
"rhoknp": "rhoknp>=1.1.0,<1.3.1",
"rjieba": "rjieba",
- "rouge-score": "rouge-score!=0.0.7,!=0.0.8,!=0.1,!=0.1.1",
"ruff": "ruff==0.14.10",
"transformers-mlinter": "transformers-mlinter==0.1.5",
"ty": "ty==0.0.20",
- "sacrebleu": "sacrebleu>=1.4.12,<2.0.0",
"sacremoses": "sacremoses",
"safetensors": "safetensors>=0.8.0",
"sagemaker": "sagemaker>=2.31.0",
diff --git a/src/transformers/models/deit/modeling_deit.py b/src/transformers/models/deit/modeling_deit.py
index 3bc5cd69e5cb..aa6a586eb08a 100644
--- a/src/transformers/models/deit/modeling_deit.py
+++ b/src/transformers/models/deit/modeling_deit.py
@@ -402,13 +402,6 @@ def forward(
@auto_docstring(
custom_intro="""
DeiT Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class DeiTForMaskedImageModeling(DeiTPreTrainedModel):
diff --git a/src/transformers/models/focalnet/modeling_focalnet.py b/src/transformers/models/focalnet/modeling_focalnet.py
index 27038f206f8c..edd9d4377f35 100644
--- a/src/transformers/models/focalnet/modeling_focalnet.py
+++ b/src/transformers/models/focalnet/modeling_focalnet.py
@@ -670,13 +670,6 @@ def forward(
FocalNet Model with a decoder on top for masked image modeling.
This follows the same implementation as in [SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class FocalNetForMaskedImageModeling(FocalNetPreTrainedModel):
diff --git a/src/transformers/models/hiera/modeling_hiera.py b/src/transformers/models/hiera/modeling_hiera.py
index 7ebc67dbccba..d588f5c5770e 100644
--- a/src/transformers/models/hiera/modeling_hiera.py
+++ b/src/transformers/models/hiera/modeling_hiera.py
@@ -1058,13 +1058,6 @@ def forward(self, feature_maps: list[torch.Tensor]) -> torch.Tensor:
@auto_docstring(
custom_intro="""
The Hiera Model transformer with the decoder on top for self-supervised pre-training.
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class HieraForPreTraining(HieraPreTrainedModel):
diff --git a/src/transformers/models/swin/modeling_swin.py b/src/transformers/models/swin/modeling_swin.py
index 14525c194830..ab51ec1b5986 100644
--- a/src/transformers/models/swin/modeling_swin.py
+++ b/src/transformers/models/swin/modeling_swin.py
@@ -892,13 +892,6 @@ def forward(
@auto_docstring(
custom_intro="""
Swin Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class SwinForMaskedImageModeling(SwinPreTrainedModel):
diff --git a/src/transformers/models/swin/modular_swin.py b/src/transformers/models/swin/modular_swin.py
index 3d077ee501ca..8a0d9330bbd4 100644
--- a/src/transformers/models/swin/modular_swin.py
+++ b/src/transformers/models/swin/modular_swin.py
@@ -851,13 +851,6 @@ def forward(
@auto_docstring(
custom_intro="""
Swin Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class SwinForMaskedImageModeling(SwinPreTrainedModel):
diff --git a/src/transformers/models/swinv2/modeling_swinv2.py b/src/transformers/models/swinv2/modeling_swinv2.py
index 472bcc6ded6f..315b28b28740 100644
--- a/src/transformers/models/swinv2/modeling_swinv2.py
+++ b/src/transformers/models/swinv2/modeling_swinv2.py
@@ -975,13 +975,6 @@ def forward(
custom_intro="""
Swinv2 Model with a decoder on top for masked image modeling, as proposed in
[SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
# Todo - Refactor as part of vision refactor. Copied from transformers.models.swin.modeling_swin.SwinForMaskedImageModeling with swin->swinv2, base-simmim-window6-192->tiny-patch4-window8-256,SWIN->SWINV2,Swin->Swinv2,192->256
diff --git a/src/transformers/models/timm_wrapper/image_processing_timm_wrapper.py b/src/transformers/models/timm_wrapper/image_processing_timm_wrapper.py
index 05c0694026ab..20119d85ec2b 100644
--- a/src/transformers/models/timm_wrapper/image_processing_timm_wrapper.py
+++ b/src/transformers/models/timm_wrapper/image_processing_timm_wrapper.py
@@ -61,7 +61,7 @@ def __init__(
self.data_config = timm.data.resolve_data_config(pretrained_cfg, model=None, verbose=False)
self.val_transforms = timm.data.create_transform(**self.data_config, is_training=False)
- # useful for training, see examples/pytorch/image-classification/run_image_classification.py
+ # useful for training
self.train_transforms = timm.data.create_transform(**self.data_config, is_training=True)
# If `ToTensor` is in the transforms, then the input should be numpy array or PIL image.
diff --git a/src/transformers/models/vit/modeling_vit.py b/src/transformers/models/vit/modeling_vit.py
index 1587fdb1d655..4ce496436d3b 100644
--- a/src/transformers/models/vit/modeling_vit.py
+++ b/src/transformers/models/vit/modeling_vit.py
@@ -391,13 +391,6 @@ def forward(
@auto_docstring(
custom_intro="""
ViT Model with a decoder on top for masked image modeling, as proposed in [SimMIM](https://huggingface.co/papers/2111.09886).
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class ViTForMaskedImageModeling(ViTPreTrainedModel):
diff --git a/src/transformers/models/vit_mae/modeling_vit_mae.py b/src/transformers/models/vit_mae/modeling_vit_mae.py
index a248efd63ca0..d652c0a5ec4c 100755
--- a/src/transformers/models/vit_mae/modeling_vit_mae.py
+++ b/src/transformers/models/vit_mae/modeling_vit_mae.py
@@ -686,13 +686,6 @@ def forward(
@auto_docstring(
custom_intro="""
The ViTMAE Model transformer with the decoder on top for self-supervised pre-training.
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class ViTMAEForPreTraining(ViTMAEPreTrainedModel):
diff --git a/src/transformers/models/vit_mae/modular_vit_mae.py b/src/transformers/models/vit_mae/modular_vit_mae.py
index 28859be4bc94..9ebf4c227083 100644
--- a/src/transformers/models/vit_mae/modular_vit_mae.py
+++ b/src/transformers/models/vit_mae/modular_vit_mae.py
@@ -493,13 +493,6 @@ def forward(
@auto_docstring(
custom_intro="""
The ViTMAE Model transformer with the decoder on top for self-supervised pre-training.
-
-
-
- Note that we provide a script to pre-train this model on custom data in our [examples
- directory](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
-
-
"""
)
class ViTMAEForPreTraining(ViTMAEPreTrainedModel):
diff --git a/src/transformers/testing_utils.py b/src/transformers/testing_utils.py
index e1766a8b2d75..8a612199a217 100644
--- a/src/transformers/testing_utils.py
+++ b/src/transformers/testing_utils.py
@@ -2588,7 +2588,7 @@ def mockenv_context(*remove, **update):
# --- pytest conf functions --- #
-# to avoid multiple invocation from tests/conftest.py and examples/conftest.py - make sure it's called only once
+# to avoid multiple invocation if several conftest.py files call it - make sure it's called only once
pytest_opt_registered = {}
diff --git a/src/transformers/training_args.py b/src/transformers/training_args.py
index 30c836773cc0..6d4596e01793 100644
--- a/src/transformers/training_args.py
+++ b/src/transformers/training_args.py
@@ -738,21 +738,17 @@ class TrainingArguments:
do_train (`bool`, *optional*, defaults to `False`):
Whether to run training or not. This argument is not directly used by [`Trainer`], it's intended to be used
- by your training/evaluation scripts instead. See the [example
- scripts](https://github.com/huggingface/transformers/tree/main/examples) for more details.
+ by your training/evaluation scripts instead.
do_eval (`bool`, *optional*):
Whether to run evaluation on the validation set or not. Will be set to `True` if `eval_strategy` is
different from `"no"`. This argument is not directly used by [`Trainer`], it's intended to be used by your
- training/evaluation scripts instead. See the [example
- scripts](https://github.com/huggingface/transformers/tree/main/examples) for more details.
+ training/evaluation scripts instead.
do_predict (`bool`, *optional*, defaults to `False`):
Whether to run predictions on the test set or not. This argument is not directly used by [`Trainer`], it's
- intended to be used by your training/evaluation scripts instead. See the [example
- scripts](https://github.com/huggingface/transformers/tree/main/examples) for more details.
+ intended to be used by your training/evaluation scripts instead.
resume_from_checkpoint (`str`, *optional*):
The path to a folder with a valid checkpoint for your model. This argument is not directly used by
- [`Trainer`], it's intended to be used by your training/evaluation scripts instead. See the [example
- scripts](https://github.com/huggingface/transformers/tree/main/examples) for more details.
+ [`Trainer`], it's intended to be used by your training/evaluation scripts instead.
"""
# Fields that accept dict values via CLI as JSON strings (e.g., '{"key": "value"}').
diff --git a/tests/fixtures/tests_samples/MRPC/dev.csv b/tests/fixtures/tests_samples/MRPC/dev.csv
deleted file mode 100644
index 96beccda96d7..000000000000
--- a/tests/fixtures/tests_samples/MRPC/dev.csv
+++ /dev/null
@@ -1,7 +0,0 @@
-label,sentence1,sentence2
-equivalent,He said the foodservice pie business doesn 't fit the company 's long-term growth strategy .,""" The foodservice pie business does not fit our long-term growth strategy ."
-not_equivalent,Magnarelli said Racicot hated the Iraqi regime and looked forward to using his long years of training in the war .,"His wife said he was "" 100 percent behind George Bush "" and looked forward to using his years of training in the war ."
-not_equivalent,"The dollar was at 116.92 yen against the yen , flat on the session , and at 1.2891 against the Swiss franc , also flat .","The dollar was at 116.78 yen JPY = , virtually flat on the session , and at 1.2871 against the Swiss franc CHF = , down 0.1 percent ."
-equivalent,The AFL-CIO is waiting until October to decide if it will endorse a candidate .,The AFL-CIO announced Wednesday that it will decide in October whether to endorse a candidate before the primaries .
-not_equivalent,No dates have been set for the civil or the criminal trial .,"No dates have been set for the criminal or civil cases , but Shanley has pleaded not guilty ."
-equivalent,Wal-Mart said it would check all of its million-plus domestic workers to ensure they were legally employed .,It has also said it would review all of its domestic employees more than 1 million to ensure they have legal status .
diff --git a/tests/fixtures/tests_samples/MRPC/dev.tsv b/tests/fixtures/tests_samples/MRPC/dev.tsv
deleted file mode 100644
index 5b814856c63f..000000000000
--- a/tests/fixtures/tests_samples/MRPC/dev.tsv
+++ /dev/null
@@ -1,7 +0,0 @@
-Quality #1 ID #2 ID #1 String #2 String
-1 1355540 1355592 He said the foodservice pie business doesn 't fit the company 's long-term growth strategy . " The foodservice pie business does not fit our long-term growth strategy .
-0 2029631 2029565 Magnarelli said Racicot hated the Iraqi regime and looked forward to using his long years of training in the war . His wife said he was " 100 percent behind George Bush " and looked forward to using his years of training in the war .
-0 487993 487952 The dollar was at 116.92 yen against the yen , flat on the session , and at 1.2891 against the Swiss franc , also flat . The dollar was at 116.78 yen JPY = , virtually flat on the session , and at 1.2871 against the Swiss franc CHF = , down 0.1 percent .
-1 1989515 1989458 The AFL-CIO is waiting until October to decide if it will endorse a candidate . The AFL-CIO announced Wednesday that it will decide in October whether to endorse a candidate before the primaries .
-0 1783137 1782659 No dates have been set for the civil or the criminal trial . No dates have been set for the criminal or civil cases , but Shanley has pleaded not guilty .
-1 3039165 3039036 Wal-Mart said it would check all of its million-plus domestic workers to ensure they were legally employed . It has also said it would review all of its domestic employees more than 1 million to ensure they have legal status .
diff --git a/tests/fixtures/tests_samples/MRPC/train.csv b/tests/fixtures/tests_samples/MRPC/train.csv
deleted file mode 100644
index 96beccda96d7..000000000000
--- a/tests/fixtures/tests_samples/MRPC/train.csv
+++ /dev/null
@@ -1,7 +0,0 @@
-label,sentence1,sentence2
-equivalent,He said the foodservice pie business doesn 't fit the company 's long-term growth strategy .,""" The foodservice pie business does not fit our long-term growth strategy ."
-not_equivalent,Magnarelli said Racicot hated the Iraqi regime and looked forward to using his long years of training in the war .,"His wife said he was "" 100 percent behind George Bush "" and looked forward to using his years of training in the war ."
-not_equivalent,"The dollar was at 116.92 yen against the yen , flat on the session , and at 1.2891 against the Swiss franc , also flat .","The dollar was at 116.78 yen JPY = , virtually flat on the session , and at 1.2871 against the Swiss franc CHF = , down 0.1 percent ."
-equivalent,The AFL-CIO is waiting until October to decide if it will endorse a candidate .,The AFL-CIO announced Wednesday that it will decide in October whether to endorse a candidate before the primaries .
-not_equivalent,No dates have been set for the civil or the criminal trial .,"No dates have been set for the criminal or civil cases , but Shanley has pleaded not guilty ."
-equivalent,Wal-Mart said it would check all of its million-plus domestic workers to ensure they were legally employed .,It has also said it would review all of its domestic employees more than 1 million to ensure they have legal status .
diff --git a/tests/fixtures/tests_samples/MRPC/train.tsv b/tests/fixtures/tests_samples/MRPC/train.tsv
deleted file mode 100644
index 5b814856c63f..000000000000
--- a/tests/fixtures/tests_samples/MRPC/train.tsv
+++ /dev/null
@@ -1,7 +0,0 @@
-Quality #1 ID #2 ID #1 String #2 String
-1 1355540 1355592 He said the foodservice pie business doesn 't fit the company 's long-term growth strategy . " The foodservice pie business does not fit our long-term growth strategy .
-0 2029631 2029565 Magnarelli said Racicot hated the Iraqi regime and looked forward to using his long years of training in the war . His wife said he was " 100 percent behind George Bush " and looked forward to using his years of training in the war .
-0 487993 487952 The dollar was at 116.92 yen against the yen , flat on the session , and at 1.2891 against the Swiss franc , also flat . The dollar was at 116.78 yen JPY = , virtually flat on the session , and at 1.2871 against the Swiss franc CHF = , down 0.1 percent .
-1 1989515 1989458 The AFL-CIO is waiting until October to decide if it will endorse a candidate . The AFL-CIO announced Wednesday that it will decide in October whether to endorse a candidate before the primaries .
-0 1783137 1782659 No dates have been set for the civil or the criminal trial . No dates have been set for the criminal or civil cases , but Shanley has pleaded not guilty .
-1 3039165 3039036 Wal-Mart said it would check all of its million-plus domestic workers to ensure they were legally employed . It has also said it would review all of its domestic employees more than 1 million to ensure they have legal status .
diff --git a/tests/fixtures/tests_samples/conll/sample.json b/tests/fixtures/tests_samples/conll/sample.json
deleted file mode 100644
index 0bc42a92fe8c..000000000000
--- a/tests/fixtures/tests_samples/conll/sample.json
+++ /dev/null
@@ -1,10 +0,0 @@
-{"words": ["He", "was", "the", "27th", "pitcher", "used", "by", "the", "Angels", "this", "season", ",", "tying", "a", "major-league", "record", "."], "ner": ["O", "O", "O", "O", "O", "O", "O", "O", "B-ORG", "O", "O", "O", "O", "O", "O", "O", "O"]}
-{"words": ["CHICAGO", "AT", "ATLANTA"], "ner": ["B-ORG", "O", "B-LOC"]}
-{"words": ["President", "Bill", "Clinton", "earlier", "this", "month", "invoked", "special", "powers", "to", "appoint", "Fowler", "during", "the", "congressional", "recess", "because", "the", "Senate", "delayed", "confirming", "his", "nomination", "."], "ner": ["O", "B-PER", "I-PER", "O", "O", "O", "O", "O", "O", "O", "O", "B-PER", "O", "O", "O", "O", "O", "O", "B-ORG", "O", "O", "O", "O", "O"]}
-{"words": ["goals", "for", ",", "goals", "against", ",", "points", ")", "."], "ner": ["O", "O", "O", "O", "O", "O", "O", "O", "O"]}
-{"words": ["\"", "It", "is", "one", "step", "short", "of", "an", "emergency", "situation", ",", "\"", "a", "police", "spokesman", "said", "via", "telephone", "from", "a", "command", "post", "in", "the", "bush", "."], "ner": ["O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O"]}
-{"words": ["U.S.", "Ambassador", "Myles", "Frechette", "applauded", "the", "move", ",", "saying", "it", "could", "prompt", "the", "Clinton", "administration", "to", "remove", "Colombia", "from", "a", "list", "of", "outcast", "nations", "that", "have", "failed", "to", "cooperate", "in", "U.S.", "counternarcotics", "efforts", "."], "ner": ["B-LOC", "O", "B-PER", "I-PER", "O", "O", "O", "O", "O", "O", "O", "O", "O", "B-PER", "O", "O", "O", "B-LOC", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "B-LOC", "O", "O", "O"]}
-{"words": ["Halftime"], "ner": ["O"]}
-{"words": ["It", "has", "manufacturing", "plants", "in", "San", "Diego", ";", "Creedmoor", ",", "N.C.", ";", "Hampshire", ",", "England", ";", "and", "Tijuana", ",", "Mexico", ",", "and", "distributes", "its", "prodcuts", "in", "more", "than", "120", "countries", "."], "ner": ["O", "O", "O", "O", "O", "B-LOC", "I-LOC", "O", "B-LOC", "O", "B-LOC", "O", "B-LOC", "O", "B-LOC", "O", "O", "B-LOC", "O", "B-LOC", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O"]}
-{"words": ["Scotland", "manager", "Craig", "Brown", "said", "on", "Thursday", ":", "\"", "I", "'ve", "watched", "Duncan", "Ferguson", "in", "action", "twice", "recently", "and", "he", "'s", "bang", "in", "form", "."], "ner": ["B-LOC", "O", "B-PER", "I-PER", "O", "O", "O", "O", "O", "O", "O", "O", "B-PER", "I-PER", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O"]}
-{"words": ["Clinton", "flew", "in", "by", "helicopter", "from", "Michigan", "City", ",", "Indiana", ",", "after", "ending", "a", "four-day", ",", "559-mile", "trip", "aboard", "a", "campaign", "train", "from", "Washington", "."], "ner": ["B-PER", "O", "O", "O", "O", "O", "B-LOC", "I-LOC", "O", "B-LOC", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "O", "B-LOC", "O"]}
\ No newline at end of file
diff --git a/tests/fixtures/tests_samples/swag/sample.json b/tests/fixtures/tests_samples/swag/sample.json
deleted file mode 100644
index d00ad8d184e3..000000000000
--- a/tests/fixtures/tests_samples/swag/sample.json
+++ /dev/null
@@ -1,10 +0,0 @@
-{"ending0": "passes by walking down the street playing their instruments.", "ending1": "has heard approaching them.", "ending2": "arrives and they're outside dancing and asleep.", "ending3": "turns the lead singer watches the performance.", "label": 0, "sent1": "Members of the procession walk down the street holding small horn brass instruments.", "sent2": "A drum line"}
-{"ending0": "are playing ping pong and celebrating one left each in quick.", "ending1": "wait slowly towards the cadets.", "ending2": "continues to play as well along the crowd along with the band being interviewed.", "ending3": "continue to play marching, interspersed.", "label": 3, "sent1": "A drum line passes by walking down the street playing their instruments.", "sent2": "Members of the procession"}
-{"ending0": "pay the other coaches to cheer as people this chatter dips in lawn sheets.", "ending1": "walk down the street holding small horn brass instruments.", "ending2": "is seen in the background.", "ending3": "are talking a couple of people playing a game of tug of war.", "label": 1, "sent1": "A group of members in green uniforms walks waving flags.", "sent2": "Members of the procession"}
-{"ending0": "are playing ping pong and celebrating one left each in quick.", "ending1": "wait slowly towards the cadets.", "ending2": "makes a square call and ends by jumping down into snowy streets where fans begin to take their positions.", "ending3": "play and go back and forth hitting the drums while the audience claps for them.", "label": 3, "sent1": "A drum line passes by walking down the street playing their instruments.", "sent2": "Members of the procession"}
-{"ending0": "finishes the song and lowers the instrument.", "ending1": "hits the saxophone and demonstrates how to properly use the racquet.", "ending2": "finishes massage the instrument again and continues.", "ending3": "continues dancing while the man gore the music outside while drums.", "label": 0, "sent1": "The person plays a song on the violin.", "sent2": "The man"}
-{"ending0": "finishes playing then marches their tenderly.", "ending1": "walks in frame and rubs on his hands, and then walks into a room.", "ending2": "continues playing guitar while moving from the camera.", "ending3": "plays a song on the violin.", "label": 3, "sent1": "The person holds up the violin to his chin and gets ready.", "sent2": "The person"}
-{"ending0": "examines the instrument in his hand.", "ending1": "stops playing the drums and waves over the other boys.", "ending2": "lights the cigarette and sticks his head in.", "ending3": "drags off the vacuum.", "label": 0, "sent1": "A person retrieves an instrument from a closet.", "sent2": "The man"}
-{"ending0": "studies a picture of the man playing the violin.", "ending1": "holds up the violin to his chin and gets ready.", "ending2": "stops to speak to the camera again.", "ending3": "puts his arm around the man and backs away.", "label": 1, "sent1": "The man examines the instrument in his hand.", "sent2": "The person"}
-{"ending0": "hands her another phone.", "ending1": "takes the drink, then holds it.", "ending2": "looks off then looks at someone.", "ending3": "stares blearily down at the floor.", "label": 3, "sent1": "Someone walks over to the radio.", "sent2": "Someone"}
-{"ending0": "looks off then looks at someone.", "ending1": "hands her another phone.", "ending2": "takes the drink, then holds it.", "ending3": "turns on a monitor.", "label": 3, "sent1": "Someone walks over to the radio.", "sent2": "Someone"}
diff --git a/tests/fixtures/tests_samples/wmt16/sample.json b/tests/fixtures/tests_samples/wmt16/sample.json
deleted file mode 100644
index 8c0e47b0648a..000000000000
--- a/tests/fixtures/tests_samples/wmt16/sample.json
+++ /dev/null
@@ -1,10 +0,0 @@
-{"translation": {"en": "Membership of Parliament: see Minutes", "ro": "Componenţa Parlamentului: a se vedea procesul-verbal"}}
-{"translation": {"en": "Approval of Minutes of previous sitting: see Minutes", "ro": "Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal"}}
-{"translation": {"en": "Membership of Parliament: see Minutes", "ro": "Componenţa Parlamentului: a se vedea procesul-verbal"}}
-{"translation": {"en": "Verification of credentials: see Minutes", "ro": "Verificarea prerogativelor: a se vedea procesul-verbal"}}
-{"translation": {"en": "Documents received: see Minutes", "ro": "Depunere de documente: a se vedea procesul-verbal"}}
-{"translation": {"en": "Written statements and oral questions (tabling): see Minutes", "ro": "Declaraţii scrise şi întrebări orale (depunere): consultaţi procesul-verbal"}}
-{"translation": {"en": "Petitions: see Minutes", "ro": "Petiţii: a se vedea procesul-verbal"}}
-{"translation": {"en": "Texts of agreements forwarded by the Council: see Minutes", "ro": "Transmiterea de către Consiliu a textelor acordurilor: a se vedea procesul-verbal"}}
-{"translation": {"en": "Action taken on Parliament's resolutions: see Minutes", "ro": "Cursul dat rezoluţiilor Parlamentului: a se vedea procesul-verbal"}}
-{"translation": {"en": "Agenda for next sitting: see Minutes", "ro": "Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal"}}
diff --git a/tests/fixtures/tests_samples/wmt_en_ro/test.json b/tests/fixtures/tests_samples/wmt_en_ro/test.json
deleted file mode 100644
index 2841b1b6aab9..000000000000
--- a/tests/fixtures/tests_samples/wmt_en_ro/test.json
+++ /dev/null
@@ -1,20 +0,0 @@
-{ "translation": { "en": "UN Chief Says There Is No Military Solution in Syria Secretary-General Ban Ki-moon says his response to Russia's stepped up military support for Syria is that \"there is no military solution\" to the nearly five-year conflict and more weapons will only worsen the violence and misery for millions of people. The U.N. chief again urged all parties, including the divided U.N. Security Council, to unite and support inclusive negotiations to find a political solution. Ban told a news conference Wednesday that he plans to meet with foreign ministers of the five permanent council nations - the U.S., Russia, China, Britain and France - on the sidelines of the General Assembly's ministerial session later this month to discuss Syria.", "ro": "Șeful ONU declară că nu există soluții militare în Siria Secretarul General Ban Ki-moon afirmă că răspunsul său la suportul militar al Rusiei pentru Siria este că „nu există o soluție militară” la conflictul care durează de aproape cinci ani iar mai multe arme nu ar face decât să agraveze violența și suferința a milioane de oameni. Șeful ONU a solicitat din nou tuturor părților, inclusiv Consiliului de securitate ONU divizat să se unifice și să susțină negocierile pentru a găsi o soluție politică. Ban a declarat miercuri în cadrul unei conferințe că intenționează să se întâlnească luna aceasta cu miniștrii de externe din cinci țări permanent prezente în consiliu - SUA, Rusia, China, Anglia și Franța - pe marginea sesiunii ministeriale a Adunării Generale pentru a discuta despre Siria." } }
-{ "translation": { "en": "He expressed regret that divisions in the council and among the Syrian people and regional powers \"made this situation unsolvable.\" Ban urged the five permanent members to show the solidarity and unity they did in achieving an Iran nuclear deal in addressing the Syria crisis. 8 Poll Numbers That Show Donald Trump Is For Real Some have tried to label him a flip-flopper. Others have dismissed him as a joke. And some are holding out for an implosion. But no matter how some Republicans are trying to drag Donald Trump down from atop the polls, it hasn't worked (yet).", "ro": "Ban și-a exprimat regretul că divizările în consiliu și între poporul sirian și puterile regionale „au făcut această situație de nerezolvat”. Ban le-a cerut celor cinci membri permanenți să dea dovadă de solidaritatea și unitatea arătate atunci când au reușit să încheie un acord referitor la armele nucleare ale Iranului, abordând astfel criza din Siria. 8 cifre din sondaje care arată că Donald Trump are șanse reale Unii au încercat să îl eticheteze ca politician „flip-flop”. Alții l-au numit o glumă. Iar alții așteaptă implozia. Însă indiferent de modul în care unii republicani încearcă să îl dărâme pe Donald Trump din vârful sondajelor, nu a funcționat (încă)." } }
-{ "translation": { "en": "Ten of the last 11 national polls have shown Donald Trump's lead at double digits, and some are starting to ask seriously what it means for the real estate mogul's nomination chances. Of course, it's still early in the election cycle. None of this is to say that Trump is likely to win the Republican nomination. Pundits point out that at this time in 2011, Rick Perry's lead was giving way to a rising Herman Cain, neither of whom won even one state in the nomination process. And there are many reasons he would struggle in a general election. But outside groups like Jeb Bush's Super PAC and the economic conservative group Club for Growth are recognizing Trump's staying power and beginning to unload their dollars to topple him.", "ro": "Zece din ultimele 11 sondaje naționale au arătat că Donald Trump conduce cu un procent din două cifre iar unele voci încep să se întrebe serios ce înseamnă acest lucru pentru șansele de numire ale mogulului imobiliar. Desigur, este încă prematur. Nimic din toate acestea nu spune că Trump va câștiga cursa pentru nominalizarea republicanilor. Pundits arată că, în aceeași perioadă a anului 2011, avansul lui Rick Perry îi făcea loc lui Herman Cain în sondaje, dar niciunul dintre ei nu a câștigat în vreun stat în cursa de nominalizare. Iar motivele pentru care s-ar lupta din greu la alegerile generale sunt numeroase. Însă grupurile din exterior precum Super PAC al lui Jeb Bush și grupul conservator economic Club for Growth admit puterea lui Trump și încep să îl susțină cu bani." } }
-{ "translation": { "en": "Here are some recent poll numbers that suggest that the real estate mogul isn't just a passing phase: Trump's favorability ratings have turned 180 degrees. Right before Donald Trump announced his candidacy in mid-June, a Monmouth University poll showed only two in 10 Republicans had a positive view of the real estate mogul. By mid-July, it was 40 percent. In early August, it was 52 percent. Now, six in 10 Republicans have a favorable view of Donald Trump. Roughly three in 10 say they have a negative view. And these numbers hold up in early states. A Quinnipiac poll in Iowa last week found that 60 percent of Republicans there had a favorable view of Trump.", "ro": "În continuare vă prezentăm câteva cifre din sondaje recente care sugerează că mogulul imobiliar nu este doar ceva trecător: Cifrele care indică susținerea față de Trump s-au întors la 180 grade. Chiar înainte ca Donald Trump să își anunțe candidatura, la mijlocul lui iunie, un sondaj realizat de Universitatea din Monmouth arăta că doar doi din 10 republicani aveau o părere pozitivă despre mogulul imobiliar. Până la mijlocul lui iulie, procentul a urcat la 40%. La începutul lui august, era 52%. În prezent, șase din 10 republicani au o părere favorabilă despre Donald Trump. Aproximativ trei din 10 declară că au o părere negativă. Aceste cifre se mențin. Un sondaj realizat săptămâna trecută de Quinnipiac în Iowa a concluzionat că 60% dintre republicanii din regiune au o părere favorabilă despre Trump." } }
-{ "translation": { "en": "Two-thirds of GOP voters would be happy with Trump as the nominee. In a CNN/ORC poll last week, 67 percent of Republicans said they would be either \"enthusiastic\" or \"satisfied\" if Trump were the nominee. Only two in 10 say they would be \"upset\" if he were the nominee. Only Ben Carson generates roughly the same level of enthusiasm as Trump (43 percent say they would be \"enthusiastic\" vs. 40 percent who say the same of Trump). The next closest in enthusiasm? Marco Rubio with only 21 percent.", "ro": "Două treimi dintre alegătorii GOP ar fi fericiți dacă Trump ar câștiga cursa pentru nominalizare. Într-un sondaj realizat săptămâna trecută de CNN/ORC, 67% dintre republicani au declarat că ar fi „entuziasmați” sau „mulțumiți” dacă Trump ar câștiga cursa pentru nominalizare. Doar doi din 10 declară că ar fi „supărați” dacă Trump ar câștiga cursa pentru nominalizare. Doar Ben Carson generează aproximativ același nivel de entuziasm ca Trump (43% declară că ar fi „entuziasmați” față de 40% care declară același lucru despre Trump). Cel mai aproape în ceea ce privește entuziasmul? Marco Rubio, cu doar 21%." } }
-{ "translation": { "en": "On the flip side, 47 percent of Republican voters say they would be \"dissatisfied\" or \"upset\" if establishment favorite Jeb Bush becomes the nominee. A majority of Republicans don't see Trump's temperament as a problem. While Donald Trump has been widely criticized for his bombast and insults, 52 percent of leaned Republican voters nationwide think that the real estate mogul has the right temperament to be president, according to Monday's ABC News/Washington Post poll. The same number holds in the first-in-the-nation caucus state of Iowa, where the same 52 percent of Republicans think he has the personality to be commander in chief, according to Quinnipiac last week.", "ro": "De partea cealaltă, 47% dintre alegătorii republicani afirmă că ar fi „nemulțumiți” sau „supărați” dacă favoritul Jeb Bush câștigă cursa pentru nominalizare. Majoritatea republicanilor nu consideră temperamentul lui Trump o problemă. Deși Donald Trump a fost puternic criticat pentru insultele aduse și stilul său bombastic, 52% dintre alegătorii republicani la nivel național consideră că mogulul imobiliar are temperamentul potrivit pentru a fi președinte, conform sondajului realizat luni de ABC News/Washington Post. Regăsim aceleași cifre în statul Iowa, unde tot 52% dintre republicani cred că Trump are personalitatea potrivită pentru a fi conducător, conform sondajului realizat săptămâna trecută de Quinnipiac." } }
-{ "translation": { "en": "Still, 44 percent think he doesn't have the personality to serve effectively, and almost six in 10 independents say his temperament does not belong in the White House, according to ABC/Post. Republican voters are getting used to the idea. When they put on their pundit hats, Republican voters think Trump is for real. When asked who is most likely to win the GOP nomination, four in 10 said Trump was the best bet, according to a CNN/ORC poll out last week. That's a change from when four in 10 placed their money on Jeb Bush in late July. Full disclosure: GOP voters haven't had the clearest crystal ball in the past.", "ro": "Totuși, 44% sunt de părere că nu are personalitatea necesară pentru a acționa eficient și aproape șase din 10 independenți afirmă că temperamentul său nu are ce căuta la Casa Albă, conform ABC/Post. Alegătorii republicani se obișnuiesc cu ideea. Atunci când iau atitudinea de intelectuali, alegătorii republicani consideră că Trump este autentic. Conform unui sondaj realizat săptămâna trecută de CNN/ORC, la întrebarea cine are cele mai multe șanse să câștige cursa pentru nominalizare GOP, patru din 10 au declarat că Trump. Situația s-a schimbat față de finalul lui iulie, când patru din 10 ar fi pariat pe Jeb Bush. Informare completă: în trecut, alegătorii GOP nu au citit foarte bine viitorul." } }
-{ "translation": { "en": "At this time last cycle, four in 10 Republicans picked Rick Perry to win the nomination, vs. only 28 percent for eventual nominee Mitt Romney. Still, it shows that a plurality of GOP voters see Trump's campaign as plausible. Even if Republicans rallied around another candidate, Trump still beats almost everyone. Some pundits point out that the splintered field is likely contributing to Trump's lead, while anti-Trump support is be spread diffusely among more than a dozen other candidates. But a Monmouth University poll in early September shows that, in a hypothetical head-to-head matchup between Trump and most other Republican candidates, Trump almost always garners majority support.", "ro": "În aceeași perioadă a ultimelor alegeri, patru din 10 republicani l-au ales pe Rick Perry în cursa pentru nominalizare, față de doar 28% pentru Mitt Romney. Însă, aceste cifre arată că majoritatea alegătorilor GOP consideră plauzibilă campania lui Trump. Chiar dacă republicanii sau repliat spre un alt candidat. Trump încă se află în fruntea tuturor. Unele voci spun că situația divizată va contribui probabil la victoria lui Trump, în timp ce susținerea contra lui Trump se va împărți la mai mult de doisprezece candidați. Însă un sondaj derulat la începutul lui septembrie de Universitatea din Monmouth arată că, în situația ipotetică a unei colaborări între Trump și majoritatea celorlalți candidați republicani, aproape întotdeauna Trump va beneficia de susținerea majoritară." } }
-{ "translation": { "en": "He leads Carly Fiorina by 13 points, Marco Rubio by 14 points, Walker by 15 points, Jeb Bush by 19 points, and, finally, Rand Paul, John Kasich and Chris Christie by 33 points each. He's in a dead heat with Ted Cruz. The only candidate who beats him? Ben Carson would lead the businessman by a wide 19 points in a hypothetical head-to-head. A bare majority of Donald Trump's supporters say they've made up their minds. A new CBS/NYT poll out on Tuesday shows that just more than half of voters who support Trump say they have locked in their votes. Obviously, a lot can happen to change that, and no one can really say they would never change their mind.", "ro": "Trump se află la distanță de 13 puncte de Carly Fiorina, la 14 puncte de Marco Rubio, la 15 puncte de Walker, la 19 puncte de Jeb Bush și, în cele din urmă, la câte 33 de puncte față de Rand Paul, John Kasich și Chris Christie. Este aproape la egalitate cu Ted Cruz. Singurul candidat care îl învinge? Ben Carson l-ar învinge pe omul de afaceri cu 19 puncte într-o confruntare ipotetică de unu la unu. Majoritatea susținătorilor lui Donald Trump declară că s-au decis. Un nou sondaj realizat marți de CBS/NYT arată că peste jumătate dintre alegătorii care îl susțin pe Trump declară că nu își schimbă opțiunea de vot. Evident, se pot întâmpla multe în acest sens și nimeni nu poate spune că aceștia nu se vor răzgândi niciodată." } }
-{ "translation": { "en": "46 percent said they are leaving the door open to switching candidates. Still, Trump's strongest competition at the moment is from fellow outsider neurosurgeon Ben Carson, but voters who say they have made up their minds are twice as likely to go for Trump. Six in 10 Republicans say they agree with Trump on immigration. Even since Donald Trump called immigrants from Mexico \"rapists\" in his campaign announcement speech two months ago, immigration has been front and center in the 2016 conversation. Some are worried that Trump's bombast will drive crucial Hispanic voters away from the Republican Party and damage rebranding efforts.", "ro": "46% afirmă că lasă portița deschisă posibilității de a-și schimba opțiunea. Cu toate acestea, cel mai important adversar al lui Trump este în prezent neurochirurgul Ben Carson, însă este de două ori mai probabil ca alegătorii care declară că s-au decis să voteze cu Trump. Șase din 10 republicani afirmă că sunt de acord cu Trump în problema imigrării. De când Donald Trump i-a numit pe imigranții din Mexic „violatori” în discursul de deschidere a campaniei sale, în urmă cu două luni, imigrarea a fost subiectul central în campania pentru 2016. Unii sunt îngrijorați că stilul bombastic al lui Trump va duce la o scindare între alegătorii hispanici importanți și Partidul Republican și va prejudicia eforturile de rebranding." } }
-{ "translation": { "en": "But according to Monday's new ABC/Post poll, six in 10 Republicans say they agree with Trump on immigration issues. So as long as immigration remains in the spotlight, it seems Donald Trump will remain too. Frustration with government is climbing to new highs. Donald Trump and Ben Carson now account for roughly half of the support from Republican voters, largely due to their outsider status. Six in 10 Republicans in Monday's new ABC/Post poll say they want a political outsider over someone with government experience. And they are angry at Washington, too.", "ro": "Însă, conform sondajului realizat luni de ABC/Post, șase din 10 republicani afirmă că sunt de acord cu Trump în problema imigrării. Așa că, se pare că atâta timp cât problema imigrării rămâne în lumina reflectoarelor, la fel va rămâne și Doland Trump. Frustrarea față de autorități atinge noi culmi. Donald Trump și Ben Carson sunt acum susținuți de aproape jumătate dintre alegătorii republicani, în mare parte datorită statutului lor de outsideri. Conform sondajului realizat luni de ABC/Post, șase din 10 republicani afirmă că preferă un outsider politic în detrimentul cuiva cu experiență în guvernare. Oamenii sunt de asemenea supărați pe autoritățile de la Washington." } }
-{ "translation": { "en": "A Des Moines Register/Bloomberg poll in Iowa from two weeks ago shows that three in four Iowa Republicans are frustrated with Republicans in Congress, with 54 percent \"unsatisfied\" and 21 percent \"mad as hell.\" Jeremy Corbyn to make debut at Prime Minister's Questions Since his election, Mr Corbyn's debut at PMQs has been keenly awaited New Labour leader Jeremy Corbyn is to make his debut at Prime Minister's Questions later, taking on David Cameron for the first time.", "ro": "Un sondaj derulat în urmă cu două săptămâni în Iowa de către Des Moines Register/Bloomberg arată că trei din patru republicani din Iowa sunt frustrați de prestația republicanilor din COngres, 54% declarându-se „nemulțumiți” iar 21% „nervoși la culme”. Jeremy Corbyn își face debutul la Prime Minister's Questions Încă de la alegerea sa, debutul domnului Corbyn la PMQs a fost îndelung așteptat Noul lider al Partidului Laburist, Jeremy Corbyn, își va face mai târziu debutul la Prime Minister's Questions, confruntându-se pentru prima dată cu David Cameron." } }
-{ "translation": { "en": "Mr Corbyn will rise to ask the first of his six allotted questions shortly after midday, with his performance likely to be closely scrutinised by the media and Labour MPs. He has called for \"less theatre and more facts\" at the weekly showpiece. He has also said he could skip some sessions, leaving them to colleagues. The encounter will be the first parliamentary test of Mr Corbyn's leadership, coming after his appointment of a shadow cabinet and his speech to the TUC annual congress on Tuesday.", "ro": "Dl Corbyn va adresa primele dintre cele șase întrebări la care are dreptul la scurt timp după prânz; prestația sa va fi probabil analizată îndeaproape de mass-media și parlamentarii laburiști. În cadrul aparițiilor săptămânale, el a cerut „mai puțin teatru și mai multe fapte”. A declarat de asemenea că poate renunța la câteva participări și că le cedează colegilor săi. Confruntarea va fi primul test parlamentar al Dl Corbyn în poziție de lider, venind după ce a numit un „cabinet fantomă” și după discursul pe care l-a ținut marți la congresul anual TUC." } }
-{ "translation": { "en": "Meanwhile, the Labour leader's decision to stand in silence during the singing of the national anthem at a service on Tuesday to mark the 75th anniversary of the Battle of Britain has attracted criticism from a number of Tory MPs and is the focus of several front page stories in the newspapers. Mr Corbyn's decision not to sing the national anthem has attracted attention A spokesman for Mr Corbyn said he had \"stood in respectful silence\" and did recognise the \"heroism of the Royal Air Force in the Battle of Britain.\"", "ro": "Între timp, decizia liderului Partidului laburist de a păstra tăcerea la rostirea imnului național în cadrul unei slujbe ținute marți cu ocazia aniversării a 75 de ani de la Bătălia Angliei a atras critici din partea unor parlamentari conservatori și a ținut prima pagină a ziarelor. Decizia domnului Corbyn de a nu cânta imnul național a atras atenția Un purtător de cuvânt al Dl Corbyn a declarat că acesta „a păstrat tăcerea în mod respectuos” și a recunoscut „eroismul Forțelor aeriene britanice în Bătălia Angliei.”" } }
-{ "translation": { "en": "But a member of Mr Corbyn's shadow cabinet, Owen Smith, told BBC Two's Newsnight programme he would have advised the Labour leader to sing the national anthem \"irrespective\" of his belief that the monarchy should be abolished. Nearly a dozen shadow ministers have refused to serve in Mr Corbyn's top team, citing differences over the economy, defence and foreign affairs, while less than a sixth of the parliamentary party originally backed him as leader. BBC political correspondent Robin Brant says policy differences are also \"stacking up\" within Labour following Mr Corbyn's appointment over its position on the European Union and the government's cap on benefits.", "ro": "Însă un membru al cabinetului fantomă al Dl Corbyn, Owen Smith, a declarat pentru emisiunea Two's Newsnight transmisă de BBC că i-ar fi recomandat liderului laburist să cânte imnul național „indiferent” de credința sa că monarhia ar trebui abolită. În jur de doisprezece miniștri din cabinetul fantomă au refuzat să facă parte din echipa de frunte a Dl Corbyn, argumentând prin diferențe de opinie legate de economie, apărare și externe, în timp ce mai puțin de o șesime din partidul parlamentar l-a susținut ca lider. Corespondentul politic al BBC, Robin Brant, declară că diferențele de politică „se cumulează” în Partidul Laburist după numirea domnului Corbyn referitor la poziția sa față de Uniunea Europeană și limita de beneficii." } }
-{ "translation": { "en": "Mr Corbyn told the TUC conference Labour was putting forward amendments to remove the whole idea of a cap altogether. Hours later Mr Smith, the shadow work and pensions secretary, said the party was \"very clear\" that it was only opposing government plans to reduce the level of cap from £26,000 to £23,000. Mr Corbyn will be the fifth Labour leader that David Cameron has faced across the despatch box over the past decade since he became Tory leader. The Labour leader, who has promised a different approach to politics, says he has \"crowd sourced\" ideas for questions to ask Mr Cameron and has been given more than 30,000 suggestions.", "ro": "Dl Corbyn a declarat la conferința TUC că Partidul Laburist va aduce modificări prin care se va elimina integral ideea limitării. Câteva ore mai târziu, Dl Smith, Ministrul Muncii și Pensiilor, a declarat că partidul „este foarte clar” în opoziția exclusivă față de planurile guvernului de a reduce nivelul „cap” de la 26.000 lire la 23.000 lire. Dl Corbyn va fi al cincilea lider laburist cu care se confruntă David Cameron la tribună în ultimul deceniu, de când a preluat conducerea Partidului Conservator. Liderul laburist, care a promis o abordare diferită a politicii, spune că are idei „din surse externe” pentru întrebări pe care să i le adreseze Domnului Cameron și că a primit peste 30.000 de sugestii." } }
-{ "translation": { "en": "The Islington North MP has said PMQs is too confrontational and that he will refrain from both \"repartee\" and trading barbs, instead vowing to focus on serious issues such as poverty, inequality and the challenges facing young people. Mr Corbyn has said that Angela Eagle, the shadow business secretary, will deputise for him at PMQs when he does not attend - for instance when Mr Cameron is travelling abroad. He has also floated the idea of allowing other colleagues to take the floor on occasion, saying he had approached the Commons Speaker John Bercow to discuss the issue.", "ro": "Parlamentarul Islington North a afirmat că PMQs implică un nivel de confruntare prea înalt și că se va abține de la replici și atacuri, angajându-se să se concentreze în schimb pe probleme serioase precum sărăcia, inegalitatea și provocările cu care se confruntă tinerii. Dl Corbyn a declarat că Angela Eagle, Ministrul de finanțe, îi va ține locul la PMQs atunci când el nu poate participa - de exemplu atunci când Dl Cameron se deplasează în străinătate. A exprimat de asemenea ideea că va permite altor colegi să ia cuvântul ocazional, spunând că l-a abordat pe Președintele Camerei Deputaților, John Bercow, pentru a discuta acest aspect." } }
-{ "translation": { "en": "When he became leader in 2005, Mr Cameron said he wanted to move away from the \"Punch and Judy\" style of politics often associated with PMQs but admitted some years later that he had failed. Since it was first televised in 1990, PMQs has been seen as a key barometer of a leader's judgement, their command of the Commons and their standing among their fellow MPs although critics have argued it has become a caricature and is in need of far-reaching reforms. 'Shot in Joburg': Homeless youth trained as photographers Downtown Johannesburg is a tough place to be homeless.", "ro": "În 2005, când a preluat conducerea, Dl Cameron a declarat că dorește să renunțe la stilul politic „Punch and Judy” asociat adesea cu PMQs însă a recunoscut câțiva ani mai târziu că nu a reușit în demersul său. De la prima transmisie, în 1990, PMQs a fost considerată un barometru cheie al raționamentului unui lider, al modului în care acesta conduce Camera Deputaților și a poziției sale în rândul colegilor parlamentari, deși criticii afirmă a ca devenit o caricatură și că are nevoie de o reformare profundă. „Cadru în Joburg”: Tineri fără adăpost beneficiază de cursuri de fotografie Este dificil să fii un om fără adăpost în Johannesburg." } }
-{ "translation": { "en": "But one group of former street children have found a way to learn a skill and make a living. \"I was shot in Joburg\" is a non-profit studio that teaches homeless youngsters how to take photographs of their neighbourhood and make a profit from it. BBC News went to meet one of the project's first graduates. JD Sports boss says higher wages could hurt expansion JD Sports Executive Chairman Peter Cowgill says a higher minimum wage for UK workers could mean \"more spending power in the pockets of potential consumers.\" But that spending power is unlikely to outweigh the higher labour costs at his firm, he says.", "ro": "Însă un grup de oameni care au trăit pe străzi în copilărie au găsit un mod de a învăța o meserie și de a-și câștiga traiul. „I was shot în Joburg” este un studio non-profit care îi învață pe tinerii fără adăpost să facă fotografii ale zonelor în care trăiesc și să câștige bani din asta. BBC News s-a întâlnit cu unul dintre primii absolvenți ai proiectului. Șeful JD Sports spune că salariile mai mari ar putea dăuna extinderii Președintele JD Sports, Peter Cowgill, declară că o creștere a salariului minim în Marea Britanie ar putea însemna „o putere de cumpărare mai mare în buzunarele potențialilor consumatori.” Este însă puțin probabil ca respectiva putere de cumpărare să depășească costurile mai mari pentru forța de muncă în cadrul firmei, afirmă el." } }
-{ "translation": { "en": "The costs could hit JD Sports' expansion plans, he added, which could mean fewer extra jobs. Thanasi Kokkinakis backed by Tennis Australia president Steve Healy Thanasi Kokkinakis deserves kudos rather than criticism for his behaviour. Thanasi Kokkinakis has been the collateral damage in the recent storm around his friend Nick Kyrgios and deserves kudos rather than criticism for his own behaviour, according to Tennis Australia president Steve Healy.", "ro": "Costurile ar putea avea impact asupra planurilor de extindere ale JD Sports, a adăugat el, ceea ce ar putea însemna mai puține locuri de muncă noi. Thanasi Kokkinakis susținut de președintele Tennis Australia, Steve Healy Thanasi Kokkinakis ar merita să fie lăudat și nu criticat pentru comportamentul său. Thanasi Kokkinakis a fost victimă colaterală în „furtuna” creată în jurul prietenului său, Nick Kyrgios, iar comportamentul său merită mai degrabă cuvinte de laudă și nu critică, în opinia președintelui Tennis Australia, Steve Healy." } }
diff --git a/tests/fixtures/tests_samples/wmt_en_ro/train.json b/tests/fixtures/tests_samples/wmt_en_ro/train.json
deleted file mode 100644
index 269d5156c23e..000000000000
--- a/tests/fixtures/tests_samples/wmt_en_ro/train.json
+++ /dev/null
@@ -1,11 +0,0 @@
-{ "translation": { "en": "Corrections to votes and voting intentions: see Minutes Assignment conferred on a Member: see Minutes Membership of committees and delegations: see Minutes Decisions concerning certain documents: see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes", "ro": "Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Misiune încredinţată unui deputat: consultaţi procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal" } }
-{ "translation": { "en": "Membership of Parliament: see Minutes Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes Verification of credentials: see Minutes Documents received: see Minutes Written statements and oral questions (tabling): see Minutes Petitions: see Minutes Texts of agreements forwarded by the Council: see Minutes Action taken on Parliament's resolutions: see Minutes Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 7.45 p.m.)", "ro": "Componenţa Parlamentului: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal Verificarea prerogativelor: a se vedea procesul-verbal Depunere de documente: a se vedea procesul-verbal Declaraţii scrise şi întrebări orale (depunere): consultaţi procesul-verbal Petiţii: a se vedea procesul-verbal Transmiterea de către Consiliu a textelor acordurilor: a se vedea procesul-verbal Cursul dat rezoluţiilor Parlamentului: a se vedea procesul-verbal Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Se levanta la sesión a las 19.45 horas)" } }
-{ "translation": { "en": "Election of Vice-Presidents of the European Parliament (deadline for submitting nominations): see Minutes (The sitting was suspended at 12.40 p.m. and resumed at 3.00 p.m.) Election of Quaestors of the European Parliament (deadline for submitting nominations): see Minutes (The sitting was suspended at 3.25 p.m. and resumed at 6.00 p.m.) Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 6.15 p.m.) Opening of the sitting (The sitting was opened at 9.35 a.m.) Documents received: see Minutes Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes", "ro": "Alegerea vicepreşedinţilor Parlamentului European (termenul de depunere a candidaturilor): consultaţi procesul-verbal (Die Sitzung wird um 12.40 Uhr unterbrochen und um 15.00 Uhr wiederaufgenommen). Alegerea chestorilor Parlamentului European (termenul de depunere a candidaturilor): consultaţi procesul-verbal (Die Sitzung wird um 15.25 Uhr unterbrochen und um 18.00 Uhr wiederaufgenommen). Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Die Sitzung wird um 18.15 Uhr geschlossen.) Deschiderea şedinţei (Die Sitzung wird um 9.35 Uhr eröffnet.) Depunerea documentelor: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal" } }
-{ "translation": { "en": "Membership of committees (deadline for tabling amendments): see Minutes (The sitting was suspended at 7 p.m. and resumed at 9 p.m.) Agenda for next sitting: see Minutes Closure of sitting (The sitting was suspended at 23.25 p.m.) Documents received: see Minutes Communication of Council common positions: see Minutes (The sitting was suspended at 11.35 a.m. and resumed for voting time at noon) Approval of Minutes of previous sitting: see Minutes Committee of Inquiry into the crisis of the Equitable Life Assurance Society (extension of mandate): see Minutes", "ro": "Componenţa comisiilor (termenul de depunere a amendamentelor): consultaţi procesul-verbal (La seduta, sospesa alle 19.00, è ripresa alle 21.00) Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (Die Sitzung wird um 23.25 Uhr geschlossen.) Depunerea documentelor: a se vedea procesul-verbal Comunicarea poziţiilor comune ale Parlamentului: a se vedea procesul-verbal (La séance, suspendue à 11h35 dans l'attente de l'Heure des votes, est reprise à midi) Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Comisia de anchetă privind criza societăţii de asigurări \"Equitable Life” (prelungirea mandatului): consultaţi procesul-verbal" } }
-{ "translation": { "en": "Announcement by the President: see Minutes 1. Membership of committees (vote) 2. Amendment of the ACP-EC Partnership Agreement (vote) 4. Certification of train drivers operating locomotives and trains on the railway system in the Community (vote) 6. Law applicable to non-contractual obligations (\"ROME II\") (vote) 8. Seventh and eighth annual reports on arms exports (vote) Corrections to votes and voting intentions: see Minutes Membership of committees and delegations: see Minutes Request for waiver of parliamentary immunity: see Minutes Decisions concerning certain documents: see Minutes", "ro": "Comunicarea Preşedintelui: consultaţi procesul-verbal 1. Componenţa comisiilor (vot) 2. Modificarea Acordului de parteneriat ACP-CE (\"Acordul de la Cotonou”) (vot) 4. Certificarea mecanicilor de locomotivă care conduc locomotive şi trenuri în sistemul feroviar comunitar (vot) 6. Legea aplicabilă obligaţiilor necontractuale (\"Roma II”) (vot) 8. Al şaptelea şi al optulea raport anual privind exportul de armament (vot) Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Cerere de ridicare a imunităţii parlamentare: consultaţi procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal" } }
-{ "translation": { "en": "Written statements for entry", "ro": "Declaraţii scrise înscrise" } }
-{ "translation": { "en": "Written statements for entry in the register (Rule 116): see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes Adjournment of the session I declare the session of the European Parliament adjourned. (The sitting was closed at 1 p.m.) Approval of Minutes of previous sitting: see Minutes Membership of Parliament: see Minutes Request for the defence of parliamentary immunity: see Minutes Appointments to committees (proposal by the Conference of Presidents): see Minutes Documents received: see Minutes Texts of agreements forwarded by the Council: see Minutes", "ro": "Declaraţii scrise înscrise în registru (articolul 116 din Regulamentul de procedură): a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal Întreruperea sesiunii Dichiaro interrotta la sessione del Parlamento europeo. (La seduta è tolta alle 13.00) Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal Componenţa Parlamentului: a se vedea procesul-verbal Cerere de apărare a imunităţii parlamentare: consultaţi procesul-verbal Numiri în comisii (propunerea Conferinţei preşedinţilor): consultaţi procesul-verbal Depunerea documentelor: a se vedea procesul-verbal Transmiterea de către Consiliu a textelor acordurilor: a se vedea procesul-verbal" } }
-{ "translation": { "en": "Action taken on Parliament's resolutions: see Minutes Oral questions and written statements (tabling): see Minutes Written statements (Rule 116): see Minutes Agenda: see Minutes 1. Appointments to parliamentary committees (vote): see Minutes Voting time Agenda for next sitting: see Minutes Closure of sitting (The sitting was closed at 12 midnight) Opening of the sitting (The sitting was opened at 09.05) Documents received: see Minutes Approval of Minutes of previous sitting: see Minutes 1. Protection of passengers against displaced luggage (vote) 2.", "ro": "Continuări ale rezoluţiilor Parlamentului: consultaţi procesul-verbal Declaraţii scrise şi întrebări orale (depunere): consultaţi procesul-verbal Declaraţii scrise (articolul 116 din Regulamentul de procedură) Ordinea de zi: a se vedea procesul-verbal 1. Numiri în comisiile parlamentare (vot): consultaţi procesul-verbal Timpul afectat votului Ordinea de zi a următoarei şedinţe: a se vedea procesul-verbal Ridicarea şedinţei (La seduta è tolta alle 24.00) Deschiderea şedinţei (The sitting was opened at 09.05) Depunerea documentelor: a se vedea procesul-verbal Aprobarea procesului-verbal al şedinţei precedente: a se vedea procesul-verbal 1. Protecţia pasagerilor împotriva deplasării bagajelor (vot) 2." } }
-{ "translation": { "en": "Approval of motor vehicles with regard to the forward field of vision of the driver (vote) 3. EC-Korea Agreement on scientific and technological cooperation (vote) 4. Mainstreaming sustainability in development cooperation policies (vote) 5. Draft Amending Budget No 1/2007 (vote) 7. EC-Gabon Fisheries Partnership (vote) 10. Limitation periods in cross-border disputes involving personal injuries and fatal accidents (vote) 12. Strategy for a strengthened partnership with the Pacific Islands (vote) 13. The European private company statute (vote) That concludes the vote.", "ro": "Omologarea vehiculelor cu motor cu privire la câmpul de vizibilitate înainte al conducătorului auto (vot) 3. Acordul CE-Coreea de cooperare ştiinţifică şi tehnologică (vot) 4. Integrarea durabilităţii în politicile de cooperare pentru dezvoltare (vot) 5. Proiect de buget rectificativ nr.1/2007 (vot) 7. Acordul de parteneriat în domeniul pescuitului între Comunitatea Europeană şi Republica Gaboneză (vot) 10. Termenele de prescripţie aplicabile în cadrul litigiilor transfrontaliere cu privire la vătămările corporale şi accidentele mortale (vot) 12. Relaţiile UE cu insulele din Pacific: Strategie pentru un parteneriat consolidat (vot) 13. Statutul societăţii private europene (vot) Damit ist die Abstimmungsstunde beendet." } }
-{ "translation": { "en": "Corrections to votes and voting intentions: see Minutes Assignment conferred on a Member: see Minutes Membership of committees and delegations: see Minutes Decisions concerning certain documents: see Minutes Forwarding of texts adopted during the sitting: see Minutes Dates for next sittings: see Minutes", "ro": "Corectările voturilor şi intenţiile de vot: a se vedea procesul-verbal Misiune încredinţată unui deputat: consultaţi procesul-verbal Componenţa comisiilor şi a delegaţiilor: a se vedea procesul-verbal Decizii privind anumite documente: a se vedea procesul-verbal Transmiterea textelor adoptate în cursul prezentei şedinţe: a se vedea procesul-verbal Calendarul următoarelor şedinţe: a se vedea procesul-verbal" } }
-{ "translation": { "en": "Written statements for entry", "ro": "Declaraţii scrise înscrise" } }
diff --git a/tests/fixtures/tests_samples/wmt_en_ro/val.json b/tests/fixtures/tests_samples/wmt_en_ro/val.json
deleted file mode 100644
index 22cdd68ecd1c..000000000000
--- a/tests/fixtures/tests_samples/wmt_en_ro/val.json
+++ /dev/null
@@ -1,16 +0,0 @@
-{ "translation": { "en": "Brazil's Former Presidential Chief-of-Staff to Stand Trial A federal judge on Tuesday accepted the charges filed against Brazil's former presidential chief of staff for his alleged involvement in a massive corruption scheme at state-owned oil company Petrobras. The federal prosecutor's office said Jose Dirceu will face trial on the corruption, racketeering and money laundering charges filed earlier this month. Fourteen other people will also be tried, including Joao Vaccari Neto, the former treasurer of Brazil's governing Workers' Party and Renato de Souza Duque, Petrobras' former head of corporate services.", "ro": "Fostul șef al cabinetului prezidențial brazilian este adus în fața instanței Marți, un judecător federal a acceptat acuzațiile aduse împotriva fostului șef al cabinetului prezidențial brazilian pentru presupusa implicare a acestuia într-o schemă masivă de corupție privind compania petrolieră de stat Petrobras. Biroul procurorului federal a declarat că Jose Dirceu va fi trimis în judecată pentru acuzațiile de corupție, înșelătorie și spălare de bani aduse în această lună. Alte paisprezece persoane vor fi judecate, printre acestea numărându-se Joao Vaccari Neto, fostul trezorier al Partidului Muncitorilor, aflat la putere în Brazilia, și Renato de Souza Duque, fostul președinte al serviciilor pentru întreprinderi ale Petrobras." } }
-{ "translation": { "en": "Dirceu is the most senior member of the ruling Workers' Party to be taken into custody in connection with the scheme. Dirceu served as former President Luiz Inacio Lula da Silva's chief of staff between 2003 and 2005. He was arrested early August in his home, where he already was under house arrest serving an 11-year sentence for his involvement in a cash-for-votes scheme in Congress more than 10 years ago. Prosecutors have said that Dirceu masterminded the kickback scheme at Petrobras, accepted bribes while in office and continued to receive payments from contractors after he was jailed in late 2013 for the vote-buying scandal.", "ro": "Dirceu este cel mai vechi membru al Partidului Muncitorilor aflat la guvernare luat în custodie pentru legăturile cu această schemă. Dirceu a servit ca șef de cabinet al fostului președinte Luiz Inacio Lula da Silva între 2003 și 2005. A fost arestat la începutul lui august de acasă, unde deja se afla sub arest la domiciliu, cu o pedeapsă de 11 ani pentru implicarea într-o schemă de cumpărare a voturilor în Congres cu peste 10 ani în urmă. Procurorii au declarat că Dirceu a dezvoltat schema de luare de mită de la Petrobras, a acceptat mită în timp ce se afla în funcție și a continuat să primească plăți de la antreprenori după ce a fost închis la sfârșitul lui 2013 pentru scandalul voturilor cumpărate." } }
-{ "translation": { "en": "According to prosecutors, the scheme at Petrobras involved roughly $2 billion in bribes and other illegal funds. Some of that money was allegedly funneled back to campaign coffers of the ruling party and its allies. It also allegedly included the payment of bribes to Petrobras executives in return for inflated contracts. 'Miraculous' recovery for Peshawar massacre schoolboy A teenager paralysed after being shot four times in Pakistan's deadliest terror attack has made a \"miraculous\" recovery following treatment in the UK. Muhammad Ibrahim Khan, 13, had been told by doctors in Pakistan that he would never walk again.", "ro": "Conform procurorilor, schema de la Petrobras a implicat aproximativ 2 miliarde de dolari sub formă de mită și alte fonduri ilegale. O parte din acei bani s-ar fi întors în fondul de campanie al partidului aflat la guvernare și al aliaților acestora. De asemenea, ar fi inclus mită către directorii Petrobras în schimbul unor contracte umflate. Recuperarea „miraculoasă” a unui elev supraviețuitor al masacrului de la Peshawar Un adolescent paralizat după ce fusese împușcat de patru ori în cel mai cumplit atac terorist din Pakistan a reușit o recuperare „miraculoasă” după ce a urmat un tratament în Regatul Unit. Lui Mohamed Ibrahim Khan, în vârstă de 13 ani, doctorii din Pakistan îi spuseseră că nu va mai putea să meargă niciodată." } }
-{ "translation": { "en": "At least 140 people, mostly children, were killed when gunmen stormed Peshawar's Army Public School last December. Muhammad, who arrived in London last month for surgery, is being discharged from hospital later. Exactly nine months ago, on an ordinary Tuesday morning, Muhammad sat in his first aid class listening to his teachers intently. At the same time seven gunmen disguised in security uniforms were entering the Army Public School. They were strapped with explosives and had one simple mission in mind: Kill every man, woman and child they came across. \"I can't forget what happened that day,\" Muhammad says with a severe stare.", "ro": "Cel puțin 140 de persoane, majoritatea copii, au fost ucise când bărbați înarmați au atacat școala publică a armatei din Peshawar în luna decembrie a anului trecut. Mohamed, care a sosit la Londra luna trecută pentru operație, va fi externat mai târziu din spital. Exact cu nouă luni în urmă, într-o dimineață obișnuită de marți, Mohamed stătea la ora de primul ajutor și își asculta atent profesorii. Chiar atunci, șapte bărbați înarmați deghizați în uniformele agenților de pază intrau în școala publică a armatei. Purtau centuri cu explozivi și aveau de îndeplinit o misiune simplă: să îi ucidă pe toți bărbații, femeile și copiii care le ieșeau în cale. „Nu pot uita ce s-a întâmplat în acea zi”, spune Mohamed cu o privire aspră." } }
-{ "translation": { "en": "We were sitting in the auditorium, we were asking questions... and then we heard heavy gunfire outside. The terrorists moved inside and they started killing - our teacher was burned alive. Muhammad described pulling four other pupils out of the auditorium as the carnage unfolded. He said he then heard his friend, Hamza calling to him. He said, 'oh brother save me'. I held his hand. That's when I was shot in the back, and he was shot in the head. Most of the people killed in the attack were pupils Hamza died in Muhammad's arms. Muhammad recalled blacking out after that, and the next thing he knew he was in a hospital bed, paralysed from the waist down.", "ro": "Stăteam în amfiteatru, puneam întrebări... apoi am auzit focuri de armă afară. Teroriștii au intrat înăuntru și au început să ucidă. Profesorul nostru a fost ars de viu. Mohamed descrie cum a scos patru elevi din amfiteatru în timp ce se desfășura carnagiul. Apoi spune că și-a auzit prietenul, pe Hamza, strigându-l. Spunea „oh, frate, salvează-mă”. L-am ținut de mână. Atunci eu am fost împușcat în spate, iar el în cap. Cei mai mulți dintre cei uciși în atac erau elevi Hamza a murit în brațele lui Mohamed. Mohamed își amintește că imediat după asta a leșinat și că următorul lucru pe care l-a știut a fost că se afla pe un pat de spital, paralizat de la brâu în jos." } }
-{ "translation": { "en": "Doctors in Peshawar in northern Pakistan, and then Rawalpindi, close to the capital, told his family there was no treatment, and he would never walk again. \"Seeing him I felt like my soul had left my body,\" says Muhammad's father, Sher Khan Those nine months were the hardest in my life. But Mr Khan and his wife, Sherbano, refused to believe that their cricket-mad son would never be able to use his legs again. They campaigned, and appealed for help on Pakistani TV, gaining the support of high profile people such as cricketer turned politician Imran Khan.", "ro": "Doctorii din Peshawar din nordul Pakistanului, apoi cei din Rawalpindi, aproape de capitală, i-au spus familiei sale că nu exista tratament și că nu va mai putea merge niciodată. „Când l-am văzut, am simțit cum îmi iese sufletul”, spune Sher Khan, tatăl lui Mohamed. Acele nouă luni au fost cele mai grele din viața mea. Însă Khan și soția lui, Sherbano, au refuzat să creadă că fiul lor atât de pasionat de crichet nu-și va mai putea folosi vreodată picioarele. Au făcut o campanie și au cerut ajutor de la televiziunea pakistaneză, atrăgând sprijinul unor oameni faimoși precum Imran Khan, jucător de crichet devenit politician." } }
-{ "translation": { "en": "Finally, they were able to raise the funds to bring Muhammad to the UK and provide him with treatment at London's private Harley Street Clinic. Consultant neurosurgeon Irfan Malik described Muhammad as \"terrified\" when he first arrived at the hospital. \"He'd spent the last [few] months lying on a bed, unable to move side to side,\" says Mr Malik. He was weak, he had a pressure sore on his back. He wasn't in great shape. A vertebra at the base of Muhammad's spine was destroyed Muhammad was shot in his shoulder, his hip, and his back during the attack, damaging his lower spine - leading to paralysis.", "ro": "Într-un final, au reușit să strângă fonduri pentru a-l duce pe Mohamed în Regatul Unit și a-i oferi tratament la clinica privată Harley Street din Londra. Neurochirurgul consultant Irfan Malik l-a descris pe Mohamed drept „înspăimântat” când acesta a ajuns la spital. „Își petrecuse ultimele [câteva] luni zăcând în pat, fără să se poată mișca de pe o parte pe alta, spune Malik. Era slăbit, se pusese multă presiune pe spatele lui. Nu era într-o formă prea bună. O vertebră de la baza coloanei vertebrale a lui Mohamed fusese distrusă Mohamed fusese împușcat în umăr, în șold și în spate în timpul atacului, iar coloana vertebrală inferioară îi fusese distrusă, ducând la paralizie." } }
-{ "translation": { "en": "But during six hours of surgery, Mr Malik and his team were able to reattach nerve endings and reconstruct the damaged part of the spine. Even Mr Malik was surprised at what happened next. Exactly one week after the surgery Muhammad stood up and started taking steps and walking. We were not expecting to get that sort of excellent result. That was miraculous,\" he says. Less than two weeks after his operation, Muhammad is ready to leave hospital and start the long road to recovery. Muhammad has defied the odds and started to walk again He says he wants to build his strength and continue his education in the UK. But he says he is determined to return to Pakistan, join the army and help fight terrorism.", "ro": "Însă, în timpul unei operații care a durat șase ore, Malik și echipa lui au reușit să lege din nou terminațiile nervoase și să reconstruiască partea distrusă a coloanei. Chiar și Malik a fost surprins de ceea ce s-a întâmplat în continuare. Exact la o săptămână după operație, Mohamed s-a ridicat și a început să facă pași și să meargă. Nu ne așteptam la un rezultat atât de bun. A fost un miracol”, spune acesta. În mai puțin de două săptămâni de la operație, Mohamed este gata să părăsească spitalul și să înceapă procesul lung de recuperare. Mohamed a sfidat soarta și a început să meargă din nou Vrea să devină puternic și să își continue studiile în Regatul Unit. Însă este hotărât să revină în Pakistan, să se înroleze în armată și să lupte împotriva terorismului." } }
-{ "translation": { "en": "\"I feel like I have a second chance at life,\" he says as he shows off pictures he's drawn of guns scribbled out next to school books and pens Muhammad grows physically stronger every day but the psychological trauma he continues to endure is unimaginable. \"My anger is not diminishing\" he says. In my school little kids were killed. What was their crime? His mother, wiping a tear from her eye, caressed his head and said: \"I can see my son walking again.\" He'll be able to get on with his normal life. 'Super Voice' 4G service from Three offers better signal Three is making use of a lower frequency 4G spectrum that can travel more widely", "ro": "„Simt că am încă o șansă la viață” spune el, arătând imaginile cu arme desenate de el lângă manuale școlare și stilouri Fizic, Mohamed devine tot mai puternic în fiecare zi, însă trauma psihologică prin care trece și acum este de neimaginat. „Furia mea nu a scăzut”, mărturisește el. În școala mea au fost uciși copii mici. Ce crimă au comis ei? Mama lui își șterge o lacrimă, îl mângâie pe creștet și spune: „Îmi văd fiul mergând din nou”. Va putea să-și continue firesc viața. Serviciul 4G „Super Voice” de la Three oferă semnal mai bun Three folosește un spectru 4G cu o frecvență mai joasă, care poate acoperi o zonă mai extinsă" } }
-{ "translation": { "en": "Mobile phone provider Three has launched a UK service it says will improve reception inside buildings and in rural black spots. Its 4G Super Voice enables customers to make calls and send texts using a lower frequency spectrum. Other networks are looking into introducing the technology, known as Voice Over Long-Term Evolution (VoLTE). It currently works on only the Samsung Galaxy S5, but recent iPhone handsets will be added in the coming months. Three said up to 5.5 million customers would have access to the service by 2017.", "ro": "Furnizorul de telefonie mobilă Three a lansat în Regatul Unit un serviciu despre care spune că va îmbunătăți recepția în interiorul clădirilor și în zonele rurale fără semnal. Serviciul 4G Super Voice le permite clienților să efectueze apeluri și să trimită mesaje text folosind un spectru cu o frecvență mai joasă. Și alte rețele intenționează să introducă aceeași tehnologie, cunoscută ca „Voice Over Long-Term Evolution (VoLTE)”. Aceasta funcționează momentan doar cu Samsung Galaxy S5, însă telefoanele iPhone recente vor beneficia de ea în lunile următoare. Three menționează că până la 5,5 milioane de clienți vor avea acces la serviciu până în 2017." } }
-{ "translation": { "en": "Chief technology officer Bryn Jones said: \"By the end of the year, one million of our customers will have access to better indoor coverage and be able to use their phones in more places than ever before.\" Stars prepare for panto season Pantomime season is big business for theatres up and down the UK, with many getting ready for this year's season now. Some of the biggest names in showbusiness now take part in the yuletide theatre. Matthew Kelly and Hayley Mills will be appearing in Cinderella - one as an ugly sister, the other as fairy godmother. They reveal their panto secrets to BBC Breakfast. Steven Wilson: 'If I don't do anything, I feel this creeping guilt'", "ro": "Responsabilul șef pentru tehnologie, Bryn Jones a declarat: „Până la sfârșitul anului, un milion dintre clienții noștri vor avea acces la o acoperire mai bună în interior și își vor putea folosi telefoanele în mai multe locuri ca până acum”. Vedetele se pregătesc pentru stagiunea de pantomimă Stagiunea de pantomimă este foarte importantă pentru teatrele din tot Regatul Unit, multe dintre ele pregătindu-se acum pentru stagiunea din acest an. Acum, la teatrul de Crăciun participă unele dintre numele cele mai mari din showbusiness. Matthew Kelly și Hayley Mills vor apărea în Cenușăreasa - primul în rolul uneia dintre surorile rele, iar a doua în rolul zânei. Aceștia dezvăluie secretele pantomimei lor la BBC Breakfast. Steven Wilson: „Dacă nu fac nimic, mă simt vinovat”" } }
-{ "translation": { "en": "Steven Wilson was recently the big winner at the Progressive Music Awards Steven Wilson is often dubbed the hardest working musician in the world of progressive rock. The multi-talented musician won three prizes at this month's Progressive Music Awards in London, including album of the year for Hand. The Guardian's five-star review called it \"a smart, soulful and immersive work of art.\" Since the 1980s, Wilson has been the driving force in a number of musical projects, the best known of which is the rock band Porcupine Tree. Now, ahead of two sell-out shows at the Royal Albert Hall, Wilson is releasing a vinyl-only double LP, Transience, to showcase the \"more accessible\" side of his solo output.", "ro": "Steven Wilson a fost desemnat recent drept marele câștigător al Progressive Music Awards Steven Wilson a fost numit de multe ori drept cel mai muncitor muzician din lumea rockului progresiv. Talentatul muzician a câștigat trei premii la Progressive Music Awards, care a avut loc luna aceasta la Londra, printre care și premiul pentru cel mai bun album al anului pentru Hand. În recenzia sa de cinci stele, The Guardian a numit albumul „o operă de artă inteligentă, expresivă și captivantă”. Încă din anii 1980, Wilson este motorul mai multor proiecte muzicale, cel mai cunoscut dintre acestea fiind trupa de rock Porcupine Tree. Acum, înainte de două spectacole cu casa închisă la Royal Albert Hall, Wilson lansează un dublu LP doar în format vinil, Transience, pentru a arăta latura „mai accesibilă” a activității sale solo." } }
-{ "translation": { "en": "He tells the BBC about his love of vinyl, his busy schedule and explains how comic actor Matt Berry came to be his support act. What does vinyl mean to you? I grew up at the very tail end of the vinyl era, and at the time, I remember, we couldn't wait for CD to come along because vinyl was so frustrating. You would buy the record, take it home, and it would have a scratch, and you would have to take it back again. I love CDs, and for some kinds of music - classical for example - it is better than vinyl. But the problem with the CD and digital downloads is that there's nothing you can really cherish or treasure. Owning vinyl is like having a beautiful painting hanging in your living room.", "ro": "A povestit pentru BBC despre dragostea lui pentru viniluri și despre programul său încărcat și a explicat cum a ajuns actorul de comedie Matt Berry să îi deschidă spectacolele. Ce înseamnă vinil pentru tine? Am crescut chiar în perioada de sfârșit a erei vinilurilor și îmi amintesc că atunci abia așteptam apariția CD-ului, căci vinilul era atât de enervant. Cumpărai un disc, mergeai cu el acasă, avea o zgârietură și trebuia să îl aduci înapoi. Iubesc CD-urile, iar pentru anumite tipuri de muzică, de exemplu cea clasică, sunt mai bune decât vinilurile. Însă problema cu CD-urile și cu descărcările digitale este aceea că nu mai există nimic pe care să îl prețuiești cu adevărat. Să ai un vinil e ca și cum ai avea un tablou frumos agățat în sufragerie." } }
-{ "translation": { "en": "It's something you can hold, pore over the lyrics and immerse yourself in the art work. I thought it was just a nostalgic thing, but it can't be if kids too young to remember vinyl are enjoying that kind of experience. Do you have a piece of vinyl that you treasure? The truth is I got rid of 100% of my vinyl in the 90s. All the vinyl I have is re-bought. I started off from the perspective that I wanted to recreate the collection I had when I was 15, but it's gone beyond that. The first record which I persuaded my parents to buy for me was Electric Light Orchestra's Out of the Blue.", "ro": "E ceva ce poți ține în mână, în timp ce te lași absorbit de versuri și copleșit de actul artistic. Am crezut că e doar o chestie nostalgică, însă nu are cum să fie așa dacă unor puști prea tineri să-și amintească de viniluri le place acest gen de experiență. Ai vreun vinil la care ții în mod special? Recunosc că am scăpat de toate vinilurile în anii '90. Toate vinilurile pe care le am sunt cumpărate din nou. Am pornit de la ideea de a reface colecția pe care o aveam la 15 ani, însă am trecut de limita aceea. Primul disc pe care mi-am convins părinții să mi-l cumpere a fost Out of the Blue de la Electric Light Orchestra." } }
-{ "translation": { "en": "If I still had my original copy, it would have sentimental value, but, alas, it's in a charity shop somewhere. Steven Wilson hopes the album will be a doorway for potential new fans Why release your new compilation Transience on vinyl? It was originally conceived as an idea for Record Store Day, but we missed the boat on that. My record company had suggested I put together some of my shorter, more accessible songs. I got a bit obsessed by the idea to make something like \"an introduction to Steven Wilson,\" and I was committed to it being a vinyl-only release. Anyone who buys the vinyl does also get a high-resolution download.", "ro": "Dacă aș mai fi avut încă exemplarul inițial, acesta ar fi avut valoare sentimentală, însă, din păcate, se află pe undeva printr-un magazin de caritate. Steven Wilson speră că albumul va fi o poartă către posibili fani noi De ce ți-ai lansat noua compilație Transience pe vinil? Aceasta a fost concepută inițial ca idee pentru Ziua magazinelor de discuri, însă am ratat ocazia. Casa mea de discuri sugerase să adun câteva dintre melodiile mele mai scurte și mai accesibile. Am ajuns să fiu ușor obsedat de ideea de a face ceva gen „introducere în muzica lui Steven Wilson” și am ținut neapărat ca proiectul să fie lansat doar pe vinil. Cine cumpără vinilul primește, de asemenea, și o variantă descărcată la rezoluție înaltă." } }
-{ "translation": { "en": "Do you have a concern that the album won't show your work in a true light?", "ro": "Ești îngrijorat că albumul nu va arăta muzica ta în adevărata ei lumină?" } }
diff --git a/tests/fixtures/tests_samples/xsum/sample.json b/tests/fixtures/tests_samples/xsum/sample.json
deleted file mode 100644
index ea6e8a8bb8f6..000000000000
--- a/tests/fixtures/tests_samples/xsum/sample.json
+++ /dev/null
@@ -1,10 +0,0 @@
-{"document": "The warning begins at 22:00 GMT on Saturday and ends at 10:00 on Sunday.\nThe ice could lead to difficult driving conditions on untreated roads and slippery conditions on pavements, the weather service warned.\nOnly the southernmost counties and parts of the most westerly counties are expected to escape.\nCounties expected to be affected are Carmarthenshire, Powys, Ceredigion, Pembrokeshire, Denbighshire, Gwynedd, Wrexham, Conwy, Flintshire, Anglesey, Monmouthshire, Blaenau Gwent, Caerphilly, Merthyr Tydfil, Neath Port Talbot, Rhondda Cynon Taff and Torfaen.", "summary": "The Met Office has issued a yellow weather warning for ice across most of Wales."}
-{"document": "You can see highlights of Sunderland v Arsenal on Match of the Day at 22:20 BST on Saturday on BBC One and the BBC Sport website.\nStoke and West Ham, for example, have started to climb away from the relegation zone but the biggest worry for Sunderland fans is that their side do not look remotely capable of doing the same.\nI know the Black Cats have got out of trouble before having found themselves in a similar situation but this time, after picking up only two points from their first nine games, things look really desperate for the only top-flight team without a win.\nAt least one element of their struggles seems to be self-inflicted, with everyone at the club feeling sorry for themselves - and not just because they have lost some players to injury and conceded some costly late goals.\nThere is a negative feeling about the place with the manager David Moyes and his players talking about how they have gone backwards since last season, when they should be searching for any kind of spark that could change things around.\nFrom the outside, looking at the way they play and their lack of creativity, it is hard to see what that spark might be or what could fundamentally change under Moyes until the January transfer window opens.\nIf they can get one win under their belt then they will get a bit of belief back but, the longer this winless run goes on, the more negativity there will be.\nMedia playback is not supported on this device\nSunderland finished last season on a high under Sam Allardyce, with a run of just one defeat in their last 11 games securing their safety.\nIn the space of five months, all of that confidence and momentum seems to have been sucked out of the club, despite them effectively having the same group of players who, not so long ago, looked inspired.\nThat is not all down to Moyes, but he has to take some responsibility for it.\nI am yet to see a defined style of play from Sunderland since he took charge at the end of July.\nThat is in contrast to Allardyce's time as manager, when they were resolute and difficult to beat and, at the end of his stint at the Stadium of Light, also played with a purpose when they went forward.\nOff the pitch, Moyes has not helped himself much either.\nThere was no need for him to be so pessimistic when he came out after the second game of the season and announced they would be in a relegation fight, which did not send out the right message to his players or the fans.\nWhen he took charge, he had actually started out by being unrealistically positive - talking about Sunderland becoming a club that regularly finished in the top half of the Premier League - but his expectations went downhill very quickly.\nI know you can argue that he has been proved right, because Sunderland are now battling the drop, but it meant there was a cloud over from them almost as soon as the season had started.\nIt seems to be a case that if you stop Jermain Defoe, you stop Sunderland. His statistics stand up well in comparison to last season, but the rest of their team are not doing enough in attack.\nThey were reliant on Defoe last season too, but others did chip in - in their first nine league games of 2015-16, five players found the net. This time around, only Defoe and Patrick van Aanholt have scored in the same period.\nIt is going to be a massive struggle for them to stay up from the position they are now in anyway, but they badly need a win and quickly. I don't see it coming at home to Arsenal on Saturday, though.\nDo they even look capable of holding out for a draw against the Gunners, the way another struggling team Middlesbrough did at Emirates Stadium last weekend? No.\nIf you struggle to make chances and score goals, as Sunderland do, that puts more pressure on your defence because you know if you concede then you are in big trouble.\nAnd the Black Cats have problems at the back as well - their only clean sheet in 12 matches under Moyes was against League One side Shrewsbury Town in the EFL Cup.\nIt does not bode well against an Arsenal side that are averaging more than two goals a game this season.\nIt is hard to find any positives from Sunderland's situation but at least they have not been cut adrift at the bottom - yet.\nUnless they win soon, that could happen. I think Hull are also in for a very tough season but when I look at the other two teams immediately above them, Boro and Swansea, they definitely have more about them than the Black Cats do.\nMedia playback is not supported on this device\nChanging manager has clearly not helped Sunderland and comparisons with his predecessor do not help Moyes much either.\nYou cannot tell me that, if Allardyce was still in charge, Sunderland would have only picked up two points so far. It just would not have happened.\nMoyes replaced him relatively late in the summer, which is difficult in itself, but he can only complain about the things that have gone against him up to a point. He should be doing much better than he is.\nHe is still the manager and he is capable of turning things around, so it is right there is no suggestion of him getting the sack.\nBut that will not last forever. This industry is results-driven and Moyes' results are not good enough.\nThat clearly has to change soon and, looking at Sunderland's next few fixtures, the one that stands out as a must-win is their home game against Hull on 19 November.\nIf they fail to beat Arsenal and Bournemouth, then the visit of the Tigers will be the game to define Moyes' tenure. If Sunderland are still without a win after that, things will become extremely difficult for him.\nChris Sutton was speaking to BBC Sport's Chris Bevan.", "summary": "We are exactly a quarter of the way through the Premier League season and some teams at the bottom of the table seem to be turning things around after making a bad start."}
-{"document": "The win keeps the Candystripes two points behind leaders Dundalk who won 2-0 away to Shamrock Rovers.\nFormer Plymouth striker Patterson scored his sixth goal of the season in the 14th minute at the Brandywell.\nHe shot into an empty net after the ball broke to him when keeper Dean Delany thwarted Barry McNamee.\nKurtis Byrne should have netted a speedy equaliser but the son of former Celtic player Paul Byrne completely missed his kick in front of goal.\nThat was the one big scare for Kenny Shiels' men on a night when both keepers had a quiet night.\nDerry City have won six and drawn two in the eight games they have played since losing to Finn Harps on the first day of the season.", "summary": "Rory Patterson's early goal proved enough to give second-placed Derry City a home victory over Bohemians in Friday night's Premier Division clash."}
-{"document": "The centre-right coalition led by Mr Passos Coelho won the most seats in the election on 4 October.\nBut Socialist leader Antonio Costa has been working to build a coalition with far-left parties.\nMany believe that Mr Passos Coelho will fail to pass the test of a vote of no confidence in Portugal's parliament.\nPresident Anibal Cavaco Silva would then be expected to ask the left to form a government.\nThere are fears that weeks of uncertainty could harm Portugal's economic recovery, more than a year after it exited the strict terms of its €78bn (£57bn) international bailout.\nEU officials have threatened to take action against Portugal for missing a 15 October deadline to present its draft 2016 budget.\nPortugal is still running one of the highest budget deficits in the eurozone.\n12%\nof the workforce is unemployed\n20%\nof people live below the poverty line\n485,000 emigrated from Portugal between 2011 and 2014\n125% debt to GDP - the second highest rate in the European Union\nMr Passos Coelho's Social Democrats have promised to present a budget, but the two left-wing parties campaigned strongly against his outgoing government's record of harsh austerity.\nThe Left Bloc is seen as allied to the anti-austerity Syriza party in Greece, which for months tried to renegotiate the terms of Greece's eurozone bailout.\nPortugal's Communist Party is regarded as anti-euro and anti-Nato, although it is thought to have moderated its eurozone policies in recent weeks.\nIf Mr Costa's Socialists are eventually chosen to lead a left-wing coalition, it would be the first time since the fall of Portugal's dictatorship in 1974 that a right-wing president appointed a government backed by communists.\nAfter his re-appointment as prime minister leading a right-of-centre coalition, Pedro Passos Coelho has 10 days to appoint ministers and secure parliamentary approval.\nThat may prove impossible, since his coalition lost its majority in the 4 October election and the Socialists have pledged to reject his programme if their talks with other parties succeed.\nTogether, the Socialists, Left Bloc and Communist Party have a majority. All wanted the president to appoint Mr Costa - arguing that anything else was a waste of time.\nIf Mr Passos Coelho does fail, the president could then appoint Mr Costa or keep the incumbent on as caretaker.\nFresh legislative elections may only take place from June, after voters have elected a new president early next year.", "summary": "The Portuguese president has invited incumbent Prime Minister Pedro Passos Coelho to form the next government, despite him having lost his majority."}
-{"document": "Nev Edwards scored an early try for Sale, before Castres' Florian Vialelle went over, but Julien Dumora's penalty put the hosts 10-7 ahead at the break.\nJoe Ford sent over a penalty before Castres' Marc-Antoine Rallier and Sales' Will Addison were sin-binned.\nJulien Caminati's late attempt to stop Charlie Ingall saw Sale awarded the decisive penalty try.\nThe win moves the English Premiership side to within one point of Pool Two leaders Newport Gwent Dragons after three games.\nSale got off to the ideal start, Edwards sprinting away for the game's opening points from an Andrei Ostrikov kick, but Castres heaped the pressure on in search of a reply, which came through Vialelle on eight minutes.\nSharks flanker Magnus Lund was forced off with a head injury before the television match official denied Castres a second try, with replays showing that the Sharks defence did enough to force full-back Caminati into touch.\nFord had a chance to put Sale ahead again, but his penalty on 27 minutes drifted wide. Dumora, however, made no mistake soon after, slotting over to give the French side the lead on 33 minutes.\nA combination of probing grubber kicks and scrappy play eventually led to Ford teeing up his second penalty attempt, with the fly-half this time booting the three points to make it 10-10.\nRallier's yellow card following a scuffle saw Ford opt for the posts soon after, but he was off target again before Sales' one-man advantage was lost as Addison was sin-binned.\nSharks pushed for the breakthrough as Ingall went close to touching down, and the video referee eventually gave the penalty try after deciding that Caminati's attempt to stop the winger was illegal.\nCastres: Caminati; Martial, Vialelle, Combezou, Decrop; Dumora, Dupont; Taumoepeau, Rallier, Montes; Samson, Moreaux, Caballero, Diarra, Beattie.\nReplacements: Beziat, Tichit, Martinez, Desroche, Babillot, Fontaine, Lamerat, Seron.\nSale: Arscott; Edwards, Addison, Jennings, Ingall; Ford, Mitchell, Lewis-Roberts, Briggs, Mujati, Mills, Ostrikov, Lund, Seymour (capt), Easter.\nReplacements: Taylor, Flynn, Parker, Beaumont, Neild, Jeffers, James, Haley.\nReferee: David Wilkinson (Ireland)", "summary": "A late penalty try gave Sale victory over Castres at Stade Pierre-Antoine in their European Challenge Cup clash."}
-{"document": "The 33-year-old was released by Norwich this summer after five years at the club, during which time he made 75 Canaries first-team appearances.\nTurner also had spells on loan at Fulham and Sheffield Wednesday during his time at Carrow Road.\nIn total, the centre-back has made 436 senior career appearances for eight different clubs.\nFind all the latest football transfers on our dedicated page.", "summary": "League One side Southend United have signed former Hull and Norwich defender Michael Turner on a one-year deal."}
-{"document": "United contacted St Johnstone this week with a view to speaking to 52-year-old Wright about the job but this approach was rejected by the Saints board.\nThe Tannadice club - bottom of the Premiership - are seeking to replace Jackie McNamara, who left last month.\nDave Bowman took the first team for Saturday's loss to Partick Thistle.\nThe Tangerines have won only once this season and prop up the table with five points from 10 games.\nFormer Northern Ireland goalkeeper Wright, who replaced Steve Lomas at McDiarmid Park in 2013, led St Johnstone to Scottish Cup success in his first season in charge.\nHe has also secured two successive top-six finishes for the Perth side and previously managed in his homeland.", "summary": "St Johnstone boss Tommy Wright is no longer under consideration for the Dundee United manager's job, BBC Scotland has learned."}
-{"document": "Media playback is unsupported on your device\n2 November 2014 Last updated at 17:20 GMT\nHomes and businesses were damaged in the storm, but weather experts were not able to confirm it was a tornado.\nNavtej Johal reports.", "summary": "Residents in Coalville in Leicestershire are cleaning up after high winds hit the town."}
-{"document": "5 August 2015 Last updated at 06:36 BST\nShe's now 84 and has been telling Newsround the inspiring story of her life before and after that devastating and world-changing event.\nThis animation contains some sad moments that you might find upsetting.\nYou can find out more about what happened in Hiroshima here.\nWatch 'Hiroshima: A Newsround Special' - Thursday 6 August at 5.30pm on the CBBC channel and on the Newsround website.", "summary": "Bun Hashizume was 14 years old and lived in Hiroshima, in Japan, when a nuclear bomb was dropped on the city 70 years ago, at the end of World War Two."}
-{"document": "But what has been your moment of the year?\nFrom Ben Stokes' 258 off 198 balls against South Africa to Stuart Broad's 6-17 against the same opponents, and Alastair Cook being the first Englishman to reach 10,000 Test runs, there are lots of highlights.\nOr perhaps you revelled in Australia being skittled for just 85? Or the dog that invaded the pitch at Vizag?\nThe cricket brains of BBC Sport and BBC Radio 5 live asked you to rank your top 10, and your shortlist will be revealed on Tuesday's Tuffers and Vaughan Cricket Show (20:30 GMT, BBC Radio 5 live and online).\nVotes will no longer count but you can still pick your top 10 and share with friends.\nWhat are your top 10 cricketing moments from this year?", "summary": "It's been topsy-turvy for the England side but eventful and entertaining nonetheless."}
diff --git a/tests/repo_utils/test_tests_fetcher.py b/tests/repo_utils/test_tests_fetcher.py
index 76219008b031..ee9f26dda5eb 100644
--- a/tests/repo_utils/test_tests_fetcher.py
+++ b/tests/repo_utils/test_tests_fetcher.py
@@ -45,7 +45,6 @@
get_repo_utils_tests,
get_tree_starting_at,
infer_tests_to_run,
- init_test_examples_dependencies,
parse_commit_message,
print_tree_deps_of,
should_run_conftest_tests,
@@ -155,18 +154,7 @@ def create_tmp_repo(tmp_dir, models=None):
f"from transformers import {cls}Config, {cls}Model\nfrom ...test_modeling_common import ModelTesterMixin\n\ncode"
)
- example_dir = tmp_dir / "examples"
- example_dir.mkdir(exist_ok=True)
- framework_dir = example_dir / "pytorch"
- framework_dir.mkdir(exist_ok=True)
- with open(framework_dir / "test_pytorch_examples.py", "w", encoding="utf-8") as f:
- f.write("""test_args = "run_glue.py"\n""")
- glue_dir = framework_dir / "text-classification"
- glue_dir.mkdir(exist_ok=True)
- with open(glue_dir / "run_glue.py", "w", encoding="utf-8") as f:
- f.write("from transformers import BertModel\n\ncode")
-
- repo.index.add(["examples", "src", "tests"])
+ repo.index.add(["src", "tests"])
repo.index.commit("Initial commit")
if "main" not in repo.heads:
repo.create_head("main")
@@ -183,14 +171,12 @@ def patch_transformer_repo_path(new_folder):
"""
old_repo_path = tests_fetcher.PATH_TO_REPO
tests_fetcher.PATH_TO_REPO = Path(new_folder).resolve()
- tests_fetcher.PATH_TO_EXAMPLES = tests_fetcher.PATH_TO_REPO / "examples"
tests_fetcher.PATH_TO_TRANSFORMERS = tests_fetcher.PATH_TO_REPO / "src/transformers"
tests_fetcher.PATH_TO_TESTS = tests_fetcher.PATH_TO_REPO / "tests"
try:
yield
finally:
tests_fetcher.PATH_TO_REPO = old_repo_path
- tests_fetcher.PATH_TO_EXAMPLES = tests_fetcher.PATH_TO_REPO / "examples"
tests_fetcher.PATH_TO_TRANSFORMERS = tests_fetcher.PATH_TO_REPO / "src/transformers"
tests_fetcher.PATH_TO_TESTS = tests_fetcher.PATH_TO_REPO / "tests"
@@ -525,17 +511,6 @@ def test_get_module_dependencies(self):
with patch_transformer_repo_path(tmp_folder):
assert get_module_dependencies(BERT_MODELING_FILE) == expected_bert_dependencies
- # Test with an example
- create_tmp_repo(tmp_folder)
-
- expected_example_dependencies = ["src/transformers/models/bert/modeling_bert.py"]
-
- with patch_transformer_repo_path(tmp_folder):
- assert (
- get_module_dependencies("examples/pytorch/text-classification/run_glue.py")
- == expected_example_dependencies
- )
-
def test_create_reverse_dependency_tree(self):
with tempfile.TemporaryDirectory() as tmp_folder:
tmp_folder = Path(tmp_folder)
@@ -621,28 +596,6 @@ def test_print_tree_deps_of(self):
assert cs.out.strip() in [expected_std_out, expected_std_out_2]
- def test_init_test_examples_dependencies(self):
- with tempfile.TemporaryDirectory() as tmp_folder:
- tmp_folder = Path(tmp_folder).resolve()
- create_tmp_repo(tmp_folder)
-
- expected_example_deps = {
- "examples/pytorch/test_pytorch_examples.py": [
- "examples/pytorch/text-classification/run_glue.py",
- "examples/pytorch/test_pytorch_examples.py",
- ],
- }
-
- expected_examples = {
- "examples/pytorch/test_pytorch_examples.py",
- "examples/pytorch/text-classification/run_glue.py",
- }
-
- with patch_transformer_repo_path(tmp_folder):
- example_deps, all_examples = init_test_examples_dependencies()
- assert example_deps == expected_example_deps
- assert {str(f.relative_to(tmp_folder)) for f in all_examples} == expected_examples
-
def test_create_reverse_dependency_map(self):
with tempfile.TemporaryDirectory() as tmp_folder:
tmp_folder = Path(tmp_folder)
@@ -655,8 +608,6 @@ def test_create_reverse_dependency_map(self):
"src/transformers/__init__.py",
"src/transformers/models/bert/__init__.py",
"tests/models/bert/test_modeling_bert.py",
- "examples/pytorch/test_pytorch_examples.py",
- "examples/pytorch/text-classification/run_glue.py",
}
assert set(reverse_map["src/transformers/models/bert/modeling_bert.py"]) == expected_bert_deps
@@ -672,8 +623,6 @@ def test_create_reverse_dependency_map(self):
"src/transformers/modeling_utils.py",
"tests/test_modeling_common.py",
"tests/models/bert/test_modeling_bert.py",
- "examples/pytorch/test_pytorch_examples.py",
- "examples/pytorch/text-classification/run_glue.py",
}
assert set(reverse_map["src/transformers/__init__.py"]) == expected_init_deps
@@ -682,8 +631,6 @@ def test_create_reverse_dependency_map(self):
"src/transformers/models/bert/configuration_bert.py",
"src/transformers/models/bert/modeling_bert.py",
"tests/models/bert/test_modeling_bert.py",
- "examples/pytorch/test_pytorch_examples.py",
- "examples/pytorch/text-classification/run_glue.py",
}
assert set(reverse_map["src/transformers/models/bert/__init__.py"]) == expected_init_deps
@@ -698,8 +645,6 @@ def test_create_reverse_dependency_map(self):
"src/transformers/models/bert/configuration_bert.py",
"src/transformers/models/bert/modeling_bert.py",
"tests/models/bert/test_modeling_bert.py",
- "examples/pytorch/test_pytorch_examples.py",
- "examples/pytorch/text-classification/run_glue.py",
}
assert set(reverse_map["src/transformers/models/bert/__init__.py"]) == expected_init_deps
@@ -774,19 +719,12 @@ def test_infer_tests_to_run(self):
commit_changes("src/transformers/models/bert/modeling_bert.py", BERT_MODEL_FILE_NEW_CODE, repo)
- example_tests = {
- "examples/pytorch/test_pytorch_examples.py",
- }
-
with patch_transformer_repo_path(tmp_folder):
infer_tests_to_run(tmp_folder / "test-output.txt", diff_with_last_commit=True)
with open(tmp_folder / "test-output.txt", encoding="utf-8") as f:
tests_to_run = f.read()
- with open(tmp_folder / "examples_test_list.txt", encoding="utf-8") as f:
- example_tests_to_run = f.read()
assert tests_to_run == "tests/models/bert/test_modeling_bert.py"
- assert set(example_tests_to_run.split(" ")) == example_tests
# Fake a new model addition
repo = create_tmp_repo(tmp_folder, models=models)
@@ -823,8 +761,6 @@ def test_infer_tests_to_run(self):
infer_tests_to_run(tmp_folder / "test-output.txt")
with open(tmp_folder / "test-output.txt", encoding="utf-8") as f:
tests_to_run = f.read()
- with open(tmp_folder / "examples_test_list.txt", encoding="utf-8") as f:
- example_tests_to_run = f.read()
expected_tests = {
"tests/models/bert/test_modeling_bert.py",
@@ -833,19 +769,15 @@ def test_infer_tests_to_run(self):
"tests/test_modeling_common.py",
}
assert set(tests_to_run.split(" ")) == expected_tests
- assert set(example_tests_to_run.split(" ")) == example_tests
with patch_transformer_repo_path(tmp_folder):
infer_tests_to_run(tmp_folder / "test-output.txt")
with open(tmp_folder / "test-output.txt", encoding="utf-8") as f:
tests_to_run = f.read()
- with open(tmp_folder / "examples_test_list.txt", encoding="utf-8") as f:
- example_tests_to_run = f.read()
expected_tests = [f"tests/models/{name}/test_modeling_{name}.py" for name in models + ["t5"]]
expected_tests = set(expected_tests + ["tests/test_modeling_common.py"])
assert set(tests_to_run.split(" ")) == expected_tests
- assert set(example_tests_to_run.split(" ")) == example_tests
@unittest.skip("Broken for now TODO @ArthurZucker")
def test_infer_tests_to_run_with_test_modifs(self):
@@ -867,42 +799,6 @@ def test_infer_tests_to_run_with_test_modifs(self):
assert tests_to_run == "tests/models/bert/test_modeling_bert.py"
- @unittest.skip("Broken for now TODO @ArthurZucker")
- def test_infer_tests_to_run_with_examples_modifs(self):
- with tempfile.TemporaryDirectory() as tmp_folder:
- tmp_folder = Path(tmp_folder)
- models = ["bert", "gpt2"]
- repo = create_tmp_repo(tmp_folder, models=models)
-
- # Modification in one example trigger the corresponding test
- commit_changes(
- "examples/pytorch/text-classification/run_glue.py",
- "from transformers import BertModeln\n\ncode1",
- repo,
- )
-
- with patch_transformer_repo_path(tmp_folder):
- infer_tests_to_run(tmp_folder / "test-output.txt", diff_with_last_commit=True)
- with open(tmp_folder / "examples_test_list.txt", encoding="utf-8") as f:
- example_tests_to_run = f.read()
-
- assert example_tests_to_run == "examples/pytorch/test_pytorch_examples.py"
-
- # Modification in one test example file trigger that test
- repo = create_tmp_repo(tmp_folder, models=models)
- commit_changes(
- "examples/pytorch/test_pytorch_examples.py",
- """test_args = "run_glue.py"\nmore_code""",
- repo,
- )
-
- with patch_transformer_repo_path(tmp_folder):
- infer_tests_to_run(tmp_folder / "test-output.txt", diff_with_last_commit=True)
- with open(tmp_folder / "examples_test_list.txt", encoding="utf-8") as f:
- example_tests_to_run = f.read()
-
- assert example_tests_to_run == "examples/pytorch/test_pytorch_examples.py"
-
def test_parse_commit_message(self):
assert parse_commit_message("Normal commit") == {"skip": False, "no_filter": False, "test_all": False}
diff --git a/tests/sagemaker/scripts/pytorch/run_ddp.py b/tests/sagemaker/scripts/pytorch/run_ddp.py
deleted file mode 100644
index 474285841b0d..000000000000
--- a/tests/sagemaker/scripts/pytorch/run_ddp.py
+++ /dev/null
@@ -1,52 +0,0 @@
-import json
-import logging
-import os
-import subprocess
-from argparse import ArgumentParser
-
-
-logger = logging.getLogger(__name__)
-
-
-def parse_args():
- parser = ArgumentParser()
- parsed, unknown = parser.parse_known_args()
- for arg in unknown:
- if arg.startswith(("-", "--")):
- parser.add_argument(arg.split("=")[0])
-
- return parser.parse_args()
-
-
-def main():
- args = parse_args()
- port = 8888
- num_gpus = int(os.environ["SM_NUM_GPUS"])
- hosts = json.loads(os.environ["SM_HOSTS"])
- num_nodes = len(hosts)
- current_host = os.environ["SM_CURRENT_HOST"]
- rank = hosts.index(current_host)
- os.environ["NCCL_DEBUG"] = "INFO"
-
- if num_nodes > 1:
- cmd = f"""python -m torch.distributed.launch \
- --nnodes={num_nodes} \
- --node_rank={rank} \
- --nproc_per_node={num_gpus} \
- --master_addr={hosts[0]} \
- --master_port={port} \
- ./run_glue.py \
- {"".join([f" --{parameter} {value}" for parameter, value in args.__dict__.items()])}"""
- else:
- cmd = f"""python -m torch.distributed.launch \
- --nproc_per_node={num_gpus} \
- ./run_glue.py \
- {"".join([f" --{parameter} {value}" for parameter, value in args.__dict__.items()])}"""
- try:
- subprocess.run(cmd, shell=True)
- except Exception as e:
- logger.info(e)
-
-
-if __name__ == "__main__":
- main()
diff --git a/tests/sagemaker/test_multi_node_data_parallel.py b/tests/sagemaker/test_multi_node_data_parallel.py
deleted file mode 100644
index a537be890a5d..000000000000
--- a/tests/sagemaker/test_multi_node_data_parallel.py
+++ /dev/null
@@ -1,99 +0,0 @@
-import json
-import os
-import subprocess
-import unittest
-from ast import literal_eval
-
-import pytest
-from parameterized import parameterized, parameterized_class
-
-from . import is_sagemaker_available
-
-
-if is_sagemaker_available():
- from sagemaker import Session, TrainingJobAnalytics
- from sagemaker.huggingface import HuggingFace
-
-
-@pytest.mark.skipif(
- literal_eval(os.getenv("TEST_SAGEMAKER", "False")) is not True,
- reason="Skipping test because should only be run when releasing minor transformers version",
-)
-@pytest.mark.usefixtures("sm_env")
-@parameterized_class(
- [
- {
- "script": "run_glue.py",
- "model_name_or_path": "distilbert/distilbert-base-cased",
- "instance_type": "ml.p3.16xlarge",
- "results": {"train_runtime": 650, "eval_accuracy": 0.7, "eval_loss": 0.6},
- },
- {
- "script": "run_ddp.py",
- "model_name_or_path": "distilbert/distilbert-base-cased",
- "instance_type": "ml.p3.16xlarge",
- "results": {"train_runtime": 600, "eval_accuracy": 0.7, "eval_loss": 0.6},
- },
- ]
-)
-class MultiNodeTest(unittest.TestCase):
- def setUp(self):
- subprocess.run(
- f"cp ./examples/pytorch/text-classification/run_glue.py {self.env.test_path}/run_glue.py".split(),
- encoding="utf-8",
- check=True,
- )
- assert hasattr(self, "env")
-
- def create_estimator(self, instance_count):
- job_name = f"{self.env.base_job_name}-{instance_count}-{'ddp' if 'ddp' in self.script else 'smd'}"
- # distributed data settings
- distribution = {"smdistributed": {"dataparallel": {"enabled": True}}} if self.script != "run_ddp.py" else None
-
- # creates estimator
- return HuggingFace(
- entry_point=self.script,
- source_dir=self.env.test_path,
- role=self.env.role,
- image_uri=self.env.image_uri,
- base_job_name=job_name,
- instance_count=instance_count,
- instance_type=self.instance_type,
- debugger_hook_config=False,
- hyperparameters={**self.env.distributed_hyperparameters, "model_name_or_path": self.model_name_or_path},
- metric_definitions=self.env.metric_definitions,
- distribution=distribution,
- py_version="py36",
- )
-
- def save_results_as_csv(self, job_name):
- TrainingJobAnalytics(job_name).export_csv(f"{self.env.test_path}/{job_name}_metrics.csv")
-
- # @parameterized.expand([(2,), (4,),])
- @parameterized.expand([(2,)])
- def test_script(self, instance_count):
- # create estimator
- estimator = self.create_estimator(instance_count)
-
- # run training
- estimator.fit()
-
- # result dataframe
- result_metrics_df = TrainingJobAnalytics(estimator.latest_training_job.name).dataframe()
-
- # extract kpis
- eval_accuracy = list(result_metrics_df[result_metrics_df.metric_name == "eval_accuracy"]["value"])
- eval_loss = list(result_metrics_df[result_metrics_df.metric_name == "eval_loss"]["value"])
- # get train time from SageMaker job, this includes starting, preprocessing, stopping
- train_runtime = (
- Session().describe_training_job(estimator.latest_training_job.name).get("TrainingTimeInSeconds", 999999)
- )
-
- # assert kpis
- assert train_runtime <= self.results["train_runtime"]
- assert all(t >= self.results["eval_accuracy"] for t in eval_accuracy)
- assert all(t <= self.results["eval_loss"] for t in eval_loss)
-
- # dump tests result into json file to share in PR
- with open(f"{estimator.latest_training_job.name}.json", "w", encoding="utf-8") as outfile:
- json.dump({"train_time": train_runtime, "eval_accuracy": eval_accuracy, "eval_loss": eval_loss}, outfile)
diff --git a/tests/sagemaker/test_multi_node_model_parallel.py b/tests/sagemaker/test_multi_node_model_parallel.py
index d5ed6145a38c..76cd0648dcda 100644
--- a/tests/sagemaker/test_multi_node_model_parallel.py
+++ b/tests/sagemaker/test_multi_node_model_parallel.py
@@ -1,6 +1,5 @@
import json
import os
-import subprocess
import unittest
from ast import literal_eval
@@ -28,21 +27,10 @@
"instance_type": "ml.p3dn.24xlarge",
"results": {"train_runtime": 1600, "eval_accuracy": 0.3, "eval_loss": 1.2},
},
- {
- "script": "run_glue.py",
- "model_name_or_path": "FacebookAI/roberta-large",
- "instance_type": "ml.p3dn.24xlarge",
- "results": {"train_runtime": 1600, "eval_accuracy": 0.3, "eval_loss": 1.2},
- },
]
)
class MultiNodeTest(unittest.TestCase):
def setUp(self):
- subprocess.run(
- f"cp ./examples/pytorch/text-classification/run_glue.py {self.env.test_path}/run_glue.py".split(),
- encoding="utf-8",
- check=True,
- )
assert hasattr(self, "env")
def create_estimator(self, instance_count):
@@ -65,14 +53,13 @@ def create_estimator(self, instance_count):
distribution = {"smdistributed": {"modelparallel": smp_options}, "mpi": mpi_options}
- name_extension = "trainer" if self.script == "run_glue.py" else "smtrainer"
# creates estimator
return HuggingFace(
entry_point=self.script,
source_dir=self.env.test_path,
role=self.env.role,
image_uri=self.env.image_uri,
- base_job_name=f"{self.env.base_job_name}-{instance_count}-smp-{name_extension}",
+ base_job_name=f"{self.env.base_job_name}-{instance_count}-smp-smtrainer",
instance_count=instance_count,
instance_type=self.instance_type,
debugger_hook_config=False,
diff --git a/tests/sagemaker/test_single_node_gpu.py b/tests/sagemaker/test_single_node_gpu.py
deleted file mode 100644
index 8b3e828995e6..000000000000
--- a/tests/sagemaker/test_single_node_gpu.py
+++ /dev/null
@@ -1,86 +0,0 @@
-import json
-import os
-import subprocess
-import unittest
-from ast import literal_eval
-
-import pytest
-from parameterized import parameterized_class
-
-from . import is_sagemaker_available
-
-
-if is_sagemaker_available():
- from sagemaker import Session, TrainingJobAnalytics
- from sagemaker.huggingface import HuggingFace
-
-
-@pytest.mark.skipif(
- literal_eval(os.getenv("TEST_SAGEMAKER", "False")) is not True,
- reason="Skipping test because should only be run when releasing minor transformers version",
-)
-@pytest.mark.usefixtures("sm_env")
-@parameterized_class(
- [
- {
- "script": "run_glue.py",
- "model_name_or_path": "distilbert/distilbert-base-cased",
- "instance_type": "ml.g4dn.xlarge",
- "results": {"train_runtime": 650, "eval_accuracy": 0.6, "eval_loss": 0.9},
- },
- ]
-)
-class SingleNodeTest(unittest.TestCase):
- def setUp(self):
- subprocess.run(
- f"cp ./examples/pytorch/text-classification/run_glue.py {self.env.test_path}/run_glue.py".split(),
- encoding="utf-8",
- check=True,
- )
- assert hasattr(self, "env")
-
- def create_estimator(self, instance_count=1):
- # creates estimator
- return HuggingFace(
- entry_point=self.script,
- source_dir=self.env.test_path,
- role=self.env.role,
- image_uri=self.env.image_uri,
- base_job_name=f"{self.env.base_job_name}-single",
- instance_count=instance_count,
- instance_type=self.instance_type,
- debugger_hook_config=False,
- hyperparameters={**self.env.hyperparameters, "model_name_or_path": self.model_name_or_path},
- metric_definitions=self.env.metric_definitions,
- py_version="py36",
- )
-
- def save_results_as_csv(self, job_name):
- TrainingJobAnalytics(job_name).export_csv(f"{self.env.test_path}/{job_name}_metrics.csv")
-
- def test_glue(self):
- # create estimator
- estimator = self.create_estimator()
-
- # run training
- estimator.fit()
-
- # result dataframe
- result_metrics_df = TrainingJobAnalytics(estimator.latest_training_job.name).dataframe()
-
- # extract kpis
- eval_accuracy = list(result_metrics_df[result_metrics_df.metric_name == "eval_accuracy"]["value"])
- eval_loss = list(result_metrics_df[result_metrics_df.metric_name == "eval_loss"]["value"])
- # get train time from SageMaker job, this includes starting, preprocessing, stopping
- train_runtime = (
- Session().describe_training_job(estimator.latest_training_job.name).get("TrainingTimeInSeconds", 999999)
- )
-
- # assert kpis
- assert train_runtime <= self.results["train_runtime"]
- assert all(t >= self.results["eval_accuracy"] for t in eval_accuracy)
- assert all(t <= self.results["eval_loss"] for t in eval_loss)
-
- # dump tests result into json file to share in PR
- with open(f"{estimator.latest_training_job.name}.json", "w", encoding="utf-8") as outfile:
- json.dump({"train_time": train_runtime, "eval_accuracy": eval_accuracy, "eval_loss": eval_loss}, outfile)
diff --git a/tests/trainer/distributed/scripts/vit_feature_extractor.json b/tests/trainer/distributed/scripts/vit_feature_extractor.json
deleted file mode 100644
index e73176d74e12..000000000000
--- a/tests/trainer/distributed/scripts/vit_feature_extractor.json
+++ /dev/null
@@ -1,4 +0,0 @@
-{
- "image_processor_type": "ViTImageProcessor",
- "size": 30
-}
diff --git a/tests/trainer/distributed/test_trainer_distributed_deepspeed.py b/tests/trainer/distributed/test_trainer_distributed_deepspeed.py
index 3c1ebce6cb84..7a002004d315 100644
--- a/tests/trainer/distributed/test_trainer_distributed_deepspeed.py
+++ b/tests/trainer/distributed/test_trainer_distributed_deepspeed.py
@@ -23,7 +23,6 @@
import itertools
import json
import os
-import subprocess
import unittest
from copy import deepcopy
from functools import partial
@@ -45,7 +44,6 @@
TestCasePlus,
backend_device_count,
execute_subprocess_async,
- get_tests_dir,
get_torch_dist_unique_port,
mockenv_context,
read_json_file,
@@ -1065,8 +1063,7 @@ class TestTrainerDistributedDeepSpeedCommon(DeepSpeedCommandsMixin, TrainerDistr
"""
Distributed DeepSpeed tests using ``accelerate launch``.
- Some tests use a simple training script (train.py), others use example
- scripts (run_translation.py, run_clm.py) for broader integration coverage.
+ Some tests use a simple training script (train.py).
"""
# -------------------------------------------------------------------
@@ -1579,128 +1576,3 @@ def test_zero3_load_registered_buffers(self):
self.assertEqual(buf.item(), -42.0, f"{name} was not loaded from checkpoint")
elif "layer_scalar" in name:
self.assertEqual(buf.item(), 0.5, f"{name} was not loaded from checkpoint")
-
-
-# ---------------------------------------------------------------------------
-# Model Zoo — test many architectures with DeepSpeed + zero_to_fp32 recovery
-# ---------------------------------------------------------------------------
-
-_ZOO_MODELS = {
- "albert": "hf-internal-testing/tiny-albert",
- "bart": "sshleifer/bart-tiny-random",
- "bert": "hf-internal-testing/tiny-bert",
- "bigbird_pegasus": "hf-internal-testing/tiny-random-bigbird_pegasus",
- "blenderbot": "hf-internal-testing/tiny-random-blenderbot",
- "bloom": "bigscience/bigscience-small-testing",
- "deberta": "hf-internal-testing/tiny-random-deberta",
- "deberta-v2": "hf-internal-testing/tiny-random-deberta-v2",
- "distilbert": "sshleifer/tiny-distilbert-base-cased",
- "electra": "hf-internal-testing/tiny-electra",
- "funnel": "hf-internal-testing/tiny-random-funnel",
- "gpt2": GPT2_TINY,
- "gpt_neo": "hf-internal-testing/tiny-random-gpt_neo",
- "gptj": GPTJ_TINY,
- "layoutlm": "hf-internal-testing/tiny-layoutlm",
- "led": "hf-internal-testing/tiny-random-led",
- "longformer": "hf-internal-testing/tiny-random-longformer",
- "m2m_100": "stas/tiny-m2m_100",
- "mobilebert": "hf-internal-testing/tiny-random-mobilebert",
- "mpnet": "hf-internal-testing/tiny-random-mpnet",
- "prophetnet": "hf-internal-testing/tiny-random-prophetnet",
- "roberta": "sshleifer/tiny-distilroberta-base",
- "squeezebert": "hf-internal-testing/tiny-random-squeezebert",
- "t5": T5_TINY,
- "t5_v1": "hf-internal-testing/tiny-random-t5-v1.1",
- "vit": "hf-internal-testing/tiny-random-vit",
- "xlm-roberta": "hf-internal-testing/tiny-xlm-roberta",
- "xlnet": "sshleifer/tiny-xlnet-base-cased",
-}
-
-_ZOO_FIXTURE_DIR = get_tests_dir("fixtures")
-_ZOO_SAMPLES_DIR = f"{_ZOO_FIXTURE_DIR}/tests_samples"
-_ZOO_SCRIPTS_DIR = f"{os.path.join(os.path.dirname(get_tests_dir()))}/examples/pytorch"
-_ZOO_VIT_FEATURE_EXTRACTOR = os.path.join(SCRIPTS_DIR, "vit_feature_extractor.json")
-
-
-def _make_zoo_tasks():
- """Build {task_model: (script, script_args)} for each task/model combo."""
- tasks2models = {
- "trans": ["bart", "m2m_100", "t5", "t5_v1"],
- "clm": ["bigbird_pegasus", "blenderbot", "bloom", "gpt2", "gpt_neo", "gptj", "xlm-roberta", "prophetnet"],
- "mlm": ["albert", "deberta", "deberta-v2", "distilbert", "electra", "layoutlm"],
- "qa": ["led", "longformer", "mobilebert", "mpnet", "roberta", "squeezebert"],
- "clas": ["bert", "xlnet"],
- "img_clas": ["vit"],
- }
-
- # task -> (script_path, task-specific args)
- task_defs = {
- "trans": (
- f"{_ZOO_SCRIPTS_DIR}/translation/run_translation.py",
- f"--train_file {_ZOO_SAMPLES_DIR}/wmt_en_ro/train.json --source_lang en --target_lang ro "
- f"--max_source_length 12 --max_target_length 12".split(),
- ),
- "clm": (
- f"{_ZOO_SCRIPTS_DIR}/language-modeling/run_clm.py",
- f"--train_file {_ZOO_FIXTURE_DIR}/sample_text.txt --block_size 8".split(),
- ),
- "mlm": (
- f"{_ZOO_SCRIPTS_DIR}/language-modeling/run_mlm.py",
- f"--train_file {_ZOO_FIXTURE_DIR}/sample_text.txt".split(),
- ),
- "qa": (
- f"{_ZOO_SCRIPTS_DIR}/question-answering/run_qa.py",
- f"--train_file {_ZOO_SAMPLES_DIR}/SQUAD/sample.json".split(),
- ),
- "clas": (
- f"{_ZOO_SCRIPTS_DIR}/text-classification/run_glue.py",
- f"--train_file {_ZOO_SAMPLES_DIR}/MRPC/train.csv --max_seq_length 12 --task_name MRPC".split(),
- ),
- "img_clas": (
- f"{_ZOO_SCRIPTS_DIR}/image-classification/run_image_classification.py",
- f"--dataset_name hf-internal-testing/cats_vs_dogs_sample --remove_unused_columns False "
- f"--max_steps 10 --image_processor_name {_ZOO_VIT_FEATURE_EXTRACTOR} "
- f"--label_column_name labels".split(),
- ),
- }
-
- common_args = "--do_train --max_train_samples 4 --per_device_train_batch_size 2 --num_train_epochs 1 --fp16 --save_steps 1".split()
-
- result = {}
- for task, models in tasks2models.items():
- script, task_args = task_defs[task]
- for model in models:
- model_args = ["--model_name_or_path", _ZOO_MODELS[model]]
- result[f"{task}_{model}"] = (script, task_args + model_args + common_args)
-
- return result
-
-
-_zoo_tasks = _make_zoo_tasks()
-_zoo_params = list(itertools.product(stages, _zoo_tasks.keys()))
-
-
-@slow
-@require_deepspeed
-@require_torch_accelerator
-class TestDeepSpeedModelZoo(DeepSpeedCommandsMixin, TestCasePlus):
- """Test many model architectures with DeepSpeed (fp16 mixed precision) via example scripts + zero_to_fp32 recovery."""
-
- @parameterized.expand(_zoo_params, name_func=_parameterized_custom_name_func)
- def test_zero_to_fp32(self, stage, task):
- script, script_args = _zoo_tasks[task]
- output_dir = self.get_auto_remove_tmp_dir()
-
- # 1. Train and save a checkpoint
- cmd = self.get_accelerate_cmd(
- script,
- config_file=DS_CONFIGS[stage],
- script_args=script_args + ["--output_dir", output_dir],
- )
- execute_subprocess_async(cmd, env=self.get_env())
-
- # 2. Recover FP32 weights from the ZeRO checkpoint
- chkpt_dir = f"{output_dir}/checkpoint-1"
- recovered_model_path = f"{chkpt_dir}/out.bin"
- subprocess.check_call(f"{chkpt_dir}/zero_to_fp32.py {chkpt_dir} {recovered_model_path}", shell=True)
- assert os.path.exists(recovered_model_path), f"{recovered_model_path} was not found"
diff --git a/tests/trainer/test_trainer.py b/tests/trainer/test_trainer.py
index d47c38db7485..df3f389e0a05 100644
--- a/tests/trainer/test_trainer.py
+++ b/tests/trainer/test_trainer.py
@@ -18,7 +18,6 @@
"""
import math
-import os
import tempfile
from functools import partial
@@ -56,10 +55,8 @@
LoggingLevel,
TestCasePlus,
backend_device_count,
- execute_subprocess_async,
require_bitsandbytes,
require_liger_kernel,
- require_non_hpu,
require_peft,
require_torch,
require_torch_accelerator,
@@ -69,8 +66,6 @@
require_torch_multi_accelerator,
require_torch_non_multi_accelerator,
require_torch_tf32,
- run_first,
- slow,
torch_device,
)
from transformers.trainer_utils import align_special_tokens
@@ -1274,52 +1269,6 @@ def test_use_liger_kernel_custom_config_trainer(self):
class TrainerIntegrationTest(TestCasePlus):
"""Integration tests: compatibility, and e2e."""
- @slow
- @run_first
- @require_non_hpu
- @require_torch_multi_accelerator
- def test_end_to_end_example(self):
- # Tests that `translation.py` will run without issues
- script_path = os.path.abspath(
- os.path.join(
- os.path.dirname(__file__), "..", "..", "examples", "pytorch", "translation", "run_translation.py"
- )
- )
-
- with tempfile.TemporaryDirectory() as tmpdir:
- command = [
- "accelerate",
- "launch",
- script_path,
- "--model_name_or_path",
- "google-t5/t5-small",
- "--per_device_train_batch_size",
- "1",
- "--output_dir",
- tmpdir,
- "--do_train",
- "--max_train_samples",
- "64",
- "--num_train_epochs",
- "1",
- "--dataset_name",
- "wmt16",
- "--dataset_config",
- "ro-en",
- "--source_lang",
- "en",
- "--target_lang",
- "ro",
- "--do_predict",
- "--max_predict_samples",
- "64",
- "--predict_with_generate",
- "--ddp_timeout",
- "60",
- ]
- execute_subprocess_async(command)
- # successful return here == success - any errors would have caused an error or a timeout in the sub-call
-
def test_special_token_alignment(self):
"""
Tests that special token changes in the tokenizer result in model configs updates when using the trainer, to
diff --git a/tests/trainer/test_trainer_checkpointing.py b/tests/trainer/test_trainer_checkpointing.py
index 042219ec7ad7..61e066e0c595 100644
--- a/tests/trainer/test_trainer_checkpointing.py
+++ b/tests/trainer/test_trainer_checkpointing.py
@@ -27,7 +27,6 @@
import shutil
import signal
import subprocess
-import sys
import tempfile
import unittest
from pathlib import Path
@@ -65,9 +64,7 @@
get_torch_dist_unique_port,
is_staging_test,
mockenv_context,
- require_accelerate,
require_deepspeed,
- require_non_hpu,
require_peft,
require_tensorboard,
require_torch,
@@ -640,41 +637,28 @@ def setUp(self):
self.n_epochs = args.num_train_epochs
self.batch_size = args.train_batch_size
- @slow
- @require_non_hpu
- @require_accelerate
- @require_torch_non_multi_accelerator
def test_auto_batch_size_finder(self):
- if torch.cuda.is_available():
- torch.backends.cudnn.deterministic = True
+ train_dataset = RegressionDataset(length=128)
+ model = RegressionRandomPreTrainedModel(RegressionModelConfig(a=0, b=2))
- SRC_DIR = os.path.abspath(
- os.path.join(os.path.dirname(__file__), "..", "..", "examples", "pytorch", "text-classification")
- )
- sys.path.append(SRC_DIR)
- import run_glue
+ def make_trainer(auto_find_batch_size):
+ args = RegressionTrainingArguments(
+ self.get_auto_remove_tmp_dir(),
+ max_steps=2,
+ save_strategy="no",
+ per_device_train_batch_size=16,
+ auto_find_batch_size=auto_find_batch_size,
+ )
+ return Trainer(model, args, train_dataset=train_dataset, callbacks=[MockCudaOOMCallback()])
- with tempfile.TemporaryDirectory() as tmpdir:
- testargs = f"""
- run_glue.py
- --model_name_or_path distilbert/distilbert-base-uncased
- --task_name mrpc
- --do_train
- --do_eval
- --max_seq_len 128
- --per_device_train_batch_size 4096
- --learning_rate 2e-5
- --num_train_epochs 1
- --output_dir {tmpdir}
- --auto_find_batch_size 0
- """.split()
- with self.assertRaises(RuntimeError):
- with patch.object(sys, "argv", testargs):
- run_glue.main()
-
- testargs[-1] = "1"
- with patch.object(sys, "argv", testargs):
- run_glue.main()
+ # Without the finder, the OOM reaches the user
+ with self.assertRaisesRegex(RuntimeError, "CUDA out of memory"):
+ make_trainer(auto_find_batch_size=False).train()
+
+ # With it, training shrinks the batch size until it fits
+ trainer = make_trainer(auto_find_batch_size=True)
+ trainer.train()
+ self.assertLess(trainer._train_batch_size, 16)
@require_deepspeed
@require_torch_non_multi_accelerator
diff --git a/tests/trainer/test_trainer_seq2seq.py b/tests/trainer/test_trainer_seq2seq.py
index de16a4fad027..956d1cf33dbf 100644
--- a/tests/trainer/test_trainer_seq2seq.py
+++ b/tests/trainer/test_trainer_seq2seq.py
@@ -12,10 +12,6 @@
# See the License for the specific language governing permissions and
# limitations under the License.
-import os
-import sys
-from pathlib import Path
-from unittest.mock import patch
from transformers import (
AutoModelForSeq2SeqLM,
@@ -29,20 +25,11 @@
T5Tokenizer,
)
from transformers.testing_utils import (
- ExtendSysPath,
TestCasePlus,
- backend_device_count,
- execute_subprocess_async,
- get_torch_dist_unique_port,
- require_bitsandbytes,
require_sentencepiece,
require_torch,
- require_torch_multi_accelerator,
- require_torch_non_multi_accelerator,
slow,
- torch_device,
)
-from transformers.trainer_callback import TrainerState
from transformers.trainer_utils import set_seed
from transformers.utils import is_datasets_available, is_torch_available
@@ -55,8 +42,6 @@
set_seed(42)
-MARIAN_MODEL = "sshleifer/student_marian_en_ro_6_1"
-MBART_TINY = "sshleifer/tiny-mbart"
@require_sentencepiece
@@ -241,173 +226,3 @@ def test_bad_generation_config_fail_early(self):
compute_metrics=lambda x: {"samples": x[0].shape[0]},
)
self.assertIn("Fix these issues to train your model", str(exc.exception))
-
-
-@require_torch
-class TestTranslationExample(TestCasePlus):
- """Tests for the run_translation.py example script (seq2seq training via CLI)."""
-
- @classmethod
- def setUpClass(cls):
- super().setUpClass()
- examples_dir = Path(__file__).resolve().parents[2] / "examples" / "pytorch" / "translation"
- with ExtendSysPath(str(examples_dir)):
- from run_translation import main as _main
-
- cls._run_translation_main = staticmethod(_main)
-
- def _run_translation(
- self,
- distributed=False,
- extra_args_str=None,
- predict_with_generate=True,
- do_train=True,
- do_eval=True,
- do_predict=True,
- n_gpus_to_use=None,
- ):
- data_dir = self.test_file_dir / "../fixtures/tests_samples/wmt_en_ro"
- output_dir = self.get_auto_remove_tmp_dir()
- args = f"""
- --model_name_or_path {MBART_TINY}
- --train_file {data_dir}/train.json
- --validation_file {data_dir}/val.json
- --test_file {data_dir}/test.json
- --output_dir {output_dir}
- --max_train_samples 8
- --max_source_length 12
- --max_target_length 12
- --do_train
- --num_train_epochs 1
- --per_device_train_batch_size 4
- --learning_rate 3e-3
- --warmup_steps 8
- --logging_steps 0
- --logging_strategy no
- --save_steps 1
- --train_sampling_strategy group_by_length
- --label_smoothing_factor 0.1
- --target_lang ro_RO
- --source_lang en_XX
- --report_to none
- """.split()
-
- if do_eval:
- args += """
- --do_eval
- --per_device_eval_batch_size 4
- --max_eval_samples 8
- --val_max_target_length 12
- --eval_strategy steps
- --eval_steps 1
- """.split()
-
- if do_predict:
- args += ["--do_predict"]
-
- if predict_with_generate:
- args += ["--predict_with_generate"]
-
- if do_train:
- args += ["--optim", "adafactor"]
-
- if extra_args_str is not None:
- args += extra_args_str.split()
-
- if distributed:
- if n_gpus_to_use is None:
- n_gpus_to_use = backend_device_count(torch_device)
- master_port = get_torch_dist_unique_port()
- distributed_args = f"""
- -m torch.distributed.run
- --nproc_per_node={n_gpus_to_use}
- --master_port={master_port}
- {self.examples_dir_str}/pytorch/translation/run_translation.py
- """.split()
- cmd = [sys.executable] + distributed_args + args
- execute_subprocess_async(cmd, env=self.get_env())
- else:
- testargs = ["run_translation.py"] + args
- with patch.object(sys, "argv", testargs):
- self._run_translation_main()
-
- return output_dir
-
- @require_torch_non_multi_accelerator
- def test_run_seq2seq_no_dist(self):
- output_dir = self._run_translation()
- logs = TrainerState.load_from_json(os.path.join(output_dir, "trainer_state.json")).log_history
- eval_metrics = [log for log in logs if "eval_loss" in log]
- first_step_stats = eval_metrics[0]
- assert "eval_bleu" in first_step_stats
-
- @require_torch_multi_accelerator
- def test_run_seq2seq_dp(self):
- output_dir = self._run_translation(distributed=False)
- logs = TrainerState.load_from_json(os.path.join(output_dir, "trainer_state.json")).log_history
- eval_metrics = [log for log in logs if "eval_loss" in log]
- first_step_stats = eval_metrics[0]
- assert "eval_bleu" in first_step_stats
-
- @require_torch_multi_accelerator
- def test_run_seq2seq_ddp(self):
- output_dir = self._run_translation(distributed=True)
- logs = TrainerState.load_from_json(os.path.join(output_dir, "trainer_state.json")).log_history
- eval_metrics = [log for log in logs if "eval_loss" in log]
- first_step_stats = eval_metrics[0]
- assert "eval_bleu" in first_step_stats
-
- @slow
- def test_run_seq2seq_slow(self):
- output_dir = self._run_translation(
- extra_args_str=f"--model_name_or_path {MARIAN_MODEL} --learning_rate 3e-4 --num_train_epochs 10 --max_source_length 128 --max_target_length 128 --eval_steps 2 --save_steps 2",
- )
- logs = TrainerState.load_from_json(os.path.join(output_dir, "trainer_state.json")).log_history
- eval_metrics = [log for log in logs if "eval_loss" in log]
- first_step_stats = eval_metrics[0]
- last_step_stats = eval_metrics[-1]
- assert first_step_stats["eval_loss"] > last_step_stats["eval_loss"], "model learned nothing"
- assert isinstance(last_step_stats["eval_bleu"], float)
- contents = {os.path.basename(p) for p in os.listdir(output_dir)}
- assert "generated_predictions.txt" in contents
- assert "predict_results.json" in contents
-
- @slow
- @require_bitsandbytes
- def test_run_seq2seq_bnb(self):
- from transformers.training_args import OptimizerNames
-
- def train_and_return_metrics(optim: str) -> tuple[int, float]:
- output_dir = self._run_translation(
- distributed=True,
- extra_args_str=f"--skip_memory_metrics 0 --model_name_or_path {MARIAN_MODEL} --learning_rate 3e-4 --num_train_epochs 1 --optim {optim} --max_source_length 128 --max_target_length 128",
- do_eval=False,
- do_predict=False,
- n_gpus_to_use=1,
- )
- logs = TrainerState.load_from_json(Path(output_dir, "trainer_state.json")).log_history
- gpu_peak_mem_mb = int(logs[0]["train_mem_gpu_peaked_delta"] / 2**20)
- gpu_alloc_mem_mb = int(logs[0]["train_mem_gpu_alloc_delta"] / 2**20)
- loss = logs[0]["train_loss"]
- return gpu_peak_mem_mb, gpu_alloc_mem_mb, loss
-
- gpu_peak_mem_orig, gpu_alloc_mem_orig, loss_orig = train_and_return_metrics(OptimizerNames.ADAMW_TORCH.value)
- gpu_peak_mem_bnb, gpu_alloc_mem_bnb, loss_bnb = train_and_return_metrics(OptimizerNames.ADAMW_BNB.value)
-
- gpu_alloc_mem_diff = gpu_alloc_mem_orig - gpu_alloc_mem_bnb
- gpu_total_mem_orig = gpu_peak_mem_orig + gpu_alloc_mem_orig
- gpu_total_mem_bnb = gpu_peak_mem_bnb + gpu_alloc_mem_bnb
- gpu_total_mem_diff = gpu_total_mem_orig - gpu_total_mem_bnb
-
- expected_savings = 120
- self.assertGreater(
- gpu_alloc_mem_diff,
- expected_savings,
- f"should use ~150MB less alloc gpu memory with BNB, but got diff={gpu_alloc_mem_diff}MB",
- )
- self.assertGreater(
- gpu_total_mem_diff,
- expected_savings,
- f"should use ~150MB less total gpu memory with BNB, but got diff={gpu_total_mem_diff}MB",
- )
- self.assertAlmostEqual(loss_orig, loss_bnb, 5, f"loss should be the same: {loss_orig} vs {loss_bnb}")
diff --git a/utils/not_doctested.txt b/utils/not_doctested.txt
index f8c9b8f9f6d8..b678b0931c05 100644
--- a/utils/not_doctested.txt
+++ b/utils/not_doctested.txt
@@ -249,7 +249,6 @@ docs/source/en/perplexity.md
docs/source/en/philosophy.md
docs/source/en/pipeline_webserver.md
docs/source/en/pr_checks.md
-docs/source/en/run_scripts.md
docs/source/en/serialization.md
docs/source/en/tasks/asr.md
docs/source/en/tasks/audio_classification.md
diff --git a/utils/notification_service.py b/utils/notification_service.py
index 2f100e8e61d2..8b9189d51dab 100644
--- a/utils/notification_service.py
+++ b/utils/notification_service.py
@@ -37,7 +37,6 @@
"run_models_gpu": "Models",
"run_trainer_and_fsdp_gpu": "Trainer & DDP & FSDP",
"run_pipelines_torch_gpu": "PyTorch pipelines",
- "run_examples_gpu": "Examples directory",
"run_torch_cuda_extensions_gpu": "DeepSpeed",
"run_quantization_torch_gpu": "Quantization",
"run_kernels_gpu": "Kernels",
@@ -48,7 +47,6 @@
"Models": "model",
"Trainer & DDP & FSDP": "trainer_and_fsdp",
"PyTorch pipelines": "torch_pipeline",
- "Examples directory": "example",
"DeepSpeed": "deepspeed",
"Quantization": "quantization",
"Kernels": "kernels",
@@ -1358,13 +1356,11 @@ def pop_default(l: list[Any], i: int, default: Any) -> Any:
# Additional runs
additional_files = {
"PyTorch pipelines": "run_pipelines_torch_gpu_test_reports",
- "Examples directory": "run_examples_gpu_test_reports",
"DeepSpeed": "run_torch_cuda_extensions_gpu_test_reports",
"Kernels": "run_kernels_gpu_test_reports",
}
if ci_event in ["push", "Nightly CI"] or ci_event.startswith("Past CI"):
- del additional_files["Examples directory"]
del additional_files["PyTorch pipelines"]
elif ci_event.startswith("Scheduled CI (AMD)"):
del additional_files["DeepSpeed"]
diff --git a/utils/tests_fetcher.py b/utils/tests_fetcher.py
index 826b9ab177a2..d5264d401934 100644
--- a/utils/tests_fetcher.py
+++ b/utils/tests_fetcher.py
@@ -67,7 +67,6 @@
PATH_TO_REPO = Path(__file__).parent.parent.resolve()
-PATH_TO_EXAMPLES = PATH_TO_REPO / "examples"
PATH_TO_TRANSFORMERS = PATH_TO_REPO / "src/transformers"
PATH_TO_TESTS = PATH_TO_REPO / "tests"
@@ -851,38 +850,6 @@ def print_tree_deps_of(module, all_edges=None):
print(line[0])
-def init_test_examples_dependencies() -> tuple[dict[str, list[str]], list[str]]:
- """
- The test examples do not import from the examples (which are just scripts, not modules) so we need some extra
- care initializing the dependency map, which is the goal of this function. It initializes the dependency map for
- example files by linking each example to the example test file for the example folder.
-
- Returns:
- `Tuple[Dict[str, List[str]], List[str]]`: A tuple with two elements: the initialized dependency map which is a
- dict test example file to list of example files potentially tested by that test file, and the list of all
- example files (to avoid recomputing it later).
- """
- test_example_deps = {}
- all_examples = []
-
- test_files = list((PATH_TO_EXAMPLES / "pytorch").glob("test_*.py"))
- all_examples.extend(test_files)
- # Remove the files at the root of examples/pytorch since they are not proper examples (they are either utils
- # or example test files).
- examples = [f for f in (PATH_TO_EXAMPLES / "pytorch").glob("**/*.py") if f.parent != PATH_TO_EXAMPLES / "pytorch"]
- all_examples.extend(examples)
- for test_file in test_files:
- with open(test_file, "r", encoding="utf-8") as f:
- content = f.read()
- # Map all examples to the test files found in examples/pytorch.
- test_example_deps[str(test_file.relative_to(PATH_TO_REPO))] = [
- str(e.relative_to(PATH_TO_REPO)) for e in examples if e.name in content
- ]
- # Also map the test files to themselves.
- test_example_deps[str(test_file.relative_to(PATH_TO_REPO))].append(str(test_file.relative_to(PATH_TO_REPO)))
- return test_example_deps, all_examples
-
-
def create_reverse_dependency_map() -> dict[str, list[str]]:
"""
Create the dependency map from module/test filename to the list of modules/tests that depend on it recursively.
@@ -894,16 +861,13 @@ def create_reverse_dependency_map() -> dict[str, list[str]]:
"""
cache = {}
- # Start from the example deps init.
- example_deps, examples = init_test_examples_dependencies()
- # Add all modules and all tests to all examples
+ # Add all modules and all tests
all_modules = list(PATH_TO_TRANSFORMERS.glob("**/*.py"))
all_modules = [x for x in all_modules if not ("models" in x.parts and x.parts[-1].startswith("convert_"))]
- all_modules += list(PATH_TO_TESTS.glob("**/*.py")) + examples
+ all_modules += list(PATH_TO_TESTS.glob("**/*.py"))
all_modules = [str(mod.relative_to(PATH_TO_REPO)) for mod in all_modules]
# Compute the direct dependencies of all modules.
direct_deps = {m: get_module_dependencies(m, cache=cache) for m in all_modules}
- direct_deps.update(example_deps)
# This recurses the dependencies
something_changed = True
@@ -963,16 +927,8 @@ def create_module_to_test_map(reverse_map: dict[str, list[str]] | None = None) -
if reverse_map is None:
reverse_map = create_reverse_dependency_map()
- # Utility that tells us if a given file is a test (taking test examples into account)
- def is_test(fname):
- if fname.startswith("tests"):
- return True
- if fname.startswith("examples") and fname.split(os.path.sep)[-1].startswith("test"):
- return True
- return False
-
# Build the test map
- test_map = {module: [f for f in deps if is_test(f)] for module, deps in reverse_map.items()}
+ test_map = {module: [f for f in deps if f.startswith("tests")] for module, deps in reverse_map.items()}
return test_map
@@ -1050,7 +1006,6 @@ def infer_tests_to_run(output_file: str, diff_with_last_commit: bool = False, te
The path where to store the summary of the test fetcher analysis. Other files will be stored in the same
folder:
- - examples_test_list.txt: The list of examples tests to run.
- test_repo_utils.txt: Will indicate if the repo utils tests should be run or not.
- doctest_list.txt: The list of doctests to run.
@@ -1082,9 +1037,7 @@ def infer_tests_to_run(output_file: str, diff_with_last_commit: bool = False, te
or len(model_impacted) >= NUM_MODELS_TO_TRIGGER_FULL_CI
or commit_flags["test_all"]
):
- test_files_to_run = glob.glob("tests/**/test_**.py", recursive=True) + glob.glob(
- "examples/**/*.py", recursive=True
- )
+ test_files_to_run = glob.glob("tests/**/test_**.py", recursive=True)
if len(model_impacted) >= NUM_MODELS_TO_TRIGGER_FULL_CI:
print(
f"More than {NUM_MODELS_TO_TRIGGER_FULL_CI - 1} models are impacted. CI is configured to test everything."
@@ -1185,7 +1138,6 @@ def parse_commit_message(commit_message: str) -> dict[str, bool]:
"tests_generate": r"(tests/models/.*/test_modeling_.*|tests/generation/test_.*\.py)",
"tests_tokenization": r"tests/(?:models/.*/test_tokenization.*|test_tokenization_mistral_common\.py)",
"tests_processors": r"tests/models/.*/test_(?!(?:modeling_|tokenization_)).*", # takes feature extractors, image processors, processors
- "examples_torch": r"examples/pytorch/.*test_.*",
"tests_exotic_models": r"tests/models/.*(?=layoutlmv|nat|deta|udop|nougat).*",
"tests_custom_tokenizers": r"tests/models/.*/test_tokenization_(?=bert_japanese|openai|clip).*",
# conftest tests exercise the test runner (repo-root conftest.py); they share the