Skip to content

fix(fmoe): correct padded SEPARATED w13 in bf16 CK-Tile gate-up - #3862

Closed
thpereir wants to merge 1 commit into
ROCm:mainfrom
thpereir:thpereir/npad_fix
Closed

thpereir wants to merge 1 commit into
ROCm:mainfrom
thpereir:thpereir/npad_fix

Conversation

@thpereir

Copy link
Copy Markdown

For Swiglu MXFP4 bf16-activation CK-Tile dispatch, use n_pad_zeros=0 so padded SEPARATED w13 layouts are handled correctly while keeping the fast bf16 path.

Scope the behavior to swiglu_mxfp4_bf16_cktile only; preserve the legacy n_pad_zeros formula for generic ksplit>1 paths to avoid impacting other models.

Add regression guards for both target and non-target paths in op_tests/test_moe_2stage_npad_guard.py.

Motivation

Properly run MiniMax M3 MXFP4 on ATOM with TP=8

Test Result

Tested with ATOM with TP=8:

python -m atom.entrypoints.openai_server \
  --model amd/MiniMax-M3-MXFP4-AttnFP8 \
  --trust-remote-code \
  --tensor-parallel-size 8 \
  --block-size 128 \
  --server-port 8000

lm-eval

lm_eval \
  --model local-chat-completions \
  --model_args "model=amd/MiniMax-M3-MXFP4-AttnFP8,base_url=http://127.0.0.1:8000/v1/chat/completions,num_concurrent=32,max_gen_toks=16384" \
  --tasks gsm8k \
  --num_fewshot 5 \
  --batch_size 1 \
  --apply_chat_template \
  --fewshot_as_multiturn

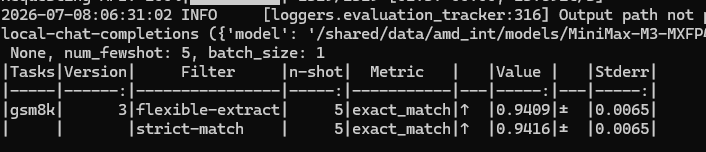
Results, for reference with TP=1 gsm8k gives ~0.9424:

Build flexible-extract strict-match
Baseline — origin/main (no fix) 0.7665 ± 0.0117 0.7657 ± 0.0117
Fixed — this branch 0.9409 ± 0.0065 0.9416 ± 0.0065

Submission Checklist

@thpereir
thpereir requested a review from a team June 22, 2026 21:01
@github-actions

Copy link
Copy Markdown
Contributor

🏷️ CI Guide

Runs automatically on every PR:

  • ✅ Pre-checks (submodule verification, code formatting)
  • ✅ Aiter op tests (gfx942 + gfx950)
  • ✅ Triton tests on MI35X (only when aiter/ops/triton/** or related paths are changed)

Extended tests (opt-in via labels):

Label Tests
ci:triton-300x Run an additional Triton test job on MI300X in PRs; main branch always runs both MI35X and MI300X
ci:sglang SGLang integration tests: DeepSeek-R1-MXFP4 accuracy, Qwen 3.5 accuracy
ci:atom ATOM benchmark: DeepSeek-R1-0528, GPT-OSS-120B
ci:atom_full ATOM accuracy suite for PR and main models from ATOM models_accuracy.json
ci:vllm vLLM benchmark: GPT-OSS-120B, DeepSeek-R1-0528, Kimi-K2.5
ci:all All standard extended tests (excludes ci:atom_full)

Only add ci:atom_full for FlyDSL or Triton upgrades.
Add labels via the sidebar or gh pr edit 3862 --add-label <label>

@thpereir
thpereir force-pushed the thpereir/npad_fix branch 2 times, most recently from 645cf33 to c636f41 Compare June 24, 2026 21:48
@zufayu
zufayu requested review from yzhou103 and zufayu and removed request for zufayu June 26, 2026 08:53
@thpereir
thpereir force-pushed the thpereir/npad_fix branch 2 times, most recently from aa917e2 to 1b55b0b Compare June 29, 2026 15:52
@yzhou103
yzhou103 requested a review from XiaobingSuper July 6, 2026 06:28
@yzhou103

yzhou103 commented Jul 6, 2026

Copy link
Copy Markdown
Contributor

@XiaobingSuper Could you help review this PR? I'm not sure whether the change will affect GPT-OSS

For Swiglu MXFP4 bf16-activation CK-Tile dispatch, use n_pad_zeros=0 so padded SEPARATED w13 layouts are handled correctly while keeping the fast bf16 path.

Scope the behavior to swiglu_mxfp4_bf16_cktile only; preserve the legacy n_pad_zeros formula for generic ksplit>1 paths to avoid impacting other models.

Add regression guards for both target and non-target paths in op_tests/test_moe_2stage_npad_guard.py.
@thpereir
thpereir force-pushed the thpereir/npad_fix branch from 1b55b0b to 96254d1 Compare July 7, 2026 15:33
@lirui927

lirui927 commented Jul 8, 2026

Copy link
Copy Markdown
Contributor

hello, I've tested the accuracy, and there are no issues of MiniMax M3 MXFP4 on ATOM with TP=8 using the current code(origin/main).

server

model_path=/shared/data/amd_int/models/MiniMax-M3-MXFP4
export HIP_VISIBLE_DEVICES="0,1,2,3,4,5,6,7"
export AITER_QUICK_REDUCE_QUANTIZATION=INT4
export ATOM_FORCE_ATTN_TRITON=1

python -m atom.entrypoints.openai_server \
  --model "$model_path" \
  --tensor-parallel-size 8 \
  --server-port 8001 \
  --trust-remote-code \
  --gpu-memory-utilization 0.8 \
  --block-size 128 \
  --max-model-len 32768 \
  --max-num-seqs 128 \
  --max-num-batched-tokens 32768 \
  --online_quant_config '{"global_quant_config": "ptpc_fp8", "exclude_layer": ["lm_head", "model.embed_tokens", "vision_tower", "multi_modal_projector", "patch_merge_mlp", "*block_sparse_moe"]}' \
  --no-enable_prefix_caching \
  --hf-overrides '{"use_index_cache": true, "index_topk_freq": 4}' 2>&1 | tee "m3-mxfp4-server.log"

lm-eval

model_path=/shared/data/amd_int/models/MiniMax-M3-MXFP4
BS=1
RUN_NAME=m3-mxfp4-atom-bs${BS}

lm_eval \
  --model local-chat-completions \
  --model_args "model=$model_path,base_url=http://localhost:8001/v1/chat/completions,num_concurrent=32,max_gen_toks=2048" \
  --tasks gsm8k \
  --num_fewshot 5 \
  --batch_size "${BS}" \
  --apply_chat_template \
  --fewshot_as_multiturn \
  2>&1 | tee "${RUN_NAME}-accuracy.log"

result
image

We're using MiniMax-M3-MXFP4, not MiniMax-M3-MXFP4-AttnFP8.
When I start the server using the following command, I get the following error:

python -m atom.entrypoints.openai_server \
  --model /shared/data/amd_int/models/MiniMax-M3-MXFP4-AttnFP8 \
  --trust-remote-code \
  --tensor-parallel-size 8 \
  --block-size 128 \
  --server-port 8001

[AITER] /app/aiter-test/csrc/py_itfs_cu/asm_pa.cu:162 get_heuristic_kernel: cannot get heuristic kernel! q_type:bf16 kv_type:bf16 gqa:8 mtp:0 msk:0 hp:0 block_size:128 ps:0 qTile:0 quant_type:0

@thpereir

Copy link
Copy Markdown
Author

The issue was fixed indeed.

Tasks Version Filter n-shot Metric Value Stderr
gsm8k 3 flexible-extract 5 exact_match ↑ 0.9363 ± 0.0067
strict-match 5 exact_match ↑ 0.9371 ± 0.0067

I will close this PR

Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Labels

None yet

Projects

None yet

Development

Successfully merging this pull request may close these issues.

3 participants